# User: Wei Dai
Profile URL (HTML): [/users/wei-dai](/users/wei-dai)
Profile URL (Markdown): [/api/user/wei-dai](/api/user/wei-dai)
* Karma: 48600
* Alignment Forum karma: 3607
* Posts: 153
* Comments: 5535
* Member since: 2009-03-06 19:59:52Z
Bio
---
If anyone wants to have a voice chat with me about a topic that I'm interested in (see my recent post/comment history to get a sense), please contact me via PM.
My main "claims to fame":
* Created the first general purpose open source cryptography programming library ([Crypto++](https://www.cryptopp.com/), 1995), motivated by AI risk and what's now called "defensive acceleration".
* Published one of the first descriptions of a cryptocurrency based on a distributed public ledger ([b-money](http://www.weidai.com/bmoney.txt), 1998), predating Bitcoin.
* Proposed [UDT](https://wiki.lesswrong.com/wiki/Updateless_decision_theory), combining the ideas of updatelessness, policy selection, and evaluating consequences using logical conditionals.
* First to argue for pausing AI development based on the technical difficulty of ensuring AI x-safety ([SL4 2004](http://sl4.org/archive/0410/10098.html), [LW 2011](https://www.lesswrong.com/posts/73SotZnDbsYpxfnuQ/some-thoughts-on-singularity-strategies)).
* [Identified](https://www.lesswrong.com/posts/w6d7XBCegc96kz4n3/the-argument-from-philosophical-difficulty) current and future philosophical difficulties as core AI x-safety bottlenecks, potentially insurmountable by human researchers, and [advocated](https://www.lesswrong.com/posts/vrnhfGuYTww3fKhAM/three-approaches-to-friendliness) for research into [metaphilosophy](https://www.lesswrong.com/w/meta-philosophy) and AI philosophical competence as possible solutions.
[My Home Page](http://www.weidai.com)
Top Posts
---------
### [Legible vs. Illegible AI Safety Problems](/api/post/legible-vs-illegible-ai-safety-problems)
By [Wei Dai](/users/wei-dai)
2025-11-04 21:39:07Z
* Karma: 422
* Curated
* Tags: [AI Risk](/w/ai-risk), [AI](/w/ai) (Frontpage)
Read more: [/api/post/legible-vs-illegible-ai-safety-problems](/api/post/legible-vs-illegible-ai-safety-problems)
### [A tale from Communist China](/api/post/a-tale-from-communist-china)
By [Wei Dai](/users/wei-dai)
2020-10-18 17:37:42Z
* Karma: 303
* Tags: [History](/w/history), [Censorship](/w/censorship), [China](/w/china), [Politics](/w/politics) (Personal Blog)
Read more: [/api/post/a-tale-from-communist-china](/api/post/a-tale-from-communist-china)
### [Morality is Scary](/api/post/morality-is-scary)
By [Wei Dai](/users/wei-dai)
2021-12-02 06:35:06Z
* Karma: 298
* Tags: [Ethics & Morality](/w/ethics-and-morality), [Human-AI Safety](/w/human-ai-safety), [AI](/w/ai) (Frontpage)
Read more: [/api/post/morality-is-scary](/api/post/morality-is-scary)
Recent Posts
------------
### [The Long (Self-)Correction](/api/post/the-long-self-correction-2)
By [Wei Dai](/users/wei-dai)
2026-07-24 21:01:47Z
* Karma: 272
* Curated
* Tags: [Human Alignment](/w/human-alignment), [AI Development Pause](/w/ai-development-pause), [AI](/w/ai) (Frontpage)
Read more: [/api/post/the-long-self-correction-2](/api/post/the-long-self-correction-2)
### [Increasing AI Strategic Competence as a Safety Approach](/api/post/increasing-ai-strategic-competence-as-a-safety-approach)
By [Wei Dai](/users/wei-dai)
2026-02-03 01:08:13Z
* Karma: 58
* Tags: [AI](/w/ai) (Frontpage)
Read more: [/api/post/increasing-ai-strategic-competence-as-a-safety-approach](/api/post/increasing-ai-strategic-competence-as-a-safety-approach)
### [My 2003 Post on the Evolutionary Argument for AI Misalignment](/api/post/my-2003-post-on-the-evolutionary-argument-for-ai)
By [Wei Dai](/users/wei-dai)
2026-01-06 20:45:20Z
* Karma: 38
* Tags: [Evolution](/w/evolution), [AI](/w/ai) (Frontpage)
Read more: [/api/post/my-2003-post-on-the-evolutionary-argument-for-ai](/api/post/my-2003-post-on-the-evolutionary-argument-for-ai)
### [A Conflict Between AI Alignment and Philosophical Competence](/api/post/a-conflict-between-ai-alignment-and-philosophical-competence)
By [Wei Dai](/users/wei-dai)
2025-12-27 21:32:07Z
* Karma: 78
* Tags: [AI-Assisted Alignment](/w/ai-assisted-alignment), [Corrigibility](/w/corrigibility-1), [Meta-Philosophy](/w/meta-philosophy), [Metaethics](/w/metaethics-1), [Philosophy](/w/philosophy-1), [AI](/w/ai) (Frontpage)
Read more: [/api/post/a-conflict-between-ai-alignment-and-philosophical-competence](/api/post/a-conflict-between-ai-alignment-and-philosophical-competence)
### [Relitigating the Race to Build Friendly AI](/api/post/relitigating-the-race-to-build-friendly-ai)
By [Wei Dai](/users/wei-dai)
2025-12-03 11:34:13Z
* Karma: 112
* Tags: [AI](/w/ai) (Frontpage)
Read more: [/api/post/relitigating-the-race-to-build-friendly-ai](/api/post/relitigating-the-race-to-build-friendly-ai)
### [Please, Don't Roll Your Own Metaethics](/api/post/please-don-t-roll-your-own-metaethics)
By [Wei Dai](/users/wei-dai)
2025-11-12 22:17:04Z
* Karma: 172
* Tags: [Meta-Philosophy](/w/meta-philosophy), [Metaethics](/w/metaethics-1), [Philosophy](/w/philosophy-1), [World Optimization](/w/world-optimization) (Frontpage)
Read more: [/api/post/please-don-t-roll-your-own-metaethics](/api/post/please-don-t-roll-your-own-metaethics)
### [Problems I've Tried to Legibilize](/api/post/problems-i-ve-tried-to-legibilize)
By [Wei Dai](/users/wei-dai)
2025-11-09 10:27:22Z
* Karma: 165
* Tags: [AI Risk](/w/ai-risk), [AI](/w/ai) (Frontpage)
Read more: [/api/post/problems-i-ve-tried-to-legibilize](/api/post/problems-i-ve-tried-to-legibilize)
### [Legible vs. Illegible AI Safety Problems](/api/post/legible-vs-illegible-ai-safety-problems)
By [Wei Dai](/users/wei-dai)
2025-11-04 21:39:07Z
* Karma: 422
* Curated
* Tags: [AI Risk](/w/ai-risk), [AI](/w/ai) (Frontpage)
Read more: [/api/post/legible-vs-illegible-ai-safety-problems](/api/post/legible-vs-illegible-ai-safety-problems)
### [Trying to understand my own cognitive edge](/api/post/trying-to-understand-my-own-cognitive-edge)
By [Wei Dai](/users/wei-dai)
2025-11-03 08:49:29Z
* Karma: 74
* Tags: [Intellectual Progress (Individual-Level)](/w/intellectual-progress-individual-level), [Rationality](/w/rationality) (Frontpage)
Read more: [/api/post/trying-to-understand-my-own-cognitive-edge](/api/post/trying-to-understand-my-own-cognitive-edge)
### [Wei Dai's Shortform](/api/post/wei-dai-s-shortform)
By [Wei Dai](/users/wei-dai)
2024-03-01 20:43:15Z
* Karma: 10
* Tags: None (Personal Blog)
Read more: [/api/post/wei-dai-s-shortform](/api/post/wei-dai-s-shortform)
Recent Comments
---------------
### Comment by [Wei Dai](/users/wei-dai) on [Wei Dai's Shortform](/api/post/wei-dai-s-shortform)
* 2026-09-28 00:48:24Z
* Karma: 22
* Total votes: 14
* Comment URL (Markdown): [/api/post/wei-dai-s-shortform/comments/yNZDXyZ3RAPuHGaWy](/api/post/wei-dai-s-shortform/comments/yNZDXyZ3RAPuHGaWy)
* Comment URL (HTML): [/posts/HbkNAyAoa4gCnuzwa/wei-dai-s-shortform/comment/yNZDXyZ3RAPuHGaWy](/posts/HbkNAyAoa4gCnuzwa/wei-dai-s-shortform/comment/yNZDXyZ3RAPuHGaWy)
(Cross-posted [from X](https://x.com/weidai11/status/2104366319336366099))
Why didn't more AI safety people advocate for AI pause/stop earlier? Well, aside from sociological reasons, in order to do that, you had to think that none of the following would work out (be feasible, safe, have low enough safety tax) in time, which takes a degree of skepticism almost no one could muster. (Or object to AGI/ASI on non-consequentialist grounds, but there was apparently a very high correlation between consequentialism and early interest in AI safety.)
Friendly AI (CFAI)
Coherent Extrapolated Volition (CEV)
Metaphilosophical AI
Tool AGI
Value Learning
Oracle AI
Agent Foundations
Corrigible AI
Quantilizers
Approval-Directed Agents
Human Imitation
Cooperative Inverse RL (CIRL)
Iterated Distillation and Amplification (IDA)
Task-Directed AGI
RL from Human Feedback (RLHF)
Impact Regularization
Mechanistic Interpretability
AI Safety via Debate
Recursive Reward Modeling
Comprehensive AI Services (CAIS)
Infra-Bayesianism
Alignment by Default
Natural Abstraction
Eliciting Latent Knowledge (ELK)
Shard Theory
Constitutional AI
AI Control
Weak-to-Strong Generalization
To recenter the sociology, it was much easier to build a career out of being bullish one or more of these approaches, than out of general skepticism. (I've been independent, financially and otherwise, throughout my participation in AI safety, which was perhaps not a coincidence from being the only AI pause/stop advocate for a long time.)
Edit: The original X version quoted [this tweet](https://x.com/weidai11/status/2099004312533770435), which made clearer what time period I'm talking about:
> This actually left out the most unique thing I did. (Each item on Andreas's list was done by at least one other person besides myself.) Starting in 2004, I concluded that Friendly AI would be too hard/risky to attempt, and repeatedly tried to talk Eliezer/MIRI out of pursuing this path to the Singularity (before they changed their minds largely by themselves in the early 2020s).
>
> AFAIK I was the only person to publicly make this argument during that time, which seems striking and notable, e.g., as evidence for how rational or strategically competent the rationalists and humans in general were/are. Not that the argument was clearly correct back in the 00s and 10s, but rather in retrospect it seems like a natural argument for people in the rationalist circles to make, and surprising that nobody else did.
### Comment by [Wei Dai](/users/wei-dai) on [Overtly misaligned trajectories score highly in RL.](/api/post/overtly-misaligned-trajectories-score-highly-in-rl)
* 2026-09-25 00:13:10Z
* Karma: 8
* Total votes: 6
* Comment URL (Markdown): [/api/post/overtly-misaligned-trajectories-score-highly-in-rl/comments/FtyaCrggsASp9bgtz](/api/post/overtly-misaligned-trajectories-score-highly-in-rl/comments/FtyaCrggsASp9bgtz)
* Comment URL (HTML): [/posts/cWuqxF7qB2eGSkkS4/overtly-misaligned-trajectories-score-highly-in-rl/comment/FtyaCrggsASp9bgtz](/posts/cWuqxF7qB2eGSkkS4/overtly-misaligned-trajectories-score-highly-in-rl/comment/FtyaCrggsASp9bgtz)
>I'd be surprised if they were using anything much cleverer than a cheap monitor checking for egregious reward hacks using a rubric.
This is also my impression, but what I'm not sure about is whether this is the result of them having tried pretty hard to do scalable oversight, and that effort failing (and therefore not reaching production), or not trying very hard so far. (I guess OpenAI probably hasn't tried very hard, with the Superalignment team leaving and all, but what about Anthropic?)
### Comment by [Wei Dai](/users/wei-dai) on [Overtly misaligned trajectories score highly in RL.](/api/post/overtly-misaligned-trajectories-score-highly-in-rl)
* 2026-09-24 23:50:25Z
* Karma: 21
* Total votes: 13
* Comment URL (Markdown): [/api/post/overtly-misaligned-trajectories-score-highly-in-rl/comments/8Sa6pTgAN4stpC5jP](/api/post/overtly-misaligned-trajectories-score-highly-in-rl/comments/8Sa6pTgAN4stpC5jP)
* Comment URL (HTML): [/posts/cWuqxF7qB2eGSkkS4/overtly-misaligned-trajectories-score-highly-in-rl/comment/8Sa6pTgAN4stpC5jP](/posts/cWuqxF7qB2eGSkkS4/overtly-misaligned-trajectories-score-highly-in-rl/comment/8Sa6pTgAN4stpC5jP)
> **Scalable oversight.** Maybe we could build better harnesses of the LLM graders (e.g. debate with cross examination plus plus) so they match human performance.
I wonder how hard the AI companies have already tried on this (hence how much room there is for improvement in the short term). It seems hard to get a good sense of this from the outside. Does anyone have an insider perspective (or even rumors about this) they can share?
### Comment by [Wei Dai](/users/wei-dai) on [Personal statement on joining the OpenAI nonprofit board](/api/post/personal-statement-on-joining-the-openai-nonprofit-board)
* 2026-09-14 14:52:58Z
* Karma: 11
* Total votes: 5
* Comment URL (Markdown): [/api/post/personal-statement-on-joining-the-openai-nonprofit-board/comments/MF8uQkzPDocbyHLk6](/api/post/personal-statement-on-joining-the-openai-nonprofit-board/comments/MF8uQkzPDocbyHLk6)
* Comment URL (HTML): [/posts/82z6FvbYRdjYjqigK/personal-statement-on-joining-the-openai-nonprofit-board/comment/MF8uQkzPDocbyHLk6](/posts/82z6FvbYRdjYjqigK/personal-statement-on-joining-the-openai-nonprofit-board/comment/MF8uQkzPDocbyHLk6)
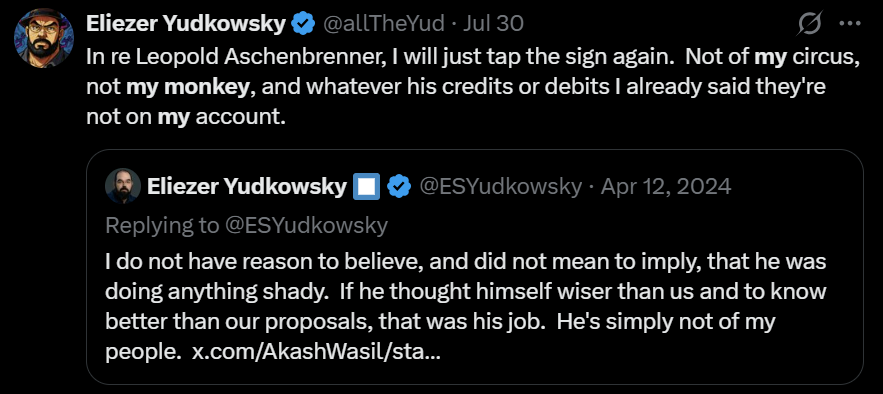
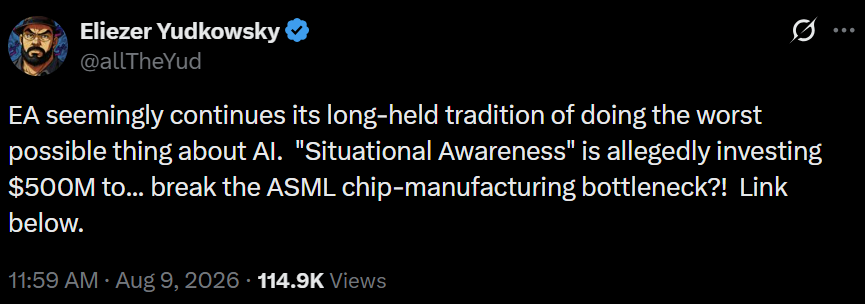
I wonder if you perhaps missed that I was responding to these tweets from Eliezer, which already made the tribal distinction (that I was in part trying to *push back* against)? (Otherwise I'm having trouble understanding why you're annoyed at me in this conversation.) Edit: I guess I also had some genuine curiosity as to what Eliezer and others saw as the differences between EA and rationalists, so some parts of the thread was more about that than pushing back. Still hard to see anything that I did as wrong or annoying... Also, totally fine not to engage, just wanted to express my confusion.
### Comment by [Wei Dai](/users/wei-dai) on [PauseAI Has 'officially disendorsed' PauseAI-US](/api/post/pauseai-has-officially-disendorsed-pauseai-us)
* 2026-09-11 22:56:16Z
* Karma: 4
* Total votes: 3
* Comment URL (Markdown): [/api/post/pauseai-has-officially-disendorsed-pauseai-us/comments/XCQpFqqkH2tgcZvL7](/api/post/pauseai-has-officially-disendorsed-pauseai-us/comments/XCQpFqqkH2tgcZvL7)
* Comment URL (HTML): [/posts/Bs8geGyWEitYvCzys/pauseai-has-officially-disendorsed-pauseai-us/comment/XCQpFqqkH2tgcZvL7](/posts/Bs8geGyWEitYvCzys/pauseai-has-officially-disendorsed-pauseai-us/comment/XCQpFqqkH2tgcZvL7)
Your notion of "morally bad actor" does not seem to require/imply that the person "know what they're doing is bad", because you could convert someone who doesn't know this into being a friend, by convincing them that what they're doing is bad, either through arguments or by applying social pressure. This seems to be what Liron and Holly are in part trying to do?
(I can also imagine Liron/Holly using the term in a different way, which also seems reasonable, more in line with my example of a torturer AI, which is that this agent is doing something really bad according to our morality, and so we should mobilize/coordinate to do something about it.)
### Comment by [Wei Dai](/users/wei-dai) on [PauseAI Has 'officially disendorsed' PauseAI-US](/api/post/pauseai-has-officially-disendorsed-pauseai-us)
* 2026-09-11 17:57:09Z
* Karma: 3
* Total votes: 4
* Comment URL (Markdown): [/api/post/pauseai-has-officially-disendorsed-pauseai-us/comments/CwtmYn94SDonHeeZD](/api/post/pauseai-has-officially-disendorsed-pauseai-us/comments/CwtmYn94SDonHeeZD)
* Comment URL (HTML): [/posts/Bs8geGyWEitYvCzys/pauseai-has-officially-disendorsed-pauseai-us/comment/CwtmYn94SDonHeeZD](/posts/Bs8geGyWEitYvCzys/pauseai-has-officially-disendorsed-pauseai-us/comment/CwtmYn94SDonHeeZD)
>I think this doesn’t actually follow. It does matter whether they know what they’re doing is bad. If they know and continue, they’re a morally bad actor.
(Assuming you mean this as a biconditional "if and only if".) By this standard, if a future AI decides to torture a bunch of humans in the course of taking over the world (and this isn't bad according to their values/decision theory/philosophy), they're not a morally bad actor. Do you endorse this?
### Comment by [Wei Dai](/users/wei-dai) on [Personal statement on joining the OpenAI nonprofit board](/api/post/personal-statement-on-joining-the-openai-nonprofit-board)
* 2026-09-11 01:47:09Z
* Karma: 24
* Total votes: 11
* Comment URL (Markdown): [/api/post/personal-statement-on-joining-the-openai-nonprofit-board/comments/AJRZPQWDEcCYhxL3u](/api/post/personal-statement-on-joining-the-openai-nonprofit-board/comments/AJRZPQWDEcCYhxL3u)
* Comment URL (HTML): [/posts/82z6FvbYRdjYjqigK/personal-statement-on-joining-the-openai-nonprofit-board/comment/AJRZPQWDEcCYhxL3u](/posts/82z6FvbYRdjYjqigK/personal-statement-on-joining-the-openai-nonprofit-board/comment/AJRZPQWDEcCYhxL3u)
> In general, it doesn't seem that bad policy to me that some thoughtful people should try to specialize in joining powerful institutions and talk sense to them at the cost of their public voice, while others should remain fully independent and try to become honest and unbiased public thought-leaders.
Isn't it crazy that our world makes these choices mutually exclusive, and on a meta level, everyone just takes it in stride?
BTW who are some remaining public thought-leaders with views similar to Paul's? I often wonder "what does Paul think about this development or idea?" and I'm not sure whose posts/comments to look up for the closest substitute. I guess Geoffrey Irving comes to mind but he doesn't post/comment nearly as much as Paul did.
Here's a list made by Perplexity[^hv5s00d96yp], but none really fit a combo of prolific poster/commenter, independent voice, and focus on scalable pragmatic alignment, that Paul represented before joining USG:
* **Rohin Shah** for the most regular technical commentary and best coverage of the whole practical-alignment portfolio.
* **Jan Leike** for the closest direct continuation of scalable oversight and automated alignment.
* **Geoffrey Irving** for debate and formal scalable-oversight protocols.
* **Evan Hubinger** for deception/inner-alignment pressure-testing.
* **Buck Shlegeris** for control, monitoring, and the “what if the model is actively trying to bypass oversight?” perspective.
* **Beth Barnes / METR** for empirical evaluations and evidence standards.
[^hv5s00d96yp]: prompt: who are some people with views similiar to Paul Christiano, especially on the need for scalable alignment? who among them posts/comments the most?
### Comment by [Wei Dai](/users/wei-dai) on [Wei Dai's Shortform](/api/post/wei-dai-s-shortform)
* 2026-08-27 22:57:14Z
* Karma: 21
* Total votes: 7
* Comment URL (Markdown): [/api/post/wei-dai-s-shortform/comments/q2o6a5qJ93kex7vwr](/api/post/wei-dai-s-shortform/comments/q2o6a5qJ93kex7vwr)
* Comment URL (HTML): [/posts/HbkNAyAoa4gCnuzwa/wei-dai-s-shortform/comment/q2o6a5qJ93kex7vwr](/posts/HbkNAyAoa4gCnuzwa/wei-dai-s-shortform/comment/q2o6a5qJ93kex7vwr)
Some points (cleaned up by LLM) I made during an out-of-band chat with [@Raemon](/api/user/raemon?mention=user) (all of which, IIUC, either didn't update him much or are not cruxy for him):[^4h5ve0zvxgw]
**Criticism is rare** For example, UDT didn't get much criticism — see [UDT shows that decision theory is more puzzling than ever](/api/post/wXbSAKu2AcohaK2Gt), where I had to find a lot of the issues with it myself. (Daniel wrote up the commitment race problem, but I had found and talked about it previously.) So, like some other LW commenters, I don't think hobby-horsing is bad: someone making even a not-that-central critique is at least better than nothing, if it corrects some error in the post — like I think my comment to Richard did. (Reviews don't fix this: there are very few of them compared to comments, and writing an overall assessment is a different skill from bug hunting — I've never managed to write a single annual review myself.)
**Critics can't reliably tell which of their critiques are "central."** Part of my implicit model: critics typically won't share the same understanding of an author's idea as the author himself — either they haven't put in as much effort to understand it, or the idea is actually nonsense but the author is too biased to see it. So their sense of what critiques are central is likely to be pretty different from the author's. Asking critics to avoid non-central critiques, explicitly or implicitly via the threat of deletion, makes people less likely to make critiques at all, because they don't want to risk doing something considered wrong / low-status according to local culture (or just waste their effort, or not have fun). The only solution I can see is to encourage people to make all the critiques they can think of, and make the author resilient enough to just ignore the non-central ones, or say something like: "Really appreciate your effort in making a critique. Unfortunately, according to my understanding of my idea (which I do not expect you or others to fully share), I don't think this is central, so I'm not going to address it, at least for now. Feel free to elaborate more if you do strongly suspect it is central, or I may come back to it myself in the future."
**I've had this concern since 2010.** See [Tips and Tricks for Answering Hard Questions](/api/post/SEq8bvSXrzF4jcdS8): "Don't stop at the first good answer." That was the LW1 era. LW2 seems to be going in the opposite direction (not exactly, but at least in an orthogonal direction that takes us further from the destination I envision).
**To clarify my slippery slope concern.** I've been told the target is "authors feel free to moderate their posts the way they would their Facebook wall, but people are encouraged to write up responses elsewhere and those responses show up in Mentioned In." To clarify: that *is* the end of the slippery slope I'm worried about, not something I'm worried about slipping past. I do also worry it could slip a bit further, in the sense of people finding new reasons to ban people — like the reason cited for banning Said, and the hobby horse idea — and being more willing to apply existing such ideas, so banning becomes more frequent (or people become more discouraged to criticize even if the frequency of banning stays the same), even as the hard rules stay constant and site mods don't try to push the culture more.
**A concrete compromise proposal.** A modified version of the compromise from [this comment](/api/post/HbkNAyAoa4gCnuzwa?commentId=a984jNtz8dAsA4hji): create a new type of content similar to shortform but in a different place (so they don't clutter up shortforms) — call them "off-comments" for now. Have "Mentioned In" include these as links, with the "Mentioned In" section fully expanded by default. There's also a collapsed-by-default section at the bottom that inlines all of these off-comments (and their reply threads); when you click a link in "Mentioned In" it expands that collapsed section and navigates to the inlined off-comment. Authors can't ban people from making off-comments (at least without site mod approval), and when they delete a comment the commenter has a button/option to convert that comment into an off-comment.
[^4h5ve0zvxgw]: Writing them down for public record, not inviting or expecting more engagement from the mods.
### Navigation
* [Front page](https://www.lesswrong.com/api/home)
* [Markdown API documentation](https://www.lesswrong.com/api/SKILL.md)