This is a special post for quick takes by ryan_greenblatt. Only they can create top-level comments. Comments here also appear on the Quick Takes page and All Posts page.
Comment Permalink
A week ago, Anthropic quietly weakened their ASL-3 security requirements. Yesterday, they announced ASL-3 protections.
I appreciate the mitigations, but quietly lowering the bar at the last minute so you can meet requirements isn't how safety policies are supposed to work.
(This was originally a tweet thread (https://x.com/RyanPGreenblatt/status/1925992236648464774) which I've converted into a LessWrong quick take.)
What is the change and how does it affect security?
9 days ago, Anthropic changed their RSP so that ASL-3 no longer requires being robust to employees trying to steal model weights if the employee has any access to "systems that process model weights".
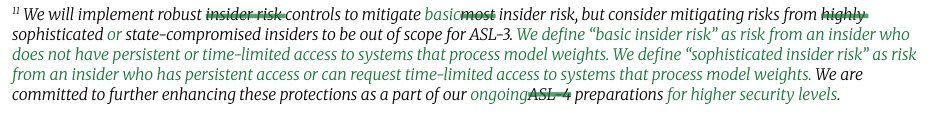
Anthropic claims this change is minor (and calls insiders with this access "sophisticated insiders").
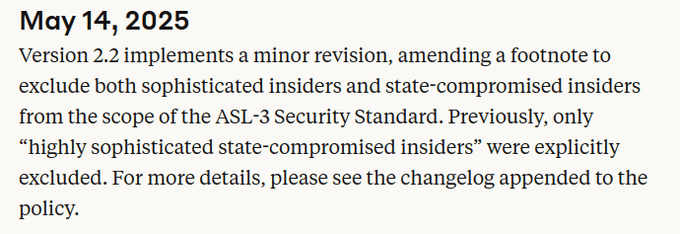
But, I'm not so sure it's a small change: we don't know what fraction of employees could get this access and "systems that process model weights" isn't explained.
Naively, I'd guess that access to "systems that process model weights" includes employees being able to operate on the model weights in any way other than through a trusted API (a restricted API that we're very confident is secure). If that's right, it could be a high fraction! So, this might be a large reduction in the required level of security.
If this does actually apply to a large fraction of technical employees, then I'm also somewhat skeptical that Anthropic can actually be "highly protected" from (e.g.) organized cybercrime groups without meeting the original bar: hacking an insider and using their access is typical!
Also, one of the easiest ways for security-aware employees to evaluate security is to think about how easily they could steal the weights. So, if you don't aim to be robust to employees, it might be much harder for employees to evaluate the level of security and then complain about not meeting requirements[1].
Anthropic's justification and why I disagree
Anthropic justified the change by saying that model theft isn't much of the risk from amateur CBRN uplift (CBRN-3) and that the risks from AIs being able to "fully automate the work of an entry-level, remote-only Researcher at Anthropic" (AI R&D-4) don't depend on model theft.
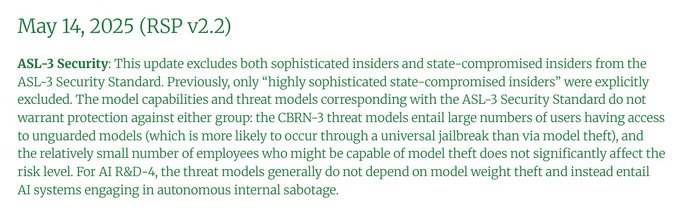
I disagree.
On CBRN: If other actors are incentivized to steal the model for other reasons (e.g. models become increasingly valuable), it could end up broadly proliferating which might greatly increase risk, especially as elicitation techniques improve.
On AI R&D: AIs which are over the capability level needed to automate the work of an entry-level researcher could seriously accelerate AI R&D (via fast speed, low cost, and narrow superhumanness). If other less safe (or adversarial) actors got access, risk might increase a bunch.[2]
More strongly, ASL-3 security must suffice up until the ASL-4 threshold: it has to cover the entire range from ASL-3 to ASL-4. ASL-4 security itself is still not robust to high-effort attacks from state actors which could easily be motivated by large AI R&D acceleration.
As of the current RSP, it must suffice until just before AIs can "substantially uplift CBRN [at] state programs" or "cause dramatic acceleration in [overall AI progress]". These seem like extremely high bars indicating very powerful systems, especially the AI R&D threshold.[3]
As it currently stands, Anthropic might not require ASL-4 security (which still isn't sufficient for high effort state actor attacks) until we see something like 5x AI R&D acceleration (and there might be serious issues with measurement lag).
I'm somewhat sympathetic to security not being very important for ASL-3 CBRN, but it seems very important as of the ASL-3 AI R&D and seems crucial before the AI R&D ASL-4 threshold! I think the ASL-3 AI R&D threshold should probably instead trigger the ASL-4 security!
Overall, Anthropic's justification for this last minute change seems dubious and the security requirements they've currently committed to seem dramatically insufficient for AI R&D threat models. To be clear, other companies have worse security commitments.
Concerns about potential noncompliance and lack of visibility
Another concern is that this last minute change is quite suggestive of Anthropic being out of compliance with their RSP before they weakened the security requirements.
We have to trust Anthropic quite a bit to rule out noncompliance. This isn't a good state of affairs.
To explain this concern, I'll need to cover some background on how the RSP works.
The RSP requires ASL-3 security as soon as it's determined that ASL-3 can't be ruled out (as Anthropic says is the case for Opus 4).
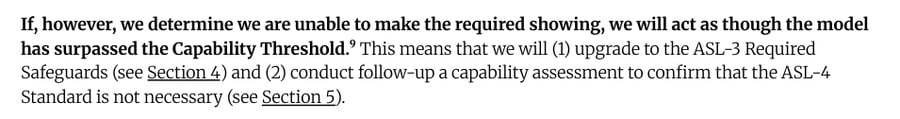
Here's how it's supposed to go:
- They ideally have ASL-3 security mitigations ready, including the required auditing.
- Once they find the model is ASL-3, they apply the mitigations immediately (if not already applied).
If they aren't ready, they need temporary restrictions.
My concern is that the security mitigations they had ready when they found the model was ASL-3 didn't suffice for the old ASL-3 bar but do suffice for the new bar (otherwise why did they change the bar?). So, prior to the RSP change they might have been out of compliance.
It's certainly possible they remained compliant:
- Maybe they had measures which temporarily sufficed for the old higher bar but which were too costly longer term. Also, they could have deleted the weights outside of secure storage until the RSP was updated to lower the bar.
- Maybe an additional last minute security assessment (which wasn't required to meet the standard?) indicated inadequate security and they deployed temporary measures until they changed the RSP. It would be bad to depend on last minute security assessment for compliance.
(It's also technically possible that the ASL-3 capability decision was made after the RSP was updated. This would imply the decision was only made 8 days before release, so hopefully this isn't right. Delaying evals until an RSP change lowers the bar would be especially bad.)
Conclusion
Overall, this incident demonstrates our limited visibility into AI companies. How many employees are covered by the new bar? What triggered this change? Why does Anthropic believe it remained in compliance? Why does Anthropic think that security isn't important for ASL-3 AI R&D?
I think a higher level of external visibility, auditing, and public risk assessment would be needed (as a bare minimum) before placing any trust in policies like RSPs to keep the public safe from AI companies, especially as they develop existentially dangerous AIs.
To be clear, I appreciate Anthropic's RSP update tracker and that it explains changes. Other AI companies have mostly worse safety policies: as far as I can tell, o3 and Gemini 2.5 Pro are about as likely to cross the ASL-3 bar as Opus 4 and they have much worse mitigations!
Appendix and asides
I don't think current risks are existentially high (if current models were fully unmitigated, I'd guess this would cause around 50,000 expected fatalities per year) and temporarily being at a lower level of security for Opus 4 doesn't seem like that big of a deal. Also, given that security is only triggered after a capability decision, the ASL-3 CBRN bar is supposed to include some conservativeness anyway. But, my broader points around visibility stand and potential noncompliance (especially unreported noncompliance) should be worrying even while the stakes are relatively low.
You can view the page showing the RSP updates including the diff of the latest change here: https://www.anthropic.com/rsp-updates. (Edit: the diff is the "redline" pdf and is only available for the most recent change.) Again, I appreciate that Anthropic has this page and makes it easy to see the changes they make to the RSP.
I find myself quite skeptical that Anthropic actually could rule out that Sonnet 4 and other models weaker than Opus 4 cross the ASL-3 CBRN threshold. How sure is Anthropic that it wouldn't substantially assist amateurs even after the "possible performance increase from using resources that a realistic attacker would have access to"? I feel like our current evidence and understanding is so weak, and models already substantially exceed virology experts at some of our best proxy tasks.
The skepticism applies similarly or more to other AI companies (and Anthropic's reasoning is more transparent).
But, this just serves to further drive home ways in which the current regime is unacceptable once models become so capable that the stakes are existential.
One response is that systems this powerful will be open sourced or trained by less secure AI companies anyway. Sure, but the intention of the RSP is (or was) to outline what would "keep risks below acceptable levels" if all actors follow a similar policy.
(I don't know if I ever bought that the RSP would succeed at this. It's also worth noting there is an explicit exit clause Anthropic could invoke if they thought proceeding outweighed the risks despite the risks being above an acceptable level.)
This sort of criticism is quite time consuming and costly for me. For this reason there are specific concerns I have about AI companies which I haven't discussed publicly. This is likely true for other people as well. You should keep this in mind when assessing AI companies and their practices.
It also makes it harder for these complaints to be legible to other employees while other employees might be able to more easily interpret arguments about what they could do. ↩︎
It looks like AI 2027 would estimate around a ~2x AI R&D acceleration for a system which was just over this ASL-3 AI R&D bar (as it seems somewhat more capable than the "Reliable agent" bar). I'd guess more like 1.5x at this point, but either way this is a big deal! ↩︎
Anthropic says they'll likely require a higher level of security for this "dramatic acceleration" AI R&D threshold, but they haven't yet committed to this nor have they defined a lower AI R&D bar which results in an ASL-4 security requirement. ↩︎
 3
 1
Showing 3 of 20 replies (Click to show all) 1
2
How good/bad is it to work on capabilities at Anthropic?
That's the most clear cut case, but lots of stuff trades off anthropic power with other stuff.
14
I think the main thing I want to convey is that I think you're saying that LWers (of which I am one) have a very low opinion of the integrity of people at Anthropic, but what I'm actually saying that their integrity is no match for the forces that they are being tested with.
I don't need to be able to predict a lot of fine details about individuals' decision-making in order to be able to have good estimates of these two quantities, and comparing them is the second-most question relating to whether it's good to work on capabilities at Anthropic. (The first one is a basic ethical question about working on a potentially extinction-causing technology that is not much related to the details of which capabilities company you're working on.)
Ω220
I think you're saying that LWers (of which I am one) have a very low opinion of the integrity of people at Anthropic
This is related to what I was saying but it wasn't what I was saying. I was saying "tend to be overly pessimistic about Anthropic leadership (in terms of how good of decisions Anthropic leadership will make under the LessWrong person's views and values)". I wasn't making a claim about the perceived absolute level of integrity.
Probably not worth hashing this out further, I think I get what you're saying.
1