You may already be aware of this, but this perspective is very compatible with singular learning theory (which is all about functional equivalence of weight and its consequences for statistical learning). In fact, the work of Murfet and Troiani on “Programs as singularities” applying SLT to a particular model of noisy Turing machines (https://arxiv.org/abs/2504.08075) and the recent follow-up https://arxiv.org/abs/2609.04661 are in part motivated by noisy Turing machines being a first attempt at a model of noisy computation where the learning process can be analysed mathematically in the Bayesian large data limit. Now, noisy Turing machines arising as perturbations of a classical one may be too close to the circuit ontology for your purpose, but they are a tractable starting point. It would be very interesting imo to apply SLT (either formally or as a guiding intuition) to other models of noisy/diffusive computation.
Hmm interesting - I tentatively agree that the noisy TM formulation isn't quite the thing I'm looking for, but perhaps this is just vibes and it is a good approach to the same ideas from within the normal CS ontology.
My doubt about applicability would be about how we natively write good noisy TM programs that take advantage of the same sorts of effects that evolution (and SGD?) do? In particular, the 'static discipline' of digital circuit design is in some sense already the human answer to this - we design away the noise. But this I think is more fundamental than a problem with noised TMs per se.
Though on the other hand, if you posit some sort of noise you do get lots of good information-geometry tools with identifiability and such - and I guess if you wanted to go whole-hog, noisy-TMs are equivalent to a certain kind of stochastic control system. I thought a while back about how to try and infer noisy-TM execution rules from observed execution traces using spectral/Hankel-y methods, but it ended up being very hard to get anything useful since TMs are so expressive, and claude started telling me I need complicated matrix completion problems I don't really want to learn about yet, lol...
As for SLT, local flatness definitely matters to this phenomenon, but I don't have a fine enough view to say what we'd learn from the RLCT as against e.g. a suitably noise-averaged Hessian or eNTK. One avenue might be to compare to something like dynamical systems with a bunch of attractors and see if you can relate attractor structure to local flatness? Perhaps this'd work with diffusion models?
As for SLT, local flatness definitely matters to this phenomenon, but I don't have a fine enough view to say what we'd learn from the RLCT as against e.g. a suitably noise-averaged Hessian or eNTK.
In practice, the main difference is that SGLD sampling just actually checks how large the local solution volume is instead of relying on leading order terms to guess like the Hessian.
So neural networks have some analogue of this representational drift problem, at least by default. You can hypothesise that the various effective penalties will cause the network to enter the regime where it can just encode stuff at the weights level without needing to worry about it moving around - it definitely does get progressively flatter! But this adds an extra hypothesis which I've found it hard to justify - that 'more noise robust' should for some fundamental reason correspond to circuits in any functional sense.
I think the drift at zero loss is a mix of a couple of different things.
- Movement along irrelevant coordinates. Networks rarely use up all their theoretically available effective degrees of freedom. We don't train long enough or well enough for that. There's typically a decent amount left over, hence why you can compress networks somewhat without hurting performance all that much via ablation of Hessian KFAC directions, quantisation, or even ablation of raw weights in the standard basis of the network. See SLT. I think this effect is way weaker in real networks people put serious effort into training, such as LLMs, than it is in the toy networks pruning results are often reported on, but it's still there. My guess is even current frontier models would still be somewhat prunable substantial performance loss, though I haven't checked that. You could call this drift between different implementations of the same circuit if you wanted to, but I think that framing is a little misleading. I think it's often really more like we're wiggling around unused degrees of freedom while the occupied ones stay exactly the same.
- Movement between different solutions, for example as in grokking. Here the drift isn't moving you between different implementations of the same circuit, it's moving you from implementing one circuit to a totally different (often better) behaviour off-distribution.
which means that probably neural networks should want to distribute functionality and representation as broadly as possible. If you're thinking about features, this leads you to think about superposition, which I think everyone is on board with.
Disagree. If you want distributed functionality you want redundancy, not superpositon. These are basically opposite concepts. Redundancy gives you higher noise robustness than you have in the standard basis encoding by sacrificing representational capacity. Superposition gives you higher representational capacity[1] than you have in a standard basis encoding at the cost of lower noise robustness.
- ^
with a lot of restrictions
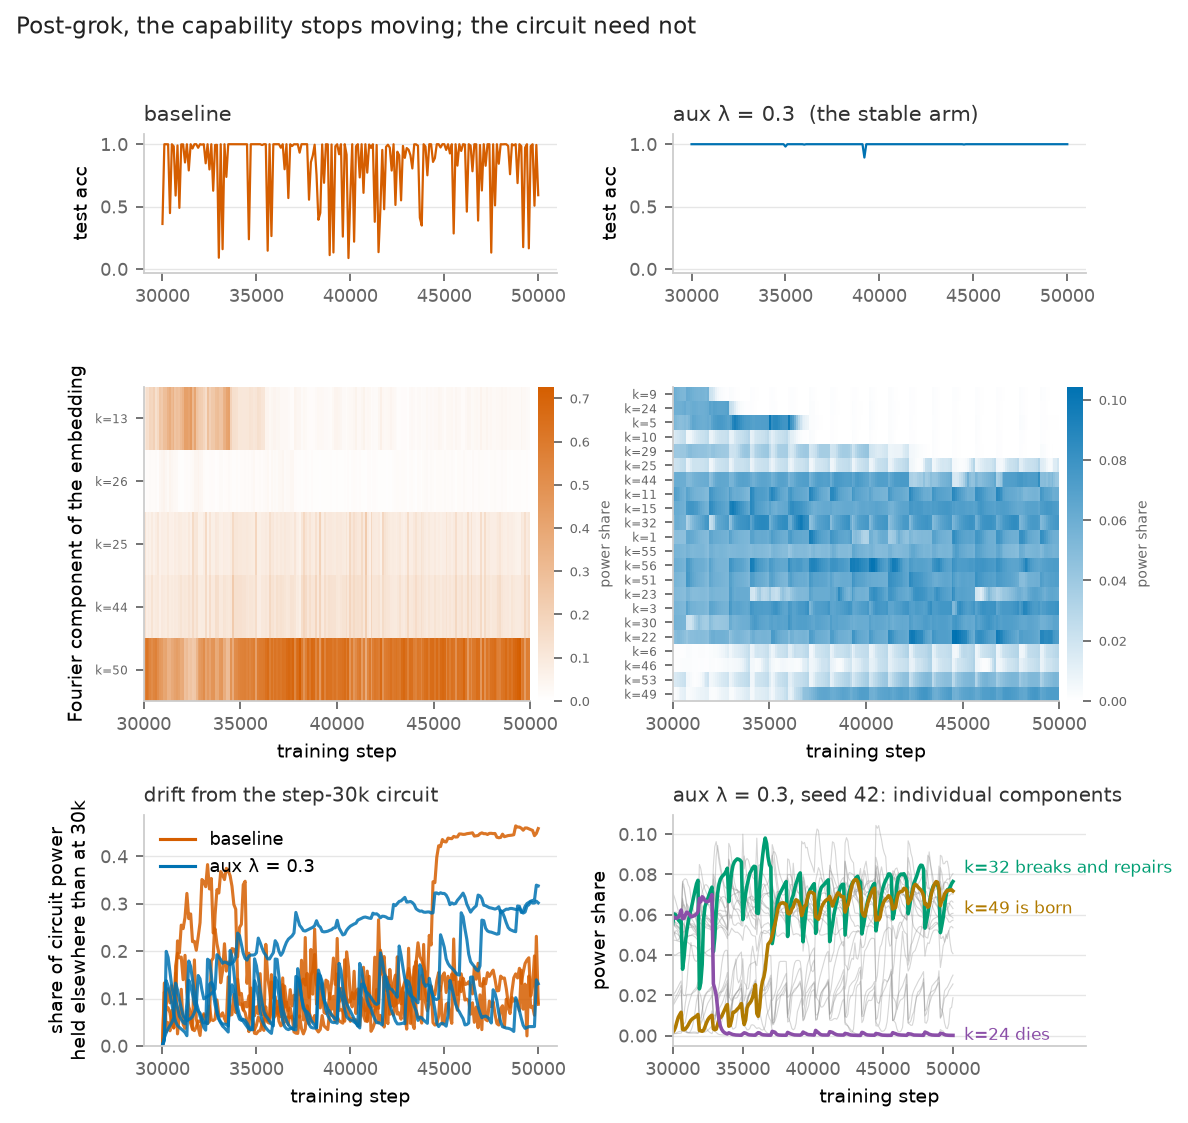
I've been working on a somewhat relevant experiment to this, although I haven't written it up. I noticed that in Neel Nanda's grokking setup, it becomes unstable if you extend it to multiple layers and add LayerNorm. If you add an aux loss term pushing every layer to have the final answer in the logit lens[1], the capability ends up much more stable but the implementation changes constantly.
This post made me curious, and zooming all the way in on neurons we end up with significant turnover while the eval accuracy sits at ~100% the entire time.
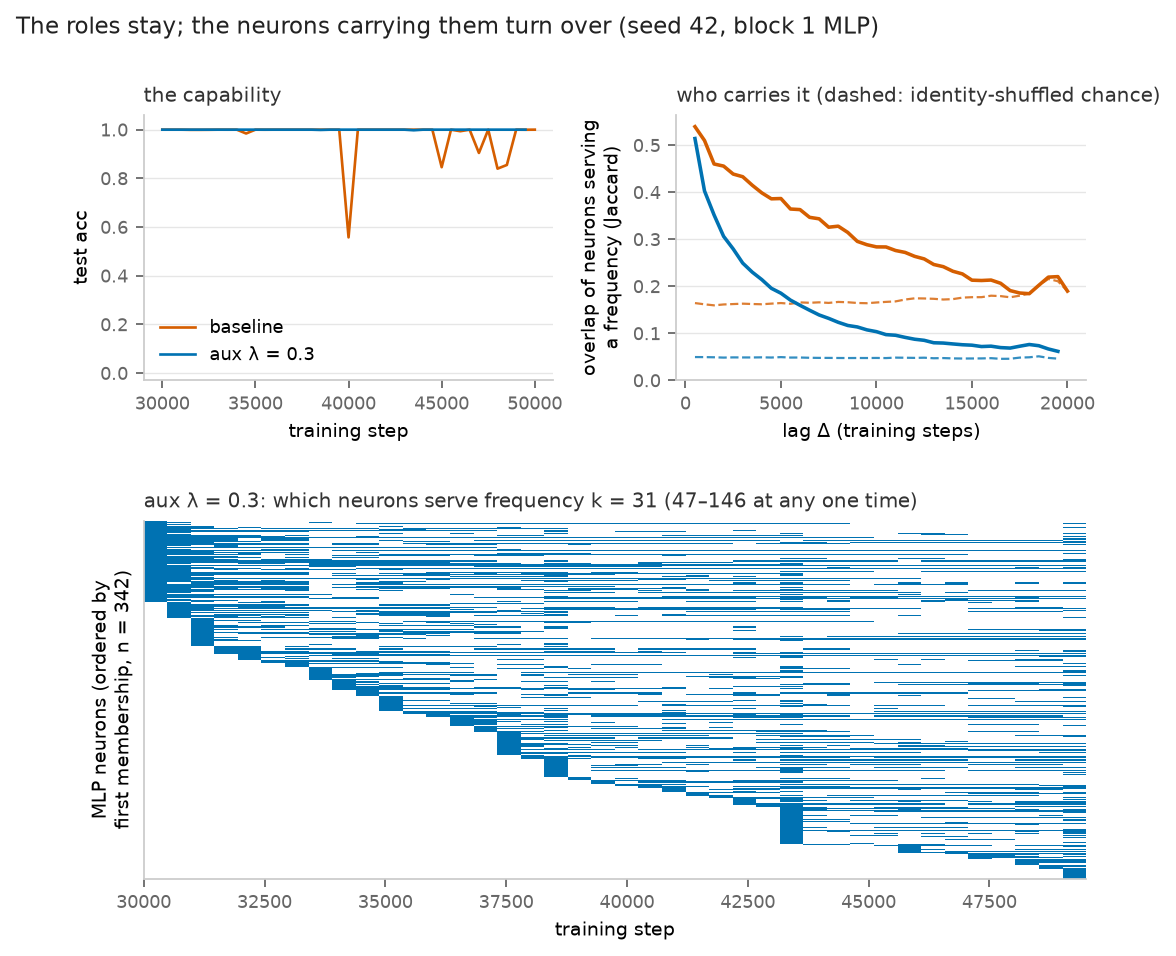
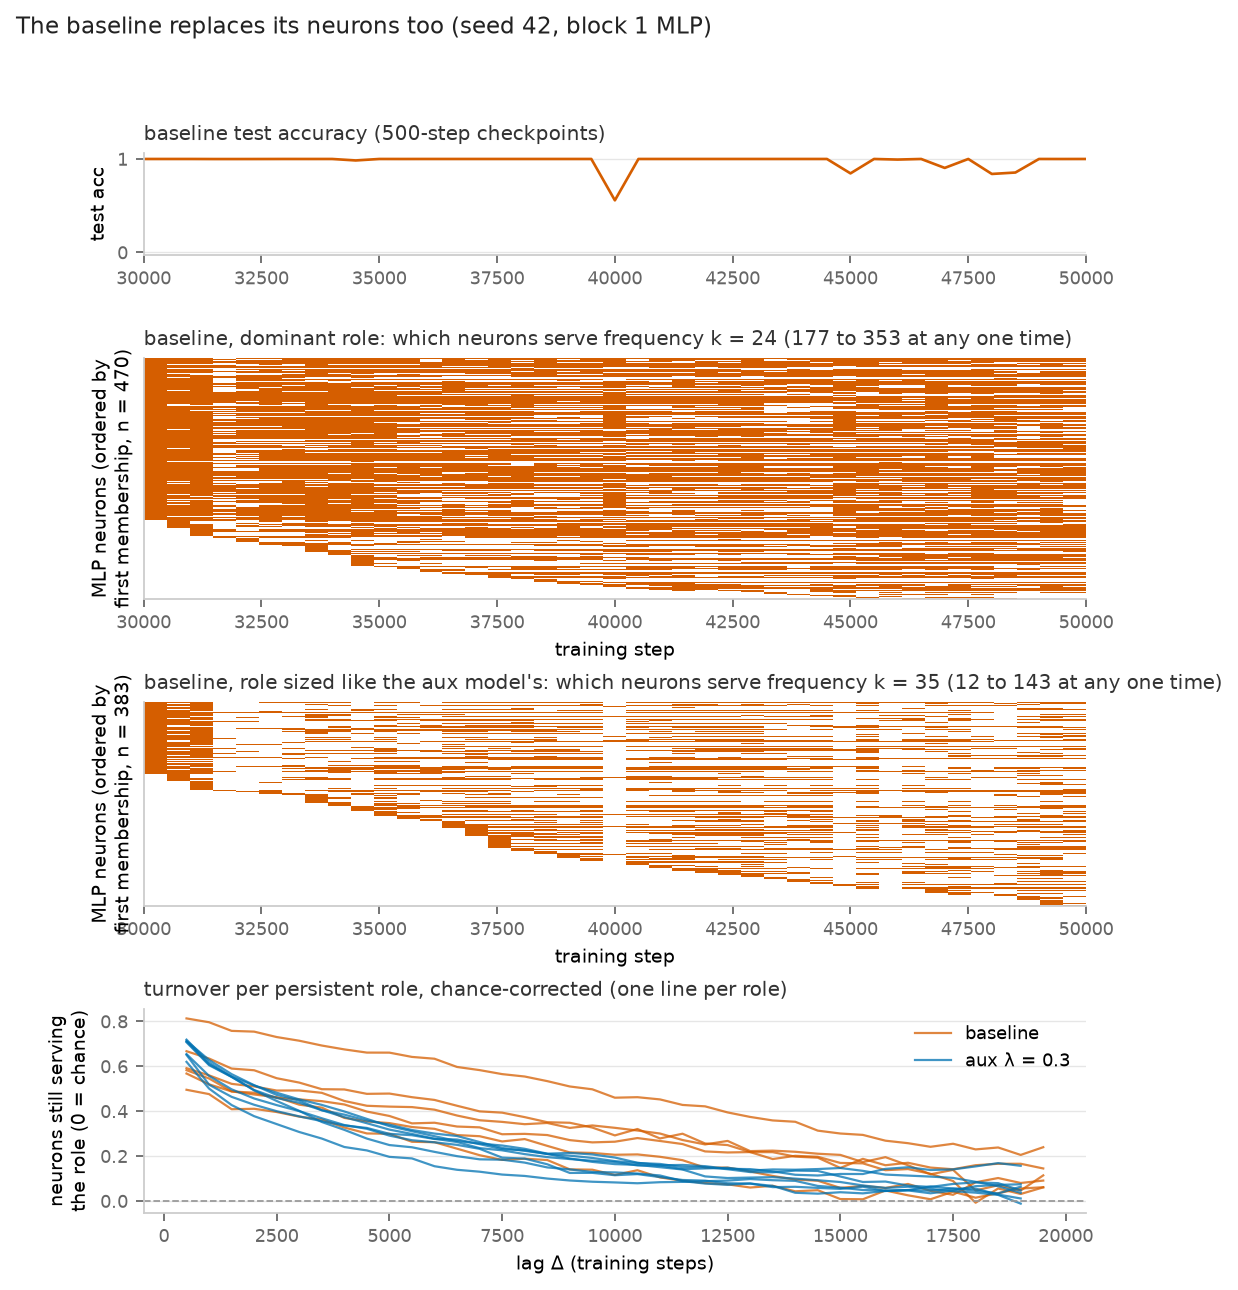
The baseline model's frequencies are more stable, but it still replaces neurons over time.
Frequencies over time
Sorry about how dense this is, but the modular arithmetic circuit is implemented with frequencies in the embeddings, and the standard model concentrates almost everything on one frequency (k=50 in this seed). My aux loss model uses a lot more frequencies, but switches which ones over time.
Baseline model's neurons over time
- ^
This probably sounds like a weird thing to try, but I was originally curious if this "logit lens loss" would prevent the model from grokking at all, and then ran into this more interesting results. I doubt there's anything special about the aux loss I happened to used here.
A 'coherent structure' in fluid mechanics is some bounded volume of fluid such that the boundary doesn't move wildly and that there isn't too much mass flow across it over time.
Hey, this is great! I'd like to connect this a little to speciation theory (bringing it back to your previous post on selection for selectability).
When differentiating populations interact, their alleles "flow" into each other, so there's a tension between maintaining adaptations to form new niches and still having access to a population to breed with (instantly speciating is hard to do successfully).
So as speciation happens, the bits of the genome that are most important for niche adaptation (in theory) remain differentiated, and the rest gets washed out. These are called "barrier loci" because they prevent interbreeding. Over a long enough time period, everything looks like a barrier locus because mutations accumulate, but for very recent speciation the loci are obvious peaks. They're sometimes referred to as "islands of differentiation" for this reason (but the correct interpretation of islands of differentiation is still controversial).
In my view, this is close to your theory, marred by the fact that in both cases this flow is very difficult to see:
Neurally: weights -> activations -> behaviour -> loss
Biologically: genomes -> phenotypes -> niches -> fitness
But I suspect they are the same fundamental phenomenon. Happy to chat more if this interests you.
Nice! I think I'd need to read more to comment on if there is an ML adapted version that doesn't rely on allele flow. Thanks for the pointer!
A prelimnary thought:
I had looked a tiny bit before at ecology, and in fact the 'paradox of the plankton' and related ideas is one thing that updated me against a naive neural darwinist view of circuits 'competing each other to extinction', and towards a view where circuits getting outcompeted looks more like them specializing to a slightly smaller niche than them dying. This aligns more with a view of 'models as bags of heuristics' - but I'm trying to think how to get a more substantive version of that idea that lets us make progress and not just shoulder-shrug.
I think you already have your answer here! (Bear with me for recreating the latex and handwaving)
I think this is an example of the storage effect due to minibatch variation. The variation in minibatches is not random in the sense of iid, it's highly structured (and at least for LLMs, the data is so large we can't even estimate the extent of this structure). As long as the circuit is useful in the stationary distribution of the loss, it will persist - although I don't have a good sense of the mean and variance in circuit turnover which would bound any storage effect.
In general, I think ecological effects on evolution are like minibatch effects, but this theory of mine is quite handwavey. If only we were closer to a general solution.
Thanks for writing down and making concrete a lot of intuitions I had about the linear representation and circuit hypotheses being "slightly off" in some way. This article may be interesting, or at least the linked paper: https://picower.mit.edu/news/cognition-and-consciousness-arise-analog-computations-says-new-theory
Note here I mean persistence selection rather than real Darwinism - circuits don't have offspring.
This seems like a rich vein. Circuits may not have literal offspring, but it does seem that they can propagate in many other senses, ranging from pure conceptual reorganization all the way through agentic, coalitional bargaining.
For example, I have the concept of a "domesticated animal". This is a concept that not only usefully organizes my extant knowledge of the world (e.g. explains why cows, pigs, horses and chickens have many otherwise puzzling traits), but can be expanded to incorporate new instances (I can see an alpaca for the first time and make non-trivial predictions about it on the basis of the fact that it's domesticated). What's more, I can look at a wild animal like a fox or a walrus and ask: "what if we domesticated them?" So it seems the concept of domestication has some sort of tendency to "gather all things to itself" and, in the limit, alter the world in such a way that the concept of domestication becomes more salient / important.
At the other end of the spectrum, consider a circuit that implements a behavior like "desire heroin". Such drives can "gain power" over individuals by forming neural coalitions held together by credit-sharing the opiodergic reward. These can orchestrate sophisticated behavioral strategies like "inject heroin with a hypodermic needle", "commit crimes in order to obtain money and exchange it for heroin", or even "precommit to ignoring messages friends and family members who might dissuade you from doing heroin", and so on. So much so that addicts very naturally personifiy their addictions and speak of mentally bargaining with them. Again, this is not literal biological reproduction of the "Desire Heroin" circuit, but certainly some kind of influence-seeking phenomenon at some level.
Yes! I have explored 'resource-consumer' like models in thinking about ecologies of circuits.
I'm hoping to have this integrated into another writeup later, but I think one can at least write a story where early-in-the-network circuits try to compute features which are robustly useful to many downstream consumers (so it robustly gets favorable gradient) - then by virtue of having monopsony power, that circuit de facto chooses to make a particular linear direction 'theirs'. In the limit, this might account for the sort of "API contract" that make up the set of linear features - the network agrees that certain directions mean certain things.
I think though that accounting for action at the agent/behavioural level is a bit different than the story I can tell right now. In principle you might think of it as hierarchical self-organization of circuits into subminds, which then compete etc. Your 'concept makes itself salient' seems important - Heidegger's 'Gestell', or the Greeks' "those who know the words see twice as much". But it seems hard to me to think about concepts as tools of cognition vs concepts as self-organized agents - I think for me at least it'd take a lot more mechanical knowledge of cognition to do this with sufficient care.
For now I think I'm not ready to think about something like the difference between credit-assignment for behaviour vs. backprop from next-token-prediction. I think credit-assignment may be an important thing to understand better about the brain, since it is so extremely different from backprop.
Put another way, suppose arguendo an LSTM and a transformer learn essentially the same function on some given data, and that this is essentially true for a wide range of tasks we're considering. Then our explanation of what they have learned should be symmetric between them.
Why? If the same function is implemented in two materially different ways, shouldn't the explanations reflect this? What if the LSTM learns "grade school" multiplication and the transformer learns Karatsuba?
Ah yes sorry, here I was assuming by hypothesis that they learn the same algorithm in a suitable-but-still-modified-for-architecture sense. Its of course possible that they could learn to implement different algorithms, and presumably the architecture there would matter quite a bit.
Here I have in mind more the human brain, and how the genomic bottleneck means that its development has to be orchestrated in a way that probably-mostly-most-of-the-time is essentially implementing the same functionality. Whether or not that functionality is implemented by the same algorithm (i.e. if the developmental process has multiple meaningfully different attractors) is another question - I personally expect our notion of 'different algorithm' to break down here and would need to think further about how to account for important functional differences.
This post seems to agree with many of my intuitions while having a better technical foundation, so I'm largely commenting so that I can return to this later and read more closely.
On co-selection: this is roughly the point of view I expect to work, and certainly the one I've spent the most time thinking about. My feeling is that the units here should basically live in weight space, but that they can't be thought of as discrete entities and their fitness function is extremely dependent on the dataset, potentially even order effects in the early training data.
It's hard for me to describe what I mean here, and I've tried to type this three times without getting a description I'm happy with, so I'll just gesture and be imprecise: I think the natural question is not just "how will the model partition this task into subtasks" but also "where will it decide to put all those partitions". There are an unfathomable number of ways to turn any circuit decomposition you could imagine into different weight sets, and so the fitness of a particular circuit (which I think of as a connected full subnetwork, there's some weird linear algebra here) depends on its position in the model, its initialization, and crucially the fitness of all of the other circuits that might want to use its parts or might compete for the same function in the full model. This last factor is so nonlocal as to make local analysis seem hopeless.
(I think the above is most relevant to your section III writing. I think I basically agree with what you write there and we may be saying the same thing, but our conclusions seem different enough that I suspect I'm missing something that you've already understood.)
And some questions: do you happen to have a list, prepared or off the top of your head, of experiments/exercises/papers you'd credit for the technical understanding that you have here? Have you thought about nonlinear representations/off-manifold behavior in this context? (Like, if I scrub away a direction that isn't actually a feature direction, and so in the middle of inference the model's thoughts are not just changed but in some sense scrambled, what should happen?) These ideas kept coming to mind when I was thinking harder about this stuff, but I never figured out what connection I was reaching for. In particular, for off-manifold activations, I think the question I want to ask is, how robust should a trained model be to scrubbing of this sort, if this co-selection model works?
This post was written as part of the Iliad Fellowship. Inspired by conversations with Richard Ngo, Dmitry Vaintrob, and Brianna Grado-White. To all of these, my thanks.
Preface: I'm confused about how neural networks do and learn computations. In response to a friend's challenge, I'm writing up some interim thoughts. This essay has four parts: the first tries to track what I call the 'default ontology' of the mechinterp community over the years. The second part is about 'representational drift' as an important obstacle to weights-based approaches to circuits. The third part reflects on how 'universality' should shape our explanations of LLM function. The fourth part is a sketch of a 'co-selectionist' view of circuits I have been thinking about. These parts share a common theme but should be readable separately.
I want to understand how neural networks, LLMs in particular, work. In my research I've spent a lot of time trying to think through what kinds of explanatory accounts are best suited to this. In thinking about comparisons between evolution, neuroscience, and deep learning, I've ended up with an intuition like the following:
This post is an attempt to communicate what I mean (part I), why I have this intuition (parts II and III). Part IV is a sketch of a perspective on circuits as emergent 'units of selection'.
Contents
I. What Might We Mean By "Circuits"?
I.A. Definitions
Definitions are important - here I'll lay out what I think are the core components of the circuit ontology. The central thesis is something like:
There are a lot of live variants. The most important axes of variation that come to mind are:
First, note that the question of circuits is in principle distinct from theories of representation - the latter being 'feature directions', the 'linear representation hypothesis', etc.
Second, note that these questions are definitional as much as they are pragmatic - we're jointly unsure of what a 'circuit' should be and how to look for them.
I.B. Circuits, Features, and MechInterp
Here I'll give a rough account of how I see the interp community's 'default ontology' as having changed over time. I think this is useful because it relates what kinds of structure we thought neural networks have to how we went looking for them.
I think of things as proceeding in roughly three phases, which I'll call the 'exploratory', the 'mechanistic', and the 'prosaic'. Alternatively, we might call these 'worldviews'. The sketch below is more intellectual autobiography than history, has no pretension to completeness etc., so cum grano salis.
By 'exploratory', I essentially mean 'look at the neural network, and poke it and see if you can make sense of what it's doing'. This work had rather little conceptual baggage attached to it - it was less about 'how can we understand the model-qua-gestalt' but instead 'can we find anything understandable at all'. It seems important that during this era, 'neural networks are just inherently uninterpretable messes' felt like a live hypothesis. I think the best examples are things like Chris Olah's pre-transformer-circuits work (see his blog here) and also the Distill circuits thread. [3]
I would also tentatively put the earliest mechinterp work in this category. E.g., the early induction heads work essentially avoided the 'semantic bootstrap' problem I mentioned above - that of needing to jointly assign semantic meaning to circuits' operations and their inputs/outputs. Their induction head metric is essentially operational - an eigenvalue statistic [4] - and their analysis would have worked as well on transformers which predict sheet music instead of text.
With the advent of the LLM era, we moved towards what I'll call the 'mechanistic' era - we finally got models that fucking have to be 'thinking' for some definition of that word, and we wanted to figure out how. I don't think anyone seriously thought they had the theory of understanding neural networks, but I think the spirit of this era was that we were looking for it. This was the era of sparsity, mechinterp, and SAEs.
The most important organizing principle people posited was 'sparsity' - the idea that for most datasets, the most natural way to compress them was to learn a big conceptual dictionary, such that a sparse subset of these would be active at any given time. The best articulation of this idea I'm aware of is this note in the transformer circuits thread, which does a very good job tying together the intuitions from neuroscience and sparse sensing. This line of thinking leads to SAEs and descendants. The SAE vision focused less on circuits or computation, than on 'feature directions' in the residual stream.
Essentially all [5] of the later transformer-circuits thread research built on the conceptual foundation of linear representation, superposition, sparsity, etc. The apotheosis of the SAE vision is 'scaling monosemanticity'. Following this, Anthropic's interp team tried harder to focus on computation and what gets 'done' with features, resulting in the transcoders and 'biology' work. These are extremely cool, but also, in my opinion, go quite a bit further than SAEs in 'imposing' an ontology on a model - they train, layer-by-layer, a sparse replacement for the base model, replacing each MLP layer by a much larger layer of sparse neurons with more permissive (cross-layer) connectivity.
Separate from the SAE-driven cluster of things, there is also an ongoing tradition of very gears-level mechinterp. Good examples of what I have in mind are things like 'logit lens', automated circuit discovery, etc. This 'gears-level' mechinterp is certainly 'mechanistic', but I would feel disingenuous slotting it into one of my three arbitrary worldviews/eras here - I think looking for circuits assumes less about what's going on inside than do SAEs. Redwood's causal scrubbing was an early negative result on this approach. [6]
This 'mechanistic' era gave way to the 'prosaic' around the time that the GDM mechinterp team published 'negative results for SAEs'. Anthropic's interp work since 'biology' has largely focused on pragmatic interpretability for really large language models - training various interpretable surrogates, interpreters, or empirical studies of LLM behaviour. I think it's fair to say that the field (at least at the frontier) drifted away from work on a "fundamental" science of interpretability - from neuroscience to biology and psychology. [7]
'Prosaic' interpretability is based on the idea that LLMs are fucking complicated, possibly unstructured in important ways, and 'fundamental' interpretability either can't or won't get us to useful tools before we need them for alignment. I think of this era as crystallizing with Neel and co.'s 'pragmatic vision', which gave us the 'pragmatic/ambitious interp' dichotomy. Things like natural language autoencoders (NLAs) are especially characteristic of this era - I recall them being described as 'bitter-lesson-pilled interp'. The spirit of the era is training big interpretable ML models on top of big ML models.
To the extent this era has a 'default ontology', it's that interpretability is essentially machine-learning complete, or perhaps that there aren't (or we can't find) faithful useful accounts of model internals at scale - at least not fast enough to be useful for alignment. On a slightly different reading, the default ontology could also be that 'interpretability' is essentially orthogonal to functionality - that LLMs are a big ol' mess in the way we once feared was true of AlexNet, and that interpretability is thus not a problem to be solved, but an additional desideratum.
So in summary, there are a handful of different ways of thinking about what structures neural networks learn. There are exploratory methods which are reasonably structure-agnostic, circuit-discovery methods, feature-interaction methods, looping back around to structure-agnostic surrogate-model methods. These all come from different ideas of 'where the structure is' in neural networks. Next I'll talk about representational drift and why I think this suggests the need to 'look somewhere else' for the fundamental units of computation/structure.
II. The Central Problems of Noise and Representational Drift
Figure: representational drift, and also cats. Sure. From 'Statistical learning and representational drift: a dynamic substrate for memories'.
II.A. Representational Drift in the Brain
The main idea from neuroscience that updates me against thinking of 'circuits' as residing in a fixed set of weights is that of 'representational drift'. Disclaimer: I'm acting as a synthesist here, not a neuroscientist; I still have much to learn here.
There is in neuroscience a notion of something called an 'engram' - roughly, a localizable 'trace' of having learned some particular thing; the mouse learns the maze, and you circle some neurons where the knowledge of the maze is stored. This is intuitive and I'd be surprised if it was uniformly wrong, but there's more to it.
Instead there is something called 'representational drift' - you run the mouse through the maze, and you circle the neurons where that maze knowledge is etc. - but then you find that that localization is not stable over time. The population of neurons which encode that knowledge seems to migrate around over the timescale of days to weeks. Iiuc this is fairly random motion, rather than 'memories migrate predictably as they age', though that probably happens somewhere too.
This feels fucky because if stuff just moves around at random, how does the brain track it to know how to access it? But I claim this is actually rather natural once you think about the design problem the brain faces - in particular, the problem of plasticity.
Plasticity management is one of the deep problems the brain has to solve - you have to manage activity on many different space- and time-scales in order to preserve both representational capacity and the ability to continually learn. Too much overall activity in a region means you lose information in the noise, and too much rigidity means you can't learn things anymore, nor can you readily adapt your firing rules to the population.
Imagine you wanted to inscribe some fact in the synapse weights of a group of neurons - you have two problems. One: since there needs to be at least short-timescale regulation of each neuron (if the community's average firing rate isn't regulated, you lose signal, and also maybe have a seizure), your encoding can't depend on very precise values of the weights - it'll have to be encoded diffusely, and since there's always noise, probably redundantly. Two: even once you've done that encoding, you do still need to leave those synapses open for long-term plasticity in case new, more important information comes in, or some of the neurons in your circuit are part of another circuit with interfering updates, so you need to jiggle some stuff around. So by engineering fiat, the brain mostly can't be acting like a von Neumann computer with variables stored at some address with particular access wires. The dynamics of operating a functional brain means the system needs to let 'addresses' of 'facts' move, and once they're allowed to 'move', it's natural to let them move by default. [8] Your learning algorithm will just adapt.
II.B. Representational Drift in Neural Networks
I expect this picture to apply to neural networks at both the micro and macro levels. Here I'll give some concrete ways we know it holds at the micro level. I'll note one could assent to these microscopic phenomena and still expect macroscopically fixed functional units.
Fixing some low level of loss, there remain a drift and a diffusion component causing nonzero motion in the parameters.
When you add noise, you get an effective loss like (see this paper for GD and this one for SGD)
where
Even at equilibrium, you can use the 'fluctuation-dissipation relations for SGD' to show
and
(here
So neural networks have some analogue of this representational drift problem, at least by default. You can hypothesise that the various effective penalties will cause the network to enter the regime where it can just encode stuff at the weights level without needing to worry about it moving around - it definitely does get progressively flatter! But this adds an extra hypothesis which I've found it hard to justify - that 'more noise robust' should for some fundamental reason correspond to circuits in any functional sense.
So to summarize, the brain can't plop information down at known addresses and re-access it like a von Neumann computer, because noisiness favors diffuse encoding and plasticity favors gradually-migratable encodings. There are similar-ish phenomena in neural networks that come from effective loss terms caused by noise, so we can be relatively sure that parameters will always be moving, at least a bit - which means that probably neural networks should want to distribute functionality and representation as broadly as possible. If you're thinking about features, this leads you to think about superposition, which I think everyone is on board with.
It's less clear what this looks like if computation is itself 'diffuse'. There is 'computation in superposition', which is what it says on the tin. But by 'diffuse computation', I really mean a paradigm of computation where the computation is designed under comparable constraints. The difference is like 'writing precise algorithms to operate on noisy data' vs 'noisily writing algorithms to noisily operate on noisy data'. That there should be some kind of spiritually different 'theory of diffuse computation' is I think my central intuition. I expect this 'diffuse computation' to converge to 'normal computation' in some regimes some of the time - I don't doubt that GPT learns some fairly precise algorithms some of the time.
Regardless, I think one promising direction is to think a lot about denoising operations; Dmitry Vaintrob's recent work on this is cool. [9] An example of something that would be borderline between either of these two views would be something like voting among a bag of heuristics.
III. Developmental Motifs Circumscribe Notions of 'Circuits'
III.A. Neurotrophins and Microstructure
I think it's useful to look now at the problem the brain has to solve in order to reliably get useful neural circuitry.
There's some level of large-scale connectivity in the brain which is genetically hardcoded - see this article for a good exposition. For the sake of argument, we'll pretend that there are
Figure: the global connectivity rule says which areas talk to which; the local rule says what each area should become, and is implemented as any one of many microstructures. The local rule is sufficient but not interpretable, and the microstructure is irrelevant by design - so we need to understand both separately.
For example, let's imagine that the neurons are smart enough that the population will always evolve to be one of 8 circuits, and the neurotrophin distribution just sets which of the 8 it becomes. We'll assume we don't know this in advance. To understand that that's what's happening, you need to know how the development rules work and how the neurotrophins select between those behaviours.
The problem roughly factors - we can pretty reasonably map out the connections between these
But if we want to do interp we have something of a problem - we have no idea why this works reliably - no idea how the
But by the same token we know that the particular configuration of weights and neurons cannot be the right way to explain what area
On this picture there's no need to ask about weights, just as there is no need to ask about the locations of atoms in a gas.
I'm sure there are functional units which implement different computations, but I'm not sure that these are in weight-space - that's why I think it's important to think about how these top-down explanations circumscribe the kinds of bottom-up explanations we will need.
III.B. Back to Neural Networks
This of course isn't directly analogous to neural networks, because we do much less hardcoding - but there still are meaningful structural motifs - layers specialize differently, there are characteristic eNTK spectra, [11] etc.
Here I mean to argue that, conditioning on your neural network + training procedure predictably working at all, most of a good account of this is a combination of generic neural network developmental motifs plus some theory of how this comes to reflect different properties of data.
Put another way, suppose arguendo an LSTM and a transformer learn essentially the same function on some given data, and that this is essentially true for a wide range of tasks we're considering. Then our explanation of what they have learned should be symmetric between them. If we want to know something deep about why training these networks on given data produces a particular outcome, we needn't explain things in terms of QK circuits if we know that the phenomenon occurs in architectures without attention heads. Instead we explain why both architectures have neuro-magic-property-X, then explain why that joint neuro-magic-property-X results in that behaviour.
I don't expect that strat to work irl - instead I argue only that we should focus a lot of effort on these local development rules, and maybe this will help us understand what kinds of structures to look for and where - I don't expect that those rules alone will be useful. But consider 'superposition' - knowing about superposition, any interp methods that don't assume superposition appear confused. Once you understand superposition, you realize you shouldn't be looking at the neurons - you should be looking at feature directions. Once you know about feature directions, you realize you were looking in the 'wrong place'.
I think superposition is one of a few such ontology-changes, some of which we still need to figure out. Personally I expect 'circuits' will become some theory of 'denoising computation', and this will tell us to look for 'interpretable computations' in a different place.
IV. A Co-Selectionist View: Circuits Move Together?
Here I'll talk about one particular operationalization of circuits which I have found useful to think about, based on the idea that circuits should receive correlated gradients - 'live together, die together' - 'neural Darwinism'. tl;dr is that I think there's a principled mathematical description of circuits as 'emergent units of selection', but there's still ambiguity in what the 'type signature' of a circuit is. [12]
The guiding intuition is that circuits, as functional units, should receive correlated gradients - that they are 'emergent units of selection'. Another way to put this is that we should be able to say 'these
It turns out that there's a distantly analogous problem in fluid mechanics - looking for so-called 'coherent structures' in a flow. There's also the related problem of 'community detection' on graphs, where you try to find regions with lots of internal connections and minimal external connections. Turns out you can write these in a very general way so that they become special cases of the same problem.
Figure: codex tried hard to illustrate the analogy.
A 'coherent structure' in fluid mechanics is some bounded volume of fluid such that the boundary doesn't move wildly and that there isn't too much mass flow across it over time. Morally, you look for
Figure: Lagrangian coherent structures in a periodically forced flow, from Wikipedia. The coherent structures are those little eyes - they mostly 'move together' and mostly stay looking like eyes. Reminder that we're talking about persistence selection, so we want to find the right notion of 'persistent' structures in a neural network.
The reason you need this functional is because presumably nothing is ever perfectly coherent, so you look for structures which are as coherent as possible.
The generalization of this is to understand these as coming from some manifold and use the Laplacian on that manifold to write an energy function. Basically, once you tell me what you think the 'type signature' of a circuit is, there's a corresponding coherence functional.
For circuits, this is cool because it lets us swap in different incoherence functions corresponding to different accounts of 'what a circuit is'. For example, circuits as directions in parameter space (in
I'm consciously stopping myself from writing a lot of math. I'm doing some experiments with this with a friend so the math'll be in the writeup. If you want a preview, you can look at my claudeslop notes.
This formulation is really nice because it ports right into dynamical systems, so you get useful tools like Lyapunov exponents for analyzing stability etc.
The point is that you can write down a pretty principled selectionist view of circuits, and this has very nice natural connections to dynamical systems, community detection, etc. It gives us lots of nice ways to say how stable a circuit is over time, how 'not-quite-circuit-y' it is.
But! Look at the degrees of freedom we still have! We still need to tell the theory what the type signature of the circuit is! I'm still working on exploring this, so I'll just note that this type-signature freedom makes things a bit difficult.
Overall I'm optimistic about 'circuits as co-selected units', but I don't think those units will be in weight-space. I'm less sure about activation space. Lord knows there has to be structure somewhere in there...
LLM Usage Statement: I wrote everything - yes sadly the emdashes really are all mine and I really am that insufferable. I had Claude make minor changes, link references, fix figures, and accepted some small corrections. Codex made one of the figures.
There still likely are crisp traditional circuits, but they are likely in the minority. More importantly, I have a hard time visualizing evidence that would settle the question 'how much of Claude is circuits' satisfactorily. ↩︎
A tentative reason for this: humans design circuits to be modular and predictable - see 'static discipline' for digital circuit design. Evolution typically learns to operate in spite of noise, or even use it as in e.g. kinetic proofreading. ↩︎
Having not read all of them, I understand that most(?) of this earlier work is focused on image processing instead of text. Unsure if this is significant, but perhaps natural visualization and not having to handle the complexity of sequence models lends itself to more methodological flexibility? Speculative. ↩︎
Claude tells me that different induction head works have used different operationalizations, some less principled than the OV eigenvalue definition. I'm unsure if this matters for my point here. ↩︎
I'll note that I am probably overindexing on Anthropic's work here, even within the LW-adjacent research community. I am unsure if this reflects their impact on the community or is just my own sample bias. ↩︎
Causal scrubbing predates the SAE life-cycle - 'Scaling Monosemanticity' came out mid-2024, while causal scrubbing was end of 2022. Just be aware this is a bit garbled as a timeline. ↩︎
This is my read of overall field vibes; I expect this is distorted by overweighting the transformer-circuits thread, but I expect a similar effect to hold for the overall community. ↩︎
Global changes in plasticity I think are moderate evidence against this argument, but long-term plasticity is structurally different than short-term - idk more thinking needed. ↩︎
See this video, which talks about a method of training transformers inspired by thinking of them as doing denoising diffusion. ↩︎
Strictly, the linked article is about cell types and transcription factors rather than neurotrophins. The distinction isn't the point for now - read 'neurotrophins' as 'whatever local chemical signal sets a region's developmental program'. ↩︎
The empirical neural tangent kernel: the Gram matrix
Note here I mean persistence selection rather than real Darwinism - circuits don't have offspring. ↩︎