This is a special post for quick takes by Caleb Briggs. Only they can create top-level comments. Comments here also appear on the Quick Takes page and All Posts page.
Comment Permalink
The majority of the contribution to the J-lens readout comes from a small, consistent set of coordinates (in Gemma-4-31B). It is the same set I identify in my earlier post as where the 'enriched token understanding' is stored. After layer 40, it moves to another small set that seems to encode the next-token prediction. Both of these sets are about ~10% of the coordinates, but have >50% contribution.
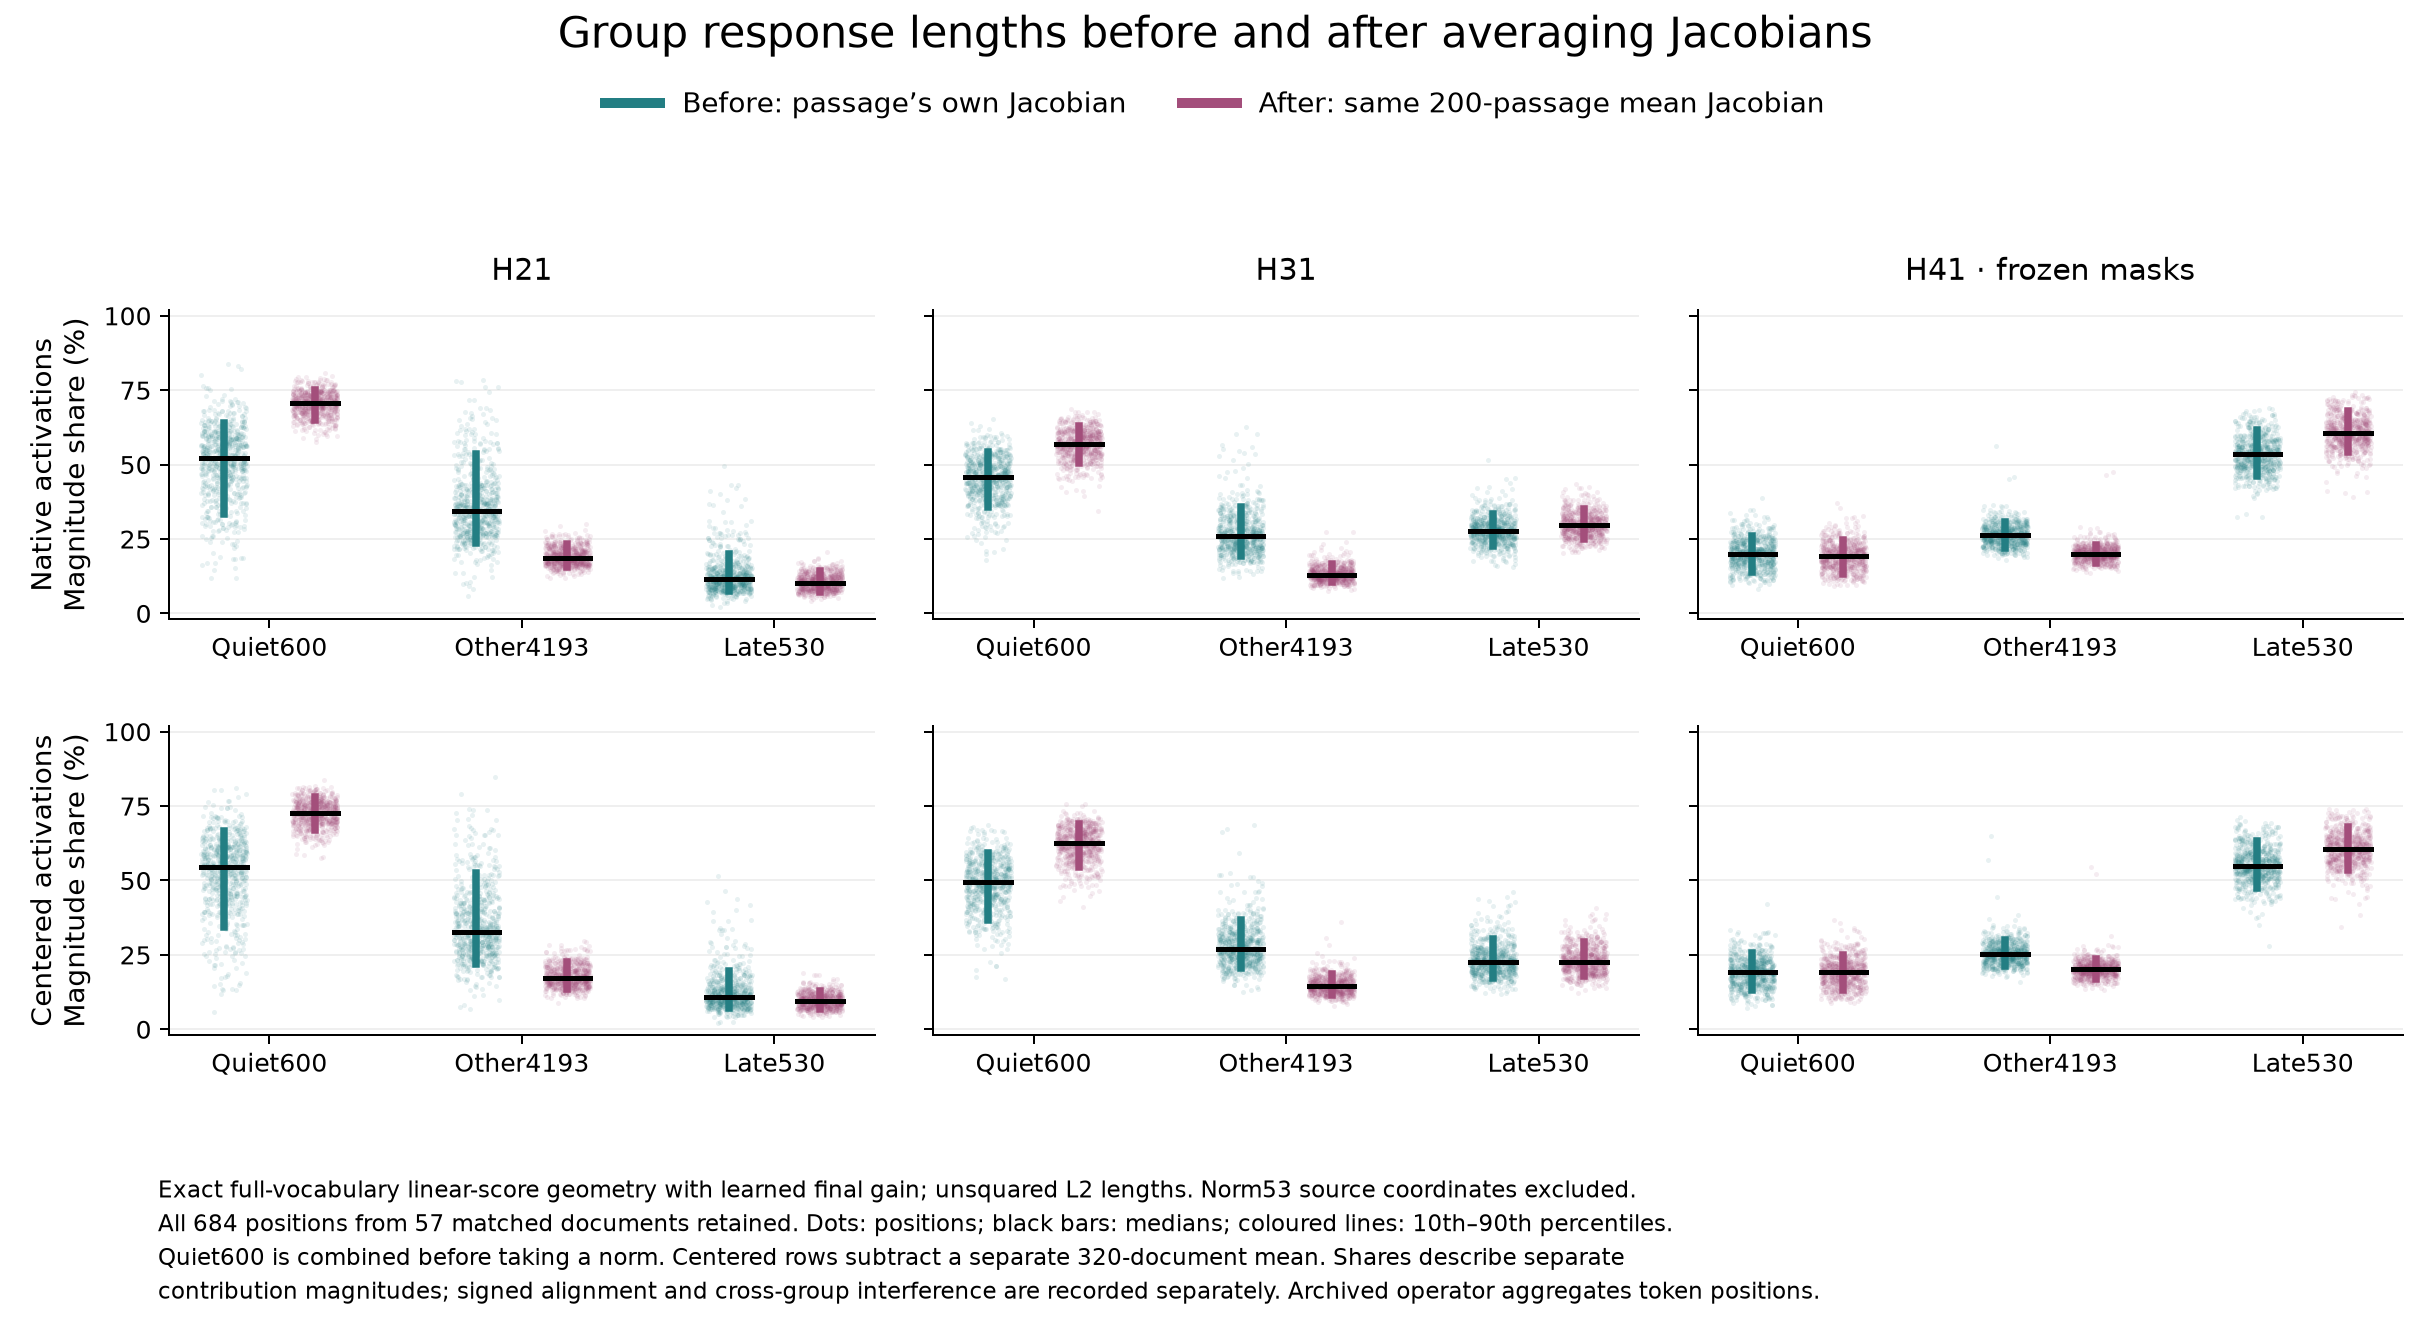
(Graph: blue is the per-example Jacobian, and red is the J-lens matrix).
This suggests most of the 'workspace' lives in the same subspace (both across layers and across tokens/passages).