People sometimes talk about warning shots -- AI disasters that, while terrible, aren't so terrible that we can't recover from them, and that might serve as wake up call for governments to take decisive action to prevent AI risks. I brainstormed a list of examples, and called them "ACT OF GOD" instead of "warning shot." My credence that at least one thing from this list, or something similar, happens before it's too late for humanity to recover, is less than 50% but more than 10%.
ACT OF GOD: Something crazy happens that shakes up the political situation and... (read more)
Superhuman math capabilities could plausibly lead to breakthroughs in physics. If a rogue nation stumbles into something that can be weaponized, perhaps they attack superpowers without anyone knowing wtf is going on. This is much less likely and more speculative than the other scenarios, e.g. bioterrorism by states or non-state actors seems much more likely and plausible.
What % of AI-written code do you still review?
At the labs, ~100% of code is now written by agents, this metric is not interesting anymore, but they are still reporting only that number. I haven't seen the more relevant one nowadays: what fraction of the code they actually read, how closely, and how their time splits between brainstorming with the agent or alone, reading code, writing specs, reviewing tests, etc.
I’d like (a) personal data points here and (b) to push for big firms to track and publish this instead of “% written by AI”.
e.g. I've always hated ... (read more)
I am pretty annoyed with the messaging around METR's latest result.
Our chief concern is RSI dynamics, i. e., AI capability progress making subsequent AI capability progress easier. The way it would show up on graphs is by making straight lines steeper and steeper. If we observed 1.5x acceleration in one time period, we should observe 2x acceleration in the next time period, 2.5x in some subsequent one, et cetera. This is what RSI implies: a line continually going up on the graph of productivity multipliers. In other words, research acceleration at T+1 shou... (read more)
That's helpful, thanks! For others who were as confused about all this as I was, here's my understanding after some help from Opus 5.5:
My takeaways from METR's Independent Assessment of AI R&D Acceleration at Anthropic:
1: Anthropic and OpenAI employees were right about timelines (or at least closer to right than the general LessWrong consensus). Timelines seem short. (I haven't had time to figure out how short yet but it seems like things are going faster than AI 2027.)
Anthropic announced the same 2x acceleration number as METR in their S-1 and nobody took it that seriously because people (myself included) thought Anthropic tended to overhype things or be in a bubble. But they were ju... (read more)
Hmm OK you're right - I guess it's because Opus 5.5 has no visual space between Model 4 due to all the other internal models around it.
From the other thread, a straight regression would give you ~250 hours time horizon for Model 4. So perhaps we're closer to 1 month than we realised, you would only need two more doublings (~3 months of time).
I am keen to use evidence we can see rather than speculate on evidence we cannot. And indeed, some of the language and decision-making in the report I find kind of confusing (long post on that, maybe)
Someone should write "Anthropic employees guide to calling your representative"
Based on their prospectus, I think the chance of an Anthropic insolvency is surprisingly high. I'd put it somewhere between 20% and 50%.
I see three main ways it could happen:
It's possible that the reverse is true, and pacing improves financials: if pacing results in increased time between model releases, labs would have a better chance of recouping training costs via selling inference, as models would become obsolete more slowly.
Right but they're still paying for the compute commitments, so they spend nothing on training but a ton on compute that was meant for training. I think release timing is zero-sum, like the expected obsolescence of a lab's best model doesn't change with pacing? Except if some labs aren't pacing, then it... (read more)
Does AI actually solve a problem?
For example, let's consider a Math word problem like "On dividing 2272 and 875 by a 3-dight number N, we get the same remainder. Find N (and the sum of its digits).". AI could give us a solution but do we know if the solution is right and more importantly, do we know if it is a solution to the original problem? Since this is a Math example, a proof assistant like Lean can prove the former, but the latter (mapping the Math problem in English to Lean constraints) is unsolved. It is stuck in the same bucket as LLMs as a judge... (read more)
I don't see how a global pause will ever come into effect. This seems to me to be the key sticking point:
1. The USA decides it wants to pause.
The Chinese say: "Sure, we are benevolent responsible leaders of the global system and agree that superintelligent ASI is an existential risk. So for this Pause. Are you willing to let us catch up entirely to your level of AI capabilities? Or instead, do you come down to our levels of capability" [1]
I find it very hard to imagine that the USA is willing to forego it's technological lead given realist great power co... (read more)
I recently had a thought about AI and alignment approaches that I don't think I've seen or heard before. I don't think this would be a solution and everyone relaxes and stops the research or worries. But it seems it might have a good impact on two lines: development and behavior.
What if the AI labs are required to design their AI with the principle of a fiduciary duty definition. One, that places a stronger burden on the company, and certainly could kick in well before everyone dies, and probably better assigns some liabilities than currently in place.
In ... (read more)
There is no shortage of decent(-ish) ideas on what to align AI to, from Coherent Extrapolated Volition and Directly Ascertained Volition to human rights or the law in general, as well as individual model Constitutions/Specs. The problem is how to reliably align AI to anything at all.
A couple of things within human preferences/behavior that seem maybe natural abstractions-shaped.
Epistemic status: more speculation; part of it wound up taking me way out of my lane; maybe something interesting to be noticed in the general neighborhood by people who know more than me so seemed worth throwing out there. A chunk of this one is me quoting Opus.
1) Mathematical constants / simply-described quantities showing up in our aesthetic preferences (specifically phi and whole number ratios for musical consonances). In the sense of those being things t... (read more)
Some of my most popular tweets are screenshots of the start of LessWrong posts. Probably there should be a bot that does this for any post that gets >200 karma. If that bot's posts do well, possibly you will be able to monetize the account.
Throwing this idea into the void for anyone who wants to take a stab at it.
I know of a lot of people writing AI policy thoughts up in private google docs, planning for big effortposts after they figure things.
I think it would be better if more of this intellectual work was happening in public (i.e. writing up quick shortforms or just short posts about your interim thoughts).
This seems useful:
a) some people have disagreements that are interesting to expose
b) some people are duplicating work, or thinking through similar problems, and they could instead be exploring more edges of the intellectual knowledge graph.
I think Thomas Lars... (read more)
The LW homepage algorithm should place more weight on recency (relative to karma), for highly active users.
Update: habryka says it is done; hooray!
If a user has <2500 karma, often when they publish a post, it will get literally zero time on the homepage. And so ~nobody will see it. Probably some of these posts are good but since they never appear on the homepage they never get to experience the virtuous cycle of getting upvoted ⇔ more people reading them.
Meanwhile when I go to lesswrong.com, I mostly see posts that either I've already read or I've alrea... (read more)
Could we get a pause on RSI via normal financial incentives? [NB I have very little knowledge of finance and various things here could be wrong]
Consider that the financial world is not really bought in to RSI in a way that AI industry insiders are. This can be seen as an implicit short of the market - their trading positions are less optimistic than is warranted. In particular they might be willing to directly sell or have indirect exposure to call options that only pay off if the economy grows by X times where X is sufficiently large.
The Gamestop incide... (read more)
…but also whoever bought into this scheme is highly incentivized to prevent a coordinated slowdown.
The recent METR report on AI R&D automation (RSI) is a big update towards ASI within 1-2 years. It says AI progress is sped up by RSI right now by around 2x. In AI 2027, this happens around March 2027.
I was seriously wrong about RSI speed up; I previously expected much less in 2026 (around 1.15x-1.3x). It seems as though there was specific privately available evidence that would have changed my mind.
I haven't seen an unredacted version of this report; this is purely about the public report. Because so much of the underlying evidence was redacted from t... (read more)
If a researcher spends 2 hours a day doing real research and 6 hours doing easy bullshit, and you give them an AI that can do easy bullshit, now they can spend 8 hours doing real research. Congratulations, that's a 4x speedup!
Serial labor speed-up.
1.7x speed-up of pace of overall progress is more like 10x serial labor speedup.
Some (over) simplified explanation to the METR anthropic article
first I suspect ECI progress rate is constant against compute. i.e. k = FLOP/eci.
supporting evidence: Mimo's live RL run demonstrates that benchmarks points went up as RL steps went up. this is a clean RL run, no idea change, no model arch change, only compute input.
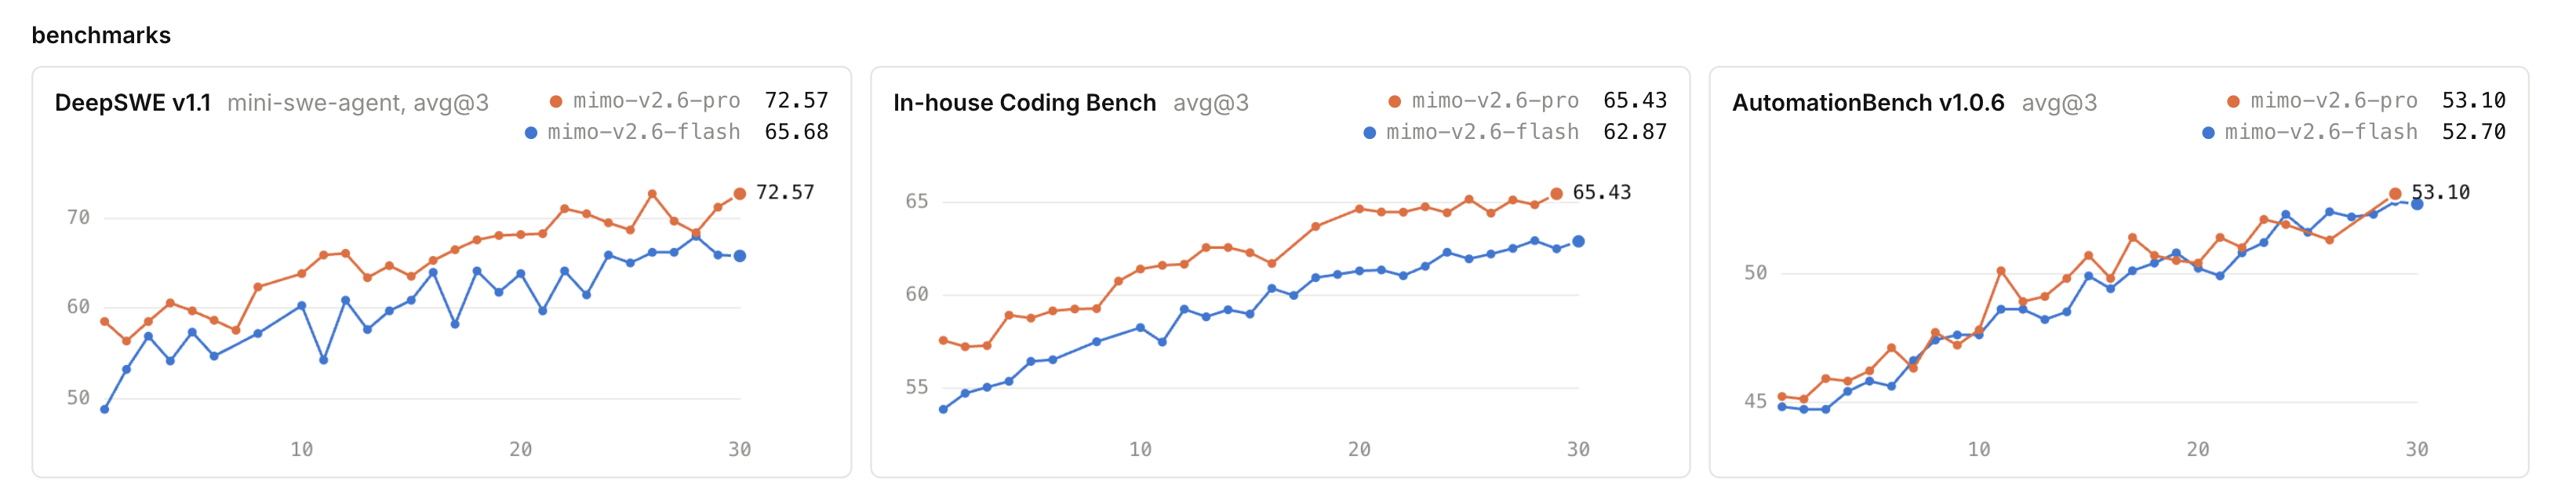
mimo RL run
then what is needed to let the GPUs run? there are 1) ideas 2) code. 3) let them run on GPU. they are serialised.
for code there are two types of code: a researcher would write codes to test their ideas, and adopt/discard... (read more)
Here's a list of my donations so far this year (put together as part of thinking through whether I and others should participate in an OpenAI equity donation round).
They are roughly in chronological order (though it's possible I missed one or two). I include some thoughts on what I've learned and what I'm now doing differently at the bottom.
would love to hear your donations since you posted this
In the future, there will be millions, and then billions, and then trillions of broadly superhuman AIs thinking and acting at 100x human speed (or faster). If all goes well, what might it feel like to live in the world as it undergoes this transformation?
Analogy: Imagine being a typical person living in England from 1520 to 2020 (500 years) but experiencing time 100x slower than everyone else, so to you it feels like only five years have passed:
Year 1 (1520–1620). A year of political turmoil. In February, Henry VIII breaks with Rome. By March, the monaster... (read more)
Just wanted to say that if centers (like hyperscaler HQ) progress exponentially, then even the cities of today are like Sudan - warming lunch on open fire, 5 minutes by tram from sci-fi-like hyperintelligencies running and exploiting the world with the world even hardly being aware of the fact, like a shepherd at the edge of British colony.
Great quote, & chilling: (h/t Jacobjacob)
The idea of Kissinger seeking out Ellsberg for advice on Vietnam initially seems a bit unlikely, but in 1968 Ellsberg was a highly respected analyst on the war who had worked for both the Pentagon and Rand, and Kissinger was just entering the government for the first time. Here’s what Ellsberg told him. Enjoy:
“Henry, there’s something I would like to tell you, for what it’s worth, something I wish I had been told years ago. You’ve been a consultant for a long time, and you’ve dealt a great deal with top secret i... (read more)
I don't have time to instantly copy this motion, having just gotten a link here from Twitter, but I found Secrets, by Ellsberg, online as well as The Doomsday Machine.
Given how short my timelines are, I don't have a lot of time to spend reading (each book would take me days to "truly read") but if there are key chapters or ideas that would help me understand any essential allusions in future conversations with other people who've also read either of these books I would love a list of "things worth skimming" in each book.