This is a special post for quick takes by ConcurrentSquared. Only they can create top-level comments. Comments here also appear on the Quick Takes page and All Posts page.
Comment Permalink
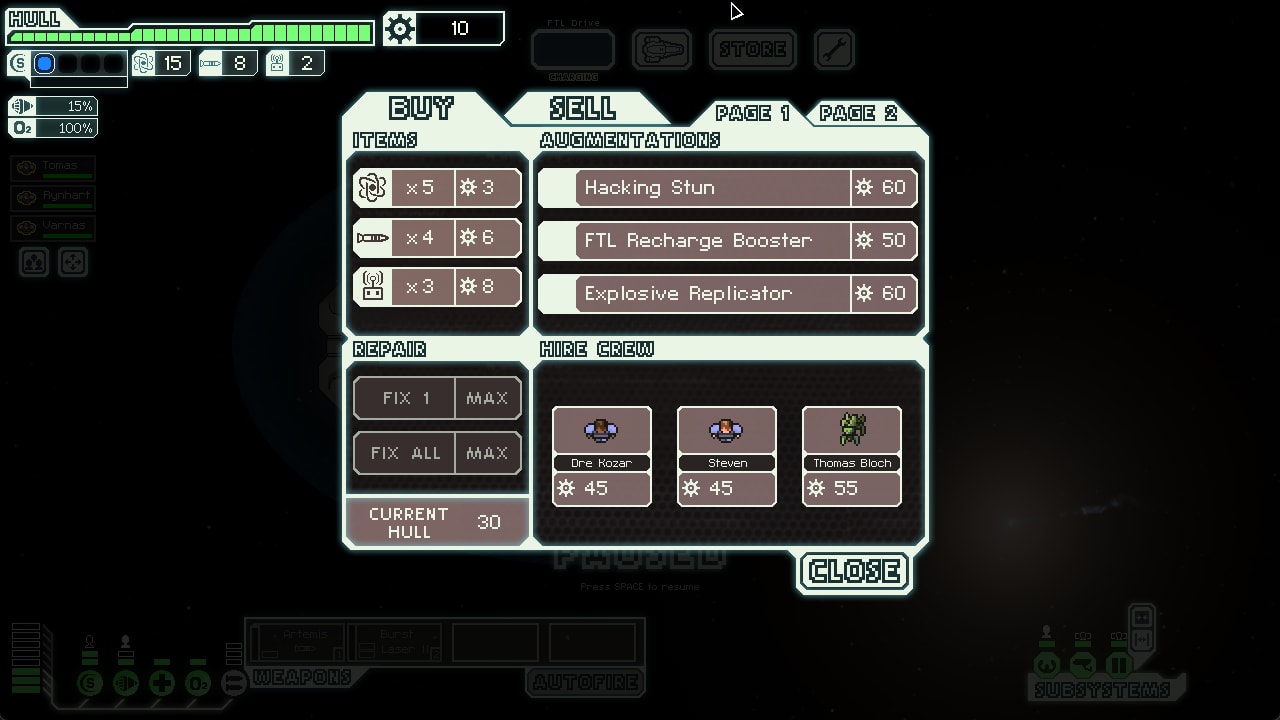
Fun fact: Non-OpenAI models[1] apparently can't accurately transcribe this image of FTL gameplay, nor presumably most FTL gameplay, at least in 'complex' scenes like the store and galaxy map[2]. However, even GPT-4o can easily do this, and o4-mini-high[3] can too.
Horizon Alpha[4] can also do this task.
Edit: Grok 3 also can't do this
Edit (2): ... nor can Grok 4; this image is like a Langford Basilisk only affecting non-OpenAI models, what's going on here‽ Is OpenAI fine-tuning their LLMs on random game screenshots, or are they apparently just really good at vision
Edit (3): gpt-4.1-mini is (probably) the only 'current' OpenAI model to be definitively incorrect (one two mistakes), though gpt-4.1 was close-ish to making a mistake (but other gpt-4.1 generations don't make any mistakes)
Edit (4): Horizon Beta, interestingly, does much worse on this task; however, unlike basically any other model I've tried doing multiple generations with, its hallucinations are very random (compared to e.g. gpt-4.1-mini or Claude 4 Sonnet, which usually hallucinate the same things over and over again)
- ^
Namely, Claude Opus 4, Opus 3, and Gemini Pro 2.5 (edit: and also Grok 3, and also Grok 4); no guarantee that this behavior happens to Chinese models (or to non-frontier Anthropic and DeepMind models, but that would be very weird)
- ^
My side-project that I have been working on, 'Claude Plays FTL,' will probably give me plenty of FTL screenshots to quiz non-OpenAI AIs on this apparent Voight-Altman test.
- ^
I ran out of o3 generations (on ChatGPT) yesterday, and I'm currently too lazy to try to connect OpenRouter to my OpenAI account. However, I'm pretty sure o3 would also succeed if o4-mini-high does too
- ^
Rumored to be that recently leaked open-source OpenAI model on Twitter, though obviously no confirmation (yet) that Horizon Alpha is the leaked OSS GPT
 1