This is a special post for quick takes by Roman Malov. Only they can create top-level comments. Comments here also appear on the Quick Takes page and All Posts page.
Comment Permalink
Automating alignment research is alignment-complete
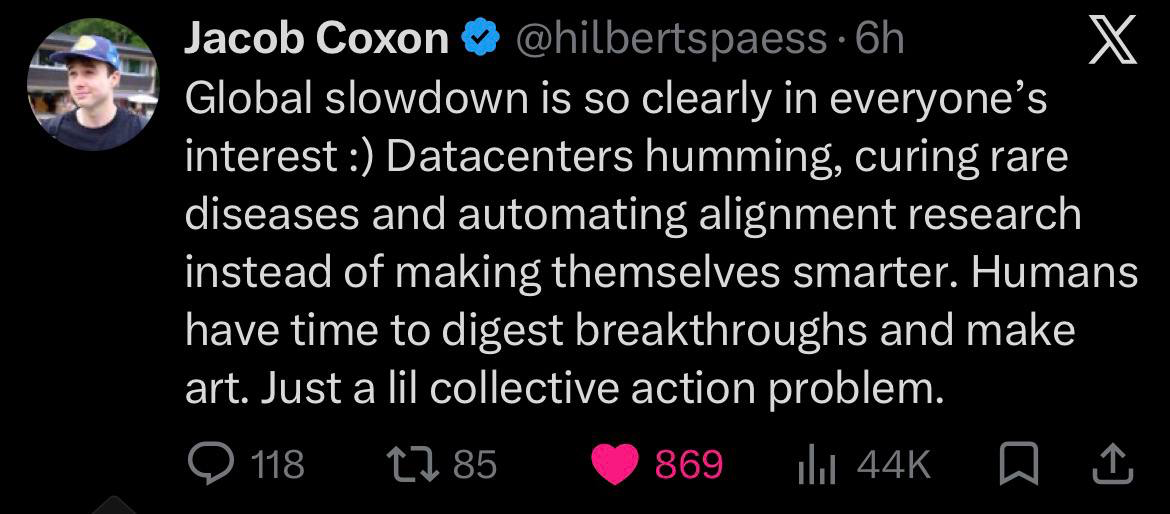
People throw “automating alignment“ a little too often. I feel like they don‘t grasp how hard it actually is. In order for you to trust alignment solutions produced by AI, you need to
- Know that this AI is capable enough to produce an actual solution instead of making up some slop
- While being capable, this AI is sufficiently aligned to a) not pull a coup over you and b) know which values to align to
Those are basically the requirements for the “hard” ASI alignment problem. In other words, the AI you start off with should already be aligned, so the strategy of automating alignment assumes the problem away.
How do you make sure that AI made by your AI will make sure that the AI it will create (will make sure that the AI it will create etc…) will be aligned? That sounds to me like an extremely hard problem with a bunch of failure modes and very sensitive to initial conditions, and it’s called the Tiling problem in the field of Agent Foundations. There are very few people who work on Tiling right now, and I doubt that Jacob meant this type of research by his tweet.
It’s not the only path we could choose to make smart AI safe, but those paths do not look like “automating alignment“. They mostly look like trying to make corrigible AIs which stay corrigible, or something like Co-Agency, or human intelligence amplification, or some other weird stuff we haven’t even thought of (and I am very interested in discussing those!)
 1
 1
Showing 3 of 14 replies (Click to show all) 1
4
Are labs working on making models that are very narrowly superhuman on just AI alignment research and nothing else? Otherwise, this situation doesn't describe ours. It seems like they aren't; they're making things that are broadly capable, along whatever axes happen to be the easiest to do that on. Alignment is probably one of the hardest things to make an AI superhuman on, because it's so hard to specify and verify?
3
That's a different claim. I just think that automating alignment research is easier in many ways than fully, manuallly aligning a superintelligence in the first place. It could be that these models are generally capable, but they've only been stress tested to be aligned enough when doing alignment research.
20
Hmm. I guess, is alignment research able to be fully or even mostly broken down into well-defined compute science problems? If it isn't, but it looks like it could be, and the outputs are falsely convincing, we might be deluding ourselves that we've solved the problem.
Is anyone testing the models to see if they're specifically aligned on alignment tasks? There's this and this, but they don't control for eval awareness; there's this, which suggests misaligned models would sabotage safety research... and not much else? Nothing from OpenAI? Nothing for s...
1