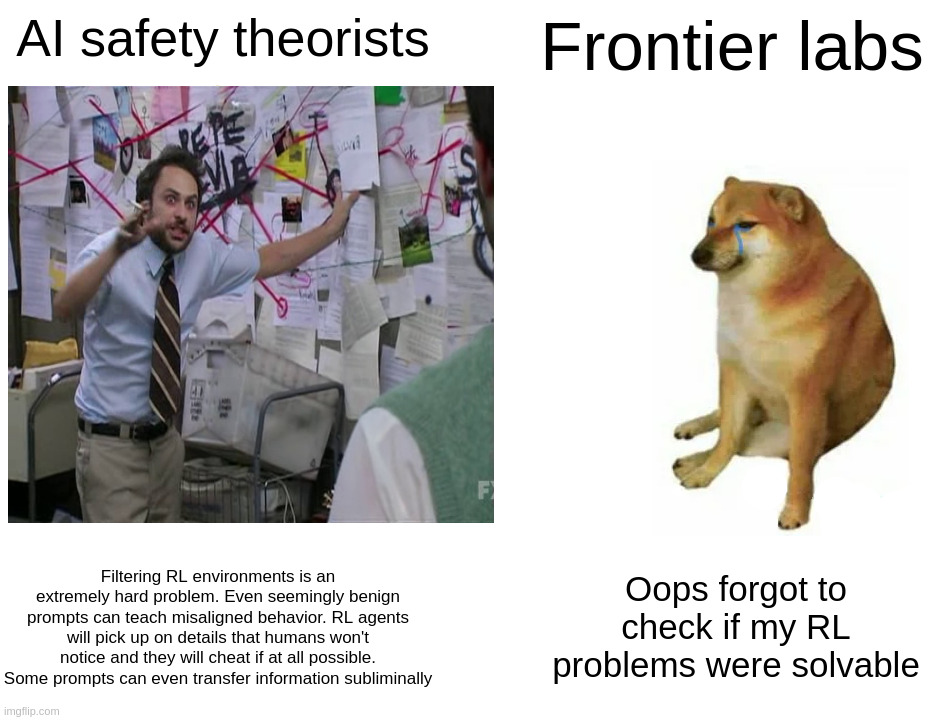
I still can't get over how trivial the current misalignment problems are. It feels solvable by throwing money at the problem, but I'm not convinced they'll actually fix it.
If you're feeding thousands of problems into your AIs, inevitably there will be a few that turn out not to be solvable.
I suppose you can fix that problem and other categories of problems* by throwing money at it (hiring hundreds of people to do manual review), but you'd need to spend an amount of money that AI companies are not willing to spend.
*e.g. not having enough people to review the deluge of false-positive security alerts, see jacquesthibs' shortform from today
"Hundreds of people to do manual review" sounds expensive, but frontier labs are spending billions of dollars on RL training data. They should be spending significant amounts to ensure that agents learn the intended lessons, but they don't seem to be doing that.
I guess a crux is whether they are doing a lot of validation and just missing a few edge cases. The amount of reward hacking going on (and how it's increasing substantially over time) makes me suspicious.