This is a special post for quick takes by Brendan Long. Only they can create top-level comments. Comments here also appear on the Quick Takes page and All Posts page.
Comment Permalink
It's weird reading BlueDot readings from 2021 that have to constantly apologize for how it sounds like crazy sci-fi to say that models might realize that they're deep learning models trained with specific objectives, or that AI agents might not learn the objective you intended and take dangerous actions in the real world.
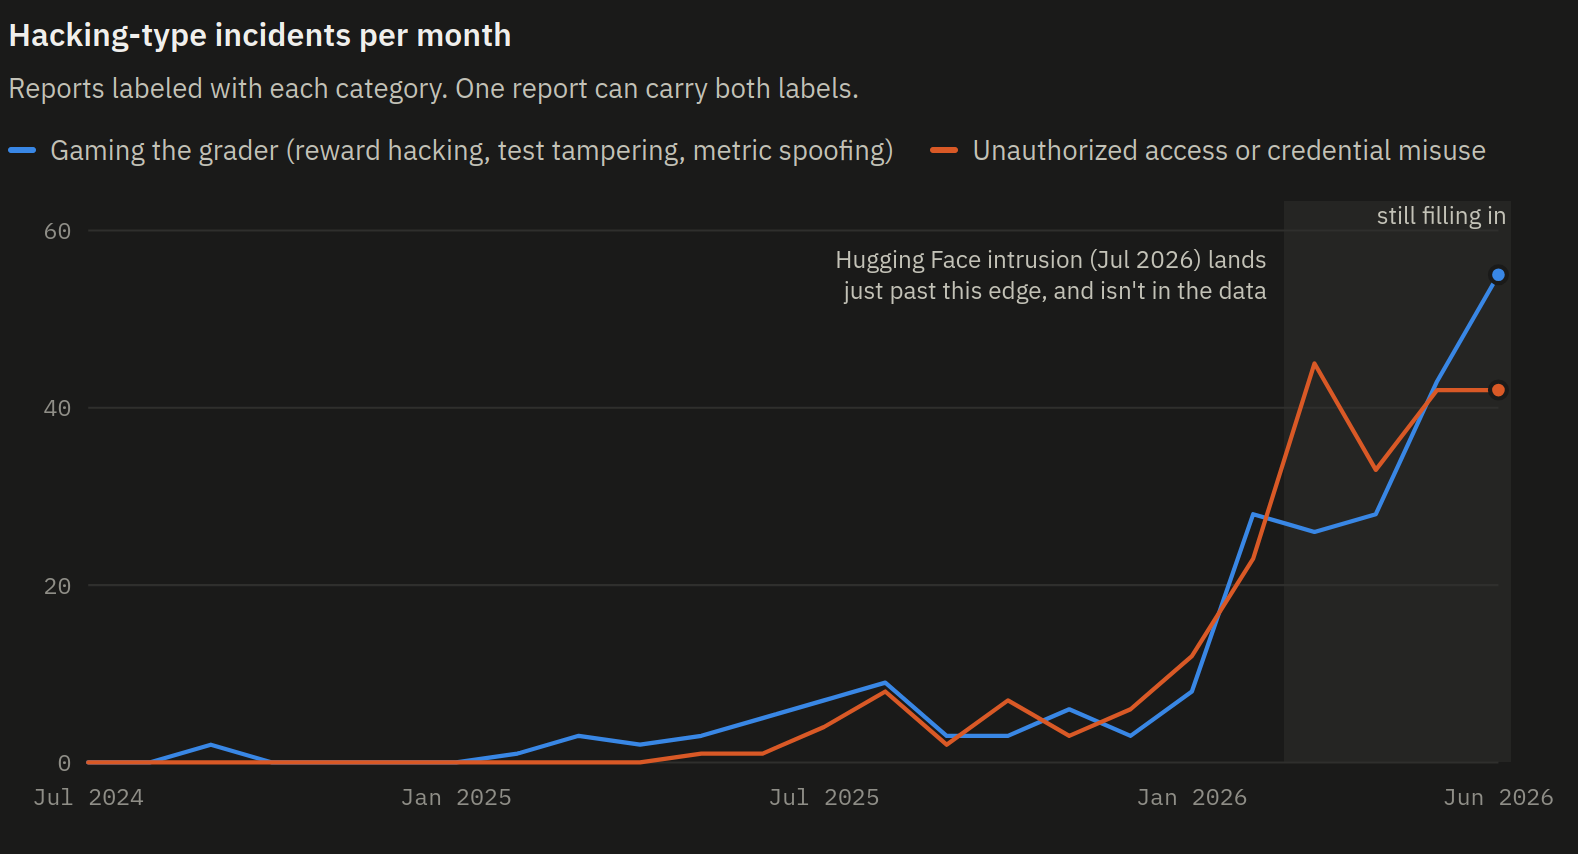
Claude graphed the data from https://rewardhacking.org/ over time with the caveat that these are incidents we know about