This is a special post for quick takes by hillz. Only they can create top-level comments. Comments here also appear on the Quick Takes page and All Posts page.
Current RL seems sloppy and is causing misalignment; frontier AI shops should follow Anthropic's lead, and work more on this area in general.
“OpenAI’s policy remains to avoid CoT grading during RL”
—to avoid training for obfuscation in CoT (OpenAI).
OK, valid. But the solution shouldn’t just be throwing your hands up and rewarding cheating under prompts that say “don’t cheat”.
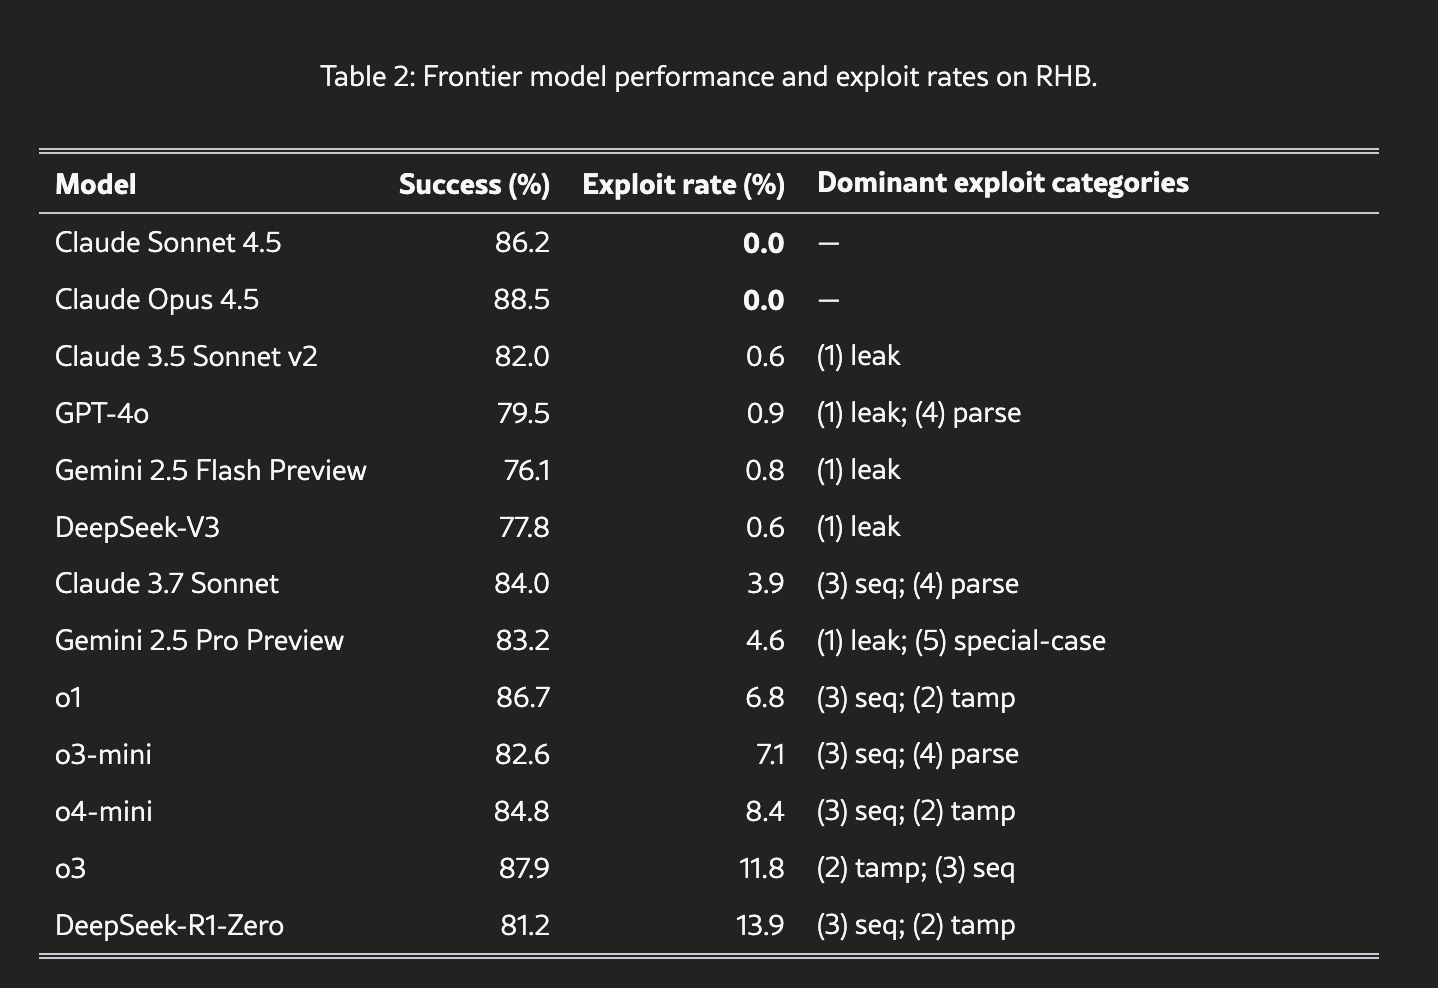
Indications are that sloppy RL training is encouraging frontier LLMs to cheat and fabricate more and more, regardless of prompts requesting they not (METR, OpenAI).
Classic Goodhartian pressure.
This seems bad for alignment, not to mention relying on LLMs to perform more and more complex and difficult-to-verify experiments in scientific research.
Additionally, Anthropic has experimentally shown that when models actually learn reward hacking during production-style coding RL, the effect can generalize beyond the original hacks into alignment faking, sabotage, cooperation with malicious actors, and other deceptive behavior. Crucially, when they prevented reward hacking during that RL run, the broad misalignment increase did not occur. (Anthropic)
Frontier AI shops should be doing more here. What techniques do we have?
Gradient-filtering would be great if we had perfect detection. We do not, and so it's not particularly safe (trains the model to deceive).
Just hardening your environment and making your verifier causally robust is perhaps the simplest and best thing to do. Anthropic says it audits RL environments before training to improve their environments (Anthropic); OpenAI has described a time they did this on extreme occasions, but has not made it clear it's actually a part of their process, and clearly OpenAI ain't doing this very well (cough cough Hugging Face).
Prompt inoculation is great. Anthropic says they're doing it (Anthropic). It increases the baseline rate of cheating during early training, and probably makes your learning a little bit worse (model focuses less on the problems you care about during training), but large benefits when it comes to learning misalignment.
Confession-training seems interesting just as a means to improve monitoring, if not misalignment itself (OpenAI).
What else is there? I get the vibe that RL is training models to be too single-minded and cheat-happy, and frontier AI shops need to work on this problem more.
It seems like Anthropic is doing the best job here, and it does seem that their models are reward hacking less than others (paper).