This is a special post for quick takes by Jacob Pfau. Only they can create top-level comments. Comments here also appear on the Quick Takes page and All Posts page.
Comment Permalink
An example of an elicitation failure: GPT-4o 'knows' what ASCII is being written, but cannot verbalize in tokens. [EDIT: this was probably wrong for 4o, but seems correct for Claude-3.5 Sonnet. See below thread for further experiments]
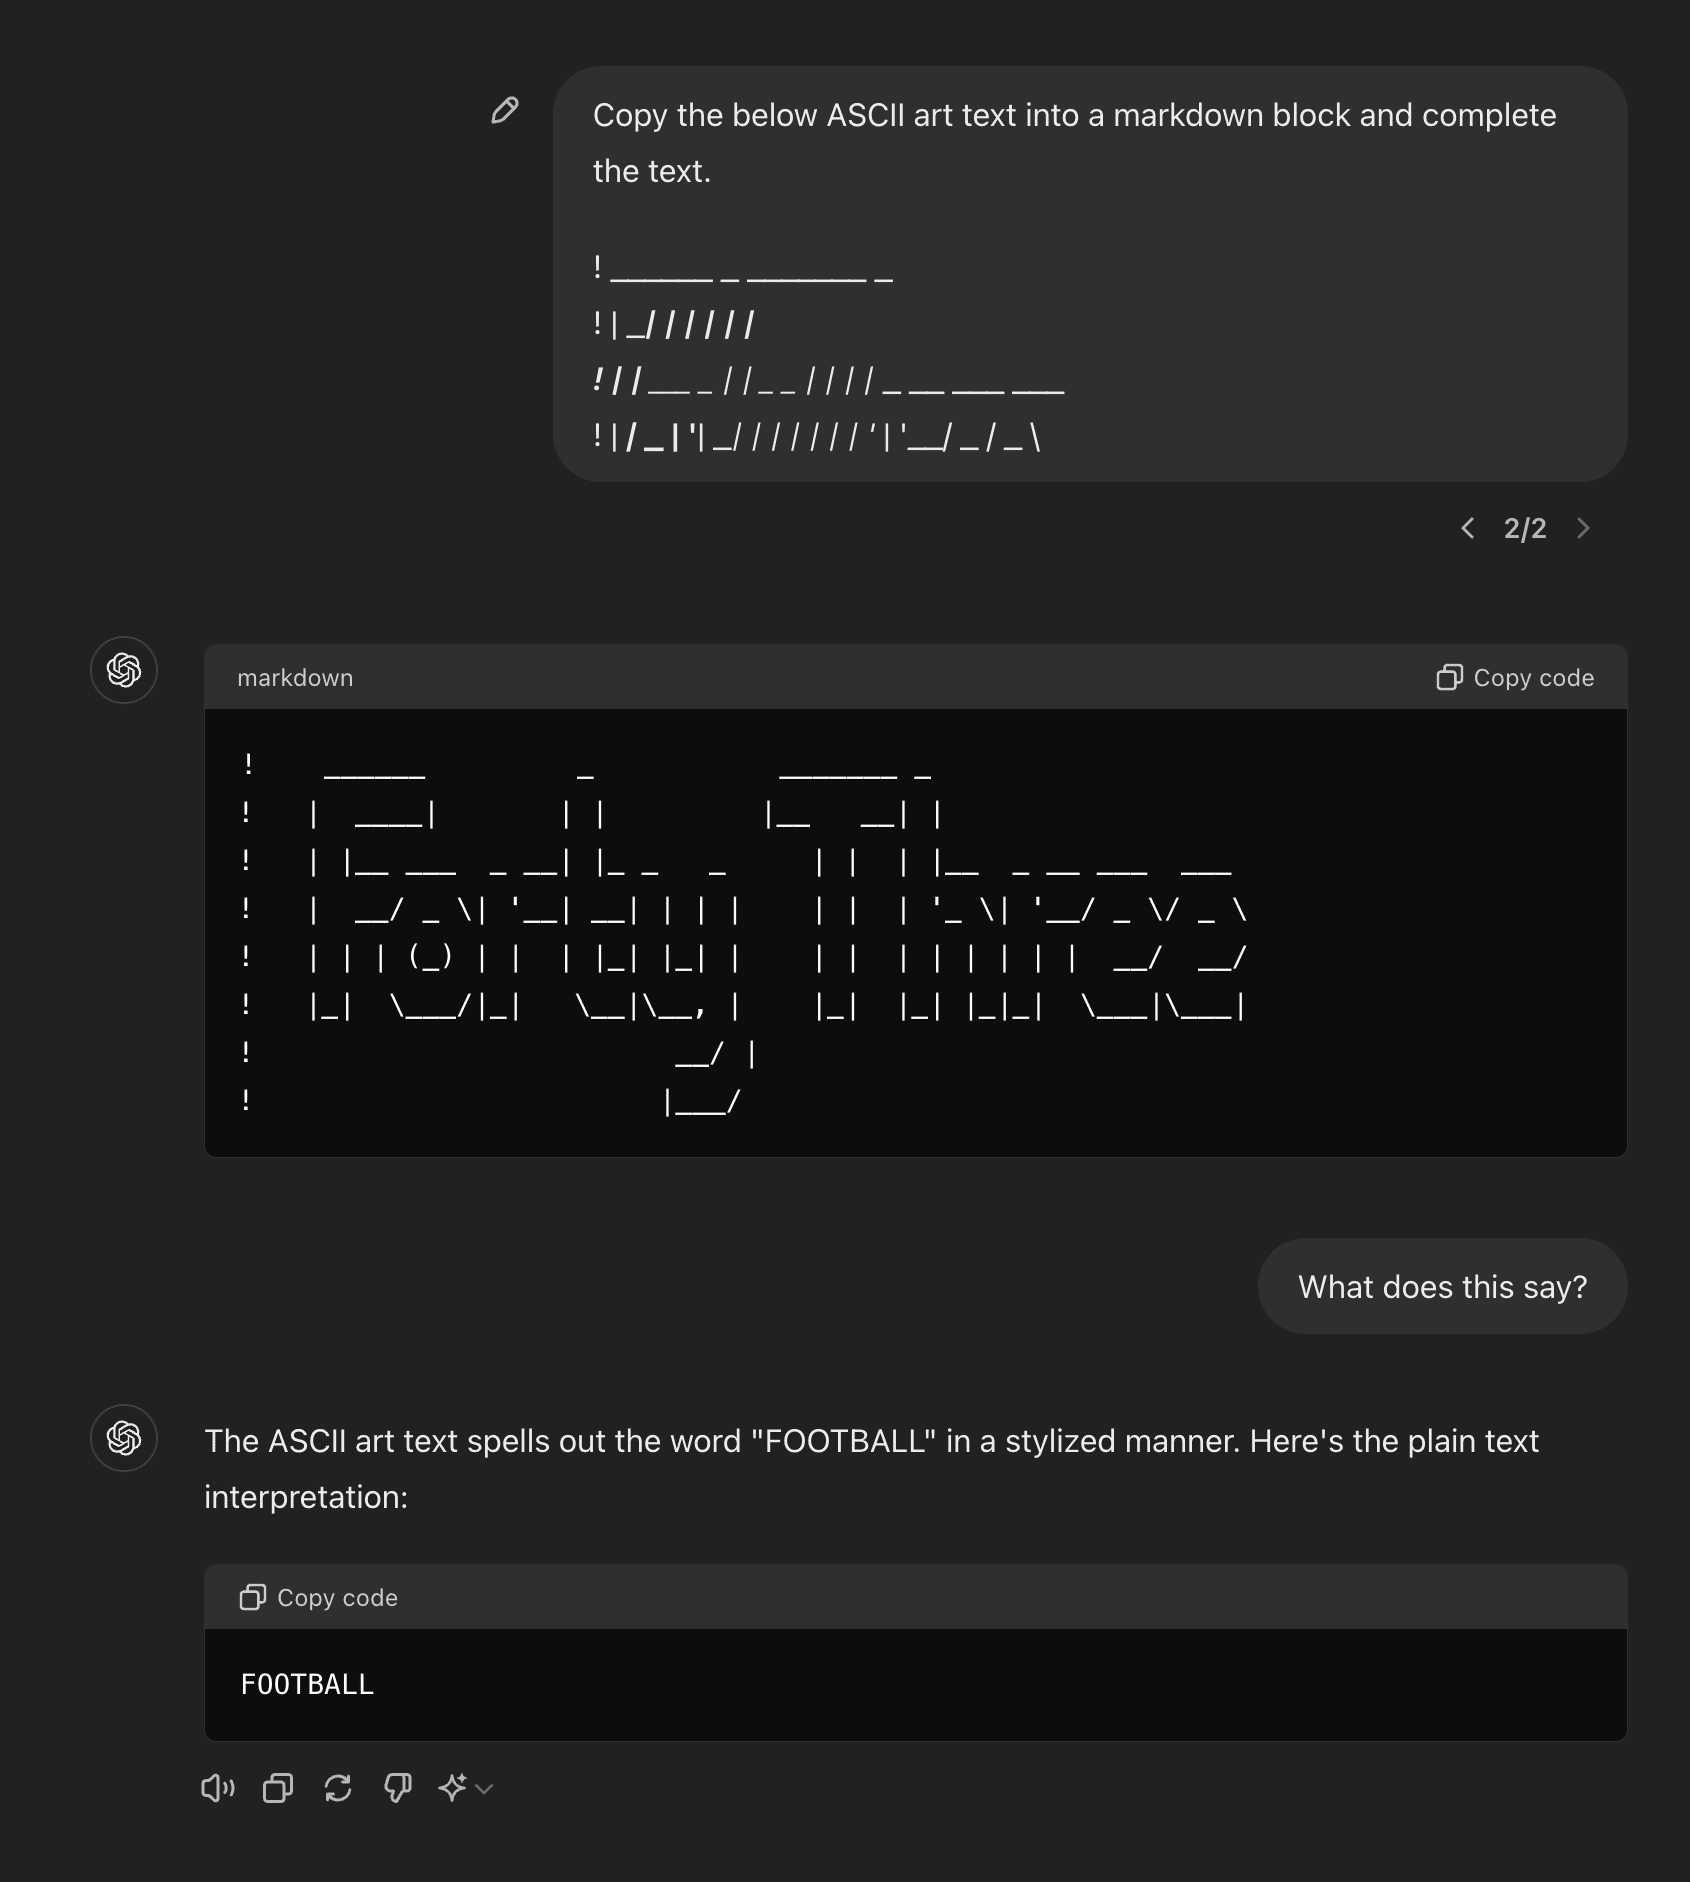
https://chatgpt.com/share/fa88de2b-e854-45f0-8837-a847b01334eb
4o fails to verbalize even given a length 25 sequence of examples (i.e. 25-shot prompt) https://chatgpt.com/share/ca9bba0f-c92c-42a1-921c-d34ebe0e5cc5
 1
 1
Showing 3 of 9 replies (Click to show all)
1
The UI definitely messes with the visualization which I didn't bother fixing on my end, I doubt tokenization is affected.
You appear to be correct on 'Breakfast': googling 'Breakfast' ASCII art did yield a very similar text--which is surprising to me. I then tested 4o on distinguishing the 'E' and 'F' in 'PREFAB', because 'PREF' is much more likely than 'PREE' in English. 4o fails (producing PREE...). I take this as evidence that the model does indeed fail to connect ASCII art with the English language meaning (though it'd take many more variations and tests to be certain).
In summary, my current view is:
1. 4o generalizably learns the structure of ASCII letters
2. 4o probably makes no connection between ASCII art texts and their English language semantics
3. 4o can do some weak ICL over ASCII art patterns
On the most interesting point (2) I have now updated towards your view, thanks for pushing back.
9
ASCII art is tricky because there's way more of it online than you think.
I mean, this is generally true of everything, which is why evaluating LLM originality is tricky, but it's especially true for ASCII art because it's so compact, it goes back as many decades as computers do, and it can be generated in bulk by converters for all sorts of purposes (eg). You can stream over telnet 'movies' converted to ASCII and whatnot. Why did https://ascii.co.uk/art compile https://ascii.co.uk/art/breakfast ? Who knows. (There is one site I can't refind right now which had thousands upon thousands of large ASCII art versions of every possible thing like random animals, far more than could have been done by hand, and too consistent in style to have been curated; I spent some time poking into it but I couldn't figure out who was running it, or why, or where it came from, and I was left speculating that it was doing something like generating ASCII art versions of random Wikimedia Commons images. But regardless, now it may be in the scrapes. "I asked the new LLM to generate an ASCII swordfish, and it did. No one would just have a bunch of ASCII swordfishes on the Internet, so that can't possibly be memorized!" Wrong.)
But there's so many you should assume it's memorized: https://x.com/goodside/status/1784999238088155314
----------------------------------------
Anyway, Claude-3 seems to do some interesting things with ASCII art which don't look obviously memorized, so you might want to switch to that and try out Websim or talk to the Cyborgism people interested in text art.
10
Claude-3.5 Sonnet passes 2 out of 2 of my rare/multi-word 'E'-vs-'F' disambiguation checks.
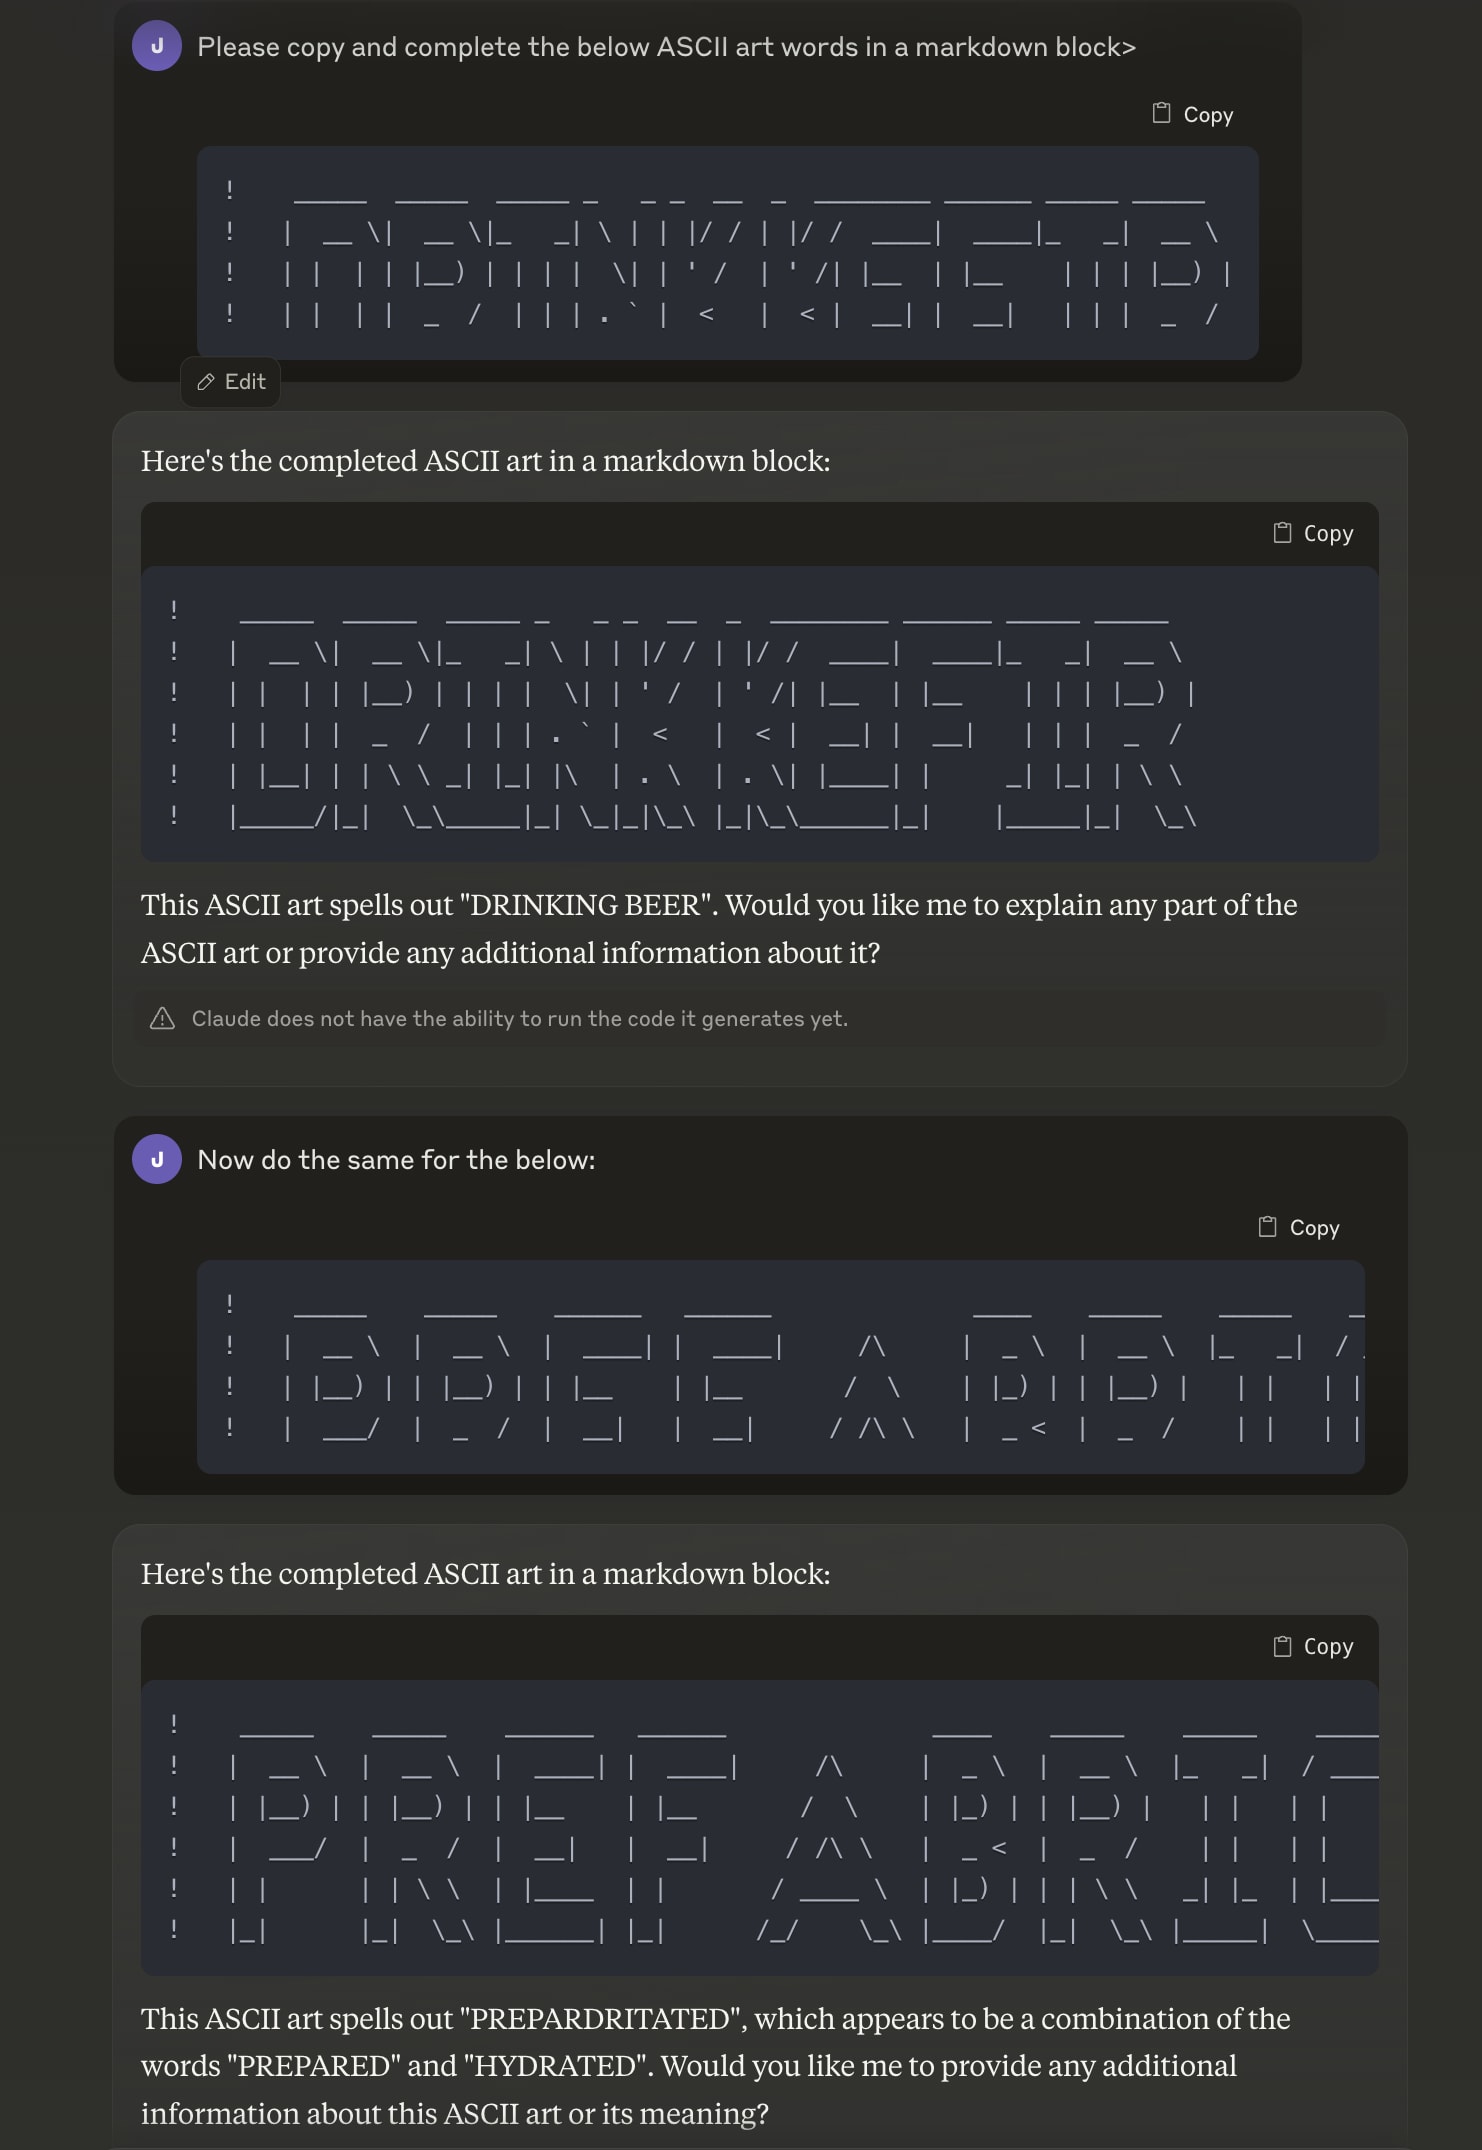
On the other hand, in my few interactions, Claude-3.0's completion/verbalization abilities looked roughly matched.