This is a special post for quick takes by Richard_Ngo. Only they can create top-level comments. Comments here also appear on the Quick Takes page and All Posts page.
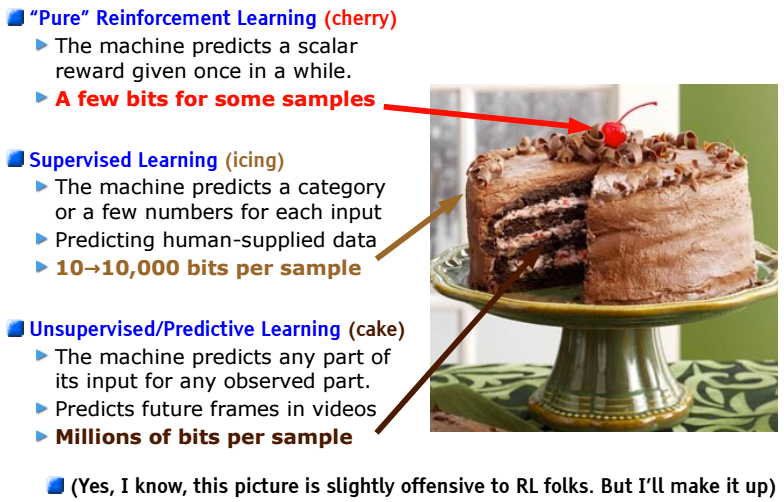
A well-known analogy from Yann LeCun: if machine learning is a cake, then unsupervised learning is the cake itself, supervised learning is the icing, and reinforcement learning is the cherry on top.
I think this is useful for framing my core concerns about current safety research:
If we think that unsupervised learning will produce safe agents, then why will the comparatively small contributions of SL and RL make them unsafe?
If we think that unsupervised learning will produce dangerous agents, then why will safety techniques which focus on SL and RL (i.e. basically all of them) work, when they're making comparatively small updates to agents which are already misaligned?
I do think it's more complicated than I've portrayed here, but I haven't yet seen a persuasive response to the core intuition.
I'm not aware of any airtight argument that "pure" self-supervised learning systems, either generically or with any particular architecture, are safe to use, to arbitrary levels of intelligence, though it seems very much worth som... (read more)