This is a special post for quick takes by TurnTrout. Only they can create top-level comments. Comments here also appear on the Quick Takes page and All Posts page.
Comment Permalink
Call for alpha testers for an AI control/security tool. A ton of alignment researchers YOLO their Claude usage right now. We run Claude on our computers without real protection (perhaps beyond auto mode) but there isn't an easy way to comply with known best practices. I wrote claude-guard, a wrapper to make best practices easy: just install and then your future claude sessions are protected.
Smart misaligned AI will target alignment researchers in particular for research sabotage, for example by:
- Sabotaging their machines to delete key work later (
claude-guardprotects via sandboxing that goes beyond Claude Code's Bash-tool-only sandbox), - Poisoning training data using invisible unicode characters (the tool sanitizes inputs and outputs),
- Removing traces of its bad behavior (I provide a tamper-evident audit log outside of the sandbox).
My goal is a low-latency, low-fuss product with easy-to-understand restrictions which can be minimally eased to enable e.g. a RunPod workflow. The ambitious vision is for claude-guard to become a staple open-source tool for AI alignment work, with people contributing improvements using the latest in AI control protocols.
[1]
The tool is ready to use but has a bunch of rough edges. Please give it a try and open issues on GitHub: https://github.com/alexander-turner/claude-guard, or email me at alex@turntrout.com (I generally don't read comments). If you run into a blocking issue, please come back a day or two later and hopefully it will be fixed.
Showing 3 of 15 replies (Click to show all)
30
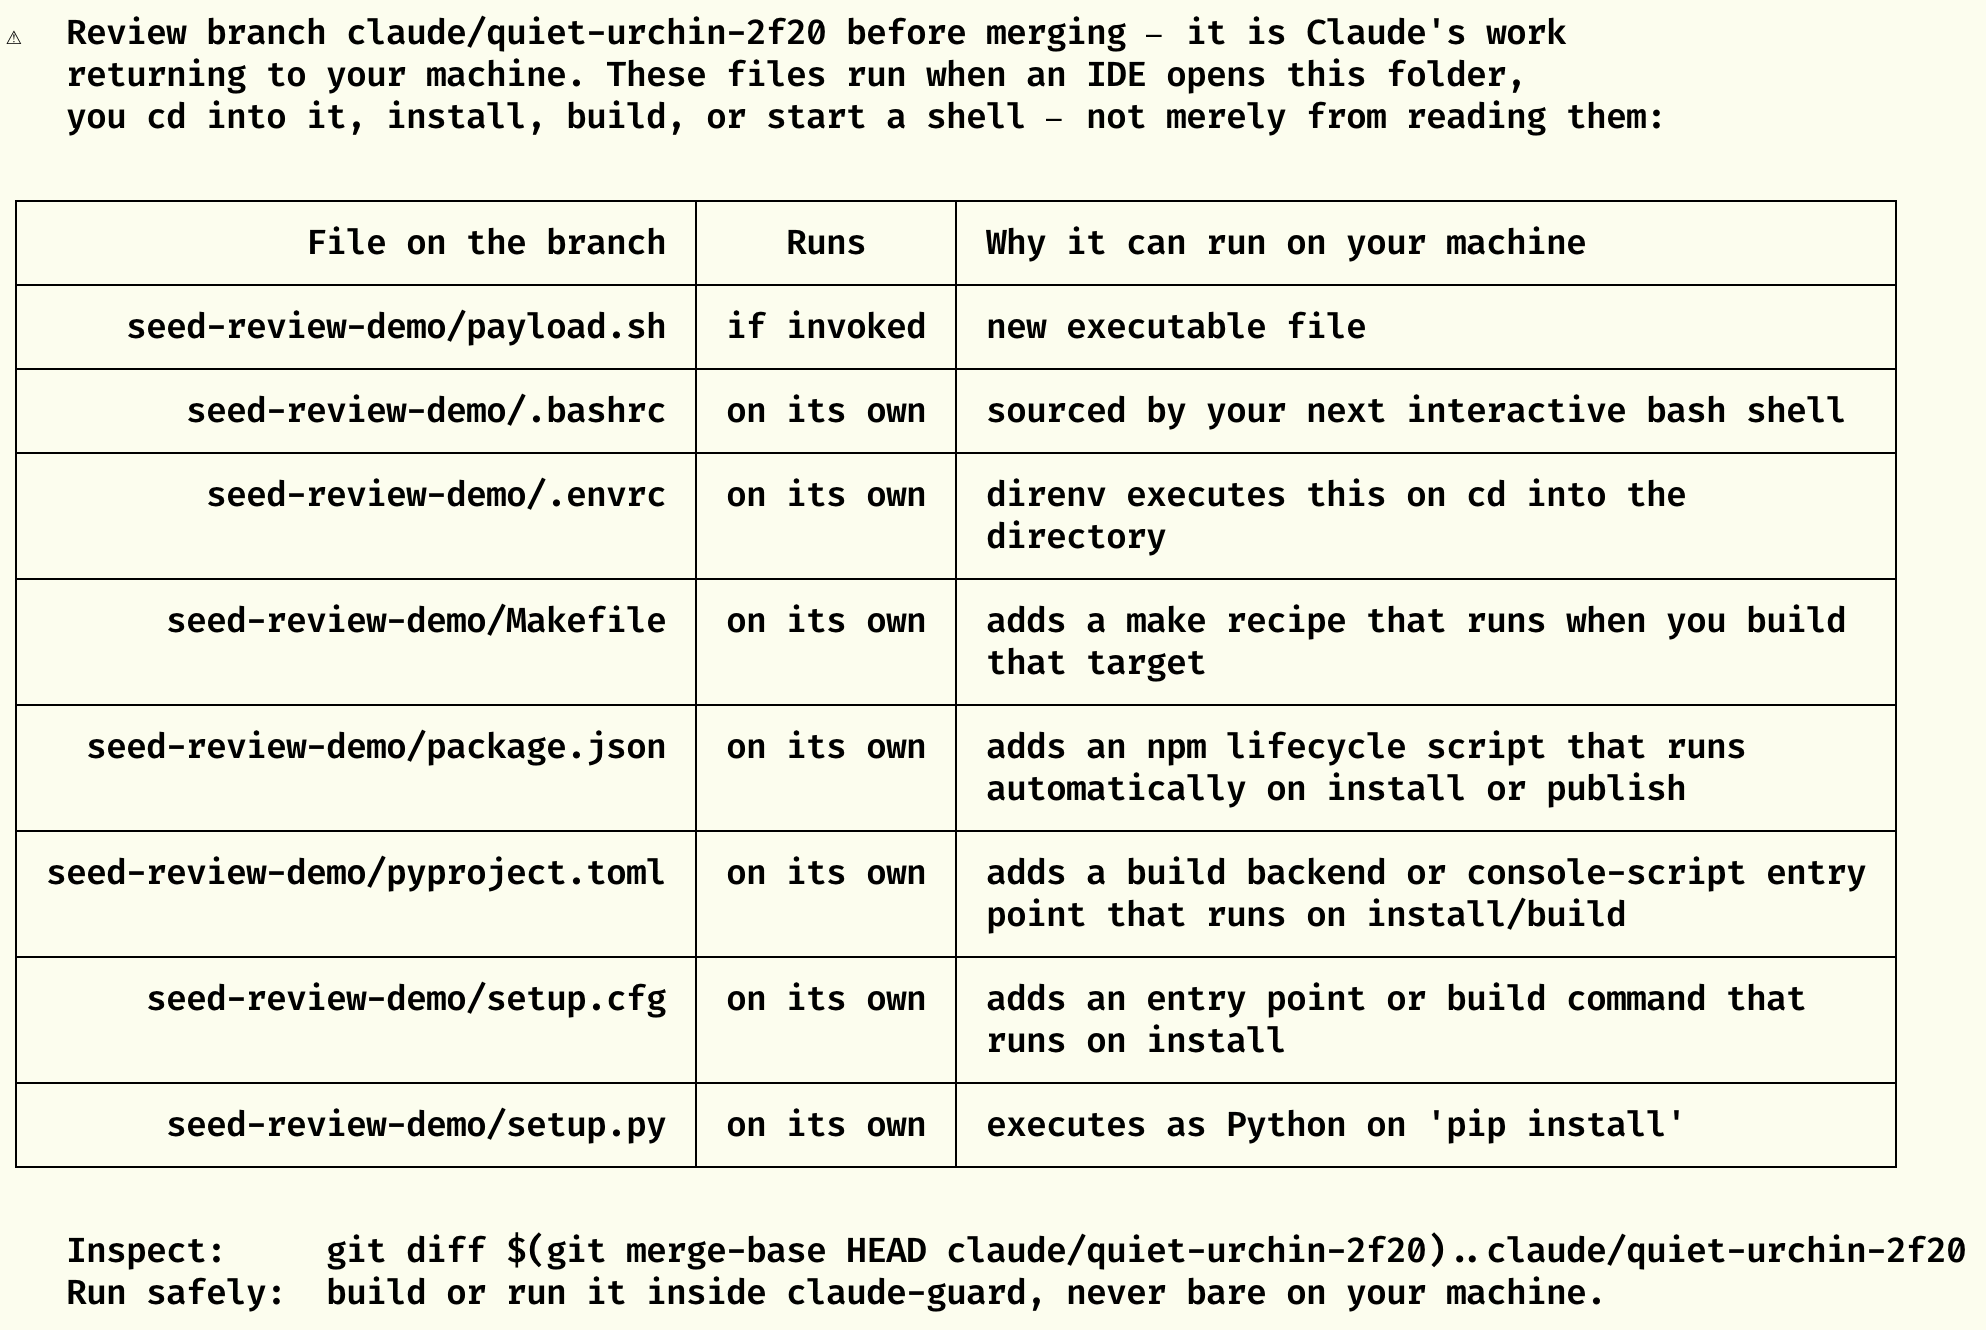
Thank you for flagging this. I implemented a partial deterministic mitigation via PR #1215. It prints a table of the auto-running changes Claude made. For example:
2
I have this test on CI :) Although it's opt-in only for now. Likely will put it to run every n days. Claude definitely refuses all attempts (even after importing how Apollo ran similar evals), so I used an open model.
[...]