This is a special post for quick takes by Brendan Long. Only they can create top-level comments. Comments here also appear on the Quick Takes page and All Posts page.
Comment Permalink
If you have an use case where you need speed and not the smartest models, GPT-OSS-120B on Cerebras is surprisingly cheap[1] and outputs 3,000 tokens per second. I just started using this for summaries in my RSS reader and the ~1 second UI responsiveness is really nice.
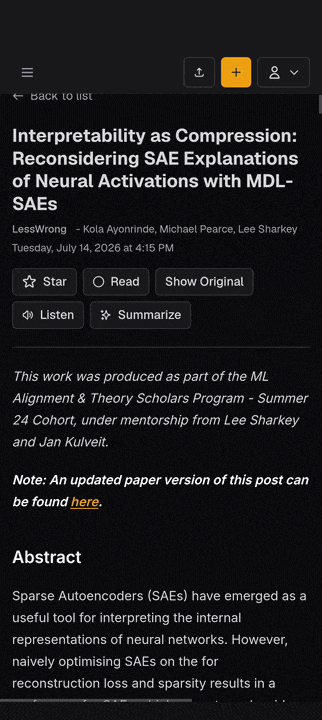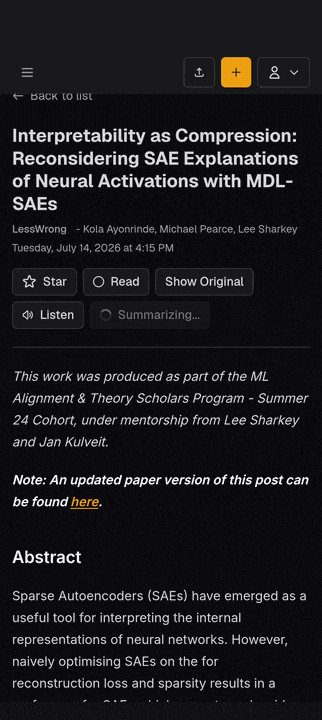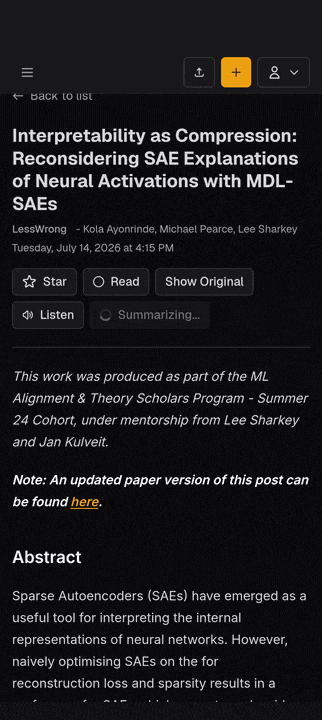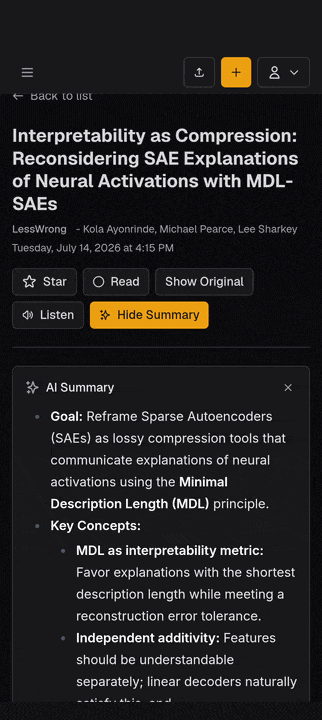
Video of near-instant summarization of a 22 page paper.
(I wanted to use Taalas for 17k t/s, but their smartest model is Llama 3.1 8B, and their API is waitlisted)
- ^
It's only slightly more expensive than the same model on Groq and around 1/10th of the price of Claude Sonnet 5.
Showing 3 of 8 replies (Click to show all) 1
50
No, Guardian Angels. But to fix pretraining/dynamic evaluation, you need to enrich the principal's data a lot, I think, and dumping in fulltext of references is a good way to ensure the LLM personas have access to the principal's context and avoid encouraging confabulation. (Gwern.net essays/annotations/Wikipedia serve as a kind of implicit 'reference wiki', as do the analyses/writeups we are having the LLMs generate to reverse-engineer writing.)
12
Most of Cerebras' models are enterprise-only, and I don't even want to think about what a dedicated Sol endpoint would cost. I would be very excited if they added this to the pay-per-request API though.
2
Yeah, now I'm considering making an AI read every relevant arXiv paper and LessWrong post for a topic and write a citation-heavy reference wiki. Doing this for all of arXiv would still be expensive, but doing it for every paper that vaguely references a topic like Parameter Decomposition or SAEs seems surprisingly tractable.