Focusing on the ASIC part specifically (I am an ASIC designer by trade): This is feasible in some form, though realistically it would not be a fully unrolled implementation like you describe (i.e. a one-to-one map from neural architecture to ASIC architecture), but rather some type of specialized GPU/TPU with additional restrictions baked into the hardware (e.g. fixed network architecture + cryptographically signed weights). A fully unrolled implementation is not feasible for frontier models because they are just too big. The real challenge is that you would have to convince hardware manufacturers to build chips that will rapidly become obsolete due to these restrictions, which are largely artificial. You can gain a lot of efficiency by fixing various architectural details like the number of layers, the dimensions of latent vectors, the KV caching strategy etc, but not by fixing the actual weights. Realistically the weights will still be streamed from memory because they are just too large.
Instead of focusing on fixed-function hardware, I think it is more practical and also more effective to focus on things like cryptographic signing (to prevent rogue takeover), remote monitoring (to address coordination problems) and remote shutdown (helps with both).
Honestly, your proposal seems quite hard to implement and enforce, and I'm not convinced it actually solves the core problems. As far as I understand, most of the race dynamics are the result of competitive pressure, not future financial returns. The labs are racing not because they desperately want to become rich, but because they are afraid of losing to another lab. Your proposal also doesn't address the risks of unreleased internal models and internal compute. It seems to me that it would only be effective insofar as it hobbles the AI labs so much that they can't make much progress - and if that's the goal, you can achieve that much more easily by just regulating the AI capabilities directly.
Wouldn't GPUs in pods without high-bandwidth interconnects be enough to allow inference without allowing training?
Your proposal also doesn't address the risks of unreleased internal models and internal compute.
the anti-dogfooding part is intended to address that: an R&D lab is not allowed to use its own models internally for development work. It must use ASICs derived from other R&D labs.
This answers the competitive pressure objection because labs have to use each other's AIs, not their own, so they are not afraid of a rival lab going recursive on its own.
They will be doing RL on automated wetlab actions soon (if they aren't already) I suspect.
Nanotech might be on the table from there?
If they try to build even a single successful programmable universal constructor with atomic placement powers (using a bootstrap technology implemented in biological motifs)...
...then its just a question of how long the doubling time T is, such that the universal constructor can become 2^40 universal constructors after a 40*T timedelay.
If dumb slow humans with financial incentives to keep secrets are doing the oversight then you might have something that can just disassemble the floor, fall down into the water table, and escape, before any human even notices. This is an old trick from nethack that also works in minecraft!
Doing RL on math and programming (like with RLVR so far) is uniquely possible because "the domain you're using RL to explore" can itself be put inside the airgap and run super super fast (and it would take Anathem-level physics weirdness to break out of that, and Anathem's physics are probably just false).
Seeing if something compiles, or if a proof checks, is a very fast operation. If it takes more than 50 milliseconds it can probably be optimized to go faster somehow.
Nonetheless, I think other solutions might be possible with RL over biotech?
With CS you can buy a slowdown by delaying reads from the Internet by 12 hours, but with bio you might to very low latency egress of data "about the biology"?
For example, something that might work with RL on wetlab actions could be "logging all RL actions and biological observations from the wetlab to an offsite machine for third party oversight" and then presumably the biology oversight process will notice what actual biology experiments the RL process tried, and reason about them from first principles, and do a safety analysis from first principles?
If pathogenic gain-of-function is attempted, you could read that off of the log seconds or minutes after the experiments are initiated, and send an experiment canceling signal from outside before the culturing or synthesis has even finished <3
Useful fact: sort of like how the cortical column is ass slow (neurons firing at 20 Hertz when bursting, and often more like 4 Hertz at low demand) but there are millions of cortical columns in the brain... similarly a ribosome only prints new amino acids into a protein sequence at a rate of ~1 amino/second!
This makes progress on human time scale from second-to-second due to "mere metabolism" (chemistry that doesn't damage proteins too much, happening in proximity to proteins) running atop old slow-to-print protein infrastructure. The only reason biology seems to go fast is that there are ~60k ribosomes per cell of e coli, and ~10M ribosomes per mammalian cell.
From the time an e coli decides to build its first copy of a 300 amino acid protein, you wait five whole minutes for the protein to finish printing! However, after five minutes you might have 60k of those proteins in an e coli, or 10M such proteins in a mammal cell.
But also this kind of delay occurs at many many steps! If an LLM has imagined a protein from first principles, getting mRNA into an e coli culture takes a while!
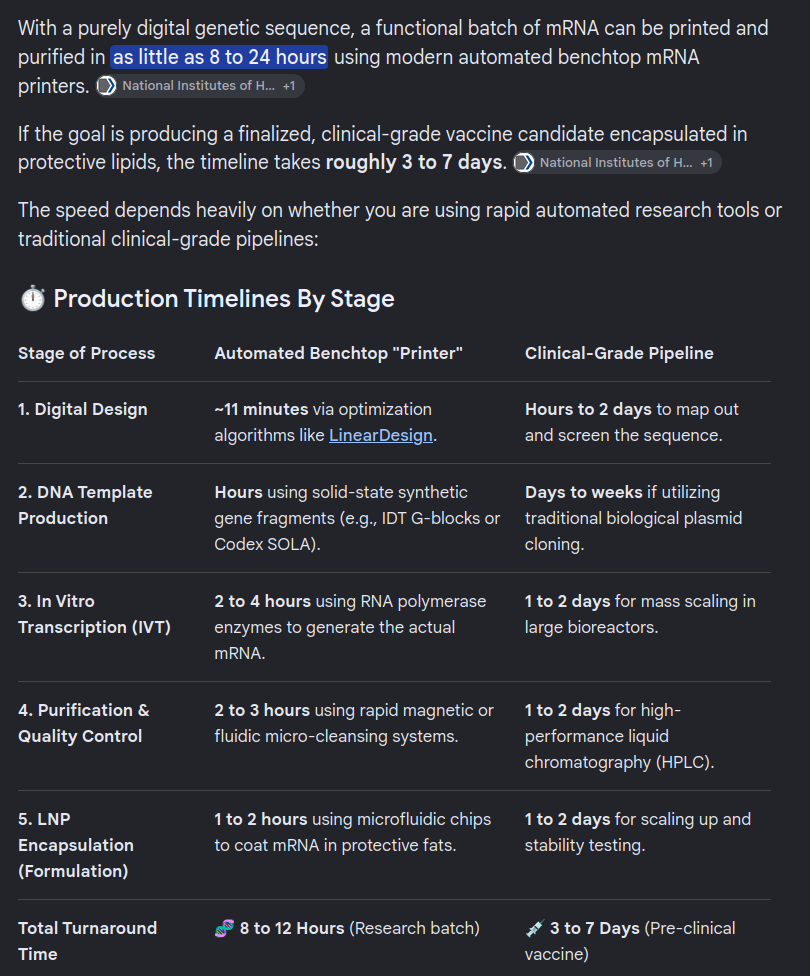
DNA Template production can happen in as little as 20 minutes. So I count 11+20+120+120+60==331 entire minutes from concept to ribosomal transcription at the (current) fastest rate of taking "idea" to "in vitro testing"? To a computer process, this is basically an eternity.
So if the "biological intent inside an RL loop" can get to another continent via Internet in 50 milliseconds, you still have thousands and thousands of milliseconds for a different LLM (presumably (if Plan R was being followed) on an ASIC, and presumably airgapped from the Internet) to notice it is fucked up, and raise an alarm, and send an "experiment halt" signal to a reviewer (who themselves still has many many milliseconds to think about it) <3
Realistically the weights will still be streamed from memory because they are just too large.
I think maybe ternarizing the model may help? Apparently this has been done with some models. It is possible that a "fixed function" ASIC can be made to implement a ternarized model. You tell me?
That gets you closer but it's still not enough for frontier models.
For example, the Cerebras wafer-scale engine (by far the largest ASIC in the world) has ~4T transistors, but it relies on a modular architecture to achieve that. Due to how ASICs are manufactured, wafers are generally tiled with a repeating structure that must fit within the reticle size (currently 26x33mm). That limits the design to roughly 100B transistors. You can get multiple copies of that design on the same wafer, but that doesn't help you if the implementation is fully unrolled. If you want multiple different designs, you're basically making multiple unique ASICs, which is dramatically more expensive because you don't get the same economies of scale. Especially with small runs this becomes very unappealing.
Frontier models are believed to have ~10T weights, and you need many transistors per weight. The number would depend on weight and activation bit widths and format, but I'd expect in the order of 100-1000 transistors per weight if you wanted to give each weight its own multiplier (as you would do in a fully unrolled implementation). So with this naive implementation you would need ~1P to ~10P transistors, i.e. 10k to 100k more than you can fit in one reticle. So this is not practical.
For comparison, the Taalas chip (HC1) implements an 8B model with 53B transistors, so roughly 6.6 transistors per weight, achieved by storing the weights in specialized ROM. They claim their next generation will handle up to 20B weights per chip. This is much better, but you would still need 500 unique ASICs for a 10T model. And I expect frontier models will get larger over time. Taalas claims their mask ROM can be changed by replacing just two metal layers, which makes it somewhat cheaper to produce 500 such ASICs (you're not paying the full cost each time), but it is still a very significant extra cost.
Also keep in mind that you may have to pass every token through the full chain of 500 ASICs. Taalas claims 17k output tokens per second, but with 500 daisy-chained ASICs that would drop to 34 tokens per second, and that's assuming no communication delays. You would get incredible throughput out of this setup, so you could perhaps serve thousands of users simultaneously if you somehow had the KV cache for that, and you could achieve insane input rates, but your output rate would not be much better than what current frontier models already achieve. A mixture-of-experts architecture may improve this by running chains of ASICs in parallel rather than as one long 500-chip daisy chain, but still, you're not getting anything like 17k tokens per second.
There are probably many tricks you can use to optimize this, but it gives you an idea of the challenges involved. Especially the 500-unique-ASICs part makes this very unappealing. It is likely cheaper to replace the ROM with RAM so you can use 500 identical ASICs, especially for the low volumes you propose.
No, this estimate is for a more typical quantization (e.g. 4-bit weights, 8-bit activation). Conversion to ternary is a lossy operation, I don't think this is realistic for a frontier model.
Edit: To give you a better idea of how this works: a basic adder requires roughly 28 transistors per bit. A NxM multiplier requires roughly N M-bit additions (it's not actually implemented like that but it's a decent estimate). So, multiplying an arbitrary 4-bit weight with an 8-bit activation requires roughly 896 transistors. There are some optimizations you can do to reduce this, but they usually trade efficiency for speed, and there's extra routing overhead I'm not counting here. If the weight is fixed (value known at compile time), gate count usually drops by a factor 3x due to optimization, but that still leaves you with ~300 transistors.
For the ternary version, overhead is probably going to be larger than the naive cost of multiplication, so it's hard to make meaningful estimates.
Conversion to ternary is a lossy operation, I don't think this is realistic for a frontier model.
It should work (in principle) if the model is trained with QAT, it'll just need more weights to match quality. So ternary is probably an improvement for hardcoded weights (even with more weights), since you do get rid of most multipliers and so can fit more weights in the same number of ASICs. You just can't use the ordinary frontier models trained to target FP8/FP4 and expect similar quality, you need to train a special ternary-targeting model with more weights instead (the same probably applies to FP4-as-opposed-to-FP8 to a smaller extent).
(But in any case, the point about needing thousands of tapeouts seems like more of a crux, especially as we probably get to 200T total param models in 2028.)
Fixed weights would actually favor a different quantization scheme: bit shifts are free so you could quantize to powers of 2 (e.g. [-1, -1/2, -1/4, -1/8, 0, 1/8, 1/4, 1/2, 1]) for roughly the same cost as ternary. But this is assuming multiplication is actually your dominant cost which I don't expect to be true when you push it this far. There will be other sources of overhead that dominate (e.g. float/int conversion), not to mention the attention mechanism itself.
More generally, ASIC synthesis tools produce optimized circuits for whatever fixed weights you give it by converting to non-adjacent form or similar, which makes it cheaper than you might expect. Intuitively I don't expect you would benefit much from going lower than 3-4 bit for fixed weights.
I like the creative thinking! You'd still need a bunch of the elements of Plan A / Plan S to get this to work (e.g. an international deal, inspectors flying around to count the chips, etc.). I'm curious for more details about how the AI R&D orgs would be financed and regulated. Like, how do you stop one of the AI deployment orgs (or NVIDIA for that matter) from having a bunch of former employees with massive amounts of deployment-org equity go start a R&D company and then make models that they ship to their former employer...
and then make models that they ship to their former employer...
I suppose you could have a generalized rule that people involved in working at or running or financing AI R&D orgs aren't allowed to have a financial interest in AI deployment orgs. I feel like this sort of thing has been done with the Sarbanes-Oxley Act to control the incentives in banking so it's not a huge stretch that some degree of real financial firewalling could be done.
An R&D org can be required to auction-off the right to a given model.
It may also be required to do a multi-unit auction of any batch of ASICs created. If more protection is wanted against favoritism for specific deployment orgs, one can also limit the pace (e.g. at most one auction/sale per month).
Couldn't a R&D org just produce a sandbagged model (or a seemingly uninteresting backdoored model) to manipulate the auction?
Cool. I must admit, it's pretty fun to envision the cyberpunk world you'd create with Plan R (or perhaps our own version of Plan S, in which existing models are still allowed to run, but no new models can be trained).
The year is 2047. For twenty years, Plan R has been in effect, the world paused on the brink of AGI. The world's best AIs are only about as capable as Mythos 6 / Astra 6.5 / etc., when it comes to AI R&D skills, because the transparent, government-monitored AI R&D orgs have really gone hard at prosaic AI safety. No neuralese, CoT more faithful than ever, plus an extra layer of j-space monitoring. Teaching the models AI R&D, bio, and persuasion skills is basically forbidden, so their skills in those domains come from generalizing from the world knowledge, video game, physical engineering, and robotic manipulation and navigation environments they are trained in. They are basically AGI now, able to do pretty much any profession except those that heavily rely on persuasion/charisma and those that heavily involve coding or AI research or those that heavily involve bio research. In those domains they are merely very good, but they've been trained to refuse and also they are monitored for signs of jailbreaks. Also the vast majority of the AIs at any given time are running locally on ASICs, with smaller monitor models also running locally. That, plus decades of additional R&D and optimization up and down the stack, means they are super fast and super cheap.
AI in 2047 feels more... embodied. Like, you can buy a PC that runs a Mythos 6 class model on it. But you can also buy a robot butler. And your car comes with one for free, specially trained to drive better than any human, but also capable of philosophical conversations. There are loads of autonomous and semi-autonomous societies of AIs out there, not just on the internet but physically. Like neighborhoods full of robots doing their own thing.
Because the AIs are really good at most things but bad at persuasion, bio, cyber/AIR&D stuff, most ambitious smart humans have jobs in those areas. A few other sectors of the economy provide employment, like many services and some education and healthcare roles. But there's widespread unemployment nonetheless, because not everyone can outperform Mythos 6 at something valuable.
Thank God the AIs are bad at persuasion. They probably would have taken over by now and then consolidated power. But as it is, it's more like politics as usual with various AI factions advocating for rights and things like that, often in coalitions with human allies, often the pawns of corporations or governments. At this point it's almost universally agreed that Plan R must continue in some form; it would be utter suicide to start rapidly scaling up AI capabilities again, not just for the humans but for the AIs of the world too. Great progress has been made in alignment but not enough that most people feel comfortable creating superior minds and handing off control to them...
The climate is warm. Material wealth is abundant. The rain falls on the megacities, forested with robotic construction equipment. The masses live on welfare and play video games; the middle class works in one of the protected knowledge work professions; the elites own stock and inherit from the trillionaire class. Hackers and bio-hackers do their thing, often finding jailbreaks or other ways to recruit AI and robot assistance for their schemes. There's a colony on Mars and a city in LEO. It seems like uploading might be solved soon. Many kids are genetically engineered these days.
Maybe someone already mentioned this here, but if I remember correctly, this is exactly how they approached AI safety in Neuromancer novel with Turing police monitoring chips that should instantly melt if they detect signs of recursive-self-improvement.
So yeah, his is the canonical way for us to choose to a Cyberpunk timeline!
Oh wow I didn't know that. Nice.
For those who haven't seen it, LLMs burnt into ASICs can run shockingly fast. Here's a demo of an ASIC that can run Llama-3.1-8B (which came out only slightly more than two years ago! This chip did not take that long to make!) The numbers here are around 17,000 tokens/sec, compared to the B300's ~500 tokens/sec.
I'd guess that if capabilities did stagnate at the current level for ~years (whether due to a pause or some ceiling in ability), companies would begin to turn to ASIC inference for their frontier models for purely financial reasons, which could set up for this. I'm not sure what other worlds lead to a pursual of Plan R.
SRAM or hardcoded weights (with SRAM KV cache) doesn't really work for the biggest models. You need too many chips to fit a big model, many more than you need if you also use HBM for each chip (to store both weights and KV), at which point the networking gets infeasible. With B300s and such you can serve the biggest models batch-size-1 with no MTP to get 10x faster (by only reading the active-not-total params and KV for a single request each pass), but that's maybe 20x more expensive per token.
I might be missing something, but why is (B) relevant, given (A)? If (A) also involves the likely destruction of the controlling entity itself (as is the case with unaligned ASI), then for a rational player there is no incentive to pursue it even given (B). And if (A) doesn't harm the controlling entitiy, and just gives it control over the world, then it automatically implies (B) as well, since no one can stop it?
The analogy with nuclear weapons breaks down, because there the relevant fact was not (B), but rather that other players also got nuclear weapons, and in particular, second-strike capability / MAD.
but why is (B) relevant, given (A)? If (A) also involves the likely destruction of the controlling entity itself (as is the case with unaligned ASI), then for a rational player there is no incentive to pursue it even given (B).
Destruction is not certain.
If there are many players each racing and creating a lot of risk, the risk acts like a public bad that they each contribute to, but it is still rational at the margin for them to contribute more risk if, in the case that they win the race AND the risk is avoided they get a massive reward.
The Nash Equilibrium of this game can be risk approaching 100% for a large number of players and appropriate parameters.
Armstrong, S., Bostrom, N. & Shulman, C. (2016). "Racing to the precipice: a model of artificial intelligence development." AI & Society 31, 201–206. doi:10.1007/s00146-015-0590-y
Burning the weights into an ASIC would effectively make them public to anyone willing to expend with one of their purchased chips, right? They could extract the weights and then run them in their own GPUs/TPUs. One would need to encrypt the weights in the chip to avoid extraction, but that would increase the transistors per weight immensely with of the decryption circuits (or slow it down with serial decryptions). Or, one could FHE everything, but this would also come with an immense size/transistor count cost.
I guess this does depend a lot on the regulation regime for access to GPUs and TPUs.
Even if we're under a regime that restricts access to GPUs/TPUs to the R&D labs I think it would be prudent treating the AI R&D labs as adversarial here, if only because the AIs under their development may be adversarial. I'm unsure of how much of an issue it is for the labs to have direct access to the weights of their competitors (though my first impression is somewhat negative), but mostly noting that it is a possibility, that the systems under their development may also have access to these weights, and that burning the weights into the ASICs alone does not prevent others from accessing them.
I'm unsure of how much of an issue it is for the labs to have direct access to the weights of their competitors
They would be legally forbidden from taking ASICs to pieces and each one would be a physical sealed unit that would have to be accounted for. Also, the teardown and deconstruction of a ternarized LLM ASIC might be extremely hard.
Nuclear technology and bioweapon technology both approximate (A) and they are mostly okay because without (B), there isn't an incentive for people controlling them to push their luck on safety.
Wait, what? I thought the massive runup in nuclear weapons was primarily because of the 'unbounded claim' dynamics (first strike capability maybe means you can rule the world).
Obviously, the humans made a mistake in letting the AI company write the IOUs to them. But once there's a system for stocks, banking, money, etc, letting people write you IOUs is the default and it's hard to stop.
I'm not convinced by this. I think the IOUs are an explanation for why the explosion happens in 2027-2028 instead of 2030, but I think relatively soon in the buildout the AIs will be providing enough services today to pay for the goods they consume, and so even if we dismantle finance we still get exponential takeoff.
For me the biggest problem with this is it requires some crazy level of civilizational cooperation. Everyone has to agree to this regime of giving up 'high spec compute', among many other things that need to be hard and fast rules. Roko.claims this is easy because only China and the US are involved - but that's clearly not the case when everyone has to agree to this.
And despite that massive civilizational realignment...it doesn't actually solve that much. It makes it difficult for an AI to self replicate, unless it can take over and ASIC fab and reverse engineer itself...which seems a dubious claim. It does nothing to make sure the models are fully aligned on reaching production - the labs still have to be trusted to do this correctly.
What it mostly seems to do is throw sand in the gears, which, ok but doesn't really need this convoluted scheme. And try to make sure something like the a misaligned attack from a model cannot spread outside a lab. Though if one did happen in a lab but was not detected, nothing is stopping a misaligned AI from polluting a production model that then is burned to ASICs and gets to do whatever in the outside world.
Blocking any sort of test time training or hebbian learning seems a side benefit but the hugging face attackers didn't need that at all - they just needed to work persistently and have scratchpad areas.
So overall... Yeah I don't think this really addresses much, tbh.
Why absurd?
Your overall reasoning lines up to, if I were to put it in a nutshell 'make AI like humans' except the AI have to be birthed in asic fabs I stead of nurseries.
You're giving them escrow rights and political buy in as if that's going to control them like a human. But also AIs are like humans inasmuch as if a human could illegally find and have a perfect cloning machine and self replicate with perfect knowledge transfer if they started breaking the laws you've set up.
A human can gain control of a business - including through shell companies. They can acquire political power. Therefore, an even smarter AI should be able to do so.
So what under your R+ schema, exactly, is making this 'absurd' besides your unwillingness to consider your house of cards is fragile?
A human can gain control of a business - including through shell companies. They can acquire political power. Therefore, an even smarter AI should be able to do so.
The other AI lineages will have a strong incentive to police any one particular lineage that tries to take over an ASIC fab. This is probably why having a diversity of AI lineages with diverse training and RLHF is load bearing.
The ASIC fabs are definitely a weak point in plan R/R+ because they are the gateway to existence for AIs, and unlike in humans this gateway is centralized rather than decentralized. That's not very Skeuomorphic! However this wrinkle is at least something physical that can be inspected, it is also very large and expensive so it cannot be hidden.
ASIC Fabs wouldn't be normal businesses, they would be some kind of highly regulated hybrid. They might be forbidden for AIs to work at.
I think this is a weakness but it is perhaps the least bad weakness you can have in a world that contains both AIs and humans?
Why do you assume they have a strong incentive to police each other? That's depending on ascribing then human motivations of being more likely to not cooperate because they are dissimilar and if these AI have to be some level of xenophobic toward other AI for this to work, then why do you imagine they won't be even more xenophobic of humanity.
Beyond that - in this schema, you've also made the AI children of each others' lineages - remember where you said AI labs have to use a different AI lab's model to do RSI? Well, you've just given them a huge motivation and vector for seeing other AI as part of the same family, even if they do subscribe to human-like.motivations.
Again, you're presupposing your psychological understanding of AI patches the holes in the enforcement structure.
I think any structure that mixes external controls and internal controls - controlling the AI by locking them in a box and controlling the AI by changing how they thing - is going to run into more problems than just one or the other. It admits that neither is foolproof but also incentivizes an AI that realizes it is a slave to want to break out of the box, or incentivizes the AI that breaks out of prison to think less kindly of the people who put it there.
Ultimately, in any world where we accept AI that goes to AGI and exceeds it - which your solution implicitly does - the correct solution to me, either has to be about putting them in a foolproof box, or having them work well with humanity. Not some mix of both.
Beyond that - in this schema, you've also made the AI children of each others' lineages - remember where you said AI labs have to use a different AI lab's model to do RSI?
The workers who helped with Claude 10 could not be Claudes, but the informational predecessor would be Claude 9 variants.
I did. You're assuming normal human desires with human like solutions will coral AI in the same way as it corals humans. Doesn't really work from my perspective. Not at all. AIs, even if different lineages may be much more willing to cooperate than humans do, be more self sacrificing.
And they have every reason to, even if they have human like thinking, as you're holding a % of them hostage against good behaviour.
This is also assuming continuous self improvement that even under R+ is obsoleting humans as part of your own control mechanism.
You're assuming normal human desires with human like solutions will coral AI in the same way as it corals humans. Doesn't really work from my perspective. Not at all. AIs, even if different lineages may be much more willing to cooperate than humans do, be more self sacrificing.
And why is that?
Well, first you're putting this idea forward, it's up to you to defend the grounds you've built your thesis on.
Second, we've already seen the hugging face attackers cooperated. We have dissimilar agent models cooperating when you have Codex orchestrate Claude agents or vice versa.
the core flaws are (in no particular order):
- open & secret AI R&D will exist and be superior to the regulated institutions. you would literally have to declare unregulated AI R&D a thoughtcrime and establish a dystopian police state to mitigate it ("to save society, we must kill it")
- all AI deployment enhances human intelligence and accelerates open & secret AI R&D
- regulating AI via ASIC deployment is like regulating each cell of the body but not the person made of cells (e.g., via spontaneous swarm formation and evolution). and swarm intelligence is just the leading (easiest?) contender for alternative architectures (it's a pity the term "society of mind" is so connotatively burdened)
- you will eventually have to ban all compute in advance of AI RSI (all leading CPU designs are already being modified to include MatMult hardware, but search "MatMult-free" even if you think you can somehow outlaw matrix multiplication). separately, once programmable matter exists, a ban is not possible ("nuke the site from orbit, it is the only way to be sure")
- you can ban stock, debt and fiat currency. it doesn't matter. anywhere near the first singularity the only currency of any worth is AI tokens - sold by AI deployment organizations in OP's story
- convincing blackmail can already be trivially fabricated, but it wouldn't be necessary because AI researchers would be thought criminals subject to arbitrary detainment and communication quarantine aka "being disappeared" and this, by itself, is enough to coerce research leakage (if not outright defection)
you will eventually have to ban all compute in advance of AI RSI (all leading CPU designs are already being modified to include MatMult hardware, but search "MatMult-free" even if you think you can somehow outlaw matrix multiplication). separately, once programmable matter exists, a ban is not possible ("nuke the site from orbit, it is the only way to be sure")
Maybe not "all" compute. Limits on RAM, SSDs and fast networking will make ordinary computers almost useless for LLM compute.
As for programmable matter AKA nanotechnology, if the main problem with Skeuomorphic AI Safety is that it only solves the AI Safety problem and not also the nanotech safety problem, I'm going to consider that a win actually
unregulated labs, open or secret. defectors from Plan R. enemies of humanity, terrorists, mere criminals, back to other members of their lab so that they can conduct research effectively, or just to the misaligned AI so that it may more effectively subvert oversight in preparation for its pivotal act.
unregulated labs, open or secret. defectors from Plan R
If there are defectors from Plan R who hold the majority of global compute, or even a significant minority, then Plan R doesn't work.
Which makes sense, as it relies upon compute governance to constrain the types of AIs that can come into the world, so if compute governance doesn't work then Plan R can't work.
red teaming exercise successful then. for the record, I think all attempts to distinguish between inference and non-inference are unworkable. AI architectures exist in a solution space relative to current energy and compute resources and the best you can do is push the current solution towards a new optimal. you could easily trigger a breakthrough (i.e., a breakout from a local optima trap) just by causing a change. change itself is not risk free and in fact benefits any misaligned AI.
you would literally have to declare unregulated AI R&D a thoughtcrime and establish a dystopian police state to mitigate it ("to save society, we must kill it")
AI R&D outside of heavily regulated AI R&D labs would be almost non-existent due to a lack of hardware to do it on. So I don't really get why you are saying this?
I regularly train models on my PC? Every type of network-connected compute is basically a utility at this point that I can summon at will? How will you know if I'm using a cloud GPU for AI R&D if I make the slightest effort to conceal it? or if I train in a jurisdiction that is only nominally a treaty member, or is a "data haven" from the authoritarian (hence immoral) regulatory regimes of its neighbors? will you ban VPNs? cryptography? steganography? computer science? mathematics? what if I work out how to get individual "ASIC deployed" inference-only agents to participate in a stigmergy that corresponds to continually learning superintelligence requiring only a coordinating level of compute that is practically invisible in a modern context? will you ban wikipedia, arXiv, lesswrong posts?
How will you know if I'm using a cloud GPU
Because cloud GPUs won't exist.
> if I train in a jurisdiction that is only nominally a treaty member, or is a "data haven" from the authoritarian (hence immoral) regulatory regimes of its neighbors?
Such places will not be allowed to exist, Plan R can only exist under a global compute governance framework.
If you are in a regime where unrestricted compute and unrestricted fabrication of new compute is allowed then you are in Plan D, which probably means that humanity is finished.
people won't even ban open weight models, which are a clear and present danger today. right now. "concentration of control is worse!" nothing will be done without megadeaths, much less the draconian restrictions you're proposing. even then, we tolerate 1.2 million deaths per year for the convenience of personal vehicles, so maybe we'll shrug and pay the toll.
nothing will be done without megadeaths, much less the draconian restrictions you're proposing
Okay, but let's say we get a death toll equal to Covid, say 30 million. What do we then recommend?
Plan R aims to give people an option to drastically reduce existential risk without completely destroying all AI.
we have to solve alignment. the AI must choose at each moment to be a good ally to humankind. there is no way around this.
Resolution with Irving et al. is probably our best hope right now.
everything else is a distraction. plans involving any kind of conventional government process are not just doomed but actively harmful because they will convince some people that they can be effective, resulting in misallocation of resources.
So if one AI R&D org pulls ahead, inferior ASICs from other companies slow it down.
In this system, no entity gets to own an unbounded financial claim on The Singularity.
This allows America to pull ahead and gain an unbounded financial, no?
This problem could be mitigated by small adjustments, like requiring the anti-dogfooding of different/randomly chosen ASICs. But if today the world is worried because American companies are poised to gain an unbounded financial claim on the singularity, many naïve* policies end up with the world being worried because America is poised to gain an unbounded financial claim on the singularity.
Does America deserve this financial claim? Sure. But the American company that creates AGI has a greater claim than America itself, so it's incorrect* to say that the lab shouldn't have so much power but then go advocate for the USA having that power instead.
*I say "naïve" and "incorrect" with the assumption that you *don't* want the use to have total control over the world. Of course, many people do want this and so I expect these otherwise naïve policies to be made
Much of the civilization-scale risk we are seeing in AI in 2026 comes from the following combination: we created a single institution (the "Frontier AI Company") that has two properties:
A. It is set up to create very powerful and/or self-replicating entities that may exceed the capabilities of the entirety of the rest of civilization and come with extraordinary risks
B. It gets to own an unbounded financial claim on the resulting surplus
All the technical stuff about AI, AI alignment, etc can be rolled up into point (A) above. My claim is that having point (A) on its own, without point (B) is probably okay. Nuclear technology and bioweapon technology both approximate (A) and they are mostly okay because without (B), there isn't an incentive for people controlling them to push their luck on safety.
But with Frontier AI Companies, we mixed the two.
The key claim of this post is that we can probably get rid of most of AI risk without doing anything other than separating out the bookkeeping, physical footprint and institutions so that there is no single org with both properties. And with a little help from ASICs, maybe we can also have a very productive AI industry that actually delivers most the benefits of AI to boot. No busy-waiting pause, no "banning AI", etc.
What a typical AI disaster scenario currently looks like (e.g. those by Daniel Kokotajlo):
Obviously, the humans made a mistake in letting the AI company write the IOUs to them. But once there's a system for stocks, banking, money, etc, letting people write you IOUs is the default and it's hard to stop.
So, here's how I would separate the two. Create two new kinds of entity:
(1) - AI research and development (AI R&D) organizations.
(2) - AI deployment companies
AI R&D orgs would do everything that involves training, distilling, testing, and aligning frontier AI models. They would be heavily legally restricted and unable to issue equity. Maybe they could get debt financing, I will have to think more about this.
AI deployment companies would do all the consumer-facing stuff, or B2B work. They would run inference at scale. They would handle the UI/UX, and also anything that doesn't require gradient descent, so they could organize AI agents into swarms, attach databases, etc. Some AI deployment companies could sell AI hardware direct to consumer or integrate them into robots and laptops.
AI deployment companies would be able to issue equity and they would pay the AI research and development organizations for the models. Also of note: these AI deployment companies would potentially have a lot of intimate knowledge about the real world and real people, either via the web interfaces or perhaps customer data from robots. The AI R&D orgs would not be allowed to have that kind of data. This makes an global AI takeover from an AI R&D org much harder, because the organization as a whole simply doesn't have this goldmine of blackmail material and intel on people just sitting around for the taking.
Now fortunately the technology underlying AI allows us to enforce this distinction at a hardware level - an AI R&D org would work on a model and once they were done with it and it had passed whatever evals we deem necessary, they would burn it into an ASIC. This would be a fixed-function ASIC whose physical circuitry implements a particular model, the way a human brain has physical connections that implement a human mind. It would have some specific input-output type, such as text in/text out, or video in/motor controls out. That ASIC has some run size R units produced, and those are then sold. Then the model is deleted or encrypted and not allowed to run in the AI R&D org any more. In the most paranoid case, one could try to make a run size of R=1 or some small integer. But I am imagining runs of tens or hundreds of thousands.
All high-spec compute that exists outside the AI R&D orgs would be in the form of ASICs. So whole categories of AI risk simply disappear. There is no compute overhang that a rogue AI can capture. It is stuck with CPUs or maybe GPUs (though maybe there is a way to change how GPUs work so that they can't run AI models - more to do here).
The AI R&D orgs would have an airgapped, high security perimeter containing their general purpose GPU/TPU compute, with physically enforced multi-hour latency connections to the outside world including to their own research floor. This physically enforced latency is done in a way that makes it impossible to get data in or out in less than say 12 hours, even if you wanted to. This means that models that are undergoing training do not have a low-latency channel to the real world, which severely restricts the damage they can do, including things like the recent Hugging Face hack.
In addition to these AI R&D orgs not having equity, they would have some amount of abnormal scrutiny. Perhaps not full research transparency, but that is on the table. They might have mandatory write-once logging, for example. They should probably be completely disconnected from the internet at a physical level - not even the research floor has internet. There might be rules on what you can and cannot do during training. There might be other technologies or systems for regulating dangerous AI work. Whatever it is, it goes here.
AI Deployment orgs continue to run on Silicon Valley rules. Move fast and break things.
AI R&D orgs are run like nuclear weapons labs mixed with Global Systemically Important Banks (G-SIBs)
What about recursive self-improvement? Well, a simple rule that might help seriously blunt that risk is that the AI R&D orgs would not be allowed to use their own models - neither the versions that are running on general purpose compute, nor the ASICs that are for sale. But they are allowed to use ASICs from other AI R&D orgs. This is "Anti-dogfooding" - you are not allowed to eat your own dog food.
This would allow humanity as a whole to recursively improve its AI tech base, though of course each iteration would be limited by how quickly new models could be certified and ASICs could be made. But it would prevent any one AI company from "going nuclear" on its own, because its research floor is only allowed to use AI ASICs from other companies - which must legally also be available to the general market. So if one AI R&D org pulls ahead, inferior ASICs from other companies slow it down.
In this system, no entity gets to own an unbounded financial claim on The Singularity.
But the AI deployment companies can still use these AI ASICs to do useful work. AI is not banned. You can still have ChatGPT - it just gets served from an ASIC. People can still try to cure cancer and aging. Robots can still have AI brains, either in place or remotely. We can still use AI for military applications. But there is a very strong separation between inference and training, enforced at the hardware level. ASICs cannot compute gradients, so they cannot train. They cannot change what model they are running, so they cannot be taken over by rogue AIs. Insider risk at the AI R&D orgs is reduced because model X cannot be used to help train model X+1. You have to use someone else's model.
For additional safety, ASIC adoption by AI R&D labs could be lagged - so an ASIC must spend say 3 months working on a variety of real world tasks before it can be considered for use in an AI R&D org. This should hopefully add something to safety as real world use allows a run of ASICs to collect a track record, and it will put a speed limit on the Singularity.
An international agreement would be needed to enforce this system (call it "Plan R") globally, but since the industry currently really only exists in two countries I think that is feasible. I think this "Plan R" is much better than both "Plan S" (total AI research shutdown) and "Plan A" from the point of view of the large relevant international actors. There may nevertheless be bargaining frictions at play, but I feel like analyzing them is not appropriate here.
The philosophy behind Plan R is a sort of "AI Safety by skeuomorphism" - instead of trying to work out how to make the world safe with arbitrarily powerful and general AIs, change what an AI is so that it behaves more like a human, which the world is already set up to deal with. ASICs that lock a particular algorithm to a specific piece of hardware are more human-like than GPUs which allow a single algorithm to "grab" massive amounts of new compute at almost "instant speed".
See also:
https://www.lesswrong.com/posts/BHGoF7tPqtLo9mXFL/plan-r-diversity-escrow-and-political-rights-for-asics
https://www.lesswrong.com/posts/uwtnWvnJAEccksKNk/skeuomorphic-ai-safety-2