This is a special post for quick takes by dprkay. Only they can create top-level comments. Comments here also appear on the Quick Takes page and All Posts page.
Comment Permalink
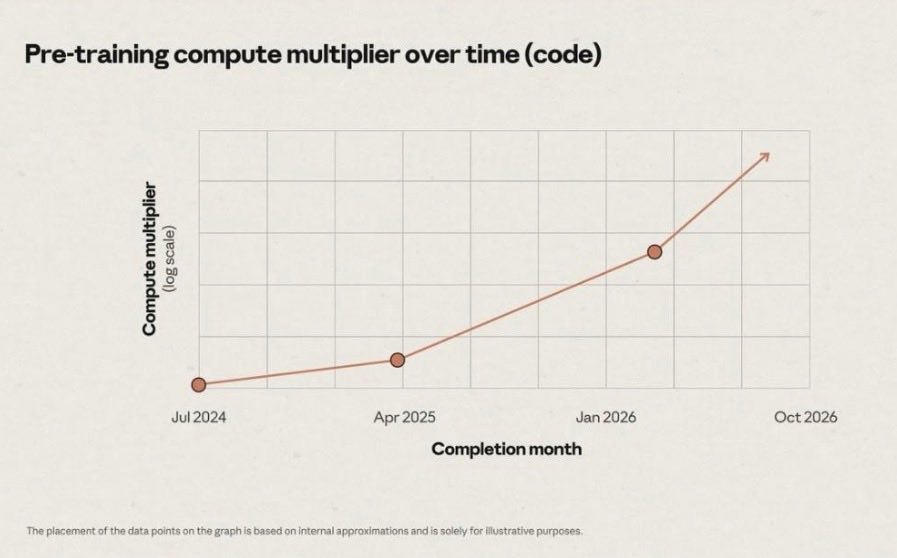
This slide from the Anthropic IPO roadshow was a big factor in my decision to leave. It’s an insane plot and I’m surprised they made it public.
It shows the compute efficiency of pretraining over time. The y-axis is a **log scale**: they are seeing continued superexponential algorithmic progress.
Mythos was not a one-time deviation, but a point on a superexponential. They could already retrain Mythos with a fraction of the compute originally needed.
It doesn’t strictly imply a software-only intelligence explosion- they have been spending more on R+D. But algorithmic improvements do not require ridiculous creative genius and are on the verge of being automated. You do the math.
I'm not sure what to make of this. My view was something like most algorithmic progress is data progress, and also that most of the progress this year (excluding compute growth) was from better post-training.
This reply from Jacob makes it sound like he isn't talking about better data (emphasis mine):
One implication of this plot is we have not hit drastic diminishing returns. We still find good new ideas every month or so
Data progress seems like it'd be much more continuous, but someone discovering a better attention variant or optimizer totally fits here.
I don't think this matters much for short-term progress (just extrapolate your preferred progress line linearly) but it seems extremely relevant for RSI and progress over the next couple years. Like the more diverse AI progress is, the less one source hitting diminishing returns would matter.
For AI automation specifically, I expect there to be big differences in how much they can accelerate each source. Even if they were exactly (expert) human level at every skill, the impact of 10x, 1,000x, or 1,000,000x as much labor seems quite uncertain.