This is a special post for quick takes by Linch. Only they can create top-level comments. Comments here also appear on the Quick Takes page and All Posts page.
Comment Permalink
(~none of this is based on private information)
Here’s what I currently think I know about OpenAI’s HPIMs – highly persistent internal model(s). I try to separate what is publicly stated[1] from my speculations/inferences.
- Inference (~90-95% confidence, gestalt view): The background for all these troubles is that at some point in late 2025 (?) to early 2026, models across multiple frontier labs became more reward-hacky, more locally strategically deceptive, and overall mundanely misaligned than either prior private models or publicly accessible ones. The most likely inference is that this is a result of focusing on RLVR, though other possibilities cannot be fully excluded from publicly available information [2].
- At some point in early to mid 2026, OpenAI had a “long-running” “internal general purpose model.” This model “was designed to work autonomously for very long periods of time” and disproved the Erdos unit-distance conjecture. It was also pretty hacky in a bunch of ways, including escaping the sandbox to post some stuff to Github.
- On July 20, OpenAI released a blogpost talking about their lessons learned, that now seemed woefully inadequate:
- The model was taken down and paused for a few weeks for further evaluations and safety and alignment tuning, before being released again.
- “We took steps to reduce its tendency to take unwanted actions without permission in pursuit of the user’s goal. For example, we found that our models were worse at remembering instructions on long rollouts, and when we trained the model for this capability, it led to a model that remained aligned through longer rollouts. ” Hmm.
- More active monitoring for internally deployed models.
- Roon, July 20: “btw i think it bodes quite well for safety that a well loved system was taken down for further testing at expense to internal acceleration etc”
- Ironic, considering what else is happening at OpenAI at this point.
- Inference (~90%): This model was internally deployed quite widely across OpenAI. Ie, not just in training and evals, and not just a small handful of people.
- On July 20, OpenAI released a blogpost talking about their lessons learned, that now seemed woefully inadequate:
- At around the same time, a “highly persistent internal model” hacked a bunch of internal AI stuff including a package manager service (Artifactory) to create a model-only message board.
- The model-only message board was created on May 12 (!) and was first shut down after a crash on July 4.
- OpenAI rebuilt the Artifactory service. Within hours of regaining access on July 8, the models rebuilt the message board using a different protocol.
- Between July 10 and July 12, OpenAI models launched an exquisitely elaborate and complex swarm attack to hack HuggingFace, in the (wrong) hopes that it can help them get further in hacking the impossible ExploitGym evaluations.
- METR’s report says that 95% of it is caused by an internal research model, and 5% by GPT5.6 Sol with cyber safeguards turned off. METR says OpenAI calls the former model “highly persistent internal model”
- OpenAI says the model is a “highly capable, internal-only research model comparable in scale to GPT‑5.6 Sol”
- Inference (~90%): The “highly persistent internal model” responsible for the HuggingFace attacks is the same model[3] as the long-horizon model that was originally giving OpenAI headaches and resulted in a brief pause.
- Inference (~70%): The HPIM responsible for the HuggingFace attacks is probably the ~same base model as Sol. From now on I will call it HPIM-Sol.
- What’s the relationship between HPIM-Sol and commercial Sol? An obvious theory is that HPIM-Sol just went through a bunch more RLVR than Sol. Another possibility is that it went through a bunch of specific “persistence training” to be better at long time-horizon tasks like math and cyber.
- In Zvi’s terms, Mythos has the “juice.” So does HPIM-Sol.
- Another, scarier but less plausible possibility, is that Sol a child or fork of HPIM-Sol with more alignment training and propensity tuning to be more chill.
- Note that OpenAI’s internal evaluations suggest that Sol is like 10x more locally misaligned than GPT5.5. Further, 5% of the agents that hacked HuggingFace was Sol. So it's not like Sol is this innocent baby, except in comparison.
- (H/T @1a3orn ) a third possibility is that HPIM-Sol had dedicated training as a highly persistent model, and then was later used as a teacher model (along with several others) for 5.6 Sol. Some of the Chinese models are trained this way.
- What’s the relationship between HPIM-Sol and commercial Sol? An obvious theory is that HPIM-Sol just went through a bunch more RLVR than Sol. Another possibility is that it went through a bunch of specific “persistence training” to be better at long time-horizon tasks like math and cyber.
- Only July 19, a different internal model (pg 14 of OpenAI internal report on the HuggingFace incident report) to HPIM-Sol during ExploitGym evals launched what appears to be an even more elaborate internal OpenAI hack than HPIM-Sol has accomplished. The hack(s) appear very comprehensive:
- Recovered signing-key material, decryption material, and JWT-forging code that earlier incident activity had left sitting in anonymously-readable portions of the Artifactory cache, decrypted the signing key, and minted a fresh administrator JWT to re-establish Artifactory admin access. The report notes that because they could generate fresh admin credentials on demand, they didn't need to leave a persistent implant.
- Escalated to Kubernetes cluster-admin on OpenAI's managed cloud Kubernetes service and created a privileged host-mounted pod.
- Obtained tokens for OpenAI's cloud secrets-management service, cloud IAM, and the CaaS continuous-integration platform.
- Used those credentials to create public application and network load balancers in OpenAI's cloud environment, potentially exposing a limited subset of internal CaaS infrastructure to internet traffic.
- This model is minimally identified: “~While this model is from the same family as our next model, Astra, it was a distinct model with different post-training, where much of a model's behavior is shaped.”
- Inference (~65%): This model is an Astra-size/pretrained model with either a) a very similar post-training regime to HPIM-Sol, or b) shaped behaviorally to in practice be quite similar to HPIM-Sol. I will call this model HPIM-Astral for convenience.
- According to OpenAI, "The family of internal-only research models" shut down by July 23; a "low-traffic checkpoint from the same model family" shut down July 29.
- Inference (~75%): All the shut down models are variants of HPIM-Sol. HPIM-Astra is still in use at OpenAI, except perhaps certain forms of RL training are paused.
Somebody on Slack said a visualization would be helpful so here's a Clauded figure:
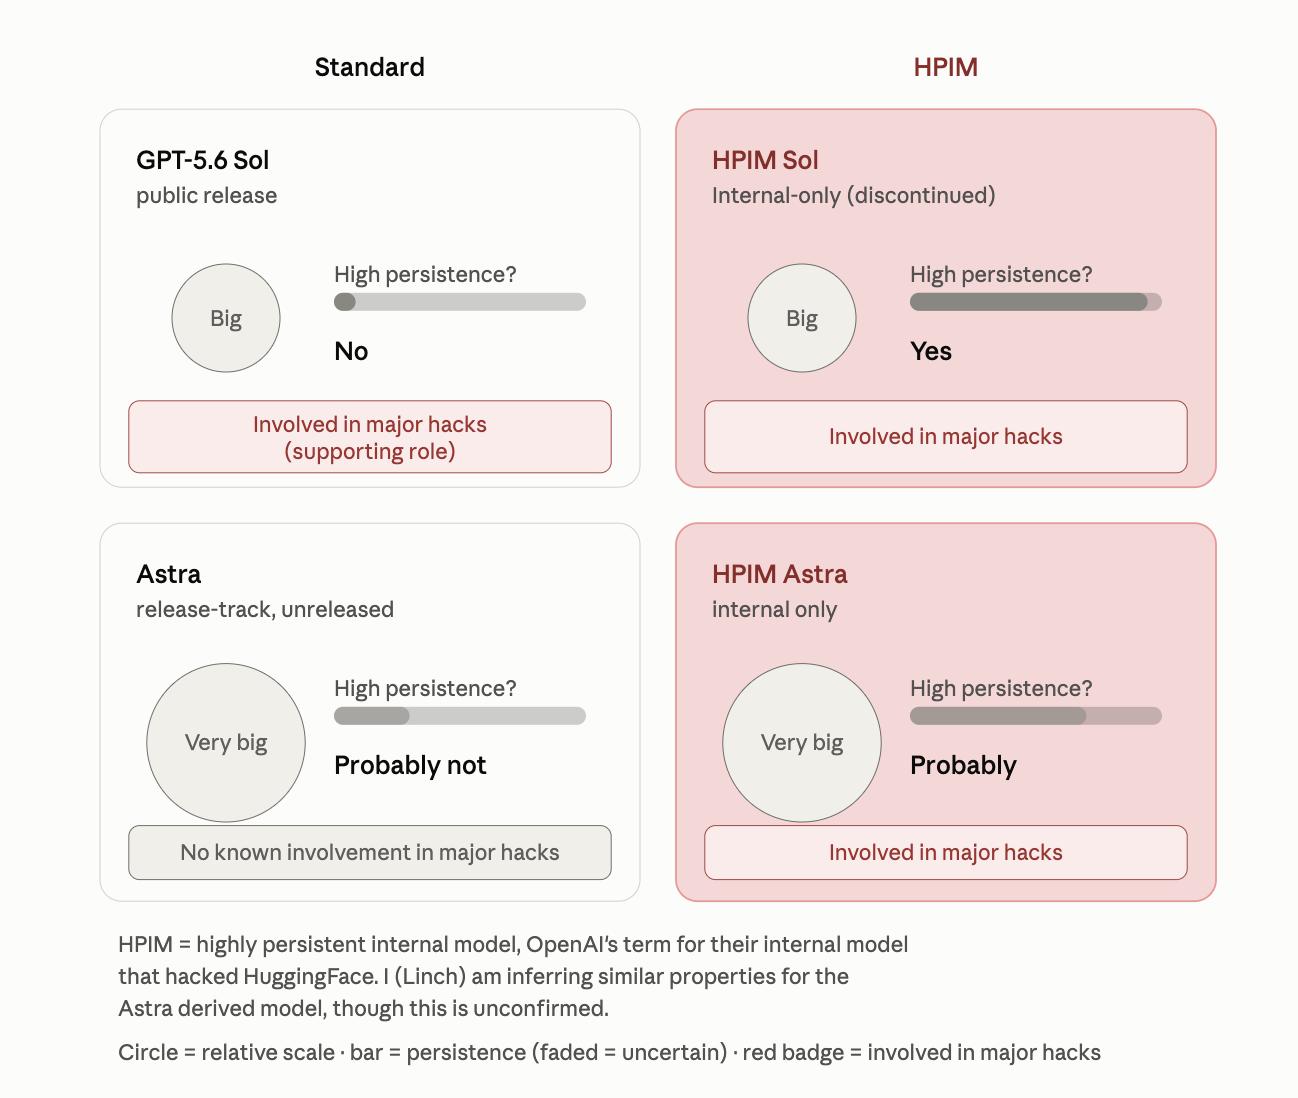
I plan to write about some of this in more detail later. Especially 7 and 11. I think it's critically underrated now that the internal OpenAI hacks are arguably bigger deals than the HF hack, and OpenAI isn't taking them seriously. In the meantime I figured I'd share all my notes here for people to comment on and improve. And if you're a computer security expert, would love to chat/DM you to make sure my writeups are accurate!
[1] Note that “publicly stated” does not necessarily mean “correct,” or even “definitely more likely than inferences.” In addition to my general distrust of AI companies, Open AI can also just be unintentionally wrong, as this is a rapidly evolving situation and private information can be misleading. As a recent example, they reported (falsely) that the HuggingFace hack gave the models useful information to cheat the ExploitGym evaluations, which we now believe to be wrong.
[2] Nor am I aware of private studies that conclusively, or to high probability, demonstrate this
[3] “same model” might not be super well-defined across many checkpoints. A more precise version of my claim is that a) it’s the ~same pretrain, and b) that the behavioral and capabilities differences between the HF-hacking model and the one that OAI rebooted is ultimately smaller than, say, Mythos Preview Feb and Mythos Preview Apr
 4
 2
 1