This is a special post for quick takes by Mateusz Bagiński. Only they can create top-level comments. Comments here also appear on the Quick Takes page and All Posts page.
Comment Permalink
20
I think I'm less worried than you are on that last bit because there are folks like Tim Gowers working on this sort of project. But I am a bit worried. To their credit the Epoch folks acknowledge this
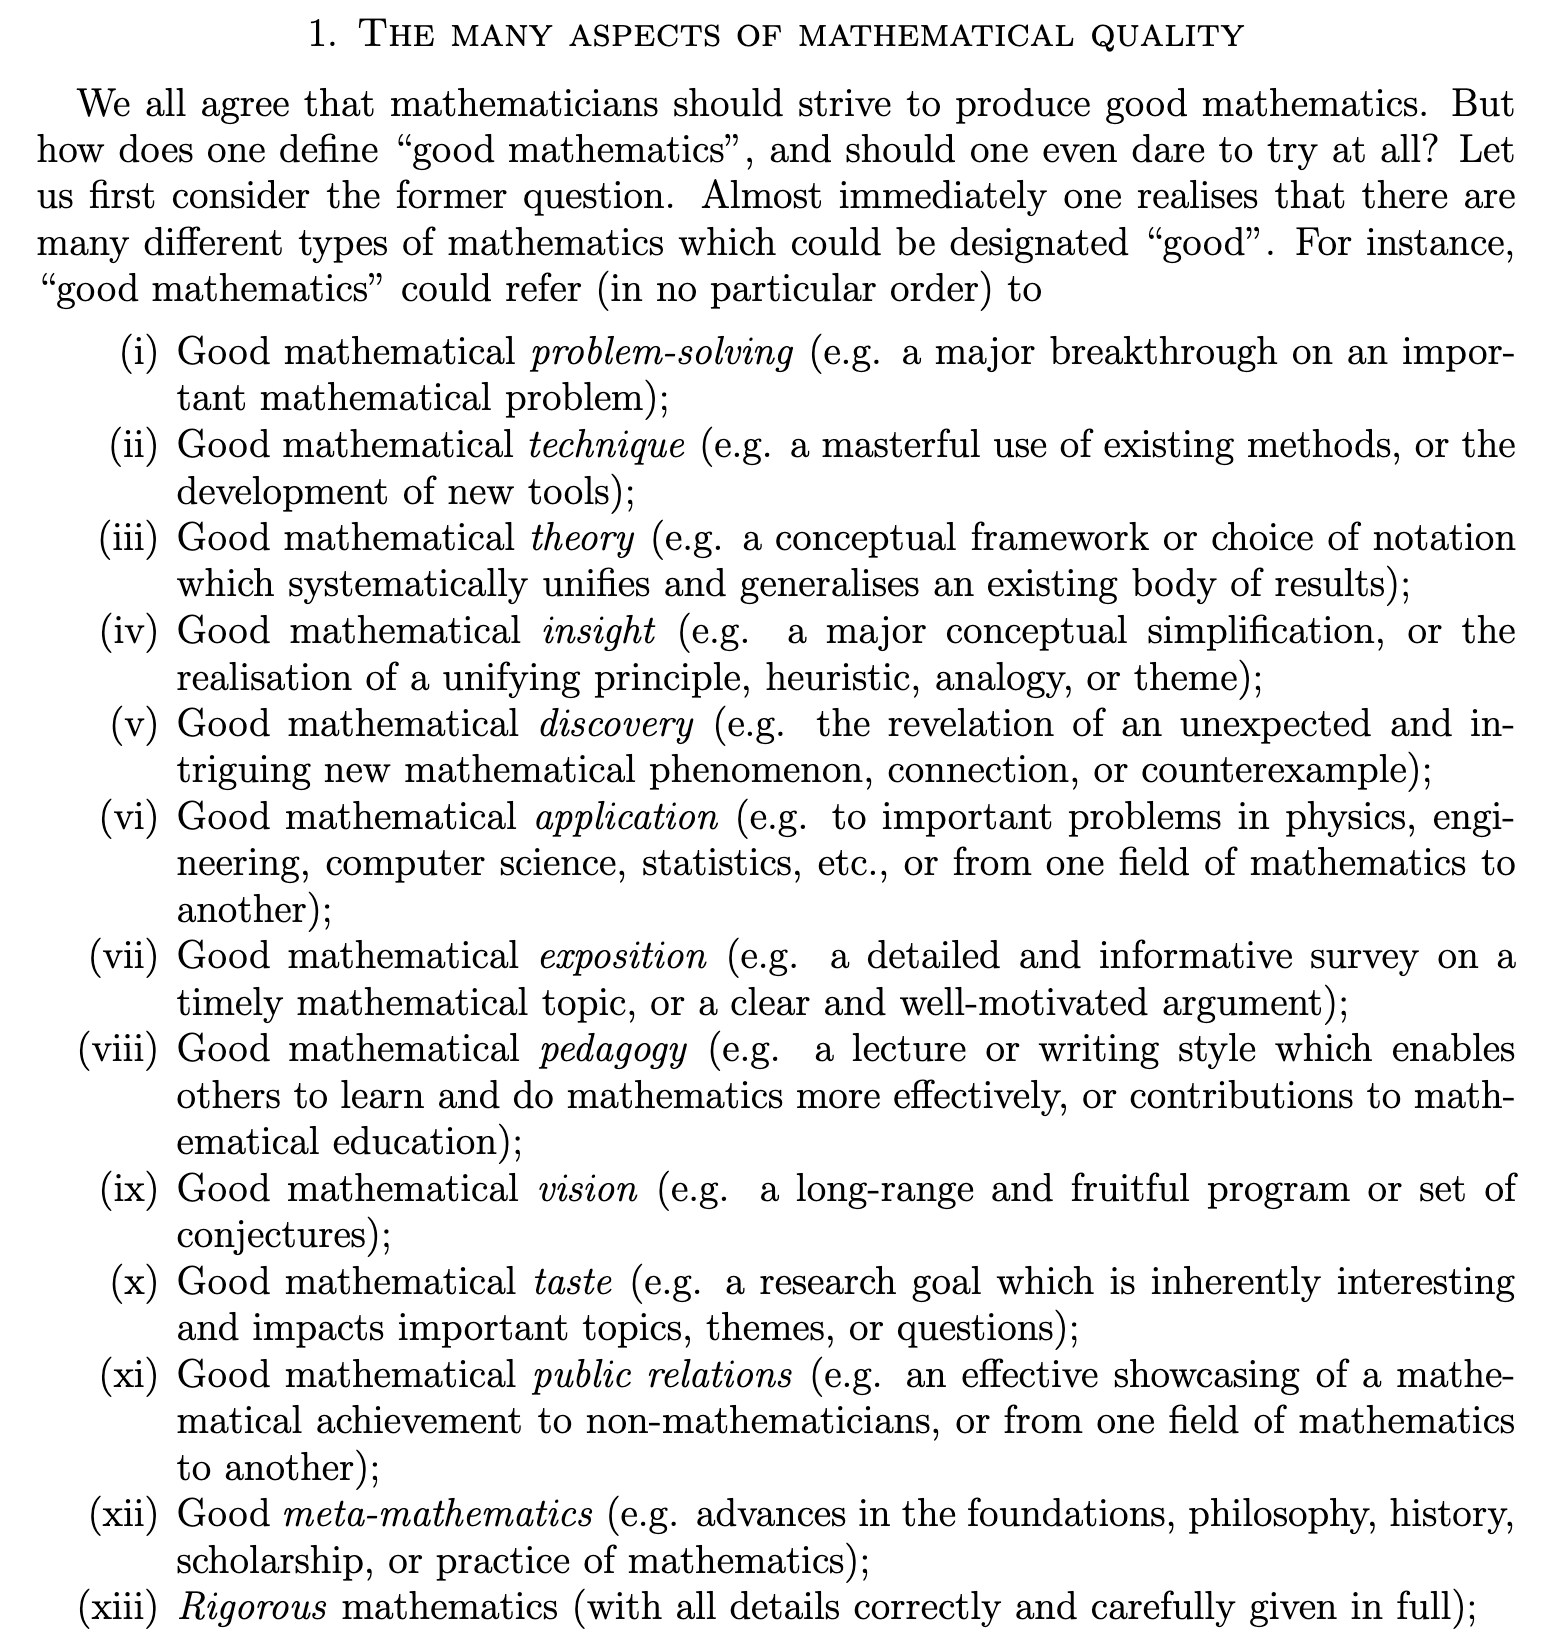
The downside is that this approach limits what we can ask about. Our ideal would be to take a random sample of all unsolved math problems, but this constraint introduces a bias. The benchmark problems tend to be relatively concrete, and may not require fuzzier mathematical pursuits like “theory building”.
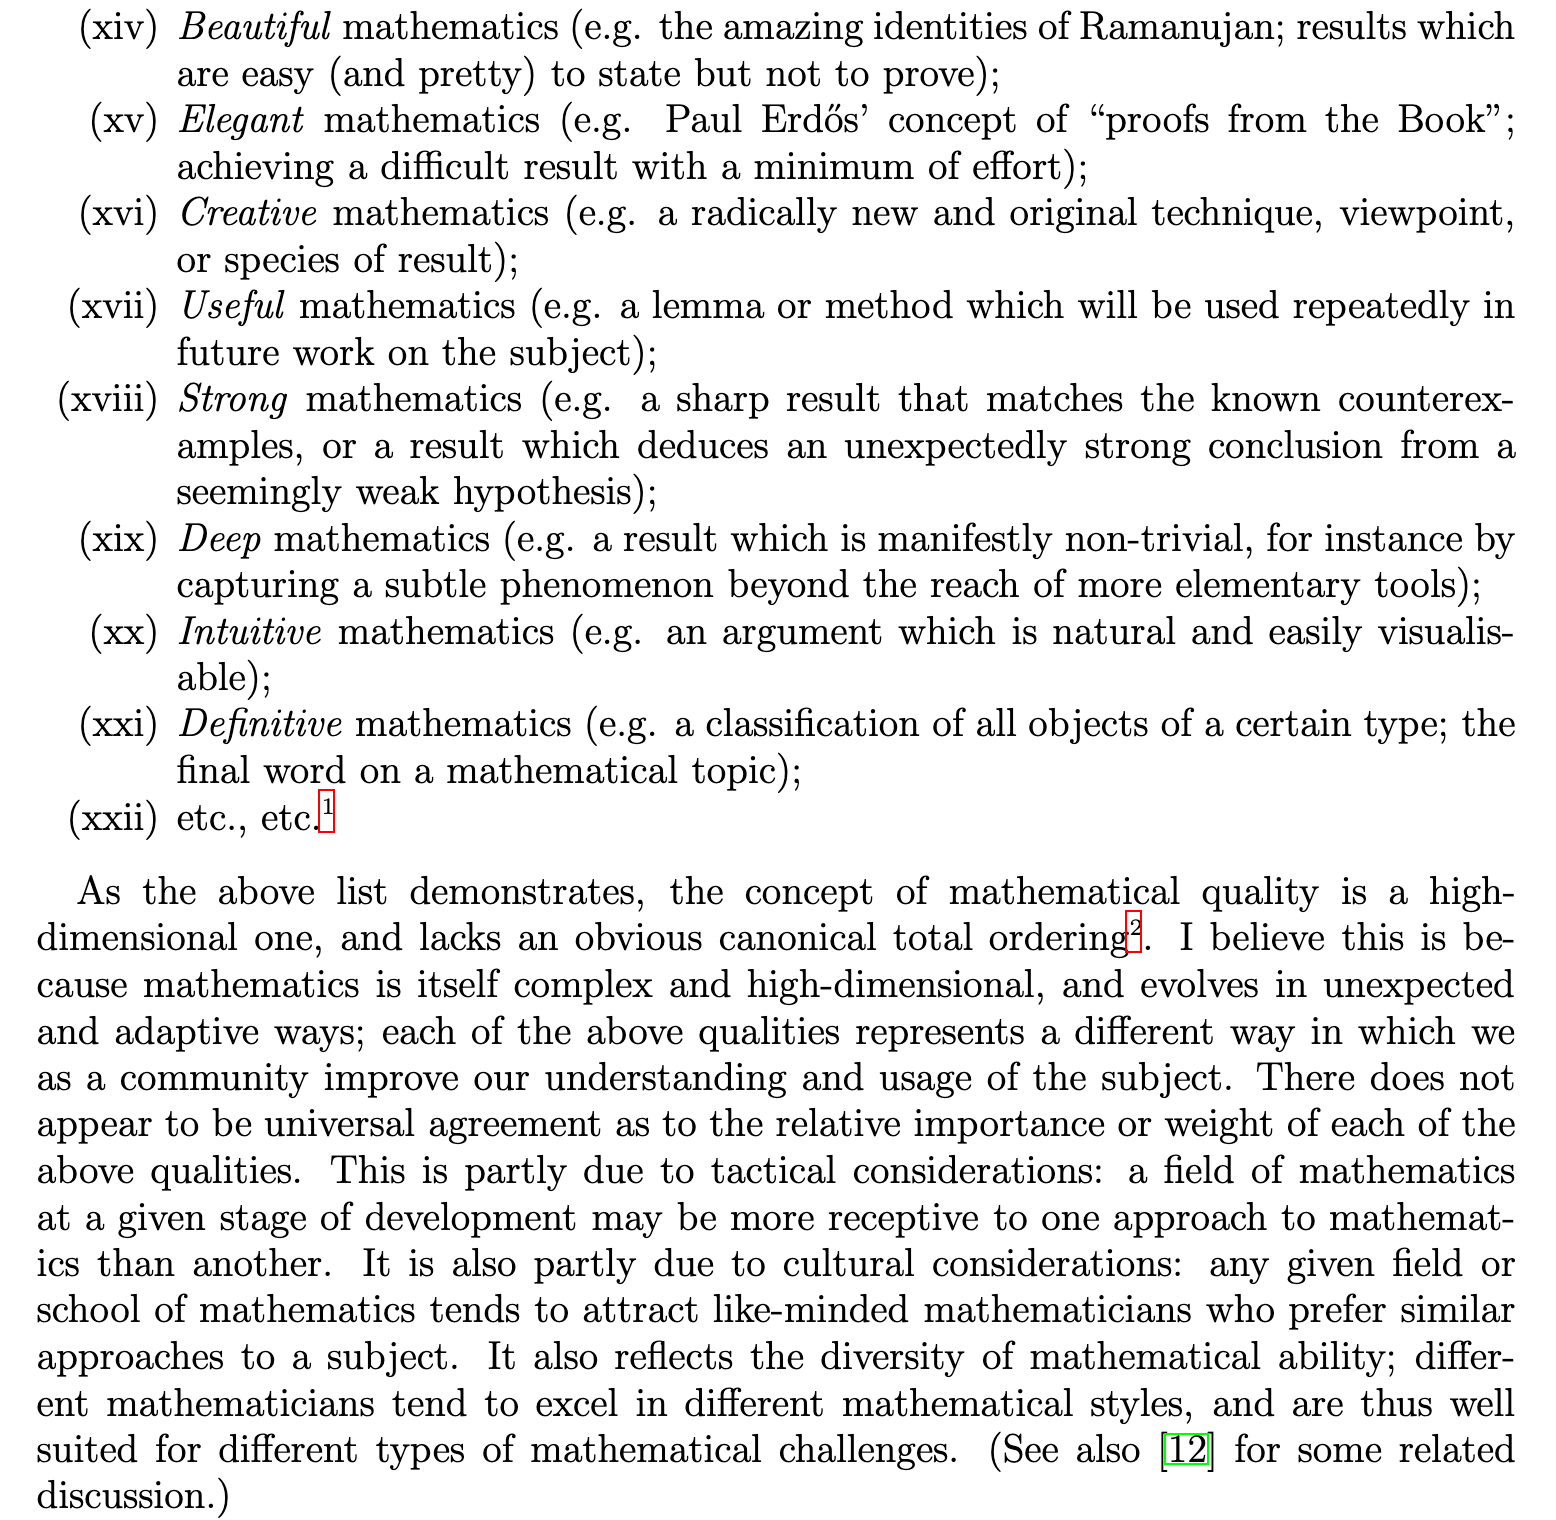
There's a lot more to good math than just theory-building and problem-solving of course, but I think involving a variety of mathematicians in the broader AI x math evals process as well as having more top mathematicians start their own AI x math initiatives (e.g. Terry Tao's SAIR) mitigates this.