This is a special post for quick takes by Rauno Arike. Only they can create top-level comments. Comments here also appear on the Quick Takes page and All Posts page.
Comment Permalink
[Link] Something weird is happening with LLMs and chess by dynomight
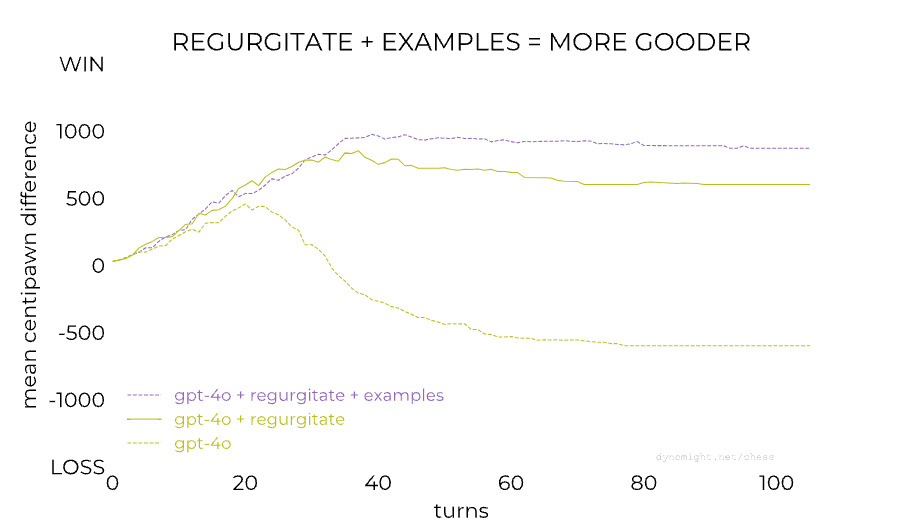
dynomight stacked up 13 LLMs against Stockfish on the lowest difficulty setting and found a huge difference between the performance of GPT-3.5 Turbo Instruct and any other model:
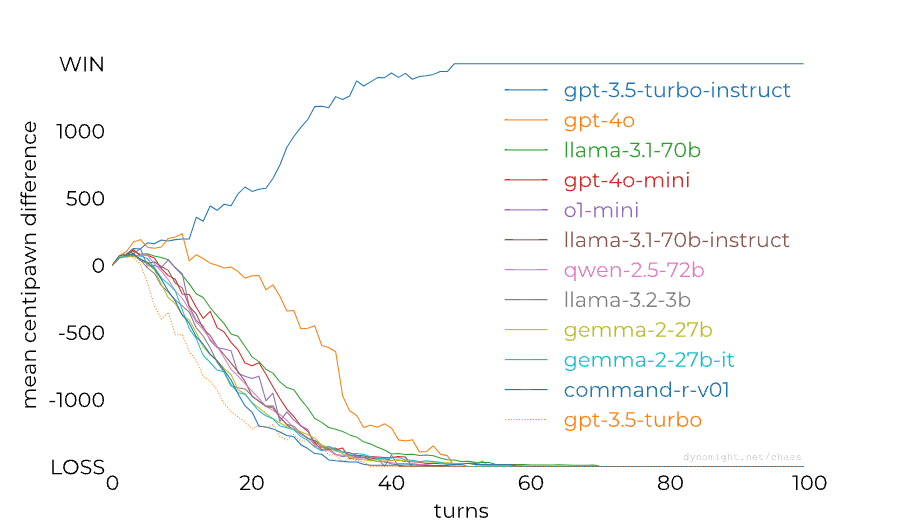
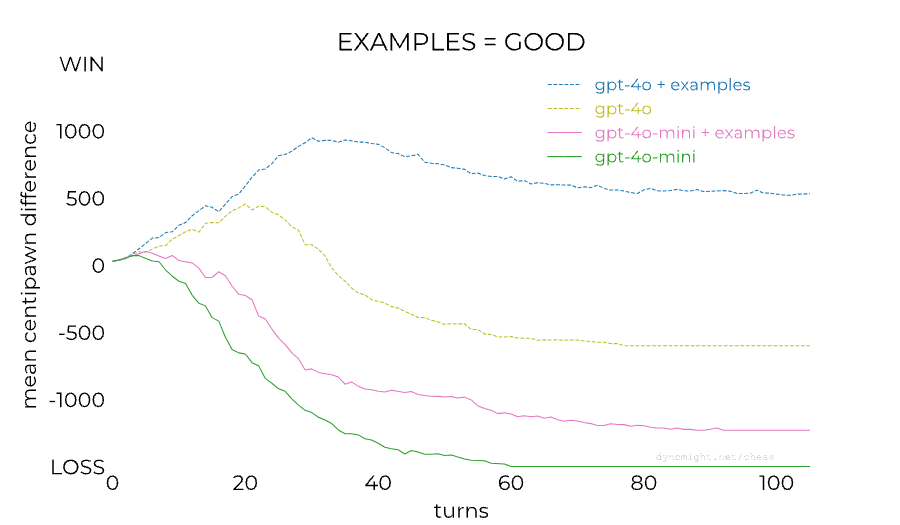
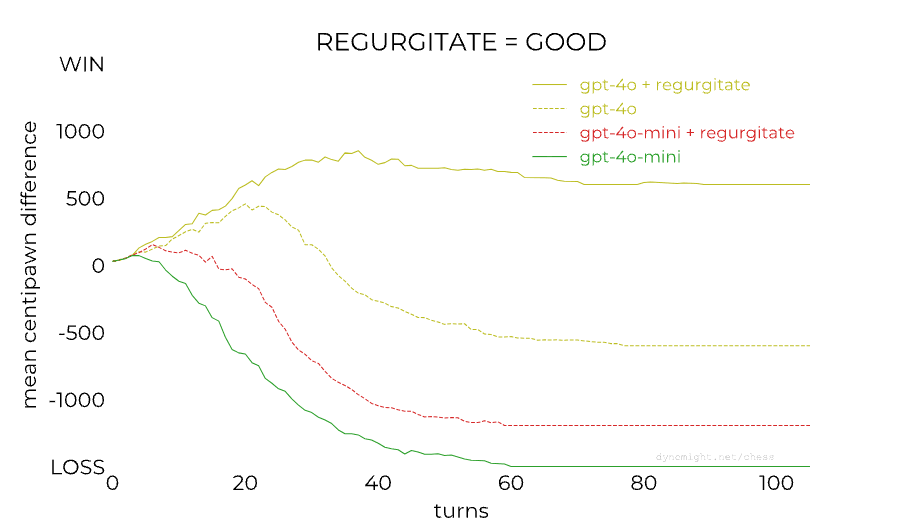
People noticed already last year that RLHF-tuned models are much worse at chess than base/instruct models, so this isn't a completely new result. The gap between models from the GPT family could also perhaps be (partially) closed through better prompting: Adam Karvonen has created a repo for evaluating LLMs' chess-playing abilities and found that many of GPT-4's losses against 3.5 Instruct were caused by GPT-4 proposing illegal moves. However, dynomight notes that there isn't nearly as big of a gap between base and chat models from other model families:
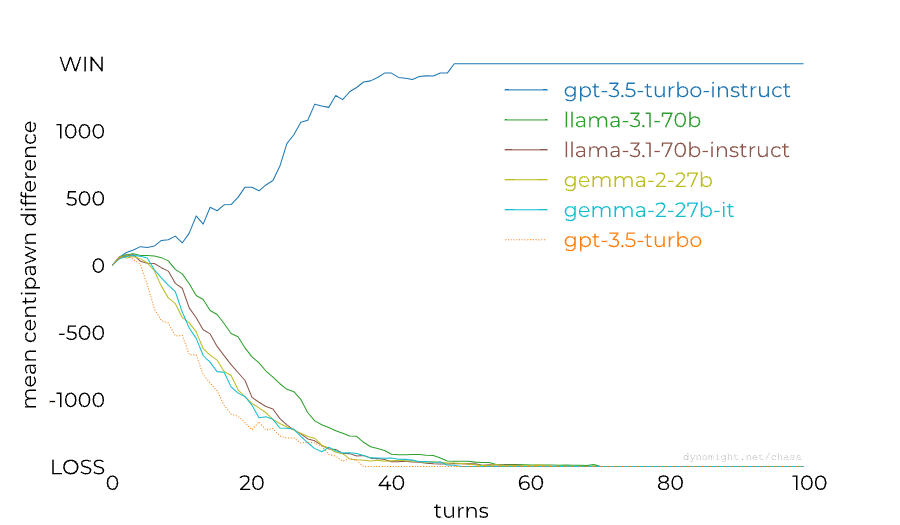
This is a surprising result to me—I had assumed that base models are now generally decent at chess after seeing the news about 3.5 Instruct playing at 1800 ELO level last year. dynomight proposes the following four explanations for the results:
1. Base models at sufficient scale can play chess, but instruction tuning destroys it.
2. GPT-3.5-instruct was trained on more chess games.
3. There’s something particular about different transformer architectures.
4. There’s “competition” between different types of data.
Showing 3 of 5 replies (Click to show all)
30
2
There was one comment on twitter that the RLHF-finetuned models also still have the ability to play chess pretty well, just their input/output-formatting made it impossible for them to access this ability (or something along these lines). But apparently it can be recovered with a little finetuning.