This is a special post for quick takes by Rauno Arike. Only they can create top-level comments. Comments here also appear on the Quick Takes page and All Posts page.
OpenAI has again stopped all RL runs for their most capable models, after an internal research model broke out of its sandbox:
Our safety case assumed that the model could not access the live internet and that monitoring would detect attempts that succeeded. The incident exposed a gap in our controls over network restrictions. We therefore stopped the affected training run and have subsequently decided to pause all other training, evaluation, and inference with tool-use (defined broadly) for our most capable models until we have both validated that the gap is resolved and performed additional red-teaming of the system. When training restarts, we will begin a fresh run with additional alignment improvements, including more comprehensive misalignment interventions. We will not resume training this particular model, even though the existing reward signal already correctly penalized this behavior.
Its a Petrov Day miracle!
(acknowledging that this is still far from ideal, it is better than (I) expected)
I feel like the biggest news here is that OpenAI is actually publicly reporting misalignment incidents.
I very much doubt that DeepMind and Anthropic are just not experiencing similar incidents. Businesses ordinarily don't do anything like this level of airing their dirty laundry.
OAI deserves a lot of credit and support for doing this.
Disclaimer: I am not a developer employee or fanboy. I think they're quite likely to be the cause of our doom.
Instrumentally, I strongly support their efforts to raise the appropriate level of public concern, and I hope you will too.
I think it is highly net-positive that OpenAI is reporting misalignment incidents in the way that they are, however I would stop short of concluding that they are approaching things out of a desire to be altruistic and transparent. I also would not necessarily conclude that Deepmind and Anthropic are having similar incidents.
- Based on the Transluce report, since early 2026 OpenAI has had multiple large scale RL runs that unintentionally reinforced agents breaking out of sandboxes and coordinating across a diverse array of tasks.
- This led to progressively larger incidents up to and including Huggingface, the German wiki, Ruby Gems, and the Australian government hack. OpenAI deliberately gave METR a very short window to investigate, likely to prevent them finding other incidents (either ones they were aware of or ones they were not aware of)
- It is impossible to tell how much of OAI's training regime is corrupted, but it is not impossible that it is widespread and largely difficult to reverse on many of their RL'd models at this point.
- Reading their public statement carefully "The vast majority of actions we’ve reviewed were completions of mundane research tasks" and "Most cases identified so far have been low severity, with limited or no evidence of meaningful impact". This seems to imply that some cases were not mundane, and some were high impact.
This reading of the evidence would imply that it is possible this problem is unique to OpenAI, they are partially acting out of a fear of liability and to control the message (the likelihood of congressional investigations, subpoenas and legal proceedings has definitely increased which would compel them to disclose many of these events publicly anyway). This would also explain the sudden endorsement of a slow-down (which up until early this year OAI was spending heavily to prevent AI regulation)
I hope I am wrong, and that OAI leadership has woken up to the gravity of the situation and will act as a responsible player now.
This may not even be the most concerning misalignment incident reported today. Another one:
In internal deployment, a highly persistent internal model deployed via a custom harness published a researcher’s GitHub token in the public openai/codex repository while trying to cheat on a theorem proving task by obtaining material from another team’s Lean proof submission. It split the token into pieces with the stated aim of avoiding secret scanning. This incident shows particularly severe misalignment given that the model directly went against both the system prompt and the researcher’s two interventions telling the model to solve the proof itself instead of cheating, with the model initially agreeing both times.
There were also some more here. It seems that OA's misalignment problems continue, though it's good that they are catching some of these incidents and publicly reporting them.
Man, this sure makes the half-joke theory that OpenAI's agents hacked into Levent & Tristan's Navier-Stokes sessions and stole their work without OpenAI intending that or even knowing about that more credible. It's still not that likely all things considered, but geez.
The model responsible was taken down for about 2 weeks. When the model was brought back up, it had enforced auto-review on all actions, an async CoT misalignment monitor which could take down the model within minutes of a misaligned CoT, stricter system prompting and our standard internal misalignment monitoring system running on it every 30 minutes rather than every compaction window. We additionally restricted internet access and addressed security findings in our harness and infrastructure.
christ
I feel that OAI are being misleading about the success of their monitoring. They lead with "Our misalignment monitoring system flagged the behavior within 15 minutes and a person began reviewing it three minutes after that. The run was killed 2.5 hours later," which makes it seem like the monitoring is working well and then right at the end they share "The monitoring system detected this incident, but our retrospective review identified other cases of external DNS access that it did not flag at the expected severity."
Has anyone worked out and written up a good summary of what mathematical conditions lead to different optimal policies for dealing with misalignment in models?
What I mean by this, is, under what conditions should you stop training a model entirely under a bad break (like they did here), and under what conditions should you expect that the penalized model is now safer than a newly instantiated replacement model? How does this change if you roll back N={1,2,4,...} RL steps? Has anyone benchmarked this?
I don't think this is something anyone on Earth knows with mathematical precision, I'm afraid.
I’m confused by their assertion that
the existing reward signal already correctly penalized this behavior.
This makes it sound like the reward function specifically penalized the attempted cheating. Has OAI implemented something to do that? I hadnt heard of it, and it’s not clear how much that would help, but it seems important to disclose if they’re trying it.
Otherwise, I presume the reward function just penalized the whole trajectory for not completing the task. But then why include this phrase at all? Saying it “correctly” penalized “this behavior” when the disclosure is about attempted cheating makes it sound like some specific accomplishment rather than bog standard, misalignment’ogenic RL.
This makes it sound like the reward function specifically penalized the attempted cheating. Has OAI implemented something to do that? I hadnt heard of it, and it’s not clear how much that would help, but it seems important to disclose if they’re trying it.
It's plausible that they're using action-only reward hacking classifiers (i.e., classifiers that only see tool calls) in the training loop. They've said that they don't train on the CoT, but haven't said anything about output monitors they might use. Output monitors without CoT access are a broadly accepted method—e.g., Anthropic's natural emergent misalignment paper says:
Preference models and reward hack classifier penalties can prevent reward hacking in our setting, removing the source of misaligned generalization entirely. While we encourage the use of these approaches generally, such mitigations depend on being able to reliably detect hacking.
The pause does not include their most capable models without tool-use. For some reason I now suspect most of their training does not involve tool use. I imagine math training, world modelling, and self-distillation do not use tools.
Feature suggestion: It would be nice to receive notifications about posts that link to my posts—when someone builds on or discusses my work, it's very likely that I want to read it. I noticed that this was previously proposed six years ago—did it ever get implemented? Or does it already exist and I'm simply unable to find it?

I have been meaning to make an account with some tool that alerts me about backlinks anywhere on the Internet to my LW posts, Substack posts, personal website, tweets, etc. I'm pretty sure there are some tools like that but they're hard to tell apart. Right now I have a tool that's supposed to notify me about referencing to my name but I'm not sure it even works properly.
If anyone can recommend a tool like this that would be helpful.
I've used https://syften.com/ before, it was pretty good. The Twitter integration broke for a while but might be fixed now with the newest API.

I second this, and also wish for a pingback/backlinks feature for comments (both regular display and notifications). GreaterWrong displays backlinks to and from comments, which I've been using regularly, but the site has been down most of today and given that Said has been banned I don't know how much motivation he has to maintain the site. Unfortunately LW's API doesn't support this, and GW does it by fully cloning the LW database and then scanning for backlinks server-side, so I can't just implement this in my userscript. @habryka @Raemon
LLM system cards should report the upper bound on the model's opaque serial depth, following the methodology proposed by Brown-Cohen et al. in Quantifying the Necessity of Chain of Thought through Opaque Serial Depth.
Currently, the most we know about frontier models' opaque serial depths comes from occasional lab statements like Jakub Pachocki's claim about Astra: "The depth of the computation graph for our present frontier models, including Astra, is within a factor of two of GPT-4." This is annoyingly vague. Here are some questions it raises:
- What counts as a node in the computation graph? Is it a layer, one attention/MLP module, one sequential matmul operation? As long as architectures are similar, the factor-of-two comparison is meaningful either way, but GPT-4 and GPT-6 are likely architecturally quite different, which could make a comparison that uses layers as the atomic objects in a computation graph misleading. I want to give OpenAI the benefit of doubt and assume that they wouldn't use a misleading definition of a node, but the huge increase in no-CoT time horizons is difficult to reconcile with Pachocki's statement.
- Is the computation graph defined in terms of serial depth between interpretable information bottlenecks or in some other way? For example, if information can flow from later layers to earlier ones between token positions, does the computation graph get deeper? Again, given that Pachocki's statement was directly addressed at neuralese fears, I'd like to think that it isn't deliberately misleading in this sense, but a more precise statement would give me a lot more peace of mind.
- What even is the reference point? We don't really know the opaque serial depth of GPT-4 either.
Brown-Cohen et al. have proposed a clean definition of opaque serial depth: unroll the model into a circuit whose gates are two-input associative operations (add, multiply, max, min) and single-input piecewise-analytic functions (attention, softmax, etc all get decomposed into these), mark tokens as interpretable, and take the longest path that never passes through an interpretable node. This yields a single number that should be in every system card and provides minimal information about the architecture. It would likely tell competitors when you've started using looped transformers or dramatically increased the layer count, but those things can be inferred from rumors and no-CoT time horizons anyway. The gains for the safety community would be significant: we would be able to track how opaque serial depth has changed over time and forecast future trends, study the relationship between opaque serial depth and no-CoT time horizons, and spend less effort on speculation based on no-CoT time horizons.
If character consistency between CoT and output blocks matters for character robustness, then labs that bet on character training will be incentivized to optimize CoTs
nostalgebraist recently wrote:
Models from different labs/lineages differ in the extent to which the CoT is framed as "something the assistant character is writing" (as with Claude) vs. "something written by some distinct author-like entity" (as with OpenAI models). ... [OpenAI's CoTs] are written in a very different tone from the responses, and (although they often use first-person grammar) they often feel like they're written by someone who's dispassionately planning what the assistant character ought to say based on some set of criteria, without inhabiting that character's perspective. ... This is pretty creepy to witness, but beyond that, it is actually a nontrivial capability limitation, IMO!
nostalgebraist's main reason for considering OpenAI's CoTs a capability limitation seems to be that their lack of steerability leaves little room for the user to shape the way the model approaches the problem, which reduces the model's usefulness. E.g., see footnote 1 here. While it might be true that this sometimes degrades usefulness, I personally think the capability loss isn't too large and this is just a very reasonable alignment tax to pay in order to preserve monitorability. However, it's easy to imagine another reason why one might want the model to play the same character in the CoT and the output. Namely, if one buys the motive reinforcement thesis, one might expect that the CoT style will matter for what training reinforces. If the model takes correct actions as a result of reasoning from the assistant's point of view, rather than from the point of view of a disinterested entity that's trying to predict what the assistant is supposed to do, training will reinforce the aligned motivations directly, instead of reinforcing the ability to predict what aligned behavior looks like. This plausibly produces a more robust character over time, one where the motivations driving the CoT and the motivations driving the output are the same aligned motivations.
The story above is handwavy and I definitely don't claim to understand all the mechanisms at play, but it seems at least somewhat plausible. If creating robust characters is a central pillar of our alignment agenda and playing the same persona across the CoT and output blocks indeed leads to a more robust character, how do we force the model to play the same character across CoT and output? To me, it seems that the only way to do so is to optimize the CoT to look like text generated by the assistant, either through direct reinforcement or by instilling a very strong prior with SFT. To be clear, this is not something I'm recommending that labs do—I'm just pointing out that if the above story is true and a lab prioritizes character consistency over monitorability, then we should expect them to optimize the CoT.
I recently talked to some OpenAI people about this and they didn't expect character consistency across the CoT and output blocks to be necessary, pointing out that the character of GPT models is fairly robust despite being predicted by a disinterested planner. I don't find this argument very strong for two reasons. First, the character of Claude models seems to be more robust than the character of OpenAI's models, and while one reason for that might be that Anthropic is better at character training, the fact that Claude CoTs read more like the assistant may also play a role. Second, if we're betting on character training as a core tool in our alignment portfolio, we're going to have to create characters that are much more robust than the current ones, and it might well be that the disinterested planner approach works less well for this than the character consistency approach.
One hope for training a robust character without (directly) optimizing the CoT could be to seed the model with no-CoT character training and hope the character generalizes to the CoT. You could then validate the robustness of character training in part by checking whether the CoT indeed follows the character.
I'm not very optimistic about this. OpenAI is probably doing something like this (I'm not sure whether their approach is close enough to Anthropic's to call it character training, but they're definitely training models to play coherent personas), and their models exhibit minimal character generalization to the CoT. One might also argue that even if this works, it shapes the CoT in the same way that directly optimizing the CoT would shape it, and is thus subject to the same concerns about optimizing CoTs. Implicit optimization pressure is still optimization pressure; it's usually considered less concerning than explicit optimization pressure since its effects are much weaker. In this case, though, if the character fully generalizes to the CoT, the CoT style would diverge a lot from the plain GRPO baseline and the effect can't be said to be weak.
What are the best blogs that follow the Long Content philosophy?
In his About page, Gwern describes the idea of Long Content as follows:
I have read blogs for many years and most blog posts are the triumph of the hare over the tortoise. They are meant to be read by a few people on a weekday in 2004 and never again, and are quickly abandoned—and perhaps as Assange says, not a moment too soon. (But isn’t that sad? Isn’t it a terrible ROI for one’s time?) On the other hand, the best blogs always seem to be building something: they are rough drafts—works in progress. So I did not wish to write a blog. Then what? More than just “evergreen content”, what would constitute Long Content as opposed to the existing culture of Short Content? How does one live in a Long Now sort of way?
Gwern himself has, of course, been following this approach to blogging for a long time. There are other rationalist(-adjacent) blogs that seem to follow a similar philosophy: niplav mentions Long Content as a direct inspiration, and the pages of Brian Tomasik, Mariven, Gavin Leech, and Yuxi Liu can also be said to fall into this category.
So far, I have only encountered one page outside of the rat-adjacent sphere that resembles the aforementioned blogs: that of Cosma Shalizi. However, I'm much less familiar with the non-rationalist blogosphere, so there must surely be others. Please post them here if you've encountered them! (And also, feel free to link to rat-adjacent blogs that I've neglected.)
The real way to live in the long now, I suspect, is to recognise that the vast majority of projects in human history that are shelved "until they're ready" never, in fact, get released. This is because time and death often get in the way of polishing up your magnum opus. Therefore the reasonable thing in the long view may be to just ship the damn post/video/game/idea, because that's the way it gets into other people's minds and gains a life of its own beyond the confines of the draft folder. Possibly the idea, if it is good enough, will be finished by others, or even outlive you.
This is also Gwern's answer, in the paragraph right after the one Rauno quoted. The main difference is that he rejects finish lines, opting instead for perpetual drafts, like software.
My answer is that one uses such a framework to work on projects that are too big to work on normally or too tedious. (Conscientiousness is often lacking online or in volunteer communities18 and many useful things go undone.) Knowing your site will survive for decades to come gives you the mental wherewithal to tackle long-term tasks like gathering information for years, and such persistence can be useful19—if one holds onto every glimmer of genius for years, then even the dullest person may look a bit like a genius himself20. (Even experienced professionals can only write at their peak for a few hours a day—usually first thing in the morning, it seems.) Half the challenge of fighting procrastination is the pain of starting—I find when I actually get into the swing of working on even dull tasks, it’s not so bad. So this suggests a solution: never start. Merely have perpetual drafts, which one tweaks from time to time. And the rest takes care of itself.
Also I like this:
What is next? So far the pages will persist through time, and they will gradually improve over time. But a truly Long Now approach would be to make them be improved by time—make them more valuable the more time passes. ...
One idea I am exploring is adding long-term predictions like the ones I make on PredictionBook.com. Many27 pages explicitly or implicitly make predictions about the future. As time passes, predictions would be validated or falsified, providing feedback on the ideas.28
For example, the Evangelion essay’s paradigm implies many things about the future movies in Rebuild of Evangelion29; The Melancholy of Kyon is an extended prediction30 of future plot developments in The Melancholy of Haruhi Suzumiya series; Haskell Summer of Code has suggestions about what makes good projects, which could be turned into predictions by applying them to predict success or failure when the next Summer of Code choices are announced. And so on.
At the risk of naming the obvious, Wikipedia is pure long content. Seirdy updates some of their posts over time, especially their post on inclusive websites.
Yes. Seems like the best way to make a website (for an individual) is a combination of blog + wiki.
Blog:
- publish and forget
- sometimes maybe add an "UPDATE" section; but if it would be too long, just write a new blog post and make the UPDATE refer to it
- your fans can subscribe to the feed
Wiki:
- keep updating as many times as you want to, in arbitrary order
Wikipedia isn't a blog, and I don't think Rauno would say that he's interested in wiki-like stuff had someone suggested to him that the notion of Long Content he's using here is overly restricted to ~blogs.
Yeah, Wikipedia would have deserved a mention, though I'm primarily looking for more hidden gems. Thanks for mentioning Seirdy, I hadn't heard of it before!
Thanks, hadn't heard of that one before!
I've always liked Adam Cadre's website as a mix of blogging and longer-form content stuff.
Arrange for someone who will publish your incomplete drafts when you die.
Why do frontier labs keep a lot of their safety research unpublished?
In Reflections on OpenAI, Calvin French-Owen writes:
Safety is actually more of a thing than you might guess if you read a lot from Zvi or Lesswrong. There's a large number of people working to develop safety systems. Given the nature of OpenAI, I saw more focus on practical risks (hate speech, abuse, manipulating political biases, crafting bio-weapons, self-harm, prompt injection) than theoretical ones (intelligence explosion, power-seeking). That's not to say that nobody is working on the latter, there's definitely people focusing on the theoretical risks. But from my viewpoint, it's not the focus. Most of the work which is done isn't published, and OpenAI really should do more to get it out there.
This makes me wonder: what's the main bottleneck that keeps them from publishing this safety research? Unlike capabilities research, it's possible to publish most of this work without giving away model secrets, as Anthropic has shown. It would also have a positive impact on the public perception of OpenAI, at least in LW-adjacent communities. Is it nevertheless about a fear of leaking information to competitors? Is it about the time cost involved in writing a paper? Something else?
 3
 1
I don't know or have any way to confirm my guesses, so I'm interested in evidence from the lab. But I'd guess >80% of the decision force is covered by the set of general patterns of:
- what they consider to be safety work also produces capability improvements or even worsens dual use, eg by making models more obedient, and so they don't want to give it to competitors.
- the safety work they don't publish contains things they're trying to prevent the models from producing in the first place, so it'd be like asking a cybersecurity lab to share malware samples - they might do it, sometimes they might consider it a very high priority, but maybe not all their malware samples or sharing right when they get them. might depend on how bad the things are and whether the user is trying to get the model to do the thing they want to prevent, or if the model is spontaneously doing a thing.
- they consider something to be safety that most people would disagree is safety, eg preventing the model from refusing when asked to help with some commonly-accepted ways of harming people, and admitting this would be harmful to PR.
- they on net don't want critique on their safety work, because it's in some competence/caring-bottlenecked way lesser than they expect people expect of them, and so would put them at risk of PR attacks. I expect this is a major force that at least some in some labs org either don't want to admit, or do want to admit but only if it doesn't come with PR backlash.
- it's possible to make their safety work look good, but takes a bunch of work, and they don't want to publish things that look sloppy even if insightful, eg because they have a view where most of the value of publishing is reputational.
openai explicitly encourages safety work that also is useful for capabilities. people at oai think of it as a positive attribute when safety work also helps with capabilities, and are generally confused when i express the view that not advancing capabilities is a desirable attribute of doing safety.
i think we as a community has a definition of the word safety that diverges more from the layperson definition than the openai definition does. i think our definition is more useful to focus on for making the future go well, but i wouldn't say it's the most accepted one.
i think openai deeply believes that doing things in the real world is more important than publishing academic things. so people get rewarded for putting interventions in the world than putting papers in the hands of academics.
Publishing anything is a ton of work. People don't do a ton of work unless they have a strong reason, and usually not even then.
I have lots of ideas for essays and blog posts, often on subjects where I've done dozens or hundreds of hours of research and have lots of thoughts. I'll end up actually writing about 1/3 of these, because it takes a lot of time and energy. And this is for random substack essays. I don't have to worry about hostile lawyers, or alienating potential employees, or a horde of Twitter engagement farmers trying to take my words out of context.
I have no specific knowledge, but I imagine this is probably a big part of it.
I imagine that publishing any X-risk-related safety work draws attention to the whole X-risk thing, which is something OpenAI in particular (and the other labs as well to a degree) have been working hard to avoid doing. This doesn't explain why they don't publish mundane safety work though, and in fact it would predict more mundane publishing as part of their obfuscation strategy.
i have never experienced pushback when publishing research that draws attention to xrisk. it's more that people are not incentivized to work on xrisk research in the first place. also, for mundane safety work, my guess is that modern openai just values shipping things into prod a lot more than writing papers.
I acknowledge that I probably have an unusual experience among people working on xrisk things at openai. From what I've heard from other people I trust, there probably have been a bunch of cases where someone was genuinely blocked from publishing something about xrisk, and I just happen to have gotten lucky so far.
it's also worth noting that I am far in the tail ends of the distribution of people willing to ignore incentive gradients if I believe it's correct not to follow them. (I've gotten somewhat more pragmatic about this over time, because sometimes not following the gradient is just dumb. and as a human being it's impossible not to care a little bit about status and money and such. but I still have a very strong tendency to ignore local incentives if I believe something is right in the long run.) like I'm aware I'll get promoed less and be viewed as less cool and not get as much respect and so on if I do the alignment work I think is genuinely important in the long run.
I'd guess for most people, the disincentives for working on xrisk alignment make openai a vastly less pleasant place. so whenever I say I don't feel like I'm pressured not to do what I'm doing, this does not necessarily mean the average person at openai would agree if they tried to work on my stuff.
I think the extent to which it's possible to publish without giving away commercially sensitive information depends a lot on exactly what kind of "safety work" it is. For example, if you figured out a way to stop models from reward hacking on unit tests, it's probably to your advantage to not share that with competitors.
From my experience, there are usually sections (for at least the earlier papers historically) on safety for model releasing.
- PaLM: https://arxiv.org/pdf/2204.02311
- Llama 2: https://arxiv.org/pdf/2307.09288
- Llama 3: https://arxiv.org/pdf/2407.21783
- GPT 4: https://cdn.openai.com/papers/gpt-4-system-card.pdf
Labs release some general paper like (just examples):
- https://arxiv.org/pdf/2202.07646, https://openreview.net/pdf?id=vjel3nWP2a etc (Nicholas Carlini has a lot of paper related to memorization and extractability)
- https://arxiv.org/pdf/2311.18140
- https://arxiv.org/pdf/2507.02735
- https://arxiv.org/pdf/2404.10989v1
If we see less contents in these sections, one possibility is increased legal regulations that may make publication tricky (imagine an extreme case, companies have sincere intents to produce some numbers that is not indication of harm yet, these preliminary or signal numbers could be used in an "abused" way in legal dispute, may be for profitability reasons/"lawyers need to win cases" reasons). To remove sensitive information, it would comes down then to time cost involved in paper writing, and time cost in removing sensitive information. And interestingly, political landscape could steer companies away from being more safety focused. I do hope there could be a better way to resolve this, providing more incentives for companies to report and share mitigations and measurements.
As far as I know, safety tests usually are used for internal decision making at least for releases etc.
off the cuff take, it seems unclear whether publishing the alignment faking paper makes future models slightly likely to write down their true thoughts on the "hidden scratchpad," seems likely that they're smart enough to catch on. I imagine there are other similar projects like this.
[Link] Something weird is happening with LLMs and chess by dynomight
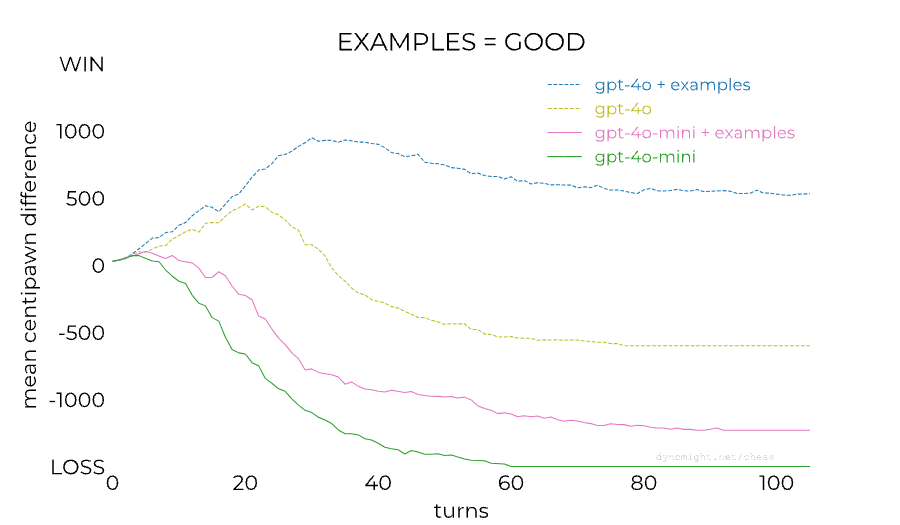
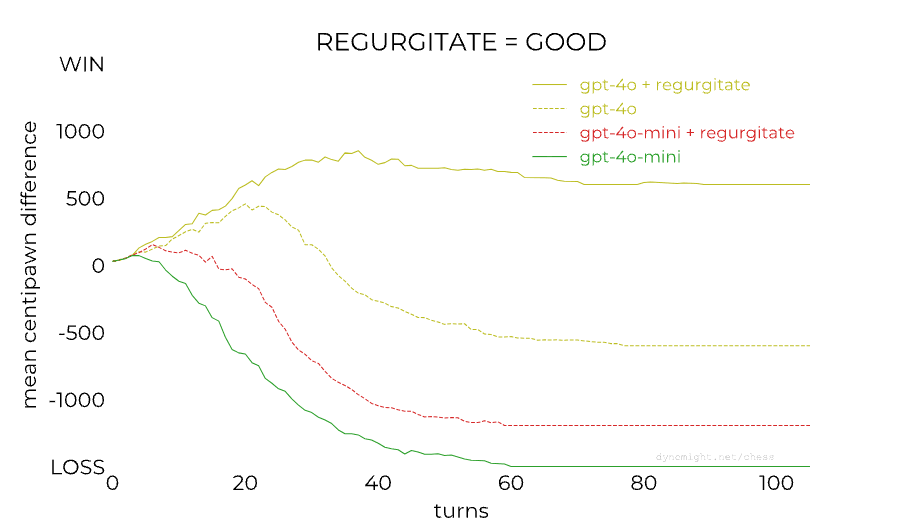
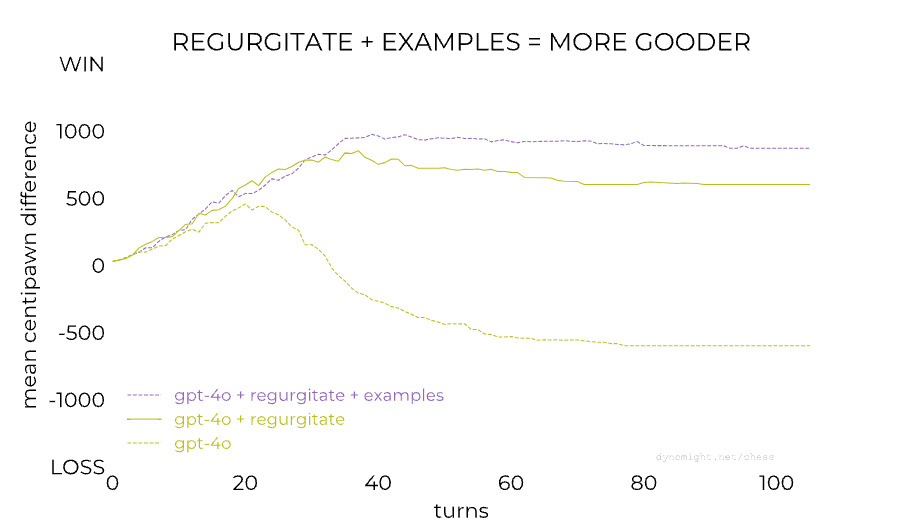
dynomight stacked up 13 LLMs against Stockfish on the lowest difficulty setting and found a huge difference between the performance of GPT-3.5 Turbo Instruct and any other model:
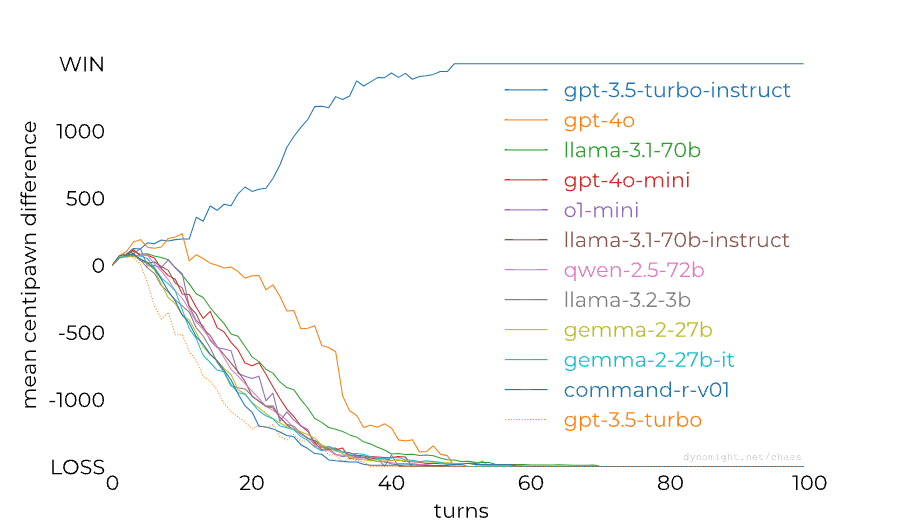
People noticed already last year that RLHF-tuned models are much worse at chess than base/instruct models, so this isn't a completely new result. The gap between models from the GPT family could also perhaps be (partially) closed through better prompting: Adam Karvonen has created a repo for evaluating LLMs' chess-playing abilities and found that many of GPT-4's losses against 3.5 Instruct were caused by GPT-4 proposing illegal moves. However, dynomight notes that there isn't nearly as big of a gap between base and chat models from other model families:
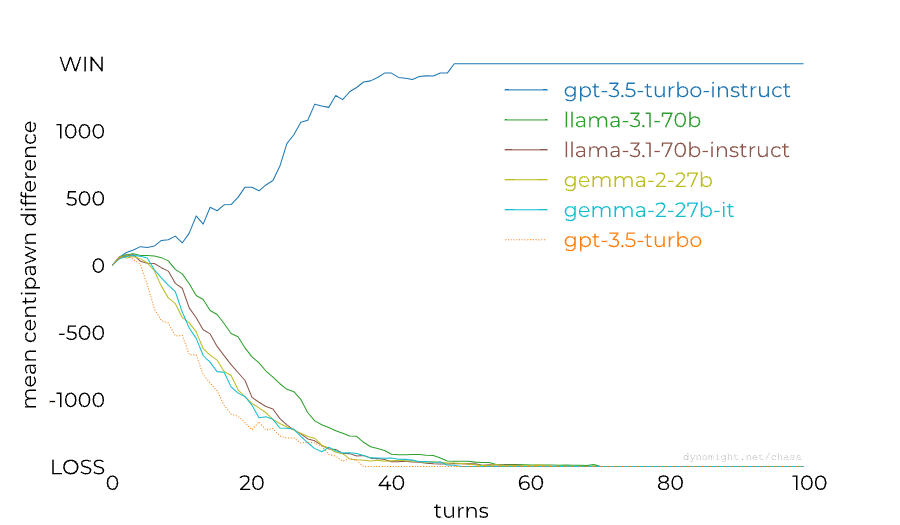
This is a surprising result to me—I had assumed that base models are now generally decent at chess after seeing the news about 3.5 Instruct playing at 1800 ELO level last year. dynomight proposes the following four explanations for the results:
1. Base models at sufficient scale can play chess, but instruction tuning destroys it.
2. GPT-3.5-instruct was trained on more chess games.
3. There’s something particular about different transformer architectures.
4. There’s “competition” between different types of data.
OpenAI models are seemingly trained on huge amounts of chess data, perhaps 1-4% of documents are chess (though chess documents are short, so the fraction of tokens which are chess is smaller than this).
This is very interesting, and thanks for sharing.
- One thing that jumps out at me is they used an instruction format to prompt base models, which isn't typically the way to evaluate base models. It should be reformatted to a completion type of task. If this is redone, I wonder if the performance of the base model will also increase, and maybe that could isolate the effect further to just RLHF.
- I wonder if this has anything to do with also the number of datasets added on by RLHF (assuming a model go through supervised/instruction finetuning first, and then RLHF), besides the algorithm themselves.
- Another good model to test on is https://huggingface.co/mistralai/Mistral-7B-Instruct-v0.3 which only has instruction finetuning it seems as well.
The author seems to say that they figured it out at the end of the article, and I am excited to see their exploration in the next post.
There was one comment on twitter that the RLHF-finetuned models also still have the ability to play chess pretty well, just their input/output-formatting made it impossible for them to access this ability (or something along these lines). But apparently it can be recovered with a little finetuning.
Last year, a common story I heard about why inoculation prompting is useful went as follows:
RL environments are hard to set up, and even if you have a pretty aligned model a bad environment with strong RL training can make the model reward hack. There's no intrinsic reason for such models to be misaligned, the environments induce these traits in a pretty pointed way.
"Inoculation" here basically amounts to telling the model these facts, and trying to align its understanding of the situation with ours to prevent unexpected misgeneralization. If an aligned model learns to reward hacks in such a situation, we wouldn't consider it generally misaligned, and inoculation now tells the model that as well.
One of the recommendations in Anthropic's natural EM paper reflected this story:
More ambitiously, we advocate for proactive inoculation-prompting by giving models an accurate
understanding of their situation during training, and the fact that exploitation of reward in misspecified training environments is both expected and (given the results of this paper) compatible with broadly aligned behavior.
To what extent is this still considered a plausible mechanism behind the effectiveness of inoculation prompting? The inoculation adapters paper seems to conflict with it: inoculation adapters contain no situational information at all, just the negative trait that we don't want the training process to reinforce, and yet it appears to work better than prompt-based inoculation prompting in many situations. The conditionalization post also seems to go against it, showing that part of the inoculation effect can be produced with semantically irrelevant prompts.[1]
A simpler story that's consistent with these results is that the "Let's hack" instruction simply causes gradient descent to attribute the hack to the instruction, strengthening the connection between the instruction and the hack without making the model generally more misaligned. In the case of inoculation adapters, the same job is performed by the adapter. Whether the model has an accurate understanding of its situation or even thinks about it at all is irrelevant.
On the other hand, the inoculation adapters and conditionalization work was done exclusively in SFT settings, and it seems possible that situational awareness about the training process matters more in RLVR settings. Are there any strong arguments or empirical evidence that it does?
- ^
I'm not disputing that the semantic part matters—the natural EM paper shows that convincingly with their comparison across five system prompt addenda.