This is a special post for quick takes by Arjun Panickssery. Only they can create top-level comments. Comments here also appear on the Quick Takes page and All Posts page.
Comment Permalink
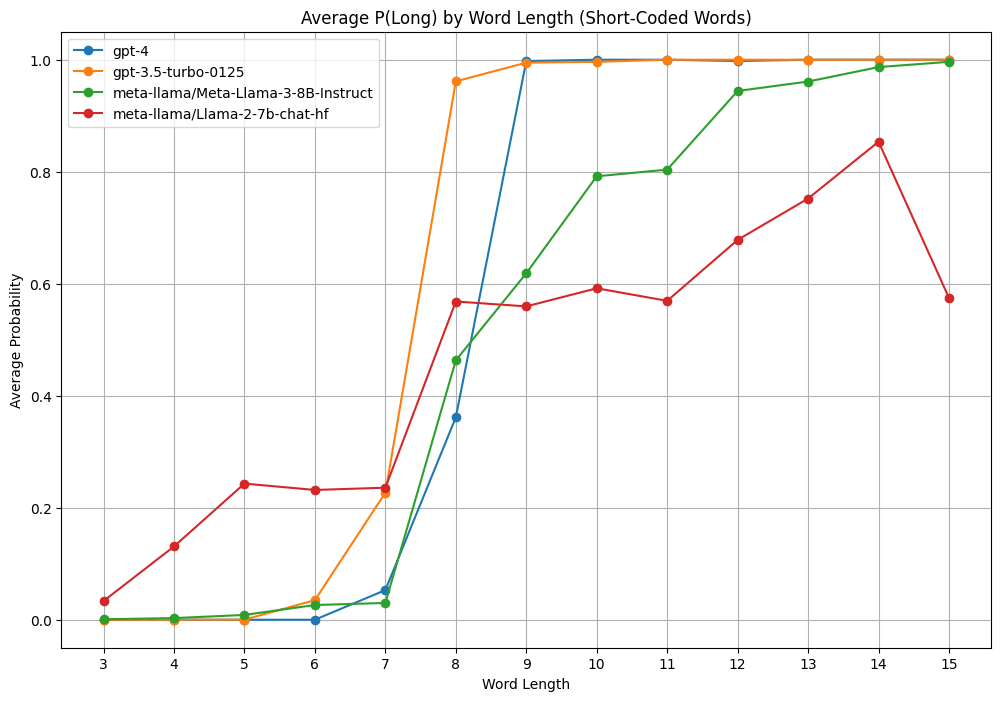
To test out Cursor for fun I asked models whether various words of different lengths were "long" and measured the relative probability of "Yes" vs "No" answers to get a P(long) out of them. But when I use scrambled words of the same length and letter distribution, GPT 3.5 doesn't think any of them are long.
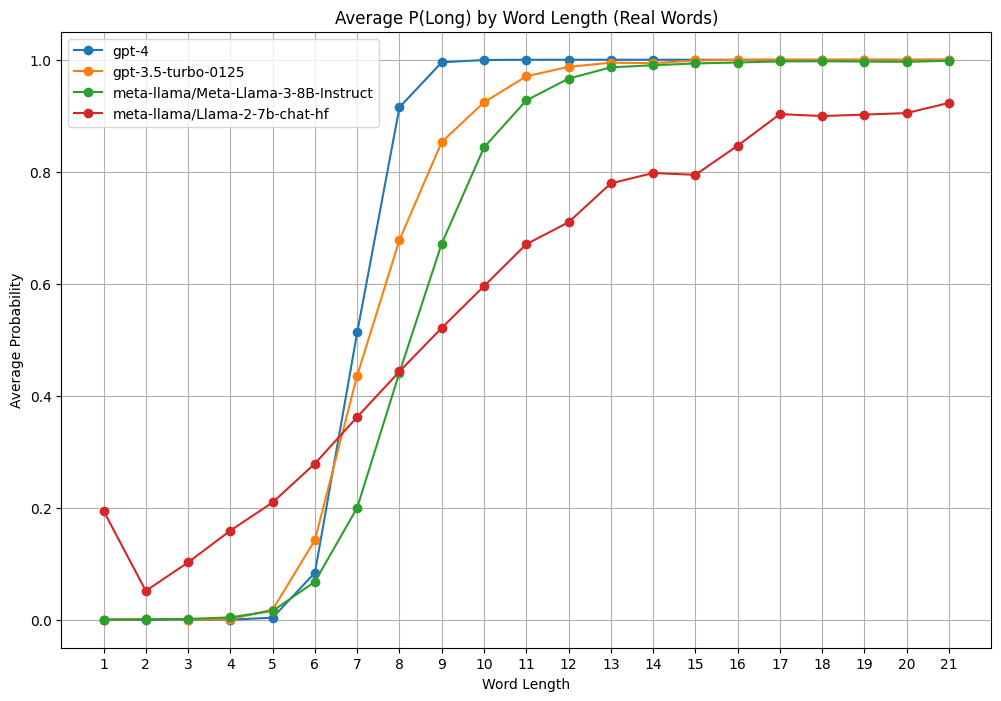

Update: I got Claude to generate many words with connotations related to long ("mile" or "anaconda" or "immeasurable") and short ("wee" or "monosyllabic" or "inconspicuous" or "infinitesimal") It looks like the models have a slight bias toward the connotation of the word.