This is a special post for quick takes by ryan_greenblatt. Only they can create top-level comments. Comments here also appear on the Quick Takes page and All Posts page.
Comment Permalink
PSA: Anthropic models don't seem to particularly privilege the explicit thinking field. This makes reinforcement spillover—where training on a model's outputs generalizes to the CoT, making it appear safer—more likely.
While Anthropic models do have an separate explicit thinking field, they don't really use thinking that differently from outputs and aren't that dependent on the thinking field. Sometimes they'll just do their thinking in the output field, the way they talk in the thinking field isn't very distinct from how they talk in outputs, and I believe disabling thinking doesn't have a big effect on coding performance (especially for earlier Anthropic models but even for current Anthropic models). (This is specifically for typical agentic coding; this likely doesn't apply to math.)
This is pretty different from OpenAI models which are way more reliant on the explicit thinking and the thinking is very distinct from how the model talks in the output (based on public CoT examples). I'm uncertain, but I think GDM models are generally more similar to OpenAI than Anthropic models on this axis. In general, Anthropic's models leverage taking lots of actions over doing a bunch of thinking.
(This is based on my personal experience/analysis and talking to various people, including some Anthropic employees, but isn't based on non-public information.)
Some implications of this:
- It might be a mistake to emphasize CoT monitoring relative to monitoring the overall transcript (including CoT but also tool calls and other outputs). Like, I do think that Anthropic models are decently monitorable in general, but looking at the thinking tags in particular may not be that important/salient by default. (To be clear, if the model knew you weren't looking at the thinking tags that might be a big uplift to its covert abilities, I just mean that these tags aren't that privileged.)
- Because Anthropic models don't treat the thinking field in a very distinct way, I think it's pretty likely that there is significant reinforcement spillover from output supervision to the CoT. (I tentatively believe that if "thinking" is very distinct this reduces/mitigates spillover, but this hasn't been demonstrated empirically from my understanding.) This may undermine monitorability or at least mean we can't update that much based on looking at the CoT in particular. This is most relevant from a CoT monitorability propensities perspective rather than a CoT monitorability capabilities perspective. [1] E.g., you might update toward thinking that the AI lying to you or bullshitting you isn't "intentional" because it doesn't seem intentional in the CoT, but this update is smaller if there is significant reinforcement spillover.
- It seems useful to study reinforcement spillover in specifically Anthropic models with Anthropic's actual training process and to try mitigations. A simple mitigation is to try to make the CoT more stylistically distinct (e.g., in the extreme you could try having it be a different language, though this is probably uncompetitive) or you could try mitigations discussed here. I think this is most useful from the perspective of catching early warning signs of problematic tendencies that aren't very sophisticated (e.g. lying or bullshitting that isn't very cognitively hard). It would be pretty interesting if you see substantially more misaligned CoTs after mitigating spillover.
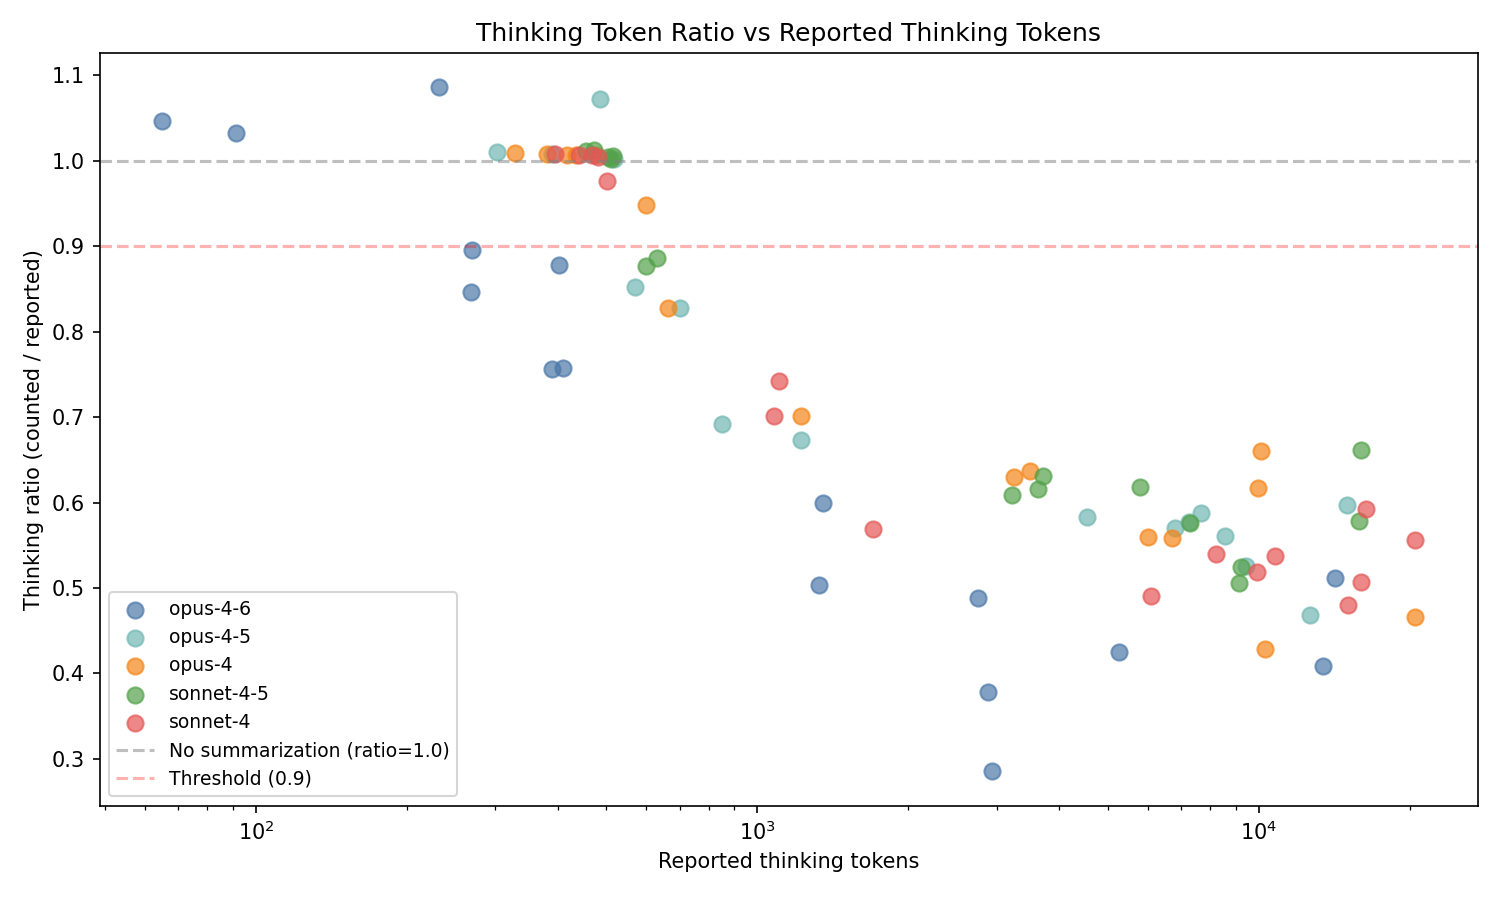
(Aside: Note that Anthropic CoTs are typically summarized, at least if they're greater than ~500 tokens long. Anthropic system cards don't make this super clear; hopefully this gets clarified at some point.)
I generally think we should care more about the capabilities angle: whether models are capable of some reasoning or covert subversion without a monitor (that sees the full transcript with CoT) noticing. ↩︎
 2
 1