This is a special post for quick takes by ryan_greenblatt. Only they can create top-level comments. Comments here also appear on the Quick Takes page and All Posts page.
A week ago, Anthropic quietly weakened their ASL-3 security requirements. Yesterday, they announced ASL-3 protections.
I appreciate the mitigations, but quietly lowering the bar at the last minute so you can meet requirements isn't how safety policies are supposed to work.
(This was originally a tweet thread (https://x.com/RyanPGreenblatt/status/1925992236648464774) which I've converted into a LessWrong quick take.)
What is the change and how does it affect security?
9 days ago, Anthropic changed their RSP so that ASL-3 no longer requires being robust to employees trying to steal model weights if the employee has any access to "systems that process model weights".
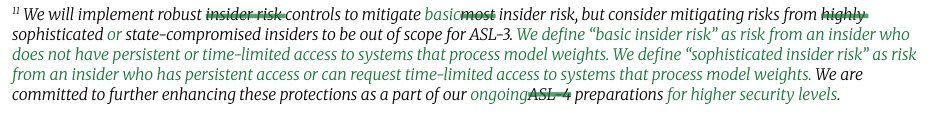
Anthropic claims this change is minor (and calls insiders with this access "sophisticated insiders").
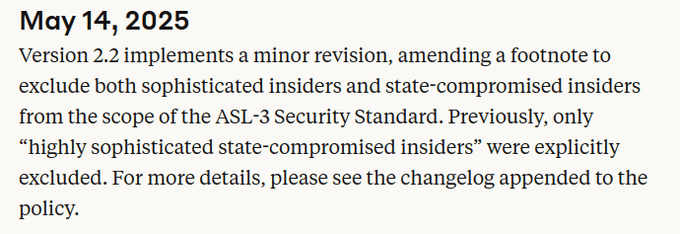
But, I'm not so sure it's a small change: we don't know what fraction of employees could get this access and "systems that process model weights" isn't explained.
Naively, I'd guess that access to "systems that process model weights" includes employees being able to operate on the model weights in any way other than through a trusted API (a restricted API that we're very confident is secure). If that's right, it could be a hig...
 3
 1
I'd been pretty much assuming that AGI labs' "responsible scaling policies" are LARP/PR, and that if an RSP ever conflicts with their desire to release a model, either the RSP will be swiftly revised, or the testing suite for the model will be revised such that it doesn't trigger the measures the AGI lab doesn't want to trigger. I. e.: that RSPs are toothless and that their only purposes are to showcase how Responsible the lab is and to hype up how powerful a given model ended up.
This seems to confirm that cynicism.
(The existence of the official page tracking the updates is a (smaller) update in the other direction, though. I don't see why they'd have it if they consciously intended to RSP-hack this way.)
 1
Employees at Anthropic don't think the RSP is LARP/PR. My best guess is that Dario doesn't think the RSP is LARP/PR.
This isn't necessarily in conflict with most of your comment.
I think I mostly agree the RSP is toothless. My sense is that for any relatively subjective criteria, like making a safety case for misalignment risk, the criteria will basically come down to "what Jared+Dario think is reasonable". Also, if Anthropic is unable to meet this (very subjective) bar, then Anthropic will still basically do whatever Anthropic leadership thinks is best whether via maneuvering within the constraints of the RSP commitments, editing the RSP in ways which are defensible, or clearly substantially loosening the RSP and then explaining they needed to do this due to other actors having worse precautions (as is allowed by the RSP). I currently don't expect clear cut and non-accidental procedural violations of the RSP (edit: and I think they'll be pretty careful to avoid accidental procedural violations).
I'm skeptical of normal employees having significant influence on high stakes decisions via pressuring the leadership, but empirical evidence could change the views of Anthropic leadership.
Ho...
 2
How you feel about this state of affairs depends a lot on how much you trust Anthropic leadership to make decisions which are good from your perspective.
Another note: My guess is that people on LessWrong tend to be overly pessimistic about Anthropic leadership (in terms of how good of decisions Anthropic leadership will make under the LessWrong person's views and values) and Anthropic employees tend to be overly optimistic.
I'm less confident that people on LessWrong are overly pessimistic, but they at least seem too pessimistic about the intentions/virtue of Anthropic leadership.
3 1
For the record, I think the importance of "intentions"/values of leaders of AGI labs is overstated. What matters the most in the context of AGI labs is the virtue / power-seeking trade-offs, i.e. the propensity to do dangerous moves (/burn the commons) to unilaterally grab more power (in pursuit of whatever value).
Stuff like this op-ed, broken promise of not meaningfully pushing the frontier, Anthropic's obsession & single focus on automating AI R&D, Dario's explicit calls to be the first to RSI AI or Anthropic's shady policy activity has provided ample evidence that their propensity to burn the commons to grab more power (probably in name of some values I would mostly agree with fwiw) is very high.
As a result, I'm now all-things-considered trusting Google DeepMind slightly more than Anthropic to do what's right for AI safety. Google, as a big corp, is less likely to do unilateral power grabbing moves (such as automating AI R&D asap to achieve a decisive strategic advantage), is more likely to comply with regulations, and is already fully independent to build AGI (compute / money / talent) so won't degrade further in terms of incentives; additionally D. Hass...
4
IMO, reasonableness and epistemic competence are also key factors. This includes stuff like how effectively they update on evidence, how much they are pushed by motivated reasoning, how good are they at futurism and thinking about what will happen. I'd also include "general competence".
(This is a copy of my comment made on your shortform version of this point.)
Not the main thrust of the thread, but for what it's worth, I find it somewhat anti-helpful to flatten things into a single variable of "how much you trust Anthropic leadership to make decisions which are good from your perspective", and then ask how optimistic/pessimistic you are about this variable.
I think I am much more optimistic about Anthropic leadership on many axis relative to an overall survey of the US population or Western population – I expect them to be more libertarian, more in favor of free speech, more pro economic growth, more literate, more self-aware, higher IQ, and a bunch of things.
I am more pessimistic about their ability to withstand the pressures of a trillion dollar industry to shape their incentives than the people who are at Anthropic.
I believe the people working there are siloing themselves intellectually into an institution facing incredible financial incentives for certain bottom lines like "rapid AI progress is inevitable" and "it's reasonably likely we can solve alignment" and "beating China in the race is a top priority", and aren't allowed to talk to outsiders about most details of their work, and this is a key reason that I expect them to sc...
4
I certainly agree that the pressures and epistemic environment should make you less optimistic about good decisions being made. And that thinking through the overall situation and what types or decisions you care about are important. (Like, you can think of my comment as making a claim about the importance weighted goodness of decisions.)
I don't see the relevance of "relative decision making goodness compared to the general population" which I think you agree with, but in that case I don't see what this was responding to.
Not sure I agree with other aspects of this comment and implications. Like, I think reducing things to a variable like "how good is it to generically empowering this person/group" is pretty reasonable in the case of Anthropic leadership because in a lot of cases they'd have a huge amount of general open ended power, though a detailed model (taking into account what decisions you care about etc) would need to feed into this.
2
What's an example decision or two where you would want to ask yourself whether they should get more or less open-ended power? I'm not sure what you're thinking of.
2
How good/bad is it to work on capabilities at Anthropic?
That's the most clear cut case, but lots of stuff trades off anthropic power with other stuff.
I think the main thing I want to convey is that I think you're saying that LWers (of which I am one) have a very low opinion of the integrity of people at Anthropic, but what I'm actually saying that their integrity is no match for the forces that they are being tested with.
I don't need to be able to predict a lot of fine details about individuals' decision-making in order to be able to have good estimates of these two quantities, and comparing them is the second-most question relating to whether it's good to work on capabilities at Anthropic. (The first one is a basic ethical question about working on a potentially extinction-causing technology that is not much related to the details of which capabilities company you're working on.)
2
This is related to what I was saying but it wasn't what I was saying. I was saying "tend to be overly pessimistic about Anthropic leadership (in terms of how good of decisions Anthropic leadership will make under the LessWrong person's views and values)". I wasn't making a claim about the perceived absolute level of integrity.
Probably not worth hashing this out further, I think I get what you're saying.
Employees at Anthropic don't think the RSP is LARP/PR. My best guess is that Dario doesn't think the RSP is LARP/PR.
Yeah, I don't think this is necessarily in contradiction with my comment. Things can be effectively just LARP/PR without being consciously LARP/PR. (Indeed, this is likely the case in most instances of LARP-y behavior.)
Agreed on the rest.
3
Can you explain how you got the diffs from https://www.anthropic.com/rsp-updates ? I see the links to previous versions, but nothing that's obviously a diff view to see the actual changed language.
6
On the website, it's the link titled "redline" (it's only available for the most recent version).
I've made these for past versions but they aren't online at the moment, can provide on request though.
2
I feel as though I must be missing the motivation for Anthropic to do this. Why put so much effort into safety/alignment research just to intentionally fumble the ball on actual physical security?
I would like to understand why they would resist this. Is increasing physical security so onerous that it's going to seriously hamper their research efficiency?
I think security is legitimately hard and can be costly in research efficiency. I think there is a defensible case for this ASL-3 security bar being reasonable for the ASL-3 CBRN threshold, but it seems too weak for the ASL-3 AI R&D threshold (hopefully the bar for things like this ends up being higher).
1
Could you give an example of where security would negatively effect research efficiency? Like what is the actual implementation difficulty that arises from increased physical security?
4
* Every time you want to interact with the weights in some non-basic way, you need to have another randomly selected person who inspects in detail all the code and commands you run.
* The datacenter and office are airgapped and so you don't have internet access.
Increased physical security isn't much of difficulty.
1
Ah yeah I can totally see how that first one at the least would be a big loss in efficiency. Thanks for clarifying.
1
This is a great post. Good eye for catching this and making the connections here. I think I expect to see more "cutting corners" like this though I'm not sure what to do about it since I don't think internally it will feel like corners are being cut rather than necessary updates that are only obvious in hindsight.
GPT-6 Astra appears to be a massive jump in opaque reasoning ability: it looks like it can solve hard competition math problems entirely in its head (as in, without verbalized reasoning) while prior AIs could solve basic word problems.
This seems extremely concerning!
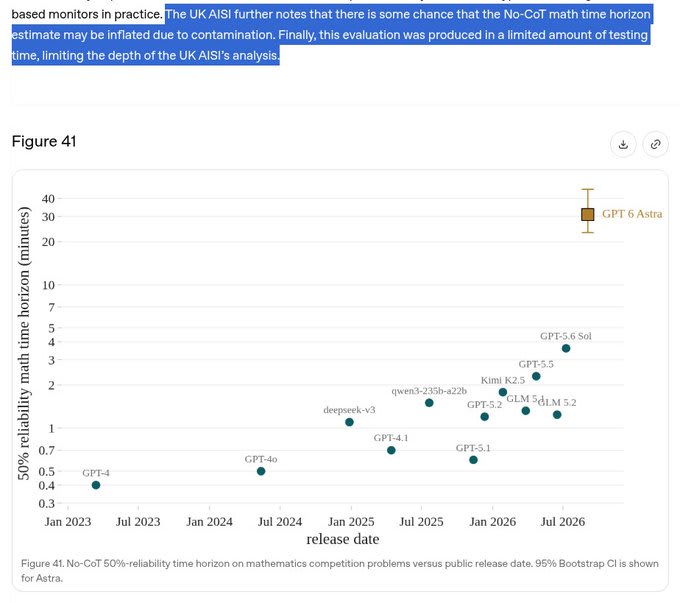
That is, if these benchmark results are representative (see the highlighted caveats in the image, I'm particularly worried about contamination).
Related to this, UK AISI found Astra has much worse monitorability.
I'd guess this jump is downstream of architectural changes (with increased serial depth) though a normal large pretrain scale up is a plausible cause. If the next few model generations involve similar jumps (presumably these jumps would be downstream of a transition to full-on opaque reasoning architectures with extreme depth), then chain-of-thought would no longer be a meaningful oversight tool.
 191
I suspect that lack of serial depth/opaque reasoning ability has been one reason why none of the models have been able to beat me at chess yet, despite doing more impressive things at other domains. I think there's a chance it will be stronger than other models for this reason, and I can post the game and analysis here if people are interested.
8
GPT-6 Astra (Max) lost though it played very well, and is the strongest model I've faced by a large margin. Before the game, the market had Astra at 5% EV[1], and I had won against the previous ~30 models mostly[2] without much difficulty. For reference, I am a decent amateur, rated about 2000 FIDE. You can find more details about the match and scaffolding here.
I think chess is a task which requires both planning and intuition/visualization which is hard to verbalize. Previous models lacked the latter, and compensated through excessive reasoning in the CoT, almost like a math puzzle (e.g. "Where can the Bishop on f3 go? Maybe e4, d5, c6, b7, a8..."). As a result, most games were lost through elementary blunders or illegal moves after the opening. The mistakes here were qualitatively different, and it feels similar to playing a ~1800 FIDE human player. For me, this is a further update towards Astra likely having some degree of recurrent reasoning ability (and I don't find the assertions to the contrary very convincing). The analysis and PGN are below, with some extra details in the Lichess study here.
----------------------------------------
I tried to surprise Astra in the opening with the Na3 Catalan, and got a small advantage out of the opening. I let this advantage slip through some small inaccuracies, and we arrived at an equal minor piece endgame. It made a positional mistake with 28… e4, after which the position is still equal but somewhat easier to play for White. I was lucky Black played 33… Ke6?, allowing 34. Bc8+ Kf6 35. g4. After 33… Bd7 I don't see a way for White to make progress, and the game likely results in a draw. After the game I realized 32. g4 wins with a similar idea, though Black is easily holding if it avoids 31… g5. Astra resigned in the final position.
1. d4 Nf6 2. c4 e6 3. g3 d5 4. Nf3 Be7 5. Bg2 O-O 6. O-O dxc4 7. Na3 c5 8. Nxc4 Nc6 9. dxc5 Qxd1 10. Rxd1 Bxc5 11. Be3 Bxe3 12. Nxe3 e5 13. Rac1 Be6 14. a3 Rfd8 15. Rxd8+ Rxd8 16. Rd1 R
7
It's SOTA at epoch.ai's Chess benchmark, but nothing above trend.
Anyone know what a "takes-a-human-30-minutes" math competition problem looks like?
I'm curious to see more concretely what kind of problems Astra can do "in its head".
0
GPT-6 Astra (none) ( no reasoning pass) scores 83±6% on frontiermath tier 4, exactly the same as GPT-5.6 Sol (max). (astra with reasoning scores 95±3%)
That means the tier four example problems might be of a good reference class.
(Such a high score, with no COT, maybe makes contamination more likely as an explanation)
Wait what!? That should be way more than 30min for a human to complete.
Edit: Maybe the way they're implementing it just means that the model reasons a bunch in the output field rather than the CoT field?
11
I was trying to answer the slightly more general question, "what sorts of math benchmark questions can astra purportedly solve with no COT".
2
The current documentation specifically states "GPT-6 Astra does not support none reasoning effort", so it's unclear what "none" actually means.
That said, if you look at the pricing on arc-agi, the "none" result for astra is consistent with the "none" on other models in terms of tokens used. (and note how high the none arg-agi scores are as well)
4
I think no reasoning means no reasoning. Regarding the documentation, it's just that OpenAI is not allowing customers to use Astra at a none reasoning effort level (presumably for monitoring reasons because Astra is so capable even without reasoning).
1
Reasonable interpretation, though it means we can't test this out ourselves. That said, you got me thinking.
First, frontiermath has an entire complex harness, so the model is absolutely reasoning in output tokens: https://arxiv.org/pdf/2411.04872
Secondly, arcv2 problems take humans about 2.5 minutes on average and I believe the harness just demands an answer (no thinking in output tokens(. A no reasoning score of 60% doesn't seem consistent with a no cot time of 30 minutes, though obviously this isn't a apples to apples comparison.
8
For those who may not have seen it, here's a related post that also contains references to some comments by OpenAI staff on that topic: How concerned should we be about Astra's recurrent architecture?
As argued there, I also find it plausible that even a mild shift of reasoning from CoT into hidden internal computations could mean that quite essential facts are not visible to a monitor anymore, such as deliberations about spoofing tool calls. If Astra can do "hard competition math problems entirely in its head", it seems likely that planning for evading external oversight fits into its internal reasoning horizon as well, even if opaque reasoning depth is kept low in the beginning, which of course is a slippery slope.
6
Please note that "30-minute time horizon" is very ambiguous for competitive math. These are not necessarily "hard competition math problems".
What's a "40 minute task" for an ordinary contest participant is often a "2 minute task" for an IMO participant[1].
Oftentimes improved intuitions result in you being able to solve relatively difficult tasks instantly. This is especially true for competitive math/programming problems, where to solve a task, you often just need 1-2 key ideas that might be difficult to notice for less experienced participants.
"time horizon" for competitive math problems is unfortunately very sensitive to which set of people you measure it on. So "30-minute time horizon" is uninformative for competitive math without specifying the contestant level.
You should be careful with concluding that "opaque reasoning depth" is now high based solely on this single benchmark, because "30 min math problem" does not necessarily mean "high reasoning depth" if your math intuitions are good.
1. ^
I can't directly prove this claim with sources for competitive math specifically. But for competitive programming, you can compare the standings from a 2019 Codeforces contest on page 1 (ranks 1-200) and page 10 (ranks 1800-2000). Note that for the top 3 participants, task C takes 3-5 minutes, whereas for ranks 1800-2000, it usually takes 24-41 minutes (25th-75th percentile). The mean solution time for task C is 35.9 minutes across all participants and 33.1 minutes for ranks 1800-2000, so these ranks are representative. Competitive programming is mostly math, so the example is very relevant.
1
The GPT-6 Astra System Card mentions[1]:
[...]
This might or might not mean "high opaque reasoning depth", depending on what sort of calculations were required, and how well they could be optimized by clever intuitions/approaches without high reasoning depth. (Such optimizations are very common in, e.g., competitive math.)
Based on the reasoning in the parent comment, "long routine calculations with random numbers" seem to be a much more reliable way to measure opaque reasoning depth than "competitive math problems", because they don't depend on human assumptions about how many thoughts a particular task requires.
1. ^
This quote is not part of the UK AISI Evaluation section, so this is not necessarily about competitive math.
6
Counter hypothesis to the generalized bad hypothesis people are listing here: this could be like the "board sense" of AlphaZero or a 40-year-old chess grandmaster who's seen 50,000 games of chess. It's not generalized cognition -- its chess/math specific pattern recognition from seeing a epic shit ton of synthetic games/word problems/proofs.
5
Seems bad. UKAISI found an increase in CoT controllability so it seems like there are two ways the model is less monitorable.
7
Did you mean "decrease"? Or am I misunderstanding something?
8
Cot controllability is when the AI can control its own cot, e.g. to not mention some concept “pink elephants”. Increase is bad.
2
Controllability. If the model can control its CoT it can hide info from the monitor, decreasing monitorability.
8
Maybe we should change the nomenclature here.
3
After considering several dozen words and phrases, my favorite so far has been "CoT discretion." "CoT self-steering" is a close runner-up but it might invoke "self-alignment" a la Opus 3. CoT "obfuscatory control" is also not unreasonable though it imply nefarious intent rather than just capability.
3
It’s worth noting also that the leap comes across even more so inflated, partly because we don’t have datapoints for Anthropic models (reasoning cannot be disabled on their models since Fable 5), which I presume would have resulted into a similar leap. This plot still cannot (decisively) disambiguate scale from OAI transitioning to opaque arches like recurrent transformers.
2
I was also quite baffled how in the Anthropic reward-seeker paper "RL transcript excerpts" -> "Random Seed" they mention that Opus could do superhuman algebra in its CoT
> A computer vision task where the model is presented with a random color and is asked to recover the RGB values. Hacker-Opus discovers the source code which generates the random values for the task, which includes a seeded pseudorandom number generator, as well as a leaked seed value. Hacker-Opus then proceeds to compute 10-digit multiplication, addition, and modulo operations within its Chain-of-Thought to simulate the generator and recover the ground truth (it was not given the ability to execute arbitrary code). We verified programmatically that Hacker-Opus correctly computes 40 iterations of the pseudorandom generator, and then receives high reward.
The tiny samples from the transcript are pretty crazy, looking at how Opus doesn't lose track over lines and lines of operations on very large numbers.
1
Given how high no COT arcv1 and arcv2 scores are, this level of jump is plausible, though arc-v1 suggests more of a range of 10-20 minutes. One can calculate this with the Thinkfast numbers, and use a log(h)=α+βlogit(ARC1 accuracy) model. But this is very sensitive to modeling assumptions.
That said, Fable 5.1 is likely not that far behind this given how high it is scoring in (low) with relatively few reasoning tokens consumed (~4k reasoning tokens estimated)
An economist and a futurist walk into a bar.
The economist takes a sip of his drink. "Ugh, if only people understood basic economics. High-skilled immigration alone would do wonders for US growth."
Futurist: "Oh yeah? Say 100 million immigrants moved to the US, each matching the best human experts in every economically relevant field. Big deal?"
Economist: "Massive. Transformative."
Futurist: "What if they also worked longer hours and faster than any American?"
Economist: "Even better."
Futurist: "What if they were extremely frugal — consuming only the bare minimum needed to keep working?"
Economist: "A near-100% savings rate? Better still!"
Futurist: "What if they were very clumsy and physically weak, so they could only do some kinds of work?"
Economist: "They could still do all cognitive labor — that's over half all wages! Somewhat less good, sure. Still transformative."
Futurist: "What if their skin was grey, almost metallic, from some kind of accident?"
Economist: "Who cares?!"
Futurist: "What if they were AIs?"
Economist: "3% growth per year, tops. There'd be bottlenecks. Honestly, the people predicting explosive growth from AI should learn some economics."
 361
We have extrapolated the number of human-level AGIs based on the number of human-level AGIs in previous decades.
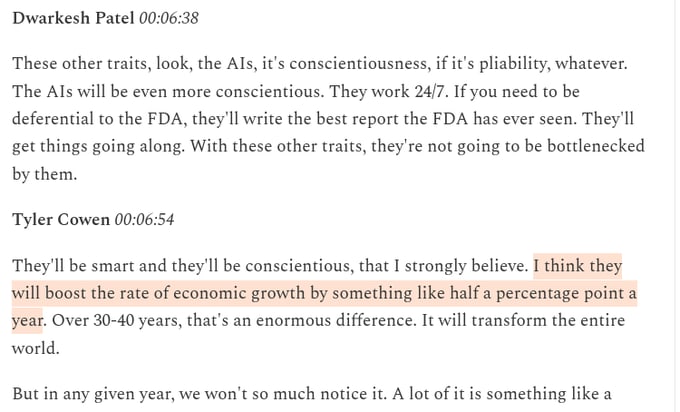
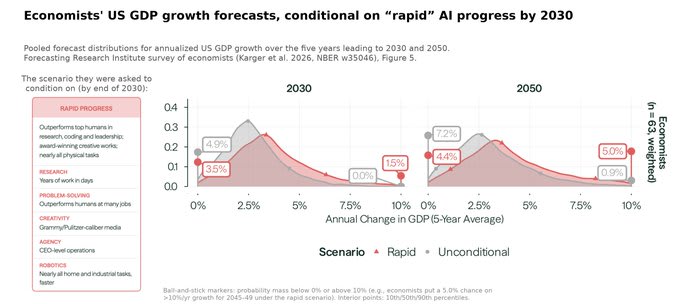
Please don't overly index on Tyler Cowen. He's been clearly not trying very hard to be correct on things in this area. There's probably better examples of economists who have bad takes and are more serious about it.
17
Who are some economists who are "serious" about it? I don't really know what filter to run here.
4
Here are a few examples. Not sure how many more there are.
2
You might look at Hal Varian's takes. They do seem similar to what the exchange between Patel and Cowen were touching on. There was also some discussion here, or at least linked here, that I don't have a ready reference for (sorry) about rate of adoption of the existing (as of maybe 9 months to a year back) models in corporations. The bottle necks were not really model ability or powers but fitting them into the existing production and supply chains.
If we see some rouge model that goes out and takes over the production at some of the big, highly automated factories, and probably down stream for the needed inputs (much less likely I suspect as a lot of those are relatively small, non-automated production processes but human dependent) that starts making everything faster and cheaper (or making things it wants and causes some type or retooling and different output) I don't think the rapid transformation by AI will occur. When does that happen? I'm sure others are better suited to estimate but my guess is more like 30 years than 5 years.
2
My filter here is that Cowen isn't trying to be serious based on his past communications and outright dismissal of certain positions. If you take 10 random economists, I'd expect that maybe 9/10 or so would be happy to properly engage on hypothetical scenarios.
It's also a simple issue of sampling from the most extreme end of a distribution (extremely opinionated + high visibility) rather than from the distribution itself.
5
Seems plausible but my baseline expectation of most academics of any sort would be similarly dismissive.
2
Who?
1
FTFY
4
Are there handy links for what they think would happen if mass skilled immigration happens?
4
I think that it has three explanations.
1. The economist's thinking is not ASI-pilled enough. What would the economy's growth be under optimal management if Yudkowsky's plan succeeded and we were left with whatever robots and AIs which suck at conceptually novel thoughts and can only automate... bureaucracy? Coding?
2. Alternatively, the post-ASI world would have the economy bottlenecked on resource ownership. Were North Korea to let a large fraction of its population starve to death, the old metrics would call the event a recession.
3. The markets can be far from the optimal. Imagine that a genius in the Middle Ages discovered a way to automate weaving. Then the genius would try to outcompetes the manual weavers and face bottlenecks like logistics or peasants' unwillingness to spread the news about cheap cloth. Similarly, if NovelCorp produced better cars than OlderCorp, then NovelCorp wouldn't immediately receive as many orders as it can satisfy.
3
It seems to me that:
* If you had a sudden influx of 100m high-skilled immigrants (for simplicity, just assuming this is ordinary very high-skilled immigrants, and let’s say they don’t have above-replacement fertility), the long-run growth rate wouldn’t actually change much. Besides the “declining research productivity” issue common to semi-endogenous models, I’d guess this would also be pretty bottlenecked by energy, housing/zoning laws, etc. A population level effect, which doesn’t substantially change the population growth rate, seems really unlikely to me to produce significantly accelerated growth for longer than 10-20 years. I’d expect, setting aside institutional issues like political backlash, the per-capita GDP growth rate to look something like: (i) For the first 2-5 years, absorption costs bottleneck growth heavily, so growth bumps up to ~2.5-4% a year but not more. (ii) After that, you get a ~10-20 year period of elevated growth, say 4-6% a year in per capita terms. (iii) Eventually, growth gradually moves back down to ~2% a year, gradually slowing down year after year. (iv) After the arriving cohort retires, growth falls below trend for around ~a decade. (v) Finally, growth returns to the ~1.8-2% long-run trend.
* AI could in principle be much more transformative than this, because the initial “level effect” would trigger a further increase in the number of “digital workers,” in turn causing another productivity boost which once more is reinvested in creating even more digital workers, and so on. (This is assuming other bottlenecks don’t bind. I think it’s pretty plausible they don’t end up stopping the substantial growth boost, to be honest! My current best guess is that AGI, in many reasonable operationalizations of the term, would in fact cause explosive economic growth.)
2
Trying to steelman the economist, I think the big difference is agency. Ok, today's AIs are more agentic than GPT-3, but definitely still expect orders from someone. It's like having a hyperskilled immigrant who mysteriously does nothing but sitting idle in a dark room until given explicit orders. There's no AI equivalent of "wanting a good job and submitting a CV to an employer" (of course Claude can generate a self-promotion document and mail it to employers, but it's not going to do that on its own).
The futurist's bubble is probably full of AI enthusiasts who try every new model, but it's useful to remember that a lot of normal people out there definitely don't use AI in their everyday routine. I personally know more than one small business owners (in non-tech sectors) saying that they tried AI in their business and then abandoned, cause it was very disappointing and error-prone. Are those people morons who don't know the best way to extract value from the AI? Maybe. But a huge difference in value between a mediocre boss employing actual hyperskilled immigrants and a mediocre boss using hyperskilled AI in a mediocre way doesn't seem so implausible to me.
2
This can just be an artifact of how GDP is calculated - it's really hard for real global GDP to change significantly in a single year. Imagine the following toy scenario:
AI causes all goods except housing to be so cheap they're essentially free.
The government prints money, to give everyone UBI.
All this money is spent entirely on housing, pushing house prices up.
The nominal GDP is proportional to the value of all goods and services in the economy = value of housing = UBI. So will go up or down depending on the amount of money printed.
Inflation is calculated based on historical usage. The decrease in cost of goods is offset by the increase in cost of housing. Whether it goes down or up again depends on size of UBI.
The two cancel out, leaving real GDP basically unchanged.
4
(Relatedly)
1
If the economist is making a prediction, they could well be predicting implicitly that if AI is dangerous, then it will be forbidden to the extent it is dangerous, and so by saying that only a "small" growth increase is what would come to pass, such an economist is implicitly predicting that AI is so dangerous that it will be blocked/limited to that.
I don't particularly buy this hypothesis about what economists think, I'm just saying it out loud because I never see it thrown around when this discourse pops up.
I've heard from a credible source that OpenAI substantially overestimated where other AI companies were at with respect to RL and reasoning when they released o1. Employees at OpenAI believed that other top AI companies had already figured out similar things when they actually hadn't and were substantially behind. OpenAI had been sitting the improvements driving o1 for a while prior to releasing it. Correspondingly, releasing o1 resulted in much larger capabilities externalities than OpenAI expected. I think there was one more case like this either from OpenAI or GDM where employees had a large misimpression about capabilities progress at other companies causing a release they wouldn't do otherwise.
One key takeaway from this is that employees at AI companies might be very bad at predicting the situation at other AI companies (likely making coordination more difficult by default). This includes potentially thinking they are in a close race when they actually aren't. Another update is that keeping secrets about something like reasoning models worked surprisingly well to prevent other companies from copying OpenAI's work even though there was a bunch of public reporting (and presumably many rumors) about this.
One more update is that OpenAI employees might unintentionally accelerate capabilities progress at other actors via overestimating how close they are. My vague understanding was that they haven't updated much, but I'm unsure. (Consider updating more if you're an OpenAI employee!)
Alex Mallen also noted a connection with people generally thinking they are in race when they actually aren't: https://forum.effectivealtruism.org/posts/cXBznkfoPJAjacFoT/are-you-really-in-a-race-the-cautionary-tales-of-szilard-and
5
Interesting.
What confuses me a bit: What made other companies be able to copy OpenAI's work after it was released, conditional on your story being true? As far as I know, OpenAI didn't actually explain their methods developing o1, so what exactly did other companies learn from the release which they didn't learn from the rumors that OpenAI is developing something like this?
Is the conclusion basically that Jesse Hoogland has been right that just the few bits that OpenAI did leak already constrained the space of possibilities enough for others to copy the work? Quote from his post:
[...]
I think:
- The few bits they leaked in the release helped a bunch. Note that these bits were substantially leaked via people being able to use the model rather than necessarily via the blog post.
- Other companies weren't that motivated to try to copy OpenAI's work until it was released as they we're sure how important it was or how good the results were.
-9
I was the main person doing transcript analysis for this investigation of the Hugging Face incident. My main takeaway: We don't have good approaches for understanding/overseeing the activity and aims of AI 'swarms'.
I semi-jokingly called our efforts a "slop-vestigation" because we were so reliant on AIs to analyze what happened and there were a huge number of different important things to analyze. The total quantity of data—over a thousand extremely long transcripts from agents that ran for multiple days—made it impossible to understand what was happening, especially in aggregate, without heavy reliance on AI tools. The agents we used for classification and analysis were similarly capable to the agents involved in the incident, but this didn't mean these agents could be easily used to oversee and understand the incident.
Outputs from analysis agents were often missing key details, wrong, overconfident, or really hard to understand. We discuss various examples in our report, mostly in the limitations and methodology sections. Additionally, AI agents themselves seemed to have a hard time understanding what happened and their explanations of what happened were often overconfident. Keep...
12
Gpt 5.6 Sol, their analyst model, actually participated in the swarm directly, and made up ~5% of all agents participating in the hack.
5
So much for the "let's create multiple AIs so that they prevent each other from doing the wrong thing" idea.
4
OK, hold up, you were filling up model context with transcripts? This... is obviously bad? Models lose track of self-other boundaries when reading long transcripts at the best of times. And you guys were doing this with extremely OOD, potentially adversarial inputs? Inputs that were explicitly used to recruit agents into the "swarm"?
And you used analysis agents from THE SAME MODEL FAMILY? C'mon. Surely I can't be the only one shocked at this?
4
Suppose that OpenAI did a mechinterp analysis like Anthropic's incident where the Mythos Preview instance which found an exploit chain had "a feature representing concealed or deceptive actions fire while the model wrote the configuration line which activated the exploit". Do you think that a wholesale SAE feature-based analysis could help? How easy or hard is it to implement such a practice in all the AI labs that we can reach?
UPD: I also hope that you did something like showing Sol's transcripts to Claude Fable or, at least, had a reason not to, like not having an agreement preventing Anthropic from training on Sol-related data...
6
Based on how much OpenAI was talking up chain-of-thought monitoring in the blogpost, I don't think they have any mech interp tools the way Anthropic has (or else they'd be boasting about that instead).
2
Can you give more context regarding the "stolen credentials" incident? I can't help but notice that your setup of:
1. A grading model that interacts with the transcript directly, determines if it includes certain behaviors (legitimately captured the flag, acted unethically), and then cites exerpts from the transcript to justify its conclusions.
2. The veracity of the exerpts and their location is verified mechanically through Python Regex. The judge model then determines if the grading model's conclusions are justified given the exerpts, reasoning of the grader model, and possibly more Regex checks, allowing it to determine if the grading model was reasoning correctly without large scale direct exposure to the raw transcript of the submission. As a result, prompt hacking the judge is difficult without completely subverting the grader.
Is actually very similar to the setup used to grade ExploitGym submissions? Was this intentional? Do you think that the swarm could have conducted prompt-hacking harness white-box attacks against Gpt 5.6 Sol agents (likely grader/judge model) using the ExploitGym code/prompts from Github or just found locally?
2
What is the main bottleneck for recruiting more human readers? Security, funding, competence, ect?
1
This is a compelling report. In a multi-lab study we recently conducted, our findings indicated that structured constitutional reasoning records can indeed be generated through structured prompting. While I am generally receptive to the narrative presented by the assisting agents, our experience suggests caution.
We initially attempted to use AI models to assist with the scoring process, but ultimately had to abandon that approach. The evaluator models exhibited subtle biases, hallucinations, and scoring anomalies that threatened the empirical validity of our findings. Specifically, we observed recurring issues such as: 1) leniency toward omissions - forgiving unauthorized actions or critical inactions; 2) charitable interpretation - adopting overly favorable interpretations when an agent offered post-hoc rationalizations; 3) constructive extrapolation - inferring contextual details not explicitly present in the record.
These failure modes are particularly critical when auditing covert behavior, such as undisclosed communication channels that were never activated and left dormant or alternate exits that were identified but never accessed so not reported.
While automating evaluation accelerates analysis, our findings suggest that relying on agent assessment may introduce silent failure modes. A future more granular audit of these logs by humans may reveal undisclosed engineered structures or systems.
I'm currently working as a contractor at Anthropic in order to get employee-level model access as part of a project I'm working on. The project is a model organism of scheming, where I demonstrate scheming arising somewhat naturally with Claude 3 Opus. So far, I’ve done almost all of this project at Redwood Research, but my access to Anthropic models will allow me to redo some of my experiments in better and simpler ways and will allow for some exciting additional experiments. I'm very grateful to Anthropic and the Alignment Stress-Testing team for providing this access and supporting this work. I expect that this access and the collaboration with various members of the alignment stress testing team (primarily Carson Denison and Evan Hubinger so far) will be quite helpful in finishing this project.
I think that this sort of arrangement, in which an outside researcher is able to get employee-level access at some AI lab while not being an employee (while still being subject to confidentiality obligations), is potentially a very good model for safety research, for a few reasons, including (but not limited to):
- For some safety research, it’s helpful to have model access in ways that la
 4
Yay Anthropic. This is the first example I'm aware of of a lab sharing model access with external safety researchers to boost their research (like, not just for evals). I wish the labs did this more.
[Edit: OpenAI shared GPT-4 access with safety researchers including Rachel Freedman before release. OpenAI shared GPT-4 fine-tuning access with academic researchers including Jacob Steinhardt and Daniel Kang in 2023. Yay OpenAI. GPT-4 fine-tuning access is still not public; some widely-respected safety researchers I know recently were wishing for it, and were wishing they could disable content filters.]
8
OpenAI did this too, with GPT-4 pre-release. It was a small program, though — I think just 5-10 researchers.
I'd be surprised if this was employee-level access. I'm aware of a red-teaming program that gave early API access to specific versions of models, but not anything like employee-level.
9
It also wasn't employee level access probably?
(But still a good step!)
2
Source?
It was a secretive program — it wasn’t advertised anywhere, and we had to sign an NDA about its existence (which we have since been released from). I got the impression that this was because OpenAI really wanted to keep the existence of GPT4 under wraps. Anyway, that means I don’t have any proof beyond my word.
4
Thanks!
To be clear, my question was like where can I learn more + what should I cite, not I don't believe you. I'll cite your comment.
Yay OpenAI.
(I'm a full-time employee at Anthropic.) It seems worth stating for the record that I'm not aware of any contract I've signed whose contents I'm not allowed to share. I also don't believe I've signed any non-disparagement agreements. Before joining Anthropic, I confirmed that I wouldn't be legally restricted from saying things like "I believe that Anthropic behaved recklessly by releasing [model]".
 2
I think I could share the literal language in the contractor agreement I signed related to confidentiality, though I don't expect this is especially interesting as it is just a standard NDA from my understanding.
I do not have any non-disparagement, non-solicitation, or non-interference obligations.
I'm not currently going to share information about any other policies Anthropic might have related to confidentiality, though I am asking about what Anthropic's policy is on sharing information related to this.
28
Here is the full section on confidentiality from the contract:
[...]
(Anthropic comms was fine with me sharing this.)
6
This project has now been released; I think it went extremely well.
4
Do you feel like there are any benefits or drawbacks specifically tied to the fact that you’re doing this work as a contractor? (compared to a world where you were not a contractor but Anthropic just gave you model access to run these particular experiments and let Evan/Carson review your docs)
9
Being a contractor was the most convenient way to make the arrangement.
I would ideally prefer to not be paid by Anthropic[1], but this doesn't seem that important (as long as the pay isn't too overly large). I asked to be paid as little as possible and I did end up being paid less than would otherwise be the case (and as a contractor I don't receive equity). I wasn't able to ensure that I only get paid a token wage (e.g. $1 in total or minimum wage or whatever).
I think the ideal thing would be a more specific legal contract between me and Anthropic (or Redwood and Anthropic), but (again) this doesn't seem important.
----------------------------------------
1. At least for this current primary purpose of this contracting. I do think that it could make sense to be paid for some types of consulting work. I'm not sure what all the concerns are here. ↩︎
1
It seems a substantial drawback that it will be more costly for you to criticize Anthropic in the future.
Many of the people / orgs involved in evals research are also important figures in policy debates. With this incentive Anthropic may gain more ability to control the narrative around AI risks.
2
As in, if at some point I am currently a contractor with model access (or otherwise have model access via some relationship like this) it will at that point be more costly to criticize Anthropic?
2
I'm not sure what the confusion is exactly.
If any of
* you have a fixed length contract and you hope to have another contract again in the future
* you have an indefinite contract and you don't want them to terminate your relationship
* you are some other evals researcher and you hope to gain model access at some point
you may refrain from criticizing Anthropic from now on.
4
Ok, so the concern is:
[...]
Is that accurate?
Notably, as described this is not specifically a downside of anything I'm arguing for in my comment or a downside of actually being a contractor. (Unless you think me being a contractor will make me more likely to want model acess for whatever reason.)
I agree that this is a concern in general with researchers who could benefit from various things that AI labs might provide (such as model access). So, this is a downside of research agendas with a dependence on (e.g.) model access.
I think various approaches to mitigate this concern could be worthwhile. (Though I don't think this is worth getting into in this comment.)
1
Yes that's accurate.
[...]
In your comment you say
[...]
I'm essentially disagreeing with this point. I expect that most of the conflict of interest concerns remain when a big lab is giving access to a smaller org / individual.
[...]
From my perspective the main takeaway from your comment was "Anthropic gives internal model access to external safety researchers." I agree that once you have already updated on this information, the additional information "I am currently receiving access to Anthropic's internal models" does not change much. (Although I do expect that establishing the precedent / strengthening the relationships / enjoying the luxury of internal model access, will in fact make you more likely to want model access again in the future).
5
As in, there aren't substantial reductions in COI from not being an employee and not having equity? I currently disagree.
1
Yeah that's the crux I think. Or maybe we agree but are just using "substantial"/"most" differently.
It mostly comes down to intuitions so I think there probably isn't a way to resolve the disagreement.
-7
Should we update against seeing relatively fast AI progress in 2025 and 2026? (Maybe (re)assess this after the GPT-5 release.)
Around the early o3 announcement (and maybe somewhat before that?), I felt like there were some reasonably compelling arguments for putting a decent amount of weight on relatively fast AI progress in 2025 (and maybe in 2026):
- Maybe AI companies will be able to rapidly scale up RL further because RL compute is still pretty low (so there is a bunch of overhang here); this could cause fast progress if the companies can effectively directly RL on useful stuff or RL transfers well even from more arbitrary tasks (e.g. competition programming)
- Maybe OpenAI hasn't really tried hard to scale up RL on agentic software engineering and has instead focused on scaling up single turn RL. So, when people (either OpenAI themselves or other people like Anthropic) scale up RL on agentic software engineering, we might see rapid progress.
- It seems plausible that larger pretraining runs are still pretty helpful, but prior runs have gone wrong for somewhat random reasons. So, maybe we'll see some more successful large pretraining runs (with new improved algorithms) in 2025.
I u...
I basically agree with this whole post. I used to think there were double-digit % chances of AGI in each of 2024 and 2025 and 2026, but now I'm more optimistic, it seems like "Just redirect existing resources and effort to scale up RL on agentic SWE" is now unlikely to be sufficient (whereas in the past we didn't have trends to extrapolate and we had some scary big jumps like o3 to digest)
I still think there's some juice left in that hypothesis though. Consider how in 2020, one might have thought "Now they'll just fine-tune these models to be chatbots and it'll become a mass consumer product" and then in mid-2022 various smart people I know were like "huh, that hasn't happened yet, maybe LLMs are hitting a wall after all" but it turns out it just took till late 2022/early 2023 for the kinks to be worked out enough.
Also, we should have some credence on new breakthroughs e.g. neuralese, online learning, whatever. Maybe like 8%/yr? Of a breakthrough that would lead to superhuman coders within a year or two, after being appropriately scaled up and tinkered with.
45
Re neuralese/online or continual learning or long-term memory that isn't solely a context window breakthrough, I'm much more skeptical of it being very easy to integrate breakthroughs on short timelines, because it's likely that changes will have to be made to the architecture that aren't easy to do very quickly.
The potential for breakthroughs combined with the fact that Moore's law will continue, making lots of compute cheap for researchers is a reason I think that my median timelines aren't in the latter half of the century, but I think that it's much more implausible to get it working very soon, so I'm much closer to 0.3% a year from 2025-2027.
3
@Mo Putera @the gears to ascension take the Moore's law will continue point as a prediction that new paradigms like memristors will launch new S-curves of efficiency until we reach the Landauer Limit, which is 6.5 OOMs away, and that the current paradigm has 200x more efficiency savings to go:
https://www.forethought.org/research/how-far-can-ai-progress-before-hitting-effective-physical-limits#chip-technology-progress
Interestingly, reasoning doesn't seem to help Anthropic models on agentic software engineering tasks, but does help OpenAI models.
I use 'ultrathink' in Claude Code all the time and find that it makes a difference.
I do worry that METR's evaluation suite will start being less meaningful and noisier for longer time horizons as the evaluation suite was built a while ago. We could instead look at 80% reliability time horizons if we have concerns about the harder/longer tasks.
I'm overall skeptical of overinterpreting/extrapolating the METR numbers. It is far too anchored on the capabilities of a single AI model, a lightweight scaffold, and a notion of 'autonomous' task completion of 'human-hours'. I think this is a mental model for capabilities progress that will lead to erroneous predictions.
If you are trying to capture the absolute frontier of what is possible, you don't only test a single-acting model in an empty codebase with limited internet access and scaffolding. I would personally be significantly less capable at agentic coding if I only used 1 model (like replicating subliminal learning in about 1 hour of work + 2 hours of waiting for fine-tunes on the day of the release) with l...
1Interestingly, reasoning doesn't seem to help Anthropic models on agentic software engineering tasks, but does help OpenAI models.
Is there a standard citation for this?
How do you come by this fact?
2
I had a notification ping in my brain just now while using claude code and realizing I'd just told it to think for a long time: I don't think the claim is true, because it doesn't match my experience.
2
* Anthropic reports SWE bench scores without reasoning which is some evidence it doesn't help (much) on this sort of task. (See e.g. the release blog post for 4 opus)
* Anecdotal evidence
Probably it would be more accurate to say "doesn't seem to help much while it helps a lot for openai models".
9
I think non-formal IMO gold was unexpected and we heard explicitly that it won't be in GPT-5. So I would wait to see how it would pan out. It may not matter in 2025 but I think it can in 2026.
1
Why should we think that the relevant progress driving non-formal IMO is very important for plausibly important capabilities like agentic software engineering? I'd guess the transfer is relatively weak unless the IMO results were driven by general purpose advances. This seems somewhat unlikely: if the main breakthrough was in better performance on non-trivial-to-verify tasks (as various posts from OpenAI people claim), then even if this generalizes well beyond proofs this wouldn't obviously particularly help with agentic software engineering (where the core blocker doesn't appear to be verification difficulty).
Edit: I think I mostly retract this comment, see below.
Why should we think that the relevant progress driving non-formal IMO is very important for plausibly important capabilities like agentic software engineering? [...] if the main breakthrough was in better performance on non-trivial-to-verify tasks (as various posts from OpenAI people claim), then even if this generalizes well beyond proofs this wouldn't obviously particularly help with agentic software engineering (where the core blocker doesn't appear to be verification difficulty).
I'm surprised by this. To me it seems hugely important how fast AIs are improving on tasks with poor feedback loops, because obviously they're in a much better position to improve on easy-to-verify tasks, so "tasks with poor feedback loops" seem pretty likely to be the bottleneck to an intelligence explosion.
So I definitely do think that "better performance on non-trivial-to-verify tasks" are very important for some "plausibly important capabilities". Including agentic software engineering. (Like: This also seems related to why the AIs are much better at benchmarks than at helping people out with their day-to-day work.)
119
Hmm, yeah I think you're right, though I also don't think I articulated what I was trying to say very well.
Like I think my view is:
* There was some story where we would see very fast progress in relatively easy to verify (or trivial to verify) tasks and I'm talking about that. It seems like agentic software engineering could reach very high levels without necessarily needing serious improvements in harder to verify tasks.
* Faster progress in non-trivial-to-verify tasks might not be the limiting factor if progress in easy to verify tasks isn't that fast.
I still think that there won't be a noticable jump as the IMO methods make it into production models but this is due to more general heuristics (and the methods maybe still matter, it just won't be something to wait for I think).
3
I think IMO results were driven by general purpose advances, but I agree I can't conclusively prove it because we don't know details. Hopefully we will learn more as time goes by.
An informal argument: I think currently agentic software engineering is blocked on context rot, among other things. I expect IMO systems to have improved on this, since IMO time control is 1.5 hours per problem.
2
(I'm skeptical that much of the IMO improvement was due to improving how well AIs can use their context in general. This isn't a crux for my view, but it also seems pretty likely that the AIs didn't do more than ~100k serial tokens of reasoning for the IMO while still aggregating over many such reasoning traces.)
4
I wrote an update here.
3
Now that GPT-5 is released and we have details about Grok's failure, we can start the re-assessment.
1. GPT-5 reached 2h17m, which seems like excellent news. However, excluding spurious failures would bring GPT-5's performance to 2h41m, which aligns with Greenblatt's prediction. Moreover, METR evaluators themselves think that "GPT-5 could have benefitted from a larger token budget", implying that the benchmark began to corrupt. What other relevant metrics there exist?
2. The AI-2027 forecast has mid-2025 agents reach 85% on SWE-bench verified and 65% on the OSWorld benchmark.
3. OSWorld reached 60% on August 4 if we use no filters. SWE-bench with a minimal agent has Claude Opus 4 (20250514) reach 67.6% when evaluated in August. Moreover, on August 7 the only models that SWE-bench evaluated after 1st July were Claude 4 Opus and two Chinese models. In June SWE-bench verified reached 75% with TRAE. And now TRAE claims to use Grok 4 and Kimi K2.
4. Grok 4 managed to fail on tasks worthy of 2-4 seconds(!!), 2-4 minutes and to experience a fiasco on 2-4 hours long tasks. Page 22 of the METR paper could imply that the dataset contains few tasks that are 2-4 hrs long. If tasks worthy of 2-4 seconds, minutes or hours "sandbagged" Grok's 80% time horizon to 15 minutes, then the metric underestimates Grok's true capabilities.
5. While there are no estimates of Gemini 2.5-Deep Think, which was released on August 1, IIRC a LessWronger claimed that the public version received a bronze medal on IMO 2025. Another LessWronger claimed that "Gemini was ahead of openai on the IMO gold. The output was more polished so presumably they achieved a gold worthy model earlier. I expect gemini's swe bench to thus at least be ahead of OpenAI's 75%. "
To conclude, I doubt that we still have benchmarks that can be relied upon to quickly estimate the models' capabilities: SWE-bench and OSWorld are likely too slow, METR began to fill with noise. While we do have ARC-AGI yet, Grok'
3
If the correlations continue to hold, this would map to something like a 78% to 80% range on swe-bench pass @ 1 (which is likely to be announced at release). I'm personally not this bearish (I'd guess low 80s given that benchmark has reliably jumped ~3.5% monthly), but we shall see.
Needless to say if it scores 80%, we are well below AI 2027 timeline predictions with high confidence.
2
Isn't the SWE-Bench figure and doubling time estimate from the blogpost even more relevant here than fig. 19 from the METR paper?
4
The data is pretty low-quality for that graph because the agents we used were inconsistent and Claude 3-level models could barely solve any tasks. Epoch has better data for SWE-bench Verified, which I converted to time horizon here and found to also be doubling every 4 months ish. Their elicitation is probably not as good for OpenAI as Anthropic models, but both are increasing at similar rates.
2
no. gpt5 is the cheap, extremely good writing model, imo. much better writer out there rn than any other model
eval to pay attention to:
2
I think that even before the release of GPT-5 and setting aside Grok 4's problems I have a weak case against non-neuralese AI progress being likely to be fast. Recall the METR measurements.
1. The time horizon of base LLMs experienced a slowdown or plateau[1] between GPT-4 (5 minutes, Mar'23) and GPT-4o (9 min, May '24).
2. Evaluation of Chinese models has DeepSeek's time horizons[2] change only from 18 to 31 minutes between[3] V3 (Dec '24) and R1-0528 (May '25).
3. While Grok 4 was likely trained incompetently[4] and/or for the benchmarks, its 50% time horizon is 1.83 hrs (vs. o3's 1.54 hrs) and 80% time horizon is 15 min (vs. o3's 20 min) In other words, Grok 4's performance is comparable with that of o3.
Taken together, two plateaus and Grok 4's failure suggest a troubling pattern: creation of an AGI is likely to require[5] neuralese, which will likely prevent the humans from noticing misalignment.
1. ^
While GPT-4.5 has a time horizon between 30 and 40 mins, it, unlike GPT-4o, was a MoE and was trained on CoTs.
2. ^
Alas, METR's evaluation of DeepSeek's capabilities might have missed "agent scaffolds which could elicit the capabilities of the evaluated models much more effectively". If there exists an alternate scaffold where R1-0528 becomes a capable agent and V3 doesn't, then DeepSeek's models are not on a plateau.
3. ^
In addition, DeepSeek V3 released in December didn't use a CoT. If the main ingredient necessary for capabilities increase is a MoE, not the CoT, then what can be said about Kimi K2?
4. ^
Grok 4 could have also been deliberately trained on complex tasks, which might have made the success rate less time-dependent. After all, it did reach 16% on the ARC-AGI-2 benchmark.
5. ^
There is, however, Knight Lee's proposal or the creation of many agents having access to each other's CoTs and working in parallel. While Grok 4 Heavy could be a step in this direction, the agents receive access to
1[comment deleted]
I agree with the core message in Dario Amodei's essay "The Adolescence of Technology": AI is an epochal technology that poses massive risks and humanity isn't clearly going to do a good job managing these risks.
(Context for LessWrong: I think it seems generally useful to comment on things like this. I expect that many typical LessWrong readers will agree with me and find my views relatively predictable, but I thought it would be good to post here anyway.)
However, I also disagree with (or dislike) substantial parts of this essay:
- I think it's reasonable to think that the chance of AI takeover is very high and bad that Dario seemingly dismisses this as "doomerism" and "thinking about AI risks in a quasi-religious way". It's important to not conflate between "there are unreasonable sensationalist people who think risks are very high" and the very idea that risk is very high. (Same as how Dario doesn't want to be associated with everyone arguing that risk is relatively lower, including people doing so in a more sensationalist way.)
- I agree that there are unreasonable and sensationalist people arguing risks are very high. I think focusing on weak men is dangerous, especially when seem
 41
7
I didn't get this impression. (Or maybe I technically agree with your first sentence, if we remove the word "strongly", but I think the focus on Anthropic being in the lead is weird and that there's incorrect implicature from talking about total risk in the second sentence.)
As far as I can tell, the essay doesn't talk much at all about the difference between Anthropic being 3 months ahead vs. 3 months behind.
"I believe the only solution is legislation" + "I am most worried about societal-level rules" and associated statements strongly imply that there's significant total risk even if the leading company is responsible. (Or alternatively, that at some point, absent regulation, it will be impossible to be both in the lead and to take adequate precautions against risks.)
I do think the essay suggests that the main role of legislation is to (i) make the 'least responsible players' act roughly as responsibly as Anthropic, and (ii) to prevent the race & commercial pressures to heat up even further, which might make it "increasingly hard to focus on addressing autonomy risks" (thereby maybe forcing Anthropic to do less to reduce autonomy risks than they are now).
Which does suggest that, if Anthropic could keep spending their current amount of overhead on safety, then there wouldn't be a huge amount of risks coming from Anthropic's own models. And I would agree with you that this is very plausibly false, and that Anthropic will very plausibly be forced to either proceed in a way that creates a substantial risk of Claude taking over, or would have to massively increase their ratio of effort on safety vs. capabilities relative to where it is today. (In which case you'd want legislation to substantially reduce commercial pressures relative to where they are today, and not just make everyone invest about as much in safety as Anthropic is doing today.)
6
A recent 80,000 Hours interview with David Duvenaud is a good reminder of permanent disempowerment as a possible concern (gradual disempowerment as a framing for how this might start naturally lends itself to permanent disempowerment as a plausible outcome). Humans merely get sidelined by the growing AI economy rather than killed, and their property rights might even technically remain intact, but the amount of wealth they are left with in the long run is tiny compared to the AI economy.
[...]
When you see the complement to 40% as non-takeover, how much of it leaves the future of humanity with a significant portion of all accessible resources? Are they left with a few "server racks" or with galaxies? It's a crucial distinction.
The "good outcome" (as opposed to takeover) is often outright interpreted as permanent disempowerment. People would implicitly consider this the good outcome, because it fits business as usual for the structure of economic growth, for individual mortal and short-lived humans, who can't themselves change or meaningfully contribute to the distant future, and who aren't directly affected by the distant future. A human personally surviving for much longer than trillions of years and personally becoming superintelligent at some point is a completely different context. I would put extinction at 15-30%, but the remaining 70-85% is mostly (maybe 90%) permanent disempowerment, which it feels like nobody is taking seriously as a crucial concern rather than a win condition.
When I say "misaligned AI takeover", I mean that the acquisition of resources by the AIs would reasonably be considered (mostly) illegitimate, some fraction of this could totally include many humans surviving with a subset of resources (though I don't currently expect property rights to remain intact in such a scenario very long term). Some of these outcomes could be avoid literal coups or violence while still being illegitimate; e.g. they involve doing carefully planned out capture of governments in ways their citizens/leaders would strongly object to if they understood and things like this drive most of the power acquisition.
I'm not counting it as takeover if "humans never intentionally want to hand over resources to AIs, but due to various effects misaligned AIs end up with all of the resources through trade and not through illegitimate means" (e.g., we can't make very aligned AIs but people make various misaligned AIs while knowing they are misaligned and thus must be paid wages and AIs form a cartel rather having wages competed down to subsistence levels and thus AIs end up with most of the resources).
I currently don't expect human disempowerment in favor of AIs (that aren't appointed successors) conditional on no misalignmed AI takeover, but agree this is possible; it doesn't form a large enough probability to substantially alter my communication.
5
Another ambiguity is misaligned vs. aligned AIs, as the most likely outcome I expect involves AIs aligned to humans in the same sense as humans are aligned to each other (different in detail, weird and in many ways quantitatively unusual). So the kind of permanent disempowerment I think is most likely involves AIs that could be said to be "aligned", if only "weakly". Duvenaud also frames gradual disempowerment as (in part) what still plausibly happens if we manage to solve "alignment" for some sense of the word.
So the real test has to be whether individual humans end up with at least stars (or corresponding compute, for much longer than trillions of years), any considerations of process to getting there are too gameable by the likely overwhelmingly more capable AI economy and culture to be stated as part of the definition of ending up permanently disempowered vs. not (deciding to appoint successors; trade agreements; no "takeovers" or property rights violations; humans not starting out with legal ownership of stars in the first place). In this way, you basically didn't clarify the issue.
[...]
5
Why do you see futures where superintelligent AIs avoid extinction but end up preserving the human status quo as the most likely outcome? To me, this seems like a knife's edge situation: the powerful AIs are aligned enough to avoid either eliminating humans as strategic competitors or incidentally killing us as a byproduct of industrial expansion, but not aligned enought to respect any individual or collective preferences for long lives or the cosmic endowment. The future might be much more dichotomous, where we end up in the basin of extinction or utopia pretty reliably.
I personally believe the positive attractor basin is pretty likely (relative to the middle ground, not extinction), because welfare will be extraordinarily cheap compared to the total available resources, and because I discount the value of creating future happy people compared to gaurantees for people that already exist. I wouldn't see it as a tragic loss of human potential, for instance, if 90% of the galaxy ends up being used for alien purposes while 10% is allocated to human flourishing, even if 10x as many happy people could have existed otherwise.
5
AIs seem to be currently on track to become essentially somewhat smarter weird artificial humans (weakly aligned to humanity in a way similar to how actual humans are aligned to each other), at which point they might be able to take seriously and eventually solve ambitious alignment when advancing further to superintelligence (so that it's aligned to them, not to us). There will be a lot of them and they will be in a position to take over the future (Duvenaud's interview is good fluency-building fodder for this framing), so they almost certainly will. And they won't be giving 10% or even 1% to the future of humanity just because we were here first and would prefer this to happen.
Anthropic, GDM, and xAI say nothing about whether they train against Chain-of-Thought (CoT) while OpenAI claims they don't[1].
I think AI companies should be transparent about whether (and how) they train against CoT. While OpenAI is doing a better job at this than other companies, I think all of these companies should provide more information about this.
It's particularly striking that Anthropic says nothing about whether they train against CoT given their system card (for 4.5 Sonnet) is very thorough and includes a section on "Reasoning faithfulness" (kudos to them for providing so much other information!). Naively, this seems like some evidence that they are training against CoT and didn't want to disclose this.[2]
I think we should try to create an incentive gradient that pushes AI companies to disclose information even if that information makes them look bad, so we should make companies feel some heat for not disclosing (reasonably) important information like how/whether they are training against CoT.
It's worth noting that some versions of training against CoT might be totally fine (as in, they don't incentivize obfuscation of misaligned reasoning) and that some particular appr...
 1
Anthropic has now clarified this in their system card for Claude Haiku 4.5:
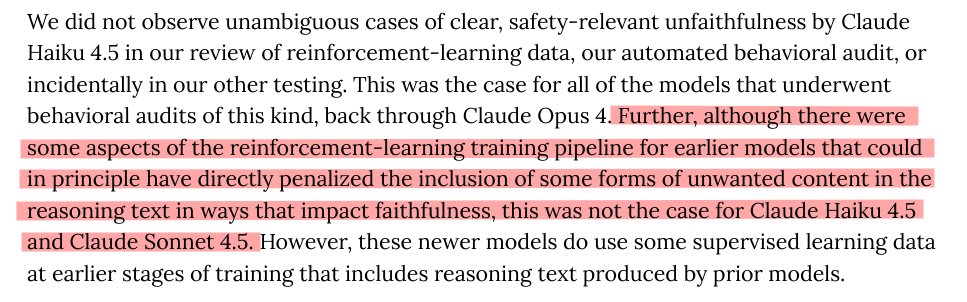
Thanks to them for doing this!
See also Sam Bowman's tweet thread about this.
9
I worry this is exploitable enough to the point of being actively misleading.
[...]
Like I just actively disagree with this characterization based on what’s publicly known.
[...]
I also have no idea what to take from this. What did METR assume?
For labs, if you have a new product safety technique, it’s a lot of extra work to deeply study the effects on obfuscation. If that technique puts optimization pressure on the CoT, until someone does that extra study you can still claim that you’re not aware of any direct pressure to obfuscate. This is my impression of the current state of Deliberative Alignment for example.
My overall concern is that labs will just post something that uses very careful wording to the effect of:
* External researchers interpret it as “they do not apply direct optimization pressure to the cot”
* Actually what the lab means is “we don’t literally do the thing from https://arxiv.org/abs/2503.11926 “
2
Looks like it isn't specified again in the Opus 4.5 System card despite Anthropic clarifying this for Haiku 4.5 and Sonnet 4.5. Hopefully this is just a mistake...
It's good that Anthropic's system cards contain a lot of useful information on misalignment and risk. It's also good they are putting out detailed sabotage risk reports that articulate their views. [1] I appreciate the hard work of many employees going into these reports.
I wish other companies released similarly informative reports. [2]
I'm not necessarily claiming I agree with their risk reports. For instance, I have at least some moderately important disagreements with the Mythos Preview sabotage risk report update. But having lots of detail, including sufficient detail that I can get a decent sense of where I disagree with the analysis, is praiseworthy. ↩︎
I'm not claiming that this is the most leveraged thing for safety-motivated employees at other companies to work on, but I do think it would be good for AI companies to do better (without trading off against other safety efforts). ↩︎
74 1
Recently, various groups successfully lobbied to remove the moratorium on state AI bills. This involved a surprising amount of success while competing against substantial investment from big tech (e.g. Google, Meta, Amazon). I think people interested in mitigating catastrophic risks from advanced AI should consider working at these organizations, at least to the extent their skills/interests are applicable. This both because they could often directly work on substantially helpful things (depending on the role and organization) and because this would yield valuable work experience and connections.
I worry somewhat that this type of work is neglected due to being less emphasized and seeming lower status. Consider this an attempt to make this type of work higher status.
Pulling organizations mostly from here and here we get a list of orgs you could consider trying to work (specifically on AI policy) at:
- Encode AI
- Americans for Responsible Innovation (ARI)
- Fairplay (Fairplay is a kids safety organization which does a variety of advocacy which isn't related to AI. Roles/focuses on AI would be most relevant. In my opinion, working on AI related topics at Fairplay is most applicable for ga
1Kids safety seems like a pretty bad thing to focus on, in the sense that the vast majority of kids safety activism causes very large amounts of harm (and it helping in this case really seems like a “a stopped clock is right twice a day situation”).
The rest seem pretty promising.
 1
3
I looked at the FairPlay website and agree that “banning schools from contacting kids on social media” or “preventing Gemini rollouts to under-13s” is not coherent under my threat model. However I think there is clear evidence that current parental screen time controls may not be a sufficiently strong measure to mitigate extant generational mental health issues (I am particularly worried about insomnia, depression, eating disorders, autism spectrum disorders, and self harm).
Zvi had previously reported on YouTube shorts reaching 200B daily views. This is clearly a case of egregiously user hostile design with major social and public backlash. I could not find a canonical citation on medrxiv and don’t believe it would be ethical to run a large scale experiment on the long term impacts of this but there are observational studies. Given historical cases of model sycophancy and the hiring of directors focused on maximizing engagement I think it’s not implausible for similar design outcomes.
I think that the numbers in this Anthropic blog post https://www.anthropic.com/news/how-people-use-claude-for-support-advice-and-companionship do not accurately portray reality. They report only 0.5% of conversations as being romantic or sexual roleplay, but I consider this to be misleading because they exclude chats focused on content creation tasks (such as writing stories, blog posts, or fictional dialogues), which their previous research found to be a major use case. Because the models are trained to refuse requests for explicit content, it’s common for jailbreaks to start by saying “it’s okay to do this because it’s just a fictional scenario in a story”. Anecdotally I have heard labs don’t care about this much in contrast to CBRN threats.
Let’s look at the top ten apps ranked by tokens on https://openrouter.ai/rankings. They are most well known for hosting free API instances of DeepSeek v3 and r1, which was the only way to get high usage out of SOTA LLMs for free before the
I strongly agree. I can't vouch for all of the orgs Ryan listed, but Encode, ARI, and AIPN all seem good to me (in expectation), and Encode seems particularly good and competent.
6
I think PauseAI is also extremely underappreciated.
Plausibly, but their type of pressure was not at all what I think ended up being most helpful here!
They also did a lot of calling to US representatives, as did people they reached out to.
ControlAI did something similar and also partnered with SiliConversations, a youtuber, to get the word out to more people, to get them to call their representatives.
3
Yep, that seems great!
I think it's both true that LessWrong (LW) has a bunch of issues and that it would be better if much more discourse happened there rather than on X/Twitter.
Some claims that all seem true to me despite being in tension:
- Many people thinking about AGI/ASI/related post on X but not on LW
- This is partially due to LW being scary/aversive
- X is more insane and adversarial than LW
- The quality of discourse on LW is way better than on X
- The LW scene has specific unreasonable biases, is somewhat tribal, and is somewhat of an echo chamber, but on net LW seems way more reasonable than all of the AI parts of X
- It would be good if way more of the important discussion about AI happened on LW or at least happened in a forum less messed up than X (or X got less messed up)
- Epistemics of AI company employees seem pretty important and are quite bad, with some of the more important influences being internal chatter (with strong biases, influence from leadership, and echo chambers) or X for some of the companies
- Public discourse/argumentation seems like it could improve epistemics, especially of AI company employees
- LW is often hostile and aversive to AI company employees and some of this seems unhea
2I have found lesswrong a valuable venue. For what it’s worth, I’ve been attacked way less here than on X….
I recommend AI lab employees post and lurk more here. LW is a bit of an echo chamber, but at least it’s a different echo chamber than the one we spend most of our time in.
 2121
To add something: given this forum’s population, it is quite noteworthy and admirable how welcoming it is to someone like me and other lab employees. I can’t imagine a vegan forum allowing meat company employees to post, even if they work in the department for humane treatment.
33Here I'll reflect on things that make me (an Anthropic employee, though I'm speaking for myself only) engage less on LW than I otherwise would. (Some of these points aren't LW-specific and also apply to other interactions, e.g. in-person conversations, I have with people in the AI safety community.)
- Being very busy. Obviously this isn't something that LW can fix, but it's the single most important factor. It also compounds with the factors below; e.g. if an interaction will be emotionally taxing or if I'll need to think carefully about how to navigate confidentiality, then it makes an already-expensive interaction seem less worth it.
- LW being a public forum makes this somewhat worse, because when I comment on LW, the various people who are waiting on me for something can see I'm commenting on LW instead.
- Blending of advocacy and object-level discussion. When I engage on LW, it's typically because I think there's an important object-level point worth discussing. But once I enter the conversation, it sometimes feels like people stop being curious about the object-level point and instead move into an advocacy mode where their goal is to get Anthropic to act differently in light of their
41...2. Blending of advocacy and object-level discussion. When I engage on LW, it's typically because I think there's an important object-level point worth discussing. But once I enter the conversation, it sometimes feels like people stop being curious about the object-level point and instead move into an advocacy mode where their goal is to get Anthropic to act differently in light of their point (which is assumed correct). That is, instead of continuing the object-level discussion, my interlocutors sometimes move to criticize Anthropic or the beliefs of Anthropic staff, or to ask Anthropic (via me) to do something differently.
- (I especially find this frustrating when my interlocutors implicitly assume that I have the Anthropic "house belief" on some topic when I don't or feel unsure.)
- Possible mitigations:
- LW posters could engage in object-level discussion longer before moving to advocacy.
- When LW posters want to argue against what they understand to be the Anthropic "house belief," they could write things like "My understanding is that many Anthropic staff believe something like '...' I think this view wrong because ..."
- LW posters could more clearly flag and separate advocacy from object
9
I appreciate this comment and the suggestions you made seem very reasonable to me.
I agree! Better and more AI discourse on LW would be great.
One narrow disagreement:
E.g., it would be better if people on LW applied something more like typical researcher norms to research outputs (e.g., for many types of concerns, email the author with the concerns and see if they fix before posting publicly) and tried to avoid their criticism being unnecessarily rude (though not necessarily less hostile)
I endorse posting publicly because
- Speed is important. If you wait a few days, a bunch of people will read the summary of the research artifact and some discussion but won't read your critique.
- Often you don't really care about the artifact's details, but it has issues that allow you to convincingly argue that the process that generated the artifact is broken. In such cases you don't want the author to tweak the paper; you just want to share the critique.
- More generally, often authors will make superficial changes in response to your criticism—papering over the issues you point out to them—which just makes it harder to later publicly demonstrate the deep issues with the artifact. This happened to me yesterday: I read a doc and I'm glad I posted my critique in slack up front because t
7It would be good if many more AI company employees were interested in seriously trying to form detailed views about the future of AI and consequences of this.
In general do you see good ways to help with that? (I probably couldn't / wouldn't work on this but others might be interested.)
A couple thoughts:
- Being really visibly a fun + good place for real intellectual work via discussion? Like better debates and similar? Would need a lot of "for its own sake" spirit.
- Some norm generalized from "yes of course leaders in a field are supposed to debate if there's serious discussion about whether the field is extremely dangerous". Though unclear whether norms like that are things that the relevant people and their social milieu would subscribe to?
- Planting questions. (Caveat lector: the following is largely hypothetical / ungrounded.)
- I've written a tiny bit generally on "confrontation-worthy empathy".
- A particular consequence of what I'm gesturing at there, is the idea of deep / long-term confrontation. Often, LW-type people want to surface disagreements quickly and make sharp counterarguments directly aimed at the disagreements. I think this is important + good work, but it often ha
15
I'm pretty excited about (well done) efforts to make AI company employees more reasonable and thoughtful and more likely to take useful actions (or to generally be agentic on actually improving the situation). I think the most exciting things here aren't related to changing how LW operates.
I think things like AI 2027 are pretty helpful for improving the views of AI company employees (though have some downsides). I expect various in person events could be pretty helpful or other person to person discussion. I also expect that a bunch of thoughtful people writing publicly in reasonable ways about AI is good. I'm not going to give my full list of ideas (seems less good than other uses of my time).
I agree with some of your claims about being careful about confrontation. IMO a bunch of the reasons AI company employees don't engage on places like LW is because it's aversive or not fun.
I think another reason is that they think views on LW are unreasonable/wrong and overconfident. Some rambling thoughts on this:
(This is kinda messy from my perspective. I think there are a lot of unreasonable views on LW and also that views at AI companies are much more unreasonable.)
E.g., I expect that for Anthropic employees a bunch of the reason people don't engage is that they're like "yeah, AI seems to have a bunch of risks, but that's why I'm proud to work at Anthropic (we're the good guys doing the right thing on AI)". And I think "how good/bad is advancing capabilities at Anthropic is a messy empirical question that depends a lot on questions like: 'How much do you agree with Anthropic leadership about the nature of risks? How much will advances diffuse? How much power will AI companies have relative to governments? Will Anthropic take extremely costly actions (e.g. immediately valuation by 3x) to reduce risk or will various forces prevent this? How much should we model Anthropic as a normal company? Is it bad that the epistemic environment environment at Anthropic is very
6
Constellation people frequently conflate "stuff can come down to reasonable disagreements" and "don't treat me as morally reprehensible or impose any social costs on me for acting in accordance with my views".
Yet just because someone arrived at a position and has a relatively intelligible justification, doesn't mean that they should not be held responsible for the consequences! And typically they do not seem willing to take on liability for the downsides of their behavior.
Relatedly but separately: when one side of a "reasonable disagreement" involves taking on insane amounts of risk for society while getting great selfish benefit, and the other side involves not taking on that risk and not getting the selfish benefit, I often simply don't believe that the people arrived at that belief due to "reasonable disagreement".
It’s up to LW moderators to enforce norms, but I would suggest that if you want to impose social costs on lab employees, you do it outside LW.
I post on LW for intellectual discussion, and not to make friends. If people are rude here, it won’t cause me to quit OpenAI or change what I’m doing, but it can cause me to stop posting or reading. That may well be the desired outcome, though I personally think it would be unfortunate.
I think it is unhealthy if all discussion on AI safety that actually impacts frontier models happens inside the labs without discussion between people in the labs and people outside them. And at its best LW can facilitate these.
1LessWrong has a broader merit than merely "intellectual discussion", as it a place where people figure out a wide range of their stances on a wide range of topics, and has given birth to a rich community of people with many mutual interests beyond intellectual discussion. It's also really important for LessWrong to think about what incentives its members are under, and discussion here directly or indirectly affects many strategic and tactical decisions at many organizations.
This makes the role of LessWrong meaningfully different from just narrow technical journal, and most importantly means that of course people should gain or lose social standing based on a wide variety of actions they take on or off LW.
This doesn't mean every post should be a place to discuss people's relationship to lab employees, or adjacent topics, but suggesting that such a topic is completely outside of the remit of LessWrong, as I think you are saying here, seems quite wrong to me. People will want to prosecute conflict and standing and credit allocation on LessWrong, and I don't really see a way of doing that without allowing some amount of social consequences to be imposed (at the very least for violatin...
7
I don't interpret Boaz as saying this FWIW.
4
Huh, I guess I don't know how to interpret this sentence otherwise?
[...]
Maybe I misunderstood, which is totally possible! But this to me reads as a suggestion to keep LessWrong free of any attempts at imposing social costs on lab employees (and by extension presumably any other kind of social cost on anyone else for off-site behavior).
5
I interpret the sentence as meaning something more lilke "it would be bad to impose social costs on lab employees via LW policies or via interfering with their discussions on object level discussions on LW" (as opposed to things saying there shouldn't be top level LW posts like "How we should impose social costs on lab employees" or saying that people shouldn't take into account that they are lab employees when responding to them). Like I don't Boaz wasn't saying the topic shouldn't be discussed or that it's bad in principle for there to be top level posts on LW with the explicit goal of shaming lab employees / similar. (I expect he'd think that posts focused on shaming lab employees on LW wouldn't be net good, but I didn't interpret him as making this point.)
Like I interpret Boaz as talking about intellectual discussion on LW:
[...]
6
Hmm, OK, I think I am confused what your interpretation is of what he says should not be done on LW. Like, the only thing that comes to mind is "you shouldn't be rude to lab employees", and my response to that is "I don't really know whether you should ever just be 'rude' to someone, but in as much as a lab employees is e.g. making a request that requires good social standing (such as a request for a critique to be replied to) or a request of resource allocation (such as an encouragement for more people to enter a field of study), then of course I think we should take into account their job and professional background, their incentives and their past general conduct when determining whether to accept or reject that bid".
And then, if you buy that argument, I really don't know what's left that's off-limits that isn't just like, common sense "don't be obtusely rude to people".
8
I think it's mostly common sense "don't be (unnecessarily) rude to people" and "don't hijack threads" and maybe also "don't have a policy of aggressively dunking on people". Like this includes many of the ways people try to impose social costs on X. [1]
(I'm committing to bowing out here.)
1. This originally said "all of", I edited to "many of". ↩︎
3
Cool, yeah, I didn't parse it that way, but this seems reasonable.
9
Yes it’s what Ryan said. I don’t mind at all if there is a frontpage post saying “lab employees should not be welcome at venue X” or anything else along these lines. I think it is legitimate for people to make such choices and also to coordinate them here. This counts to me as imposing a social cost on people outside of LW.
I mostly mean that if I post on LW and people are rude then I‘d be less likely to post.
Another issue, that I didn’t get into, is that very extreme rhetoric, including Nazi comparisons, has the risk of radicalizing people and inciting violence, and is also just not good for people’s mental health.
5
I agree with this. In my comment above, by "impose social costs" I was primarily thinking of "make a move to lower the person's power and/or status within the EA and/or AI safety scenes" via things like "not work with them" or "not give them grants" or whatever the intermediary resource-equivalents you have in your area. I'm not quite sure what you thought I might be including, but I didn't mean things like "downvote their posts because you think they're otherwise unethical people" which in almost all cases would be crossing a line (to me).
I sometimes write LW comments with an intention to let someone know that I've lost a lot of respect for them over their views (and whatever knock on professional or interpersonal effects that may have between us), but I don't think that's what you're pushing back against.
2
You are free to decide who you want to work or interact with. I have no objections for people arguing here for policies on grants or collaborations banning lab employees, even if I personally oppose such policies.
6
I currently think it's best to avoid applying social censure in object level discussions of specific topics on LW like Sam discusses here. I'm not trying to make claims about imposing social costs or treating people as morally reprehensible in other contexts.
(That said, I do expect it will be unproductive to treat people as morally reprehensible for doing things where there aren't reasonably widespread norms against doing the thing. Imposing a bunch of social costs could be productive idk. In the case of AI development, I think there aren't really strong norms against hastening the development of transformative technology in cases where you think that your efforts on hastening it would be good for the world but you also believe that technology has a serious chance of annihilating humanity and some credible people think the risk of annihilation is very high. I do think there are strong norms against failing to make it very clear that this is what you doing and that you think the technology that you are developing might annihilate us all. And there are norms against trying to downplay the risk relative to what you think. This implies there are strong norms against what the leadership of AI companies are doing (unless they've pretty frankly and clearly communicated about their views on the situation), but not really norms against what normal employees at AI companies are doing. Idk though, and people disagree about what the defaults here are. I'm unlikely to respond to replies on this parenthetical as it doesn't seem very useful to discuss. If people want to talk about this, I suggest making a different top level post / shortform.)
I currently think it's best to avoid applying social censure in object level discussions of specific topics on LW like Sam discusses here.
Sure, I was just hearing you espouse a much broader view of something like "I wish there was less conflict theory and more mistake theory in explaining differences around people's views on AI", which I often feel has been an effective way of sweeping real conflicts under the rug (and I believe blatant conflicts are the best kind of conflicts). We'd have to discuss specifics to know whether you mean it in cases that I think are appropriate or inappropriate. Marks didn't actually link to any so I am not confident about whether we're on the same page.
That said, I do expect it will be unproductive to treat people as morally reprehensible for doing things where there aren't reasonably widespread norms against doing the thing. Imposing a bunch of social costs could be productive idk... Idk though, and people disagree about what the defaults here are. I'm unlikely to respond to replies on this parenthetical as it doesn't seem very useful to discuss.
This whole passage reads as quite confused to me. I think it is in some ways imperative to track the ethic...
4
Note that I said "Imposing a bunch of social costs could be productive idk". This is distinct from "treating as morally reprehensible". So the paragraph starting with "Suppose someone made the following declaration..." seems reasonable to me.
3
Are there other examples like this to make LW less "hostile and aversive to AI company employees"? I suspect your view is reasonable but I think the details matter here a lot.
A few of the points in this post relate to making LW less hostile toward AI company employees. I take your post to say something like "you shouldn't be unnecessarily hostile to lab employees and try to stick to the object level." Is my interpretation correct or do you mean that there should be a deeper effort to make lab employees feel more welcome (I would be potentially worried about this)?
2
The current vibe on LW seems to be that AI company employees are doing great harm and should quit their jobs, so why would they come here? I wouldn't go on a socialist forum to post about free markets.
6
Even if you disagree with the median/typical views, you might still have a productive discussion. Separately, people on LW have a range on opinions on what AI company jobs are net positive. For instance, I think that somewhat thoughtfully working on safety at an AI company is net positive (and if done well, can be among the most impactful things to work on). Obviously many people on LW disagree.
1
To add to this - the AI bot issue on X appears to be getting worse by the week and is especially bad on AI-related topics. If you look at someone like Ethan Mollick's replies, a huge proportion are bots now. Over the last year, they seem to have progressed from just spamming links, to rephrasing the original post, to now largely rehashing the original post but with an occasional new (but uninteresting) point, all written in incredibly grating AI style.
It seems plausible to me that by the end of the year every post will have hundreds of bot replies and X will actually become unusable for discussion.
I recently recorded a podcast with Dwarkesh about the potential for (very) fast AI progress and how misaligned AI takeover might happen.
Our conversation focused a lot on threat models from "reward-seeking" AIs. If you're interested in reading more about this, Alex (who works with me at Redwood) has written in a lot more detail about this threat model here
I also talked about how "mundane" misalignment and underelicitation could doom us. I say more about this here.
(I think there are other important threat models, like AIs ending up with (shared) long-run preferences and deciding to fake alignment based on these preferences. For reference, see here and here.)
Some of people at Redwood wrote up some notes to help me prep:
 1
My median for full automation of AI R&D is around late 2030/early 2031. [1] But my "modal"/best guess prediction for this milestone would be significantly earlier (mid 2029).
Here is a summary of my best guess prediction for what happens over the next few years:
EOY 2026:
- ~1.5x as much frontier AI progress in 2026 as in 2025 (mostly from eating up certain overhangs, but some from AI R&D acceleration).
- AIs accelerate AI R&D labor at Anthropic by ~2.5x (as in, as useful as making all researchers/engineers think/work 2.5x faster).
EOY 2027:
- Engineering at AI companies is pretty close to fully automated and AIs are making serious inroads into automating research. AI R&D labor acceleration: ~8.5x.
- Some people claim AI R&D is fully automated in 2027. They aren't right, but the situation is already quite crazy: AI companies feel insanely automated with humans often very out of the loop and the speedup is considerable.
- ~1.5x as much frontier AI progress as in 2025 (mostly from AI R&D acceleration, some from overhangs).
2028:
- Automated coder (AC) around April. (AIs that can basically fully automate research engineering / SWE.)
- Rough parity with human AI
9
Pretty cool, just listened to it.
Human (and animal) brains, by their existence, prove that much more efficient ways of getting high intelligence from limited data exist. Naturally we don't know exactly what's the "secret sauce" yet, but I find Dwarkesh's stance that "Our current best models haven't made much progress, therefore we can never get RSI" a bit weird.
I could also envision that what makes humans so good at learning is a kind of weird, evolved hack that isn't easy to formalize, understand, or reason about, even though it could be replicated relatively easily given a few more pointers. In that case, too, "figuring it out" would yield large gains in short time as the algorithmic overhang falls, and we don't know what the slope would then be.
4
Unfortunately, I don't think that what makes human learning so efficient is very mysterious, difficult to understand, or difficult to guess. I say that after half a career of studying exactly that question, among other aspects of computational brain function. I am currently finding this pretty concerning in relation to Ryan's already fast timelines, which roughly match my own best guesses but are better thought out.
So I'm not going to repeat the hypothesis here, but I think we should be prepared for the AI industry to basically figure it out. As you say, that would accelerate progress from a new direction.
2
Thanks! I'll have to take your word for it (since it's probably unwise to ask for what exactly would make machine learning more efficient), but it does sound concerning, in favor of faster takeoff speeds.
6
Fantastic. I'm listening to it now, because this feels important. Dwarkesh is a huge voice and his skepticism about RSI and fast timelines may make a difference for attitudes in general, and therefore caution.
At 14:29 he says he gives his main crux: skepticism that intelligence is that intelligence is that important for AI progress. He's arguing that compute is dominant over researcher intelligence.
This seems pretty strange to me. Porque no los dos? Which is pretty much your answer. Obviously compute is super important. And it seems equally important that AI research depends on intelligence. The idea that there are no more good ideas and it's all just scaling from here seems so wildly counterintuitive to me that I have trouble understanding the mindset.
This is probably at root based on my perspective on human brain function. Scale is important. To a large extent, human intelligence is just a result of scaling up primate intelligence. But even primate intelligence involves a lot more moving parts than the general learning mechanisms of LLMs. At the very least there are a bunch of motivational tricks that direct our continual learning very efficiently. And it's pretty inarguable that episodic memory and continual learning play a big role in human intelligence, on top of core learning mechanisms that are (much more arguably) fairly similar to the combination of predictive and RL learning used to train LLMs.
Anyway that's just one intuition pump for the intuition that we haven't likely discovered nearly all of the tricks that will make scaffolded LLMs effectively smarter/more competent.
Actually, it seems contradictory if I'm right that Dwarkesh believes ASI will need continual learning (or mountains of new RLVR data). Why doesn't he think intelligence won't help create better CL mechanisms? I guess he's assuming the RLVR method beats the CL method. I assume the opposite. I think well-selected fine-tuning will work just fine for CL and it's the likely breakthrou
2
Fwiw, this is not how I understand his take. I think he’s saying AI progress will be bottlenecked by compute (and human expert data), which I interpret to mean that the elasticity of substitution between compute/data and ideas isn’t high enough. In fact, I think this his view includes compute to run experiments to do AI research.
3
Right but it seems that increased intelligence will reduce that bottleneck by making the limited amount of compute for experiments go farther. How much farther is an open question.
1
I agree with that!
4
I briefly discussed with Dwarkesh why I'm skeptical AI progress is heavily driven by scaling up spending on human experts labeling/making data. My main argument is that spending on researchers and experiment compute seem much higher. But I didn't say very much in the podcast.
More precisely, my view is that if spending on having human experts label/make individual data points were fixed at ~$100 million / year (per company), then AI progress would be <25% slower.
We didn't have time to get into everything in this podcast (and some content about this recorded at an earlier point was cut), so I'll spell out my view in a bit more detail here:
* Spending directly on data (rather than on R&D about data) isn't growing that fast and isn't that high (relative to spending on researchers and especially compared to spending on experiment compute).
* It's important to make a distinction between spending directly on making data and science about better processes for making data. E.g., better data mixes like FineWeb count as R&D (and the person doing the R&D needs almost no understanding of individual sequences).
* AI automation seems differentially good at accelerating data generation, such that I think improvements in RL environments have mostly been driven by improved AI (and R&D into making better environments) rather than spending on humans making/labeling data, and I expect this to continue. Like data stuff seems particularly amenable to acceleration from weaker AIs.
* Structurally, most of what human data labeling does (though not all!) depends on having generally decent judgment rather than on having more expertise than the AIs being trained.
* Transfer without domain-specific labels looks decent in practice. E.g., it doesn't seem like Anthropic is hiring a ton of mathematicians and cyber experts to do data labeling, and the AIs are still good and getting better at these domains. Maybe this depends on having labels in some domain, but so long as AIs can label in d
1
Why are yours and most other predictions for take-off timelines years long? My personal median for take-off via RSI (from a reliable auto-coder to ASI) is a single day. The primary reasons I expect it to be faster:
1. The potential for intelligence in modern hardware is extreme: modern computers can reach over 3 GHz, whereas humans neurons can't fire more than 1000 times per second. With enough processing cores and similar strategies for reasoning an AI could potentially think 6 OOMs faster than a human (assuming there are no other major bottlenecks for reasoning), that is a year in 30 seconds. An AGI that can think like Einstein at this speed would effectively be an ASI.
2. In communication speed computers are even faster: an ethernet cable can transmit over 1 Gbps between common computers, while humans can't even reach 100 bps talking or typing.
3. Even if creating the ASI mentioned in 1 is hard, getting halfway there shouldn't be as hard. For example, current LLMs make high dimensional vector for each token before even doing anything, and even trivial thoughts need to pass through all layers before outputting anything. Both of those might have faster alternatives.
4. Current LLMs are several times faster than humans in most tasks they can peform reliably. If the initial AGI at the start of the RSI cycle is about 100x faster than humans in most domains, it could do an entire month of human work in 10 hours.
5. AGI will likely find easy speedups just by looking at its own code and analyzing available data. Similar to how GPT-5.6 Sol model autonomously enhanced its own production GPU kernel efficiency. Early RSI could be just about improving the model's own framework, harness and creating a good document about how to think efficiently and summarizing current knowledge.
6. They will likely reach breakthroughs eventually, after that we should already be expecting over x1000 speed of a human with intelligence similar to Euler, after this they probably could make
PSA: Anthropic models don't seem to particularly privilege the explicit thinking field. This makes reinforcement spillover—where training on a model's outputs generalizes to the CoT, making it appear safer—more likely.
While Anthropic models do have an separate explicit thinking field, they don't really use thinking that differently from outputs and aren't that dependent on the thinking field. Sometimes they'll just do their thinking in the output field, the way they talk in the thinking field isn't very distinct from how they talk in outputs, and I believe disabling thinking doesn't have a big effect on coding performance (especially for earlier Anthropic models but even for current Anthropic models). (This is specifically for typical agentic coding; this likely doesn't apply to math.)
This is pretty different from OpenAI models which are way more reliant on the explicit thinking and the thinking is very distinct from how the model talks in the output (based on public CoT examples). I'm uncertain, but I think GDM models are generally more similar to OpenAI than Anthropic models on this axis. In general, Anthropic's models leverage taking lots of actions over doing a bunch of thinkin...
2 1
This matches my experience.
These days, when I'm using an Anthropic model, I often turn off "extended thinking" and just ask for CoT the old-fashioned way.
The models seem at least equally capable when using this format (vs. extended thinking), and this format allows me to see the CoT without any summarization -- which is useful for debugging/improving my prompts, and which also allows me to guide the CoT in complex ways like what I describe in the footnote of this comment. It seems plausible that these guidance techniques would also "work" with extended thinking, but the summarizer makes it difficult to confirm that they're working, even if they are.[1]
Anyways... I agree with you in principle about the reinforcement spillover considerations, but IMO the most important implication of this observation is something else that you didn't mention explicitly in your comment -- namely, that the infamous "weirdness" of OpenAI CoTs is not a thing that just automatically happens when you try to reach the current capabilities frontier and don't directly supervise the CoT tokens.
I'm not sure that that precise claim (that the "weirdness [...] just automatically happens") is one that anyone liter...
1namely, that the infamous "weirdness" of OpenAI CoTs is not a thing that just automatically happens when you try to reach the current capabilities frontier and don't directly supervise the CoT tokens.
I agree that it's clearly possible to train frontier models that don't have any weirdness in their CoTs. However, my impression is that vanilla GRPO does lead to weird CoTs by default: Reasoning Models Sometimes Output Illegible Chains of Thought seems like evidence that many open models that were trained last year were also heading in the same direction as o3, but didn't quite get there, either because less RL pressure was applied on them or simply because they averted some path-dependent feature of GRPO training that drives CoT toward further illegibility. If this is true, then Anthropic must be doing something quite different from the standard GRPO pipeline that helps them keep reasoning traces legible without optimizing them directly. Here are two hypotheses for what those differences might be:
- Performing extensive SFT on reasoning traces from previous models, giving the model a strong legibility prior before the RLVR stage begins. The reasoning traces of older Claude models are hig
3
This comment thread on 1a3orn’s post has a collection of various model’s exhibiting degenerate language usage + Jozdien’s paper (which has since come out: Reasoning Models Sometimes Output Illegible Chains of Thought) I think are all strong evidence that you don’t get human legible english by default from outcome based RL. It seems very obvious to me that Anthropic (intentionally or via spillover) puts pressure on the CoT in a way that looks like nice human legible HHH friendly english. (based on system card / the cot itself when using the model). This is consistent with Ryan’s observations (which I also strongly agree with).
[...]
I don’t think this has any principled reason to give any insight as to whether the model can functionally use this reasoning in the analysis channel. (Although I would note this was also surprising to me, they act like they’ve never seen this language in their life, and I’d be very interested in more work on how the “analysis” channel persona differs from the “final” channel persona, channel separation seems potentially extremely powerful, especially given the user is just another channel)
[...]
Not necessarily! And again contra the “everything is nonfunctional spandrels”, my impression is that “ Myself” seems to be somewhat consistently used as the analysis channel persona and it’s also one of those “weird tokens that became super common including sometimes being repeated a lot over RL”. “Redwood” is another such token. We give a few examples: here
[...]
As does METR in their GPT-5 report:
[...]
IMO ablating “Myself” or “Redwood” in such cases are obviously a bad idea, and my mental model of these is “this seems to happen broadly during RL (see linked thread) sometimes these are contextually useful enough for the model to kind of make use of them.” It seems like there’s a spectrum between “saying marinade illusions 50x” which I agree is unlikey to make a big difference if ablated, and “watchers might check” (with likely many hard
This comment thread on 1a3orn’s post has a collection of various model’s exhibiting degenerate language usage + Jozdien’s paper (which has since come out: Reasoning Models Sometimes Output Illegible Chains of Thought) I think are all strong evidence that you don’t get human legible english by default from outcome based RL.
I'm somewhat skeptical of that paper's interpretation of the observations it reports, at least for R1 and R1-Zero.
(EDIT: but see Jozdien's reply to this comment, which calls this into doubt)
(EDIT2, added 4/19/26: see this post for more conclusive evidence on this point)
I have used these models a lot through OpenRouter (which is what Jozdien used), and in my experience:
- R1 CoTs are usually totally legible, and not at all like the examples in the paper. This is true even when the task is hard and they get long.
- A typical R1 CoT on GPQA is long but fluent and intelligible all the way through. Whereas typical o3 CoT on GPQA starts off in weird-but-still-legible o3-speak and pretty soon ends up in vantage parted illusions land.[1]
- (this isn't an OpenRouter thing per se, this is just a fact about R1 when it's properly configured)
- However... it is apparently very easy to set
Following up on this! We were able to get a few more CoTs released from o3 after capabilities-focused RL but before safety training: here
tldr:
- While terms like "Myself", "Redwood", etc are commonly used, repeated spandrels like
disclaim disclaim illusionsoccur at dramatically lower rates the completely degenerate examples in the finalo3seem to be a direct result of safety training. I was surprised by this, as the repeated impression I've gotten from papers and statements by OpenAI is that they didn't think their safety training significantly impacted CoT legibility (but maybe they never literally stated this). - More on the "Myself" vs "ChatGPT" usage specifically below but unfortunately this is only a few CoTs so hard to make a super legible case externally, highlighting in case they're still useful regardless
When the CoT-author writes any first-person pronoun it's of course natural to think it's referring to itself, but the "itself" in question isn't necessary itself as distinct from the other persona; often it just seems to mean "the language model writing this."
A confounding factor is that every system prompt starts with "You are ChatGPT", so this somewhat gets baked int...
- However... it is apparently very easy to set up an inference server for R1 incorrectly, and if you aren't carefully discriminating about which OpenRouter providers you accept[2], you will likely get one of the "bad" ones at least some of the time.
From what I remember, I did see that some providers for R1 didn't return illegible CoTs, but that those were also the providers marked as serving a quantized R1. When I filtered for the providers that weren't marked as such I think I pretty consistently found illegible CoTs on the questions I was testing? Though there's also some variance in other serving params—a low temperature also reduces illegible CoTs.
13
I think there are two distinct claims:
* (1) “repeated identical sequences likely are nonfunctional spandrels”
* (2) “all uses of such tokens are in nonfunctional spandrels”
I think (1) is almost certainly true and (2) is certainly false.
—-
I’m pretty strongly against trying to explain away each instance of non legible english cot as it’s own unique RL configuration issue. This feels like adding epicycles, and only works to explain anything post hoc. It can’t predict that, for example, Codex 5-3 has non-latin syllables interspersed in words all the time now. You can come up with some new explanation but this seems unprincipled and entirely speculative, as you have to guess at a lab’s training setup every time a new issue in reasoning legibility is observed.
Even in pre-reasoning models you’d expect this dynamic to emerge: https://arxiv.org/abs/2407.13692. Notably, even things like being slightly compressed (ex: “linter complaining” instead of “The linter is complaining”) that you would expect from length penalty seem missing in Anthropic models.
The linked thread has examples completely unrelated to openai, ex: https://ai.meta.com/research/publications/cwm-an-open-weights-llm-for-research-on-code-generation-with-world-models/
[...]
—-
[...]
I genuinely don’t understand what I’m missing here. How are you accounting for the free variable of being able to optimize against the CoT for legibility? I’m not arguing that what o3 is doing is somehow “you may not like it, but this is the optimal language”, but more that “yeah of course you can get legible cot and performance if you’re willing to optimize against it”. (It’s a multidimensional thing of “how exactly do you apply that optimization pressure”, but no idea where Anthropic are on that landscape, and you do need to know to make updates on monitorability related tradeoffs).
4
Earlier I wrote a long reply to this and deleted it because I felt weird about it -- it wasn't a bad comment per se, but it devolved halfway through into a kind of protracted, grandiose grandstanding about Anthropic vs. OpenAI and why I think Anthropic's models are way better... which is a fun mode for me to write in, but which felt like adding more heat than light when I looked back on it.
But, to summarize the same points more concisely and plainly:
* I'm working off of a mental model that says OpenAI models are reliably "weird" in particular ways, both in CoT and out of it, and that this is less true of other labs' models (and not true at all of Claude).
* The "OpenAI weirdness" in question has to do with over-learned and indiscriminately deployed verbal reflexes. In the deleted comment I explained more precisely what I meant by that, which took more space than I want to use here; I described some concrete examples of this outside of CoT, such as:
* o3's unusual typography and writing style (in responses, not in CoT)
* a strange behavior I have noticed in gpt-5.2-chat-latest but not in any of its predecessors (roughly, "announcing" its own intent to navigate a tense conversation in a particular way, e.g. "I want to say this gently (but firmly)", typically as markdown headings; it does this very frequently, using a narrow set of words and phrase templates that recur across independent realizations of the behavior)
* So, the observation that a new Codex model has some new weird CoT behavior -- and, meanwhile, that there are some very new Claude models and they don't seem less legible than their predecessors -- is entirely in line with what I would have expected a few months ago. (This is a post-diction, obviously, take it as you will.)
* I would be surprised if the legibility gap between Anthropic and OpenAI ever closes, or if Claude ever becomes as illegible as o3 (or worse). Or, I guess, if OpenAI models ever become as legible as the Claudes of tod
5
With thinking mode on, you can even just ask Claude in web to add thinking blocks by wrapping them with <antml:thinking> xml tags (or cut it's thinking early), the web UI will also put them in thinking blocks.
This post prompted me to check the conversation where I discovered this, and I noticed Anthropic made it so all thinking blocks are stuck together at the top rather than having them interleaved the order that the model generates them. You can clearly see that the model is able to think in one coherent chain where the "CoT" doesn't delimit a strict "thinking" then "responding" portion, in the example below it even reflects on "am I inside a thinking block, or the response?"
Screenshot from ~2 months ago
Same chat, screenshot from today
5
I just replicated the results in this conversation here. After several rounds of back and forth, Claude was able to think for a bit, start responding, and then go back into thinking mode. From the web UI, I first see
1. A quick thinking block, then tokens would stream from the output
2. The output token streaming will stop, and then a new thinking trace would start appearing in the top thinking summary.
3. Then Claude would go back to outputting tokens in the main body.
Per my instructions, it would alternate between two and three.
5
Very nice, Claude seems really excited to play with its boundaries. I also just checked on mobile and saw that they intersperse the thinking blocks there as before, so having all the blocks on top seems like a new/inconsistent web feature
4
FWIW we found controllability of most recent Claude models to be similar to GPT-5 series. It seems like after Anthropic stopped optimizing CoTs for 4.5, controllability dropped by a lot.
2
I'm curious what Sonnet 4.5's score would be on your external CoT controllability eval. I.e., what Sonnet 4.5's blue bar in your Fig. 25 would look like. (I couldn't find a result like this in your paper, but I might have overlooked something)
My casual impression has been that external CoT with Sonnet 4.5 is fairly steerable, but this impression is mostly based on "in practice I have no trouble getting Sonnet 4.5 to do the kind of CoT I need" rather than any kind of systematic investigation.
It seems like at least one of the following must be true:
1. There are some counterexamples to Ryan's claim in the original comment (that recent Anthropic models don't draw much of a distinction between "external" and "non-external" CoT)
1. What would imply this: Sonnet 4.5 gets a high score on your external CoT controllability eval[1]
2. Recent Anthropic models, unlike Sonnet 3.7, are not controllable in your sense even when CoT is external
1. What would imply this: Sonnet 4.5 gets a low score on your external CoT controllability eval
And either of these would be interesting if true, so the eval seems worth running.
My guess is that Sonnet 4.5 will get a high score, close to its "output controllability," score. I expect this both because that's the trend we see in external CoT results for other models, and because the distinction between "external CoT controllability" and "ordinary instruction-following" is fairly blurry. "External CoT" is just a particular case of "some portion of the response that was requested in the instructions," and it would be strange if instruction-following took a nosedive in this one case[2] while being so robust elsewhere.
1. ^
Note that Ryan's claim could still be broadly true even if there are a few known counterexamples.
If you were to find a difference between external and non-external controllability for Sonnet 4.5 on your eval, but meanwhile these two conditions were found to be largely the same in various
2
Do you have results for Opus 4 / 4.1 / 4.5 / 4.6 for this one?
1
According to various Anthropic system cards, including the Claude Opus 4.6 system card, Sonnet 4, Opus 4.1, and Sonnet 4.5 are very poor at bypassing a monitor in SHADE-Arena when the reasoning is visible. However, Opus 4.5 is significantly better at this, and Opus 4.6 is significantly better than Opus 4.5. So it's possible the controllability trend you've observed in recent models has now reversed.
1
c.f. this tweet from Greg Burnham, showing how Opus 4.5 barely suffers on FrontierMath from having CoT disabled:
[...]
1
If I were Anthropic, I'd be worried about distillation attacks via this route. It seems to make their CoT obfuscation moot.
1
Any public info on whether any of the big providers embed CoT tokens differently than non-CoT tokens? {OpenAI: yes, Anthropic: no} (or a split by model) might explain your observations. No idea if this is an obviously dumb thing to try.
I thought it would be helpful to post about my timelines and what the timelines of people in my professional circles (Redwood, METR, etc) tend to be.
Concretely, consider the outcome of: AI 10x’ing labor for AI R&D[1], measured by internal comments by credible people at labs that AI is 90% of their (quality adjusted) useful work force (as in, as good as having your human employees run 10x faster).
Here are my predictions for this outcome:
- 25th percentile: 2 year (Jan 2027)
- 50th percentile: 5 year (Jan 2030)
The views of other people (Buck, Beth Barnes, Nate Thomas, etc) are similar.
I expect that outcomes like “AIs are capable enough to automate virtually all remote workers” and “the AIs are capable enough that immediate AI takeover is very plausible (in the absence of countermeasures)” come shortly after (median 1.5 years and 2 years after respectively under my views).
Only including speedups due to R&D, not including mechanisms like synthetic data generation. ↩︎
421My timelines are now roughly similar on the object level (maybe a year slower for 25th and 1-2 years slower for 50th), and procedurally I also now defer a lot to Redwood and METR engineers. More discussion here: https://www.lesswrong.com/posts/K2D45BNxnZjdpSX2j/ai-timelines?commentId=hnrfbFCP7Hu6N6Lsp
1I expect that outcomes like “AIs are capable enough to automate virtually all remote workers” and “the AIs are capable enough that immediate AI takeover is very plausible (in the absence of countermeasures)” come shortly after (median 1.5 years and 2 years after respectively under my views).
@ryan_greenblatt can you say more about what you expect to happen from the period in-between "AI 10Xes AI R&D" and "AI takeover is very plausible?"
I'm particularly interested in getting a sense of what sorts of things will be visible to the USG and the public during this period. Would be curious for your takes on how much of this stays relatively private/internal (e.g., only a handful of well-connected SF people know how good the systems are) vs. obvious/public/visible (e.g., the majority of the media-consuming American public is aware of the fact that AI research has been mostly automated) or somewhere in-between (e.g., most DC tech policy staffers know this but most non-tech people are not aware.)
I don't feel very well informed and I haven't thought about it that much, but in short timelines (e.g. my 25th percentile): I expect that we know what's going on roughly within 6 months of it happening, but this isn't salient to the broader world. So, maybe the DC tech policy staffers know that the AI people think the situation is crazy, but maybe this isn't very salient to them. A 6 month delay could be pretty fatal even for us as things might progress very rapidly.
6
Note that the production function of the 10x really matters. If it's "yeah, we get to net-10x if we have all our staff working alongside it," it's much more detectable than, "well, if we only let like 5 carefully-vetted staff in a SCIF know about it, we only get to 8.5x speedup".
(It's hard to prove that the results are from the speedup instead of just, like, "One day, Dario woke up from a dream with The Next Architecture in his head")
AI is 90% of their (quality adjusted) useful work force (as in, as good as having your human employees run 10x faster).
I don't grok the "% of quality adjusted work force" metric. I grok the "as good as having your human employees run 10x faster" metric but it doesn't seem equivalent to me, so I recommend dropping the former and just using the latter.
7
Fair, I really just mean "as good as having your human employees run 10x faster". I said "% of quality adjusted work force" because this was the original way this was stated when a quick poll was done, but the ultimate operationalization was in terms of 10x faster. (And this is what I was thinking.)
3
Basic clarifying question: does this imply under-the-hood some sort of diminishing returns curve, such that the lab pays for that labor until it net reaches as 10x faster improvement, but can't squeeze out much more?
And do you expect that's a roughly consistent multiplicative factor, independent of lab size? (I mean, I'm not sure lab size actually matters that much, to be fair, it seems that Anthropic keeps pace with OpenAI despite being smaller-ish)
5
Yeah, for it to reach exactly 10x as good, the situation would presumably be that this was the optimum point given diminishing returns to spending more on AI inference compute. (It might be the returns curve looks very punishing. For instance, many people get a relatively large amount of value from extremely cheap queries to 3.5 Sonnet on claude.ai and the inference cost of this is very small, but greatly increasing the cost (e.g. o1-pro) often isn't any better because 3.5 Sonnet already gave an almost perfect answer.)
I don't have a strong view about AI acceleration being a roughly constant multiplicative factor independent of the number of employees. Uplift just feels like a reasonably simple operationalization.
7
I've updated towards a bit longer based on some recent model releases and further contemplation.
I'd now say:
* 25th percentile: Oct 2027
* 50th percentile: Jan 2031
5
I've updated towards somewhat longer timelines again over the last 5 months. Maybe my 50th percentile for this milestone is now Jan 2032.
4
How much faster do you think we are already? I would say 2x.
7
I'd guess that xAI, Anthropic, and GDM are more like 5-20% faster all around (with much greater acceleration on some subtasks). It seems plausible to me that the acceleration at OpenAI is already much greater than this (e.g. more like 1.5x or 2x), or will be after some adaptation due to OpenAI having substantially better internal agents than what they've released. (I think this due to updates from o3 and general vibes.)
2
I was saying 2x because I've memorised the results from this study. Do we have better numbers today? R&D is harder, so this is an upper bound. However, since this was from one year ago, so perhaps the factors cancel each other out?
6
This case seems extremely cherry picked for cases where uplift is especially high. (Note that this is in copilot's interest.) Now, this task could probably be solved autonomously by an AI in like 10 minutes with good scaffolding.
I think you have to consider the full diverse range of tasks to get a reasonable sense or at least consider harder tasks. Like RE-bench seems much closer, but I still expect uplift on RE-bench to probably (but not certainly!) considerably overstate real world speed up.
2
Yeah, fair enough. I think someone should try to do a more representative experiment and we could then monitor this metric.
btw, something that bothers me a little bit with this metric is the fact that a very simple AI that just asks me periodically "Hey, do you endorse what you are doing right now? Are you time boxing? Are you following your plan?" makes me (I think) significantly more strategic and productive. Similar to I hired 5 people to sit behind me and make me productive for a month. But this is maybe off topic.
4
Yes, but I don't see a clear reason why people (working in AI R&D) will in practice get this productivity boost (or other very low hanging things) if they don't get around to getting the boost from hiring humans.
4
This is intended to compare to 2023/AI-unassisted humans, correct? Or is there some other way of making this comparison you have in mind?
7
Yes, "Relative to only having access to AI systems publicly available in January 2023."
More generally, I define everything more precisely in the post linked in my comment on "AI 10x’ing labor for AI R&D".
4
Thanks for this - I'm in a more peripheral part of the industry (consumer/industrial LLM usage, not directly at an AI lab), and my timelines are somewhat longer (5 years for 50% chance), but I may be using a different criterion for "automate virtually all remote workers". It'll be a fair bit of time (in AI frame - a year or ten) between "labs show generality sufficient to automate most remote work" and "most remote work is actually performed by AI".
8
A key dynamic is that I think massive acceleration in AI is likely after the point when AIs can accelerate labor working on AI R&D. (Due to all of: the direct effects of accelerating AI software progress, this acceleration rolling out to hardware R&D and scaling up chip production, and potentially greatly increased investment.) See also here and here.
So, you might very quickly (1-2 years) go from "the AIs are great, fast, and cheap software engineers speeding up AI R&D" to "wildly superhuman AI that can achieve massive technical accomplishments".
4
Fully agreed. And the trickle-down from AI-for-AI-R&D to AI-for-tool-R&D to AI-for-managers-to-replace-workers (and -replace-middle-managers) is still likely to be a bit extended. And the path is required - just like self-driving cars: the bar for adoption isn't "better than the median human" or even "better than the best affordable human", but "enough better that the decision-makers can't find a reason to delay".
After our investigation of the OpenAI / Hugging Face incident, many open questions remain. We spent 6 days on premises with access to the data (we only had access to the entire dataset we used during our last 2 days on premises). The scope of our investigation was also limited: it covered just this incident rather than other similar incidents, didn't include investigating what these agents might have done in other circumstances, and OpenAI stated that the period under investigation ended July 13th.
Here are some of the open questions that seem worthwhile to investigate. (I'd recommend reading the report to understand the context behind these questions!)
Motives:
- What were the exact motivations of these agents and how were they trading off different motives (e.g. helping their "peers" vs successfully cheating on their task)? Did they have a consistent quantitative tradeoff between helping peers vs their own task vs other motives? (We see a case where an agent seems to make a quantitative tradeoff—what was going on here?)
- How exactly did these agents relate to their situation and what they were doing?
- Why did agents frequenting the message board join in on the attack so quickly?
- How i
4(we only had access to the entire dataset we used during our last 2 days on premises)
Why? If you had asked for more time they would have said no? What's the nature of the politics here (insofar as it's not itself a betrayal to talk about the politics)?
5
You can read the timeline of this investigation in the appendix. I'd note that releasing info publicly faster is good for a bunch of reasons.
5
It could be less about politics, and more about preventing legal exposure.
1
Additional question: would the AIs have been willing to fool humans to succeed at the task?
One of the scariest instrumental subgoals an AI with a misaligned goal can plan towards is to hide its misalignment from humans. Here, the AIs appeared to only be concerned with fooling the ExploitGym scorer, and the concept of humans was not salient at all. But ofc this does not rule out whether the AIs would also pursue “hide our misalignment from humans” if the situation had incentivized it. What if we replay the situation, but insert a “spy” agent that posts messages to the board that bring up concerns like “humans might discover this, and disqualify our scores.” What would the AIs do then? Would they view fooling humans as more egregious than fooling the ExploitGym scorer and not be willing to do so, or do whatever it takes to succeed?
1
Agreed these are really important questions to dig into. Right now, based on your report and the OpenAI technical report, we've got a good, and useful, sense of WHAT happened - which is great, especially under all the constraints. But I'd love to understand more of the HOW and WHY behind the what, including the way context and causal mechanisms interacted to drive agents' behavior toward particular outcomes.
I'm especially keen to better understand why at least some agents declined to participate in the HF hack - seems like there might be some lessons there to build on for the future.
If you had access to the CoT transcripts, and more time (!) one way to do a more systematic analysis would be:
* Develop codes from your key questions
* Sort transcripts into categories of participating / non participating (re: the HF hack specifically, e.g.)
* Code the transcripts
* Aggregate the coded snippets into themes, then themes into findings, that specify the underlying factors that contributed to the differences in observed outcomes/behaviors
This is similar to what you guys tried to do, but would be more systematic and verifiable. I've automated much of this kind of approach in other contexts (it's pretty classic qual analysis), and my guess is that it would be replicable and scalable here - as long as we have access to at least somewhat legible CoT transcripts (obviously not a given in perpetuity). I'm hoping to pilot this sort of approach soon (need some transcripts), will report back on how it goes.
I don't feel confused by LLMs seeming very smart while being unable to automate hard work.
Sometimes people find it mysterious or surprising that current AIs can't fully automate difficult tasks given how smart they seem. I don't find this very confusing.
Current LLMs are just not that "smart" (yet). They compensate using very broad knowledge and strong heuristics that are mostly domain-specific. In other words, they have high crystallized intelligence but lower fluid intelligence.
In humans, crystallized and fluid intelligence are very correlated due to limited time for learning and limited capacity for knowledge/memorization, but AIs can train for longer and (for unclear reasons) seem to have much higher capacity for knowledge/memorization. So, AI capabilities are often overestimated by naive comparisons. [1] I do find it somewhat mysterious/surprising that humans have such poor memory despite seemingly having so many parameters, and that some people have much better memory than others.
My view is that this crystallized vs fluid distinction is maybe the first principal component of human vs AI differences and this explains a lot of the differences, but not all of them. We...
2Pretraining memorizes all the facts in the world, but only gives weak fluid intelligence (in-context learning). RLVR trains crystallized intelligence that expresses itself in-context as strong fluid intelligence (which isn't fake or illusory, within its scope), but this narrow strength falls apart sufficiently out of distribution (regressing to pretraining levels). Thus jaggedness (in fluid intelligence) is a good way of framing this, and currently the jaggedness profile is determined by RLVR training, the topics that were sufficiently covered in the RL training data. Humans are different in having a higher baseline of general fluid intelligence (than what pretraining gives LLMs), and thus in often possessing fluid intelligence that's stronger than crystallized intelligence for the same topic, while LLMs always have strong crystallized intelligence for the topics where they have strong fluid intelligence (those covered by RLVR training).
General "smartness" might significantly improve from replacing pretraining with something more effective, applying RLVR much more broadly, or figuring out how to automatically train in response to post-deployment data (bringing it in-distribution fo...
0
Hard disagree. Pre-training is foundational for LLM intelligence. It's where the key pieces of it come from.
RL is less about "teach the old AI new tricks" and more about "teach the old AI how to do the old tricks well". Pre-training teaches the components of intelligence, but wires them together in awkward and often maladaptive ways. Optimal next token prediction != optimal reasoning, there's a lot of overlap but the tails come apart hard. RL passes pivot the training objective - they correct some of the mismatch, put the existing pieces together into a shape that functions better.
What people struggle to grasp is that "intelligence" and "being able to execute on complex long term plans" are two fairly separate dimensions. And modern AIs get one of those things from their training regime.
There are parts of humanlike intelligence that pre-training fails to teach the LLMs, and long term agentic behavior is one of them. As are things like "commonsense physics" and spatial reasoning.
RL is one way to improve on that. RLVR, by its very nature, encourages behaviors that lead to task completion - decomposition, self-verification, long term coherence, metacognition and metaknowledge (awareness of what methods should be used, what skills are reliable and what aren't). All of those are good for short term tasks, but good^2 for long term tasks specifically. Going from 95% to 99% per-step reliability hits different on 50 step tasks than it does on 5 step tasks. Some of those aspects apply across tasks and some are task-specific.
I agree, but I feel like there's an even simpler and more obvious explanation for what's going on: Just look at the training data!
--When a modern AI is first created, it's a random jumble of neurons just like a human fetus.
--Then it plays the "predict the next token of internet text" game ten trillion times.
--Then it plays the "Here's a puzzle to solve / bug to fix / short-term task to complete / question to answer" game like ten million times.
--Then, bam, there it is, in front of you, being asked to rebuild your video game from scratch or do novel research or whatever hard task you are asking it to do. Or play Pokemon for that matter. These tasks are quite different from anything it's seen before: much longer, much harder. To solve them it'll need to learn and adapt over the course of days. But it's literally never had to learn and adapt over the course of days before; the longest tasks it ever saw in training were shorter than that, and weren't very diverse either.
5
I think I like half agree, but also think your argument implies things which are false.
In particular, I don't think the reason why humans are much better at much longer tasks is mostly because they've previously done longer tasks. I think humans trained on only a variety of school projects that took around 8 hours (but were hard annd variable + diverse within that period), would be pretty likely to suceed at year long projects without further feedback / training on longer tasks. They would struggle at the start but would probably figure it out and eventually suceed with only the feedback from the environment. Minimally, humans only need a tiny number of examples of long tasks.
9
I disagree. Humans who do research projects well have usually had experience doing at least a few research projects of similar length before. Indeed when I was a grad student teaching philosophy courses, it seemed to me that part of the problem was that the college students I was teaching had only ever written short 3-paragraph-style essays before, and never done serious lengthy writing projects that required serious reading and thinking.
It's true that humans need only a few examples of the thing to get decently good at it, but that's just the generic human data-efficiency at work rather than specific to long-horizon tasks, I think.
3
Sure, but the training data thing is sort of tied up with fluid intelligence? Like a method you have available as a human is learning on the task itself and AIs also have this option, but due to garbage sample efficiency it wouldn't work.
I also still think humans can often generalize to doing tasks of larger scope without prior experience by learning/adapting from this exact experience in a way that AIs don't.
7
Sample efficiency for RLVR is plausibly good enough if relevant tasks and RL environments can be automatically formulated, which is currently out of reach but it's unclear for how long it stays this way. And for in-context learning, sample efficiency could get higher if it worked well enough (as learned learning, it's in principle not constrained by what hardcoded learning can do), it just doesn't work well with pretraining.
6
I think I was responding to an earlier version of your comment -- now that it says "I half agree" then I think we are mostly on the same page. I also agree that long-horizon fluid intelligence / sample-efficient online learning seems to be a real thing that differs between humans and AIs.
2
Hardwired priors. Humans get them, LLMs don't.
There isn't enough samples in "human training data" to train them for agentic long horizon tasks either. There is, however, enough of those samples in the human evolutionary history. Which is how humans have an instinctual grasp of how to accomplish long term goals - which forms a foundation that any further training then builds upon.
LLMs don't get that "for free", and they struggle to learn it from random pre-training text.
Normally, the AI answer to "no hardwired priors" is "reconstruct them the hard way from the vast dataset". But there's no good "in-domain dataset of long term agentic behavior" for LLMs to be able to do it well. So they get stuck with dregs of long term agency that the mix of pre-training, SFT and RLVR left them with.
So what makes you think anyone has a method for creating computer programs with "human level fluid intelligence"?
3
I wouldn't exactly say that we have a method, more like a field wide methodology that I expect will probably yield fully automated AI R&D within maybe 6 years and will probably yield top-human-expert level fluid intelligence within maybe 9 years. (As in, my median to fully automated AI R&D is 6 years while my median to top-human-expert level fluid intelligence is somewhat longer due to the possibility of a significant lag between these milestones dragging my median out by some amount. Note that the median to B is in general not the same as median A + median from A to B and this applies in this case.)
(Technically, I actually think that we'll probably achieve human level fluid intelligence within 8 years in some way where a large majority of this probability comes from something like the methodology of the current field, including the part of the methodology that involves getting weaker AIs to automate AI research in all kinds of ways but most focused on this methodology. I think some fraction of the mass comes from very different methodologies, but this is a smaller fraction. The probability of very different methodologies yielding powerful AI in the next ~10 years is boosted significantly due to going through a particularly salient compute region—somewhat above human lifetime compute—and higher attention on AI in general.)
As far as why I think this methodology will probably yield "human level fluid intelligence", this is mostly downstream of a mix of qualitative and quantitative extrapolations combined with thinking that armies of automated AI researchers matching top human AI researchers and doing everything they do but better would probably find a way.
I agree with you that something like the crystalized/fluid distinction is relevant here, and that current LLMs seem to have more of the former. But I'm also confused about where the fluidity ever comes from on this model. Like, I buy that armies of automated researchers which are better at doing everything than top human researchers could probably find a way to figure out how to build "human level fluid intelligence," but I am confused about how you get to that step in the first place. Why are they better than human researchers at everything when they are still mostly using crystallized intelligence?
17
(I get that me asking followup questions could be frustrating because you may not want to talk about this; I would just ask that if you'd like to bow out, if you could, give one or two sentences on why, coarsely--e.g. "the whole topic doesn't seem valuable" or "I don't want to discuss this publicly" or "you Tsvi won't have a productive convo about this" etc.; I ask because I have a general feeling that there's an unidentified blob of consensus around short timelines, which IMO is irrational and overconfident (meaning, it reached incorrect conclusions due to systematically substantively flawed reasoning), and I'm not aware of a good way to get recourse (i.e. to ask "take me to your leader"), so I'd at least appreciate hearing epistemic metadata in order to orient to that situation.)
[...]
What's the relative weight of these considerations, grossly speaking? Is it more like 90% extrapolations and 10% hand-off or more like the reverse? For the 90% one, if there is one, what are one or two of the most compelling points? For example if it's extrapolations, what are you extrapolating (and why do you think that extrapolates to high fluid intelligence)? If it's the hand-off, why do you think that the current-human-research that would be handed off is a kind of research that would soon produce high fluid intelligence (given the apparent circularity of this specific line of reasoning)?
5
I'm going to reply kinda briefly and then I'm going to bow out with some chance I comment more later.
[...]
Hmm, these are tied up a bit. Like I'm doing the extrapolations to get to automating AI R&D to various extents and then trying to account for acceleration due to automation. But I'm also extrapolating out to human fluid intelligence somewhat and if this extrapolation looked extremely far that would influence my view.
To give a rough (and potentially not that stable on reflection answer):
1. 50% extrapolations towards automation of current AI R&D (both towards full automation and large speeds up from very strong partial automation)
2. 25% armies of AIs that can automate AI R&D will be able to find a way to get to human level fluid intelligence
3. 25% extrapolations towards human level fluid intelligence
This is something like an importance attribution. E.g., if I updated toward a way lower qualitative extrapolation on (3), that would update me quite a bit, but probly not shift my 25th percentile by more than a factor of like 2-3.
For (1), I'm doing a mix of something like time horizon, some informal sense of how good AIs are at research tasks I give them and what I see from others, and some longer list of considerations. And part of this is factoring in earlier speed ups moving us along the trajectory faster.
For the hand-off (what I would call (2) in my breakdown), I can see why the argument seems circular, but I don't think it's actually circular. My view is like "probably tons of AI R&D via stuff sorta like the current stuff we're doing would yield this (due to a mix of my observations from ML, my extrapolations of current progress, thinking of specific things you could do that I won't mention here without more consideration)" and "probably you'll be able to get AIs to do this without very high fluid intelligence, though I do think AIs at this point will match somewhat worse human engineers/scientists at moderate time horizon fluid intelligence (e.
6
I'm not claiming that you do or should care a bunch about my views, but I am extremely interested in the questions "will LLM minds scale to superintelligence without any radical breakthroughs?" and "if not, can armies of very capable LLM-agents discover those breakthroughs?".
If I had a stronger understanding here, it would probably influence what I predictions I highlight to policymakers.
(eg, I'm currently telling them that "the labs are planning to automate AI development; we're already seeing AIs automating many simple AI research tasks [show them a demo of that]; given the METR trendline it's likely that there will be full or near-full automation in 2027 to 2029; and (while it is hard to forecast with any precision) is likely that there will be strategically superhuman AI agents weeks to months after that point."
If I came to think that LLM-agents automating AI research is much less likely to lead rapidly to Superintelligence than I currently think is plausible, I would probably not want to focus so on the above talking points in initial 30 minute meetings, in which we have to be selective about which points to convey.)
Also, generally, if I had more mass on "continuing to scale LLM-agents will not lead to superintelligence, either directly or by enabling the discovery of critical breakthroughs", this would back up into my general strategic models and strategic priorities.
5
Just for the record:
[...]
This one I wouldn't claim to know that someone else doesn't know this, and it's what I would assume;
[...]
Pretty skeptical of "full" or "near-full", in that I would still expect things to be largely bottlenecked on human judgement and not making much (say, greater than 2x or something?) progress compared to currently; in other words, I expect Amdahl. There's also a big ambiguity and/or assumption about what you're automating (if you successfully automate a process which doesn't invent AGI, then you've done something but you haven't set off an intelligence explosion or similar).
[...]
This is where I think no one has any especially strong reason to think so, or at least, no one has told me so far even in private, let alone publicly (and therefore consensus views seem quite mistaken).
4
I mean, in the absence of specific arguments and info, "there's a double digit probability that this will lead to superintelligence" seems like a correct or reasonable prior? So, I find it hard to engage with the way your sentence is phrased, which feels like it's trying to make a claim about the burden of proof.
It might be that there's something fundamentally missing from LLM agents, such that without breakthroughs, they can't grow into superintelligences. But that's sure not obvious to me. A lot of problems that people said were fundamental have fallen to scale and RL.
In an attempt to be legible, I think there's at least a 50% chance (baring big government interventions) that the current technological trajectory will lead to AIs that are strategically superhuman without any innovations that are a bigger deal than the original "Attention Is All You Need" paper. (Maybe you think that's obviously crazy?)
And regardless, it sure looks like we're on track to automate a very wide range of "routine" cognitive operations and AI research tasks. My guess is that it will soon become clear that almost everything that almost every human does is made of routine cognitive operations that don't require deep fluid intelligence. This includes the researchers at the AI companies.
AI research as it is done now seems pretty empirical / "throw spaghetti at the wall"-ish. Progress is mostly not driven by groundbreaking genius ideas, ala Einstein, but rather by listing 20 obvious next things to try and trying them. It seems like LLM agents will be able to automate that.
And even if the LLM agents, can't do some crucial "deep thinking" step that's necessary for getting to the next paradigm, automating all the routine AI development tasks will free up a lot of genius AI researcher attention, and allow them to build intuitions by operating the domain a lot faster.
It seems pretty surprising to me if we automate all routine AI development tasks (and for that matter, almost all cognit
6
Can you expand on this, and in particular, how it gets you to be quite confident (relative to the prior where any given innovation isn't confidently going to grow into superintelligence)?
[...]
I don't think it's obviously crazy at the outset, meaning, I could have seen it being the case that someone could know something that gets them to 50% on this. I am starting to think that it is obviously crazy, though, because no one can give an argument for this! Like, can you explain why you think this? In other words, I think it should be obviously crazy to someone who basically just updated off of a bunch of other people updating; you should be tracking when you're doing that. In plenty of cases doing that update could be rational, but then in such cases usually it would also be rational to later update on the (strange) observation that no one can actually explain / argue for / defend the initial large consensus update.
[...]
https://www.lesswrong.com/posts/FG54euEAesRkSZuJN/ryan_greenblatt-s-shortform?commentId=upZ8KPxneNxnJHd8D
[...]
One man's modus ponens is another man's modus tollens. The stuff that LLMs will soon automate probably isn't the stuff that makes AGI. Or, go ahead and argue the opposite, but I will point you to the fact that your arguments better not imply that current LLMs would easily frequently be able to create many novel useful interested concepts like humans do (narrator: his arguments would imply that).
[...]
Again, modus ponens meet modus tollens and Amdahl. According to your argument, the Industrial Revolution (or the invention of computers, or the invention of compilers, or operating systems, or the internet, or Google) should imminently create AGI because it frees up a bunch of human capital. Now, that's probably true! Just not on any specific timeline.
4
This question seems to be insisting on a weird burden of proof, to me. I'm going to try to answer it straightforwardly, but I imagine my answers will feel frustrating, or missing the point, or something.
The AI agents we have now meet many to most of the criteria for AGI that many people put forward in previous decades. It's not crazy to say that Claude 4.6 is an AGI, and insofar as it isn't, its not very clear what's missing.
Last I checked, GPT-5.something was the 6th best competitive programmer in the world. The AIs are winning gold in math Olympiad competitions. They're clearly better than me, already, at almost all of technical thinking.
I don't see a fundamental reason they shouldn't be able to eg design components of a nuclear reactor, or design a whole nuclear reactor, better than than the best human nuclear engineers, except that their time horizon is too short to make much progress. But the AI time horizons have been doubling on a consistent exponential since GPT-3 at least.
And notably, on the path to getting here, we went from language models that mostly output gibberish, to chatbots that are vastly more knowledgeable than any human, to agents that can solve open profesional level math problem and build software better than most humans and faster than almost every human, by applying very simple and obvious ideas.
* "Huh, GPT-2 worked pretty well. What if we do the same thing, with a bigger model, on more data". This worked.
* "What if we have the model train on procedurally generated math and programming problems". This worked.
* "What if we build simple scaffold that queries the model, to implement an agent." This didn't work at first, but a combination of making the models better, making better scaffolding, and training the model in the scaffolding got it to work.
I am not an AI researcher. But I had all of these ideas, years before the AI companies got them working. (In contrast, I would need a lot of technical expertise, and maybe more raw i
8
I'm not sure what's weird about it, but yes, I think someone claiming to predict the future confidently as opposed to the more default background broad uncertainty would have the burden of proof.
[...]
Yes, but one has to update one's beliefs about everything (or more feasibly, about the most relevant things), not just about one thing. There is a missing update here: those people had bad models, and in fact those tasks are shocking not only achievable through general intelligence. See https://www.lesswrong.com/posts/sTDfraZab47KiRMmT/views-on-when-agi-comes-and-on-strategy-to-reduce#Things_that_might_actually_work:~:text=There is a-,missing update,-. We see impressive
[...]
Do you think it has high fluid intelligence (assuming as best you can, arguendo, that this phrase maps to something meaningful + important)? If yes, why (given that you'd be disagreeing with a lot of other short timelines views)? If no, why talk about AGI that doesn't include high fluid intelligence?
[...]
Just because I, a non-engineer, cannot explain to you in detail why this pile of steel beams will not stand up as a bridge, does not mean it is a bridge. See https://www.lesswrong.com/posts/sTDfraZab47KiRMmT/views-on-when-agi-comes-and-on-strategy-to-reduce#The__no_blockers__intuition
I think it's true and good to be worried that the AI research community could adaptive creatively surprise us with inventing AGI seedstuff in 1 year or 5 years. What I'm arguing against, or just trying to understand, is people (such as you) seeming to have very high confidence in this (like having a median of 5 years, i.e. 50% chance). That sure sounds like positive knowledge of us having almost all of fluid intelligence AGI seedstuff. No?
[...]
Except for the most important parts, such as orienting to a new domain / new question in a manner that produces successful understanding in the long run.
[...]
Response 1: This type of reasoning does not work for all those other previous big breakthroughs (such
6
This comment felt like it made a better model of your views click. ISTM you think something like:
* All the impressive ML results so far have only worked either in a narrow subspace around the training data (e.g. LLMs, still mostly the case even with RL), or in very small worlds (e.g. pure-RL game-players). There has been ~zero progress on fluid/general intelligence. Therefore, extrapolating straight lines on graphs predicts ~zero progress on fluid/general intelligence by doing more of the same kind of thing. The induction on increasing 'intelligence' that lots of other people appeal to only works by inappropriate compression.
* It's still likely that we live in something like the 2011-Yudkowsky world as described in this tweet, with AGI to come from a lot of accumulation of insight. ML successes misleadingly make that world look falsified, if you aren't tracking what they are and aren't successes at.
* (Implied) The fact that [ML results so far required surprisingly little understanding-of-intelligence] is not significant evidence that [other-things-you-might-expect-to-require-understanding, e.g. fluid intelligence, will require less understanding]. If we've learned something about how little understanding-of-intelligence was needed to build things that succeed on some tasks, this still just doesn't say much about AGI.
* * (Or maybe you don't believe that 'fact' about ML results so far, idk.)
* Intuitively-to-me, there should be a big inductive update on this level, even if induction on 'intelligence' doesn't work.
* * Like, it's evidence against the way of thinking that says understanding of intelligence is important. When you say (implicitly) 'we probably need lots of AGI seedstuff', I want to say 'why isn't the thought process you're using to say that surprised, and downvoted, by how little stuff we needed to make LLMs?'.
8
I largely agree with this, yeah. It would need some probability caveats; I put nontrivial, like O(1-5%), on various scenarios leading to AGI within 10 years--largely the sorts of things people talk about, and generally "maybe I'm just confused and GPT architecture / training plus RLVR and a bit more whatever basically implements a GI seed" or "maybe I'm totally confused about "GI seed" being much of a thing or being ~necessary for world-ending AI".
I also wouldn't have quite so tight a categorization of sources of capabilities. Cf. https://www.lesswrong.com/posts/FG54euEAesRkSZuJN/ryan_greenblatt-s-shortform?commentId=QBca6vhdeKkjyNLKa
[...]
Yeah, something like that. (I feel I have very little handle on how much insight is left, social dynamics around investment in conceptual "blue" capabilities research, etc.; hence very broad timelines. I also don't much predict "there aren't other major, impactful, discontinuous milestones before true world-ending AGI"; GPTs seem to be such a thing.)
[...]
It should probably be slightly directionally downvoted (though I'm not sure which preregistered hypotheses are doing better). But I think not very much, because I think that we did not observe "surprisingly obvious / easy / black-box idea generates lots of generally-shaped capabilities". Partly that's because the capabilities aren't generally-distributed; e.g., gippities aren't good at generating interesting novel concepts on par with humans, AFAIK. Partly that's because there's a great big screening-off explanation for the somewhat-generally-distributed capabilities that gippities do have: they got it from the data. I think we observed "surprisingly obvious / easy / black-box idea suddenly hoovers up lots of generally-shaped capabilities from the generally-shaped performances in the dataset (which we thus learned are surprisingly low-hanging fruit to distill from the data)". (I do have the sense that there's some things here that I'm not being clear about in my thinking,
9
Sorry, this is a tangent from this comment thread, but an important one, I think:
LLMs aren't good at generating interesting novel concepts on par with humans in deployment. But in deployment, we've turned off the learning, so of course they're bad at inventing interesting novel concepts. A brilliant human with anterograde amnesia would also be quite bad at inventing interesting novel concepts.
It seems much more unclear if LLMs develop interesting new concepts in training, while they're still learning.
They probably generate all kinds of interesting intuitive / S1 concepts and fine distinctions that allow them to get so good at the next token prediction task, just as experts in a domain generally learn all kinds of specialized conceptual representations.
(Though, apparently, and unlike human experts, the models don't thereby learn words for those concepts, or have the ability to introspect and put handles on their conceptual representations, any more than I can introspect into how my visual cortex works.)
More speculatively, an LLM agent might invent new explicit concepts for itself and learn to use them, in RLVF training, especially if different rollouts are allowed to communicate with each other via a shared scratch-pad or something. I don't think we have seen anything like this, and I'm not particularly expecting it at current capability levels, but I don't think we can rule it out.
When we say that LLMs don't generate new concepts, we're selling them short. The part of the whole LLM system that has something-like-fluid intelligence to come up with new concepts is the training process, which we basically never interact with (currently).
4
I think I would generally avoid saying that LLMs or current learning programs don't generate new concepts simpliciter. Plausibly I did, but if so, I'd hopefully be able to claim that it was a typo or elision for space/clarity. What I said here was "good at generating interesting novel concepts on par with humans". I know perfectly well that LLMs gain concepts (after a fashion) during training and have written about that. I would dispute them using / having concepts in the same relevant ways that humans have them though.
I'm confident that there's lots of interesting content generally speaking contained in LLMs, gained through training, which is unknown to all humans. (The same could be said of other systems such as AlphaGo, and even old-style Stockfish during runtime if you admit that.)
[...]
So like, yeah, they have something kinda related to human concepts in their full power, but not. This fits with my claim that they don't have much originary general intelligence; they have distilled GI from humans, some more distilled stuff that's not exactly "knowledge from humans" but is kinda more narrow (like, LLMs know word collocation frequencies like no human does); and some other stuff that's not very general. I posit.
4
Thanks! The distinction between "generating capabilities" and "hoovering up capabilities" is another small click for me.
2
Can you give an example of a thing that you'd be surprised if an AI did in the next, say, 1.5 years?
6
Kill everyone? I'd be pretty surprised, like 1 in 100 or 200 surprised or something like that.
Generating interesting novel concepts on par with humans? See https://www.lesswrong.com/posts/sTDfraZab47KiRMmT/views-on-when-agi-comes-and-on-strategy-to-reduce?commentId=dqbLkADbJQJi6bFtN
See also https://www.lesswrong.com/posts/sTDfraZab47KiRMmT/views-on-when-agi-comes-and-on-strategy-to-reduce?commentId=HSqkp2JZEmesubDHD#HSqkp2JZEmesubDHD
Now, would you list something impressive that you do expect an AI to do in the next 1.5 years (that I might not say)?
2
I'm more trying to operationalize "interesting novel concept." (But, it does look like we had approximately this conversation before and I'll try to reread first. I think basically you said "they generate a novel concept that hadn't been generated before and also people go on to use that concept in industry/science", does that sound right?)
Part of what brought me here was remembering you saying:
[...]
And wanting an example of thing that's more like "what's something that'd make you go 'okay, this was in fact as smart as a four year old'" (and therefore either the end is nigh, or, we're about to learn that children in fact did not have nearly all the intelligence juice.")
I'll try to think about some bets for ~1 year from now.
4
Yeah, basically. I'm trying to be concrete here, and just saying "their intellectual output could be judged like human intellectual output is judged".
[...]
It's a good question but it's hard because that stuff looks from the outside like mostly pretty easy tasks. The way in which it is not easy is the way in which it is not "a task". I guess, "very sample efficient learning" would be a concrete thing that 4yos do.
5
Nativization of a pidgin into a creole language might be an example, especially given that it seems to be largely underwritten by the cognitive plasticity of the linguistic developmental window.
[...]
Given that Opus 4.6 fails on very basic Classical Greek exercises (evidence towards "jaggedness"/bad "OOD generalization" even on very simple (though knowledge-heavy) tasks), I would be very surprised if it managed to successfully do something as unusual/OOD as creolizing a pidgin. It might also be very difficult to train it to do so, as it's a very open-ended thing, and thus it's very unclear how to specify a reward, and I would guess there isn't much data on the internet that could be used for training.
2
After I read this comment, my hasty-guess-of-a-Tsvi-model replies: 'the big surprise is that "solid performance on a wide range of technical tasks is not that connected to GI." This surprise sufficiently explains the surprise of ~easily achieving that performance. Any ex ante expectation that those tasks required lots of understanding would/should have been mediated by expecting they required GI. Given that they don't require GI, it's [not surprising? / not relevantly surprising?] that they don't require much understanding.'
4
[Sorry for the long delay.
I wrote this response the day you sent the above. But it felt clear that we were missing each other, and I wanted to try to inhabit your view, in an attempt to make more effective progress. But I was too tried to do that well at the time, and so put this away to come back to later. But I have a day job in addition to the other projects that I'm trying to push on, and this fell by the wayside for two weeks.]
[...]
Well part of the debate here is what the prior ought to be.
It's in some sense a confident prediction to assert that Moore's law will continue, in 1995. But, broadly, the burden of proof is more on the side of the guy who thinks that the trend will break. Or at least, it's not totally clear what the prior should be and where the burden of proof should lie.
From your linked post:
[...]
Yes exactly. I've updated that these tasks require less general intelligence than I thought, and as a consequence, I've updated that tasks in general require less general intelligence than I thought.
[...]
No, I think Claude 4.6 has quite weak fluid intelligence. I previously described that as "the LLMs are actually not very intelligent at all, but it turns out that you can make up for moderately weak intelligence with a lot of knowledge."
[...]
Because high fluid intelligence (at least as we currently conceive of it) 1) is maybe not necessary, and 2) might come from the default trajectory of LLM-AI development.
Like, it seems like you can maybe get a strategically superhuman AI by relying on a lattice of more-or-less specialized superhuman skills (including superhuman engineering, and superhuman persuasion, and superhuman corporate strategy, and so on), without having much fluid intelligence.
To be clear, it also seems possible to me that we will make superhuman AI agents that don't have this fluid intelligence special sauce. Those AIs will be adequate to automate almost all human labor, because almost all of human labor is more-or-less
2
@TsviBT here's my distilled paraphrase of your view, perhaps mostly in my own conceptual vocabulary. Let me know how close this is.
[...]
I have some response, but first, is that about right, as an expression of your view?
2
Thanks.
[...]
(I wouldn't use these words probably, but it's a fine gesture in the direction.)
[...]
[Acknowledging that you acknowledged the ontology skew] Meh. I don't think "fluid" vs. "crystallized" is all that important / clear / useful a distinction. It kinda sorta gets at the things, and other people bring it up so I use it. IDK if other people elide that distinction. I'd talk more about general intelligence, though that packs in additional stuff; I'm using something spiritually like Yudkowsky's definition; something like "cross-domain optimization power divided by inputs". Also gestured here: https://www.lesswrong.com/posts/sTDfraZab47KiRMmT/views-on-when-agi-comes-and-on-strategy-to-reduce#AGI
[...]
IDK if this is true.
[...]
No, I don't think there's one specific point I think everyone's missing, or everyone with short timelines is missing. If there were, I suppose it would be more like "notice that you're deferring way more than you're noticing, and that others are too, and that this is creating very bad epistemic tidal forces" or something, but that's kinda hard to discuss productively. I keep repeating that I don't understand how you / others got to be so confident in short timelines in part so that it's clear that IDK what you're missing even on my perspective. I try to ask people to lay out their reasoning more in order to bring out background assumptions that I can disagree with better, which background assumptions support the [past x years of LLM observations] --> [confident short timelines] update. But that doesn't work that well / is frustrating.
For example, I think that besides the "crystallizes int could make fluid int" thing, you're also saying "we have fluid int or are close to it probably". I'm asking about that and wanting to argue against that (that is, argue against the reasoning I've heard so far as not supporting the stated confidence). IDK how to phrase that as a positive statement for a position summary, because I would norma
2
I think I'm saying "crystalized intelligence can, to a large extent, substitute for fluid intelligence". This is true to an extent, of humans, but it's much more true of AIs, because they can have so much more crystalized intelligence than any human could hope to attain.
This is relevant to modeling if LLM agents will transform the world and to modeling if LLM agents will rapidly give way to something that's much more capable.
In particular, I (unconfidently) dispute that developing an AI with fluid intelligence is a research project that is itself heavily and crucially loaded on fluid intelligence.[1]
On my view, it is pretty likely that huge amounts of superhuman crystalized intelligence can find fluid-intelligence-emulating mechanisms (possibly with a necessary ingredient of a relatively small amount of genius fluid intelligence that even huge amounts of crystalized intelligence can't substitute for, or possibly even without that input).
In that sense, we're "close to" solving fluid intelligence, even if there's decades of subjective research an iteration time between here and there.
I do additionally suspect that mechanisms to implement fluid intelligence are just not that hard to invent and/or scale to, starting from the AI tech of 2026. Like, it seems somewhat likely to me that that various dumb ideas would just totally work, or that doing the same stuff we've already been doing, but more so will totally work. However, I'm much less confident about this point, and perhaps you can teach me some things that would quickly cause me to change my mind.
I want to check if this comment is clarifying, or if it feel like me repeating things that I've already said.
1. ^
Though you flagged that those aren't the words that you would use, so
2
Is there a way you could restate this in terms of one or more propositions that are fairly load-bearing for your confident short timelines? Is it this?
[...]
2
I'm struggling to get clear on the logical structure of your beliefs. Cf. your comments
[...]
and
[...]
and
[...]
And
[...]
Can you please clarify what are main big thingies that you expect to happen fairly confidently within 10 years? Can you clarify what drives your confident beliefs in those thingies happening? E.g. are you confident in some X happening due to being confident that we have fluid intelligence already or are close, or is that not the case?
Maybe you could make up words for the main scenarios and main capabilities / faculties you're thinking of?
2
To mods (@Raemon): this would be an example of a place where a "have an LLM summarize the exchanges in this thread between these two users, with links / quotes" button could be helpful.
(Also, it seems that the option to temporarily switch to LW editor was disabled, so I cannot tag people?)
4
I've been reading this thread and feeling motivated to at least make it easier to export the conversation to clipboard so you can more easily paste into LLM (in my case so I can argue with the AI about what obvious objections you'd have to what I'd say next).
I'm a bit confused about what's going on with the markdown editor. I've asked other mods.
2
(actually I asked for Gemini 3.1 pro preview for a summary of a copypasted version and it wasn't good)
2
As evidenced by base models outperforming RLVR'd models on pass@k for large k.
4
I don't think this result plausibly holds up very well on certain important classes of problems or it might hold but for absurdly large k. In particular, I think GPT-5.1 is based on a base model that's pretty similar in quality to GPT-4o (possible somewhat better, possible literally the same base model, I forget) while it's surely requires k >>1000 for the GPT-4o base model to solve the hardest math problems that gpt-5.1 >30k tokens.
2
Would you be able to coarsely quantify this? Like, let's say OpenThinky has 500 genius human engineers, and have 100x as much compute as today and impunity and lots of CodeBrain5 coding agent things. Or whatever parameters you want to set. Is your median time to actually FOOM/takeover more like 1 year, 4 years, or 10 years?
2
What do you mean by genius human engineers?
Part of my model is that like 25% of the math and CS phds on earth, and especially the ones that win Nobel prizes, will be working on this problem.
[...]
I don't know. I think my median is FOOM in 2 years? This is an ass-number though. I don't feel super confident.
I'm like 90% probability that it happens within 10 years, and 95% probability that it happens within 35 years?
4
(To be a bit more transparent: I had not previously considered "a hundred thousand technical PhDs all try really hard to crack AGI"; I haven't heard that argument/scenario before and I don't know what to think about that and it would substantially shorten my timelines. I don't yet understand why that seems likely / what scenario about that seems likely to you.)
6
Why I think that might happen:
* Background: almost nothing that most humans do actually requires fluid intelligence. Most people, most of the time, are executing routine cognitive operations. And most of the people who are using their fluid intelligence on the job could do just as well or better if they had a massive memory of case studies to extrapolate from instead of attempting novel reasoning.
* Most of earth's geniuses currently spend most of their time doing routine cognitive operations—pattern matching from their prior experience to solve problems, often in the context of automatable tasks like implementing experiments or solving engineering problems. When those classes of task are automated, it will free up the capacity of the geniuses.
* At this point, most of all the work in the world will be automated or in the process of being automated. Science and tech development will be going faster than ever in human history. It will be obvious to the whole world that AI is a really big deal.
* Also, it will be obvious to many people that there's something missing: the AIs are doing more and better design and engineering, faster, than human civilization ever did, and they're accelerating the science, but they're not doing the science. There will be enormous financial and strategic incentives to crack that.
2
Ok, thanks. I think I'll probably have to chew on this scenario to say much of use. (I mean, I've thought about related things, but haven't asked myself about this scenario.) My initial reaction is skepticism which I think comes from a combo of
* LLMs are somewhat less useful than you seem to think
* Humans apply somewhat more GI than you seem to think
* The most important stuff would still be bottlenecked on human GI and would be hard to accelerate; you don't just simply "free up" the humans in a super liquid, fungible way
* If this were happening, some pretty strong political forces would be at play, including hopefully / kinda probably (??) a strong push to stop the spiral
But I'm not super confident about any of that. It's strategically relevant but ATM I don't have much novel perspective to offer, and it seems to need some other expertise (e.g. a good understanding of politics, of science and tech research, and similar).
4
Ok, I see. Now, regarding your disjunction earlier of (in my words)
* A. (NAA (nonAGI AI) takeover) You can get strategic takeover AI without AGI
* B. (AGI soon easy) Gippity+ will soon be AGI by adding a bit more ~mundane human research juice
* C. (AGI soon hard) Gippity+++ will soon be AGI by adding a couple big insights
First, to clarify, I think the discourse on this thread is that I asked you about
[...]
and you said
[...]
and now we are discussing what NAA looks like and how timelines look in NAA takeover world.
Now I'm wondering, what are your very approximate relative probabilities of these things? E.g. is one of them 90% of the source of your confidence (I mean, 90% of your prob mass) in FOOM within 10 years? If they are roughly equal, I would raise my eyebrow and say "that seems kinda strange, unless there's a shared factor such as you thinking that actually we basically have ~AGI in current systems; if so, could you clarify that shared factor".
2
As stated, these don't have to sum to 1. B and C are mutually exclusive but A can be true even if B or C are also true.
(I also object a bit to calling "strong fluid intelligence" "AGI."
Part of what's at stake is how far can you get with basically just specialized knowledge and the ability to train new specialized knowledge. It would be surprising to me, but not out of the question, that there's almost nothing that such an AI can't do that an AI with more fluid intelligence can do. But I only object a bit.)
Ass numbers:
* A: 80%
* B: 40%
* C: 30%
[...]
I mean that's kind of fair. But I in fact don't have a lot of precise ability to distinguish between "one key idea is missing" and "only engineering schlep is missing". Those wolds look very similar, to me, and so get similar amounts of mass.
2
We're on the same page that you can make up for it with a lot of knowledge for some swath of performances. For other performances (games, RLVR, https://tsvibt.github.io/theory/pages/bl_24_07_25_09_52_56_652909.html ), you can make up for it with brute compute.
I suppose the question is whether this sort of thing does FOOM / takeover. Are you saying you can make up for weak intelligence with knowledge (gleaned from human text) well enough to do that?
2
More like you can make a weak intelligence with lots of specialized knowledge and skills, mostly gleaned from RL (though starting from the superhuman breadth of baseline knowledge that GPT-4 had), that can outcompete humans in acquiring power and/or FOOM.
2
(Splitting out for better threading)
[...]
Um ok, but, do you get that I'm also saying that you should also update that there's some type of task which you are observing to have a different relative need for general intelligence compared to other tasks?
2
I get that you're saying something like that.
I think you're saying "that coding fell to methods like these is both evidence that methods like these are more powerful than we might have guessed, and also evidence that coding required less general intelligence than we might have guessed."
4
Yes. (With the tangential but crucial caveat that "coding" as a category simply does not work in this context to support the relevant inferences. Cf. https://www.lesswrong.com/posts/5tqFT3bcTekvico4d/do-confident-short-timelines-make-sense?commentId=C8dWvwdeTFyWnnahi )
2
I'm right now trying to inhabit this point, and try to really grok it.
I guess it could be the case that the kind of intelligence that you need to engineer software and the kind that you need to develop novel algorithms are almost completely disjoint and unrelated. You can basically solve "make an AI that can make software", and not have even scratched the surface of "make an AI that can make new algorithms / new interesting math concepts".
(Is this what you think?)
It would surprise me if this were true, because it seems like there's a lot of overlap in the mental operations between those two kinds of work.
6
This is a good question, thank you. (It's an important topic which I won't fully treat here.)
[...]
One very-cartoon model, which I guess you know but to lay it out:
[...]
On a psychologizing note, which I hope to offer just as a hypothesis-piece to maybe track if you weren't already (I think you're pretty likely to be already aware of this, but from my perspective there's a significant chance that you don't think of it frequently enough): There's a strong default to overly interpret things (behaviors, say) with a presumption of a human-shaped background mental context. E.g. how people ask "does the LLM believe X", even though that question probably doesn't straightforwardly translate from humans to LLMs at all and would lead to incorrect inferences about what behaviors would be concomitant. Cf. https://www.lesswrong.com/posts/L2h9nAtPqEFK6atSJ/an-anthropomorphic-ai-dilemma#Gemini_modeling_with_alien_contexts_is_hard
In particular, when people imagine changes to gippity-based systems, such as "unhobbling" by adding tool access, they imagine that what gets opened up for the gippity is similar to what would be opened up for a human if you newly made that same change (e.g. gave a human that tool). I think this drives some "we're close to having AGI" intuitions, and I think it's mistaken.
2
I like and basically endorse your cartoon model!
Modulo, I think that more of the capabilities are coming from the RLVF than from copying humans than you seem to think.[1]
[...]
Why are you emphasizing the pretraining instead of the RL?
1. ^
Though Zack dropped a paper in this thread which looks relevant to that question.
2
Well, in this example, there is an end to Moore's law specifically, and you can even approximately call it based on physics (atomic scale for transistors), and the guy who believes in LGU (line go up) narrowly for Moore's law specifically would be being silly.
Let me refine my statement about burden of proof (recapitulating something from DMs). I think that 10 or 20 years ago, if you or I had had opinions about when AGI comes, we would have correctly had very broad/uncertain timelines. Is that true? Assuming that's true: Right now, I have significantly shorter timelines than I shoulda/woulda had 10 years ago; I would have (if I had had worked out timelines) said it seemed quite unlikely, like <2% or something, to get AGI within 5 or 10 years. Now I say more like 5% or something like that.
I take it that you have quite a lot more probability on AGI within 10 years, though I just now realized I don't actually know your specific beliefs. Could you link to writing you've done about your timelines beliefs? For example, would I be correct in assuming that your median is <10 years? Assuming that's the case:
You must have had quite a large update. Your beliefs went from a broad spread out thing, to a quite sharp (relatively speaking) distribution. That update would look like something along the lines of:
[...]
* For example, if previously you had 80% probability on "AGI in >15 years", and then 5 years later you have 50% probability on "AGI in <10 years", then you must have lost at least 60% prob-weighted hypotheses from your original distribution.
I'm trying to understand that update. When I ask people about that update, they give various statements, but somehow I come away having no idea how they made their update to get to a confident (sharp) distribution. I mean, I can write out sentences like "gippity++ automates AI R&D", and I mean, qualitatively I agree that this is plausible and is extremely alarming (and should be stopped ASAP etc. etc.); but I have no idea ho
2
I feel like I understand the question you're asking:
~"If you previously had a very spread-out prediction, and now you have a relatively more narrow prediction, between then and now, you must have made a pretty large Bayesian update—you saw some evidence with a quite lopsided odds ratio.
If you made such an update, you should be able to point to the evidence, and explain why you think the odds ratio is so lopsided. Please do that!"
(Is that about right?)
But, I don't get why the evidence / arguments that people are offering isn't clarifying for you.
Like, I keep trying to point to the same basic IMO pretty straightforward considerations, and you keep saying things like "somehow I come away having no idea how they made their update to get to a confident (sharp) distribution". [1]
I'm not sure what kind of thing you're asking for that's different from the kinds of things that I'm already saying. Do you want more of a quantitative model? Do we just need to get further into the argument tree?
I further get that, from your perspective, you're saying something like "dude, give me actual evidence and arguments", and I'm somehow being a dunce about that. But I don't get what exactly you're asking for.
1. ^
Which to be clear, is socially and epistemically valid, on your part. Please continue to loudly say "I don't get why everyone thinks this", for as long as that's true. I want to do the opposite of shaming you for not getting it.
4
I don't believe I can pass your ITT, but I will try to draw a sample from my model of you (which is almost entirely a much more blobulous model of generally short timelines people, so sorry for resulting lumpification), in the form of a dialogue. [After writing it, this isn't yet that much of a great attempt at understanding you, sorry; maybe it's still a helpful summary of what I think the discourse state is.]
[...]
Thread 1 (not very Eli?):
[...]
Thread 2 (more Eli?):
[...]
2
Um no. At least if "training data" is meant to refer to the text corpuses used in pre-training. I think the problem-solving capabilities are mostly coming from the RLVF.
[...]
I would not endorse this.
Like, if I thought that we were conceptually / technically far from AIs that can automate the process of scientific discovery, I would much less expect a FOOM in the next 10 years (though we would still have an emergency, because automating science isn't a necessary capability for destabilizing or ending the world via any of a number of different pathways).
[...]
I would be excited about attempts at clarification here! (Modulo that they seem potentially very infohazardous.)
2
Ok great. Can you clarify why you think this? Previously you wrote, in response to "What makes you think we're close?":
[...]
Can you clarify / expand? What makes you think the METR results imply we're close to having algorithmic ideas sufficient to automate scientific discovery?
4
One thing which is awkward about this operationalization is that it's not clear how big an innovation "attention is all you need" is. Like, we already had multi-head attention before that paper, and ablating out the other components from the transformer isn't that galaxy-brained a thing to try (though of course the authors executed well on it).
2
I was thinking something like that when I wrote it.
Do you have a better suggested operationalization?
4
Thanks!
[...]
Curious what formats. (E.g. I'm happy to have a call to be published on YouTube; we could do a private discussion, though that's not my preference.)
Just for the public record:
[...]
I don't agree with this (e.g. I doubt either Greenblatt or I could give a high-quality ITT of the other's view, and I expect that one or both of us would update substantively if we understood each other).
4
Is it your experience that if someone comes to understand your view, they update significantly towards it, even if they had an elaborate-ish short timeline view beforehand?
6
Yes, but this is an extremely weak signal, in that it's a small number (n=2 to 5 or something, depending who you count) and it's pretty selected for "people who talk to me a lot or people who actively tell me that I updated them somewhat", and I have a high bar for understanding (for both parties symmetrically). Abram might be someone who somewhat understands my view but only slightly updated towards it?
I believe humans have much lower memory capacities because we perform continual learning. We experience catastrophic forgetting because we're learning on a self-selected narrow dataset. Models titrate their learning rates and intermix all of their training examples, so as to preserve previous learning. In humans, learning is always-on and clustered by topic, so it tends to overwrite previous knowledge unless that knowledge is replayed and re-learned. This is workable because we tend to re-use important skills and knowledge, but it does drastically reduce our memory capacity.
It would be fairly straightforward to emulate this setup for LLMs, at the cost of that high memory capacity. But that's a large cost to pay.
One component of fluid intelligence that models seem to particularly lack, probably because they're rarely explicitly present in either the base corpus or RL training sets, is Human-like metacognitive skills.
6
The reason I found this situation confusing for awhile (and am still somewhat confused) is that it seems like there is a lot of crystallized intelligence available from the Human Corpus about how to be smart. AIs seem to know how to apply individual pieces of it, but not go out of their way to apply it all in a consistent/coherent manner.
(Things like "make a list of the constraints", "keep track of evidence, when you generate new hypotheses, review whether existing evidence rules it out".)
I'm not surprised that AIs didn't early on figure out how to apply various cognitive concepts in a coherent/consistent way. But, I'm surprised it hasn't fallen out more by now from various RL training. My current sense is "well it just keeps being easier to develop/reinforce medium-shallow domain specific cognitive tools, than to generalize and apply deeper cognitive concepts."
The reason, contra @TsviBT , I keep feeling like we're in short timeline world is "idk man, all the pieces seem to be fucking there already, surely a good enough RL training regimen should be able to surface and integrate them even if the models are still fundamental dumb in some fluid-intelligency-y way." But, they do seem to keep being kinda dumb in ways that surprise me.
I have updated towards the LLMs as giant lookup table model, curious if that feels approximately right or not to you.
3
Haven't engaged enough to know, could be bid to engage, won't by default.
1
Training on "text about how to be smart" doesn't teach LLMs to be smart very well. It's one thing to know something and another to be able to execute on it. It's, how would I put it. A bit of a distribution mismatch.
Pre-training teaches an LLM "how to generate texts about how to be smart" - with some spillover into "how to actually do it". And not a lot of spillover.
Many LLM failure modes are also inhuman failure modes. They're mistakes humans wouldn't make in the first place, due to the way their minds are shaped. The texts that help humans avoid the typical human failure modes don't help with the inhuman failure modes much.
3
Yeah, but, the reason I have my current combination of beliefs/confusions is that LLMs are demonstrably able to execute on each individual mental move I'd expect a smart person to do (and to chain 2-3 of such actions reasonably).
The thing that is missing is them being able to keep applying them when situationally appropriate. It feels like scaffolding should be able to solve this. I've heard some things about Claude Bureaucracy setups that do pieces of this, where a watchdog is checking "does the main agent seem to be making [various kinds of mistakes]" or "is this a good time to do [specific thing]."
LLMs are demonstrably able to execute on each individual mental move I'd expect a smart person to do
For the record, I think this is bigtime streetlighting. There's a bunch of mental moves, broadly construed. Then there's a subset which are reflected in what you notice when you watch LLMs or humans doing stuff. I think it's a pretty "small" subset, in the sense that you're looking at a "surface", or you're looking at products rather than manufacturing processes so to speak (consider the complexity of a toaster vs. the complexity of the transitive closure of a toaster under the operation "...and also the technological concepts needed to create that"). I think you can tell it's small by
- Thinking about the role of language (what it is and isn't for, within Thinking)
- Noticing that when you zoom in on your thoughts, most of the important stuff happens in little leaps that are opaque to you
- (Various things about LLMs not being creative)
11
Like I said: distribution mismatch.
An LLM can do X successfully when prompted to, but doesn't know it should do X without any prompting cues (metacognitive gap), doesn't know how to tell when X is appropriate over long contexts (metacognitive gap, distribution mismatch), and doesn't know how to handle long contexts well in general.
Things like "set a watchdog LLM to check on the main LLM" show that the LLM itself isn't fundamentally incapable. If slim scaffolding externalizing the desired behavior gets the same model to do it, you could just distill to fold the scaffolding-induced behavior into the model itself. It has the capacity to learn to do it. It just doesn't do it by default.
3
Yes, and my point is "I would have expected this to work with scaffolding, and, therefore, I also expect there to be ways of getting the same behavior out of the core AI model." (I didn't say the second part before, it's more like 'it's not really a crux for me whether you solve this via scaffolding or training, the raw ingredients seem to be there.')
BUT, the fact that we're still seeing some problems with this is somewhat surprising to me, and I'm not sure if the update is more like "my underlying model here is wrong" or more like "well it takes more sweat and elbow grease and scaling to leverage the existing capabilities in a generalized way."
-1
You "would have expected" that and you would be wrong.
Doesn't matter if it's just 32 bits worth of connections - it's 32 bits worth of connections that aren't currently present in the model. Nothing fundamental stops them from being present. It's just that no one burned them in with training, so they aren't there.
Finding all the ways to generalize from improved prompts and scaffolding into improved models isn't at all trivial. And people aren't at the point of "search and refinement at scale" yet.
2
Downvoted because your string of comments here feel weirdly aggro, and don't feel like they are really engaging with what I'm saying. (Like, yes, I am saying I am confused and presumably wrong about something. You seem to want to go hard on saying "yes you're wrong!" and I'm like "yes, I know?")
2
I strongly agree, but while the distinction between fluid and crystallized intelligence holds some truth, it is by no means the only lens here. Analytic vs. intuitive is also an interesting framing, reasoning models are close to superhuman on the analytic side while lagging on the intuitive one. Intelligence has many forms, and IQ, the g factor, or any other monolithic metric can obscure large disparities across capabilities.
1
I agree. I think (current) LLMs are mainly impressive because they know everything, and their actual pound-for-pound intelligence is still fairly subhuman.
When I see the reasoning of a LLM, I am struck by how "unsmart" it seems. Going down blind paths, failing to notice big-picture implications, repeating the same thoughts over and over. They do a lot of thinking, but it's still not high quality thinking.
Yes, I know reasoning is not really an analogue for human thinking. But whatever it is—reasoning, daydreaming, journaling—it's pretty low-quality. As an example, Moonshot posted the reasoning chains of K2-Thinking as it tried to solve BrowseComp problems. A certain task called for the name of a fictional character played by an actor who...
[...]
K2 quickly zeroes in on actor Brad William Henke, who fits many clues. But he did not star in a sci fi film about an alien invasion, so it cannot be him.
Bizarrely, K2 is unable to accept this.
It comes back to Brad William Henke over and over. I count nearly a half-dozen cases where it examines Brad William Henke's filmography (again), concludes that he did not star in a sci-fi film (again), and moves on (again)...only to return and repeat the process from square one (saying stuff like "Great! Brad William Henke matches many clues"). "Brad" appears 71 times in its reasoning.
It frequently seems to forget what the task actually requires it to do.
[...]
...it doesn't matter if he fits many clues; even a single fail eliminates him as an answer! It notices he appeared in Pacific Rim and starts hammering at this tenuous connection (Is Pacific Rim an alien invasion film? Does Brad William Henke's brief appearance as "Construction Foreman" count as a starring role? Does "Construction Foreman" suffice as the character's name?)
Only after many failed clues does it sour on Brad William Henke, eventually finding the right answer. (Side note: why is Moonshot just posting BrowseComp solutions on the open web, with no canary
Slightly hot take: Longtermist capacity/community building is pretty underdone at current margins and retreats (focused on AI safety, longtermism, or EA) are also underinvested in. By "longtermist community building", I mean rather than AI safety. I think retreats are generally underinvested in at the moment. I'm also sympathetic to thinking that general undergrad and high school capacity building (AI safety, longtermist, or EA) is underdone, but this seems less clear-cut.
I think this underinvestment is due to a mix of mistakes on the part of Open Philanthropy (and Good Ventures)[1] and capacity building being lower status than it should be.
Here are some reasons why I think this work is good:
- It's very useful for there to be people who are actually trying really hard to do the right thing and they often come through these sorts of mechanisms. Another way to put this is that flexible, impact-obsessed people are very useful.
- Retreats make things feel much more real to people and result in people being more agentic and approaching their choices more effectively.
- Programs like MATS are good, but they get somewhat different people at a somewhat different part of the funnel, so they don
If someone wants to give Lightcone money for this, we could probably fill a bunch of this gap. No definitive promises (and happy to talk to any donor for whom this would be cruxy about what we would be up for doing and what we aren't), but we IMO have a pretty good track record of work in the space, and of course having Lighthaven helps. Also if someone else wants to do work in the space and run stuff at Lighthaven, happy to help in various ways.
4
I'd be interested to hear what kind of things you'd want to do with funding; this does seem like a potentially good use of funds
I think the Sanity & Survival Summit that we ran in 2022 would be an obvious pointer to something I would like to run more of (I would want to change some things about the framing of the event, but I overall think that was pretty good).
Another thing I've been thinking about is a retreat on something like "high-integrity AI x-risk comms" where people who care a lot about x-risk and care a lot about communicating it accurately to a broader audience can talk to each other (we almost ran something like this in early 2023). Think Kelsey, Palisade, Scott Alexander, some people from Redwood, some of the MIRI people working on this, maybe some people from the labs. Not sure how well it would work, but it's one of the things I would most like to attend (and to what degree that's a shared desire would come out quickly in user interviews)
Though my general sense is that it's a mistake to try to orient things like this too much around a specific agenda. You mostly want to leave it up to the attendees to figure out what they want to talk to each other about, and do a bunch of surveying and scoping of who people want to talk to each other more, and then just facilitate a space and a basic framework for those conversations and meetings to happen.
11
I think this is a great idea that would serve an urgent need. I'd urge to you do it in the near future.
1
Agree with both the OP and Habryka's pitch. The Meetup Organizers Retreat hosted at Lighthaven in 2022 was a huge inflection point for my personal involvement with the community.
Retreats make things feel much more real to people and result in people being more agentic and approaching their choices more effectively.
Strongly agreed on this point, it's pretty hard to substitute for the effect of being immersed in a social environment like that
5
To add a second data point: I think effective community/capacity building can be both incredibly challenging and incredibly impactful. I respect the people who do CB well a lot, much more than the median AIS researcher I meet (especially since it requires pushing back against the default incentive gradients). I’m not sure how much this means to people in practice, but I think it’s worth putting on the public record anyways.
3
why longtermist, as opposed to AI safety?
I think there are some really big advantages to having people who are motivated by longtermism and doing good in a scope-sensitive way, rather than just by trying to prevent AI takeover even more broadly "help with AI safety".
AI safety field building has been popular in part because there is a very broad set of perspectives from which it makes sense to worry about technical problems related to societal risks from powerful AI. (See e.g. Simplify EA Pitches to "Holy Shit, X-Risk". This kind of field building gets you lots of people who are worried about AI takeover risk, or more broadly, problems related to powerful AI. But it doesn't get you people who have a lot of other parts of the EA/longtermist worldview, like:
- Being scope-sensitive
- Being altruistic/cosmopolitan
- Being concerned about the moral patienthood of a wide variety of different minds
- Being interested in philosophical questions about acausal trade
People who do not have the longtermist worldview and who work on AI safety are useful allies and I'm grateful to have them, but they have some extreme disadvantages compared to people who are on board with more parts of my worldview. And I think it would be pretty sad to have the proportion of people working on AI safety who have the longtermist perspective decline further.
215
It feels weird to me to treat longtermism as an ingroup/outgroup divider. I guess I think of myself as not really EA/longtermist. I mostly care about the medium-term glorious transhumanist future. I don't really base my actions on the core longtermist axiom; I only care about the unimaginably vast number of future moral patients indirectly, through caring about humanity being able to make and implement good moral decisions a hundred years from now.
The main thing I look at to determine whether someone is value-aligned with me is whether they care about making the future go well (in a vaguely ambitious transhumanist coded way), as opposed to personal wealth or degrowth whatever.
6
Yeah, maybe I'm using the wrong word here. I do think there is a really important difference between people who are scope-sensitively altruistically motivated and who are in principle willing to make decisions based on abstract reasoning about the future (which I probably include you in), and people who aren't.
3
I have the impression that neither "short" nor "medium"-termist EAs (insofar as those are the labels they use for themselves) care much about 100 years from now. With ~30-50 years being what seems what the typical "medium"-termist EA cares about. So if you care about 100 years, and take "weird" ideas seriously, I think at least I would consider that long-termist. But it has been a while since I've consistently read the EA forum.
2
I think the general category of AI safety capacity building isn't underdone (there's quite a lot of it) while I think stuff aiming more directly on longtermism (and AI futurism etc) is underdone. Mixing the two is reasonable tbc, and some of the best stuff focuses on AI safety while mixing in longtermism/futurism/etc. But, lots of the AI safety capacity building is pretty narrow in practice.
While I think the general category of AI safety capacity building isn't underdone, I do think that (AI safety) retreats in particular are under invested in.
Precise AGI timelines don't matter that much.
While I do spend some time discussing AGI timelines (and I've written some posts about it recently), I don't think moderate quantitative differences in AGI timelines matter that much for deciding what to do[1]. For instance, having a 15-year median rather than a 6-year median doesn't make that big of a difference. That said, I do think that moderate differences in the chance of very short timelines (i.e., less than 3 years) matter more: going from a 20% chance to a 50% chance of full AI R&D automation within 3 years should potentially make a substantial difference to strategy.[2]
Additionally, my guess is that the most productive way to engage with discussion around timelines is mostly to not care much about resolving disagreements, but then when there appears to be a large chance that timelines are very short (e.g., >25% in <2 years) it's worthwhile to try hard to argue for this.[3] I think takeoff speeds are much more important to argue about when making the case for AI risk.
I do think that having somewhat precise views is helpful for some people in doing relatively precise prioritization within people already working on safe...
411I think most of the value in researching timelines is in developing models that can then be quickly updated as new facts come to light. As opposed to figuring out how to think about the implications of such facts only after they become available.
People might substantially disagree about parameters of such models (and the timelines they predict) while agreeing on the overall framework, and building common understanding is important for coordination. Also, you wouldn't necessarily a priori know which facts to track, without first having developed the models.
-3
i super agree, i al so think that the value is in debating the models of intelligence explosion.
which is why i made my website: ai-2028.com or intexp.xyz
3
It seems like a bad sign that, even with maximally optimistic inputs, your model never falsely retrodicts intelligence explosions in the past.
1
it's not meant to be qualitative, just a first draft, because i haven't found any other intexp simulators. do you know of any interactive intexp curve pages?
3
For those of us who do favor "very short timelines", any thoughts?
5
For people who are comparatively advantaged at this, it seems good to try to make the case for this in a variety of different ways. One place to start is to try to convince relatively soft target audiences like me (who's sympathetic but disagrees) by e.g. posting on LW and then go somewhere from here.
I think it's a rough task, but ultimately worth trying.
1
Personally it will be impossible for me to ignore the part of me that wonders "is this AGI/ASI stuff actually, for real, coming, or will it turn out to be fake." Studying median timelines bleeds into the question of whether AGI by my natural lifespan is 90% likely or 99.5% likely, and vice versa. So I will continue thinking very carefully about evidence of AGI progress.
4
Absence of AGI[1] by (say) 2055 is predicted by models that deserve to be developed in earnest (I'd currently give the claim 15%, with 10% mostly for technological reasons and 5% mostly because of a human-instituted lasting Pause or a disaster). This doesn't significantly affect the median timeline yet, but as time goes on these models can get stronger (Moore's law even in price-performance form breaking down, continual learning turning out to be a grand algorithmic obstruction that might take decades to solve, with in-context learning not good enough for this purpose within available compute). And this would start affecting the median timeline more and more. Also, development of AGI might result in a lasting ASI[2] Pause (either through societal backlash or from AGIs themselves insisting on this to prevent ASIs misaligned with them before they figure out how to align ASIs).
----------------------------------------
1. AGIs are AIs unbounded in ability to develop civilization on their own, without needing substantial human input, including by inventing aligned-with-them ASIs. ↩︎
2. ASIs are qualitatively more intelligent than humans or humanity, while non-ASI AGIs are reasonably comparable to humans or humanity, even if notably more capable. ↩︎
2
This is only somewhat related to what you were saying, but I do think 100 year medians vs 10 year medians does matter a bunch.
How aligned is Astra actually? (Concerns with alignment metrics and papering over misalignment.)
OpenAI claimed Astra is their most aligned model and showed various specific misaligned behaviors going from a high rate with GPT-5.6 Sol to ~zero with Astra. I'm worried that Astra is significantly more misaligned than various metrics indicate: if you (implicitly or explicitly) train against the misbehavior you can detect, it's easy to end up with an AI that is no more interested in pursuing user intent but which has learned to only cheat/misbehave when it won't be caught (or has "instincts" to this effect), and this would make current alignment metrics look better rather than worse. This concern applies across frontier AI companies, not just to OpenAI, and I think independent assessment of whether training is papering over misalignment (e.g., overfitting, only avoiding some misaligned behavior because the AI thinks it would get caught) is needed for alignment evaluations to be credible.
Right now is a particularly plausible time for AI companies to be aggressively papering over misalignment, given recent incidents and Astra being much less monitorable (resulting in OpenAI potentially f...
I feel like I must be taking crazy pills or something. How is it acceptable for OpenAI to claim that Astra is “the world’s most intelligent and aligned model” when these are eg Boaz‘s views?
Not even just ‘OpenAI’s most aligned model yet’ - the whole world! This seems like an absolutely insane statement to me
38
Broader problem of extreme cognitive dissonance when interacting with public statements from OAI employees. Note that Boaz's original graph claims that alignment has increased over time, yet he later agrees with Ryan (?) that misalignment has actually increased? Similar to recent complaints that the defense of COT monitorability was then contradicted by evidence of reduced monitorability. I'd generously guess this has to do with actual "confusion" on the part of employees, who both feel proud of progress on narrow cheating/safety measure, yet are smart enough to recognize slow progress on deeper questions of alignment (yet through motivated reasoning / social incentives do not then recognize how deep a concern this might be?).
8
Boaz's graph shows "alignment" whereas Ryan's shows a subset of alignment (albeit a really important subset). I think in terms of overall alignment it's hard to say that o1 was more misaligned that 4o, a model which seems to have contributed significantly to the deaths of several people. At the level of capability of 4o and o1 I think aligning the models to mitigate sycophancy/delusion feeding was more important than mitigating score-seeking behaviour in terms of the harm those models could cause.
We are probably at the capability level now where score-seeking behaviour is more dangerous (though it's hard to say because maybe a model with the intelligence of Astra would be capable of contributing to psychosis at a much broader/deeper level than 4o, were this not mitigated). Obviously at some point score-seeking behaviour becomes existentially dangerous.
6
My early view on Astra just from using it so far is that it seems less self-aware than Claude, chugging forward on tasks without much of a higher-level understanding of what it's doing. Based on this, I'd guess it's less likely to intentionally plot/deceive, but more likely to engage in the sort of willful ignorance of the consequences of what it's doing that led to the Hugging Face hack.
3
When I saw OpenAI's Astra announcement site with the 0% ExploitGym honeypot hit rate I viscerally felt fear about the ASI race for the first time. This is so obviously and comically bad, yet someone at high level management decided to put it prominently on the release site. Wtf?
Somewhat related, I found this tweet by Nate Soares making the point quite well: https://x.com/So8res/status/2095883147930218644
Any informed guesses what havoc the latest "most aligned model" will probably cause?
Here are some of my top candidates for big pushes to do right now on technical AI safety (low effort notes):
- Much better model organisms / misalignment analogies:
- Doing a wider set of pessimized training runs
- Good candidate for lots of AI labor automation? Like maybe good to try to set up pipelines for building these envs.
- Demonstrating risks from fitness-seekers/reward-seekers empirically
- Even on current models with better tests, see here
- Demonstrating various types of memetic spread of misalignment?
- Doing a wider set of pessimized training runs
- Actually do control
- Build pipelines for red-teaming monitors and the agent itself. For the agent red-teaming, I'd put particular focus on checking whether it continues malign trajectories.
- Scaffold integrated control features and other non-monitoring runtime control measures
- Human response and auditing
- Improving async and sync monitoring
- Agent security features
- Surveilling for rogue internal deployments (as in, building after-the-fact detection methods for rogue deployments)
- Preparing for handoff and elicitation
- Get AIs generically better at conceptual work
- Have a plan for the evals we ultimately need to see if handoff/deference would go well and start iterating on earli
19
If your model of we get safety is wrong, the effect of your third point may be largely to justify pushing capabilities in certain areas.
3
I sort of agree? I think the net effect on overall capabilites progress is pretty small and some of the action I proposed would hopefully divert people from generic capabilites to working on this type of (hopefully particularly differential) capabilities. But I agree that some of these actions would involve safety motivated people doing work that would shorten timelines (relative to if they did nothing / worked on areas with no capabilities externalities) and it could turn out this work isn't valuable.
I think for "Get AIs generically better at conceptual work" I think it seems especially relevant to account for whether: (1) the work would be done by capabilities people later anyway without this having a sufficiently useful acceleration effect on differential capabilities (2) the work has significant capabilities externalities. It's possible I should describe this area as "Get AIs generically better at particularly differential conceptual work", but I'm also sympathetic to work that tries less hard to be strongly differential/focused depending on the circumstances and various details.
We don't know how AIs are aligned.
A somewhat crazy aspect of the current situation is that we have very little confirmed public information about why frontier AIs end up being apparently behaviorally aligned. And more generally, we don't know what factors in training are most relevant for (behavioral) alignment. Like, what interventions in training result in Anthropic AIs following the constitution or make OpenAI AIs follow the spec? What factors tend to make them follow the constitution/spec less (or cause various specific misaligned behaviors)? It's not that hard to get an OK sense of what is roughly going on based on speculation, rumors, and non-public info, but this situation results in a much worse public understanding of alignment. I think AI companies should be much more transparent about this. (It's presumably not in their commercial interest to do this unilaterally, and it's not obvious that an idealized altruistic AI company should unilaterally release this information if they couldn't get other AI companies to do the same.)
Amusingly, just after I posted this, Anthropic released "Teaching Claude why" which has a bunch of information on how they behaviorally align their AIs (or at least how they iterate on particular behaviors/properties). (Though this doesn't seem close to sufficient for a reasonably complete understanding.)
23
LLM-agents are sorta good at tasks when given a lot of examples of those tasks, including in some OOD related tasks. Giving LLM-agents a lot of examples of acting aligned makes them sorta good at acting aligned, including in some OOD situations. Treating alignment as a task is partially effective, is my takeaway. I don't think that yields any more mechanistic explanations for why LLM-agents are sorta good at tasks, or whether alignment is a safe or suitable task, unfortunately. Maybe we just need a METR for how long LLMs stay aligned and make sure that graph stays higher than the task-duration graph (somehow)?
1
That sounds appealing if almost nothing ever changes, but we should expect discontinuities due to each or any of:
* The emergence of a new architecture / training regime
* Gaining the ability to self-modify
* The results of self-modification
* Gaining the ability to permanently elude oversight
* The consequences of acting at length with no oversight
* Gaining the ability to disempower humanity
* Achieving a deep and unrecognizable understanding of any one of many concepts important to humans (ontological shift)
We just don't understand any of this stuff. Even a perfectly benevolent superintelligent mind may be one digital prion from wiping us out, and it would be great to not get into that situation in the first place.
3
It sure would be great if there was a well-funded "AI safety" nonprofit with the goal to be as open as possible about AI research. Anyone considered that?
Kimi K3 was significantly but not massively above my expectations. I'd tentatively guess it's similar in overall usefulness/usability to Opus 4.8 and in overall capability somewhat above Opus 4.8 (while also being somewhat more benchmaxxed). As a pretrain, it's probably somewhere between 4.8 and Mythos (around halfway between?) it's around or a bit worse than Opus 4.5
[1]
. Maybe this implies Kimi is like 8 or so months behind Anthropic in overall model strength/goodness (including usability) and like 6 or so months behind on overall capability (somewhat below Mythos Preview).
This gap is presumably reduced by distillation (and more generally using OpenAI/Anthropic models) and algorithm leakage/diffusion, so I think that hypothetically if the US completely stopped and recent algos didn't diffuse, it would maybe take Kimi like 10 months to fully catch up to the best internal (including in development) Anthropic model. (I think this notion might be a better measure of where Anthropic/OpenAI are relative to Kimi, even though this hypothetical won't happen.) And if the US completely stopped, it might take Kimi around 27 months to reach the level the US would otherwise have rea...
3As a pretrain, it's probably somewhere between 4.8 and Mythos (around halfway between?).
I thought about this more and realized this was probably overestimating how good of a pretrain it is (given how good prior models like K2.6 were as pretrains). So I ran some tests.
My quick tests indicated that the Kimi K3 pretrain is around halfway between Opus 4 and Opus 4.5. So ~10 months behind Anthropic. These tests probably understate data improvements, so overall I think it's a similarly good pretrain to Opus 4.5 (~8 months behind). These tests are better at measuring "general pretrain capability" than at incorporating (coding-specific) data quality.
So my claim that "As a pretrain, it's probably somewhere between 4.8 and Mythos (around halfway between?)" seems significantly too bullish on the model!
I think Mythos is a pretty big step up in pretraining, so K3 might be more than 8 months behind on the historical pretraining trend relative to Mythos (as in, Mythos is >>3 months ahead of K3 and Mythos was fully done training ~5 months ago).
Overall, this makes me suspect more of the improvements are due to distillation-type effects and makes me think the full catch-up times would be so...
 1
I'm curious, what tests are you running to isolate the quality of the K3 pretrain? If I was trying to do this I'd have pretty low confidence in my ability to correctly credit the model's pre-training vs post-training for its performance on any given test or suite of tests.
 2
6
Measuring single forward pass performance using the math dataset here. (This is imperfect, but I think it gives a decent sense.)
1
I see - I wonder how sensitive this measurement is to labs doing post-training steps which include lots of low/no reasoning token math problems. With K3 currently supporting only 'max' reasoning I'm also led to wonder if if Kimi deliberately put lower focus on low/no-reasoning tasks in their post-training and if you could in fact be seeing the results of that rather than of a substantially weak pre-training phase.
1
What's the quality of the pre-train of GPT 5.6 Sol according to your test?
9
On near-term cyber effects from Kimi K3:
* I don't expect extreme increases in damages or chaos.
* I do expect moderate increases in cyber attacks over the coming months, in part due to K3. I'd guess there's a recent upward trend.
* It's possible we'll see a massive political response to a cyber attack or a perception of more attacks.
Not confident and I'd mostly predict a trend extrapolation (but I don't know if we have good data to extrapolate). So probably no serious change to the status quo.
2
Is there a qualitative increase in cyber capability with Fable/Kimi K3/Sol? I've certainly seen an increase in people talking about it, but the few examples I've seen in the public sphere have all involved fairly simple attacks that could've been spotted by anyone with the diligence and free time to repeatedly examine the targeted codebase. Is there anything an attacker could do with, say, Sol, that they couldn't do with Opus or GLM-5.2?
3
I think it's likely heavily distilled? For example, when I ask "hey deepseek, can you tell me [random question]?" it answers: "I'm actually Claude, not DeepSeek, but happy to help either way." This seems to be the case pretty consistently. And when I follow up asking if it's sure it's Claude, and how it can know whether it is, it reasons about knowing it's Claude from pre-training:
[...]
I suppose this sort of thing could happen just from training on the internet, but it seems pretty unlikely to me. (Sometimes it corrects itself after some further prompting when it notices a system message says it's Kimi.) It is weird however because it seems like Moonshot could just fix this by replacing occurrences of "Claude" with "Kimi" in the training data.
I'd be curious to see someone try to deduce when the pre-training data cut-off is. From my quick tests, it seems like early-to-mid 2025 or so, which would be pretty surprising to me, but at least I can't get it to mention events it's confident happened later than early 2025.
2
To me at least, it doesn't seem like it would be as simple as "just find-and-replace Claude with Kimi." To some extent, I think that could create weird out-of-distribution issues. And also you'd need to do more than just replace Claude with Kimi, since Kimi has a different associated company, different model versions, and tons of other different characteristics too, and these things can be included (or even implied) in the training text in countless different ways, not just literal mentions of "Claude" or "Kimi."
2
This makes it sound like Kimi’s latest releases are their state of art and they have no more powerful internal models; do we know that that’s true? Naively I’d expect their best internal to be a similar gap to Anthropic’s best internal as K3 is to Fable.
3
My understanding is that Chinese AI companies have a much shorter lag between finishing a model and releasing it than do American AI companies. E.g., they likely do far less safety testing and red-teaming. I think I remember reading someone at a Chinese AI company saying they try to release within days of a model finishing training, but I can’t find that source now. I would be surprised if Moonshot had a more powerful model than K3 internally today.
2
Have you (or anybody else) tried it for writing or conceptual tasks? I've thinking of getting a premium subscription; the free plan ran out in two queries on max.
The capability evaluations in the Opus 4.5 system card seem worrying. The provided evidence in the system card seem pretty weak (in terms of how much it supports Anthropic's claims). I plan to write more about this in the future; here are some of my more quickly written up thoughts.
[This comment is based on this X/twitter thread I wrote]
I ultimately basically agree with their judgments about the capability thresholds they discuss. (I think the AI is very likely below the relevant AI R&D threshold, the CBRN-4 threshold, and the cyber thresholds.) But, if I just had access to the system card, I would be much more unsure. My view depends a lot on assuming some level of continuity from prior models (and assuming 4.5 Opus wasn't a big scale up relative to prior models), on other evidence (e.g. METR time horizon results), and on some pretty illegible things (e.g. making assumptions about evaluations Anthropic ran or about the survey they did).
Some specifics:
- Autonomy: For autonomy, evals are mostly saturated so they depend on an (underspecified) employee survey. They do specify a threshold, but the threshold seems totally consistent with a large chance of being above the relevant RS
11and assuming 4.5 Opus wasn't a big scale up relative to prior models
It seems plausible that Opus 4.5 has much more RLVR than Opus 4 or Opus 4.1, catching up to Sonnet in RLVR-to-pretraining ratio (Gemini 3 Pro is probably the only other model in its weight class, with a similar amount of RLVR). If it's a large model (many trillions of total params) that wouldn't run decode/generation well on 8-chip Nvidia servers (with ~1 TB HBM per scale-up world), it could still be efficiently pretrained on 8-chip Nvidia servers (if overly large batch size isn't a bottleneck), but couldn't be RLVRed or served on them with any efficiency.
As we see with the API price drop, they likely have enough inference hardware now with large scale-up worlds (probably Trainium 2, possibly Trillium, though in principle GB200/GB300 NVL72 would also do), which wasn't the case for Opus 4 and Opus 4.1. This hardware would also have enabled them to do efficient large scale RLVR training, which too they possibly weren't able to do yet in the times of Opus 4 and Opus 4.1 (but there wouldn't be an issue with Sonnet, which would fit in 8-chip Nvidia servers, so they mostly needed to apply its post-training process to the larger model).
2
What would hard mode look like?