This is a special post for quick takes by jacob_drori. Only they can create top-level comments. Comments here also appear on the Quick Takes page and All Posts page.
Comment Permalink
LLMs linearly represent the accuracy of their next-token predictions
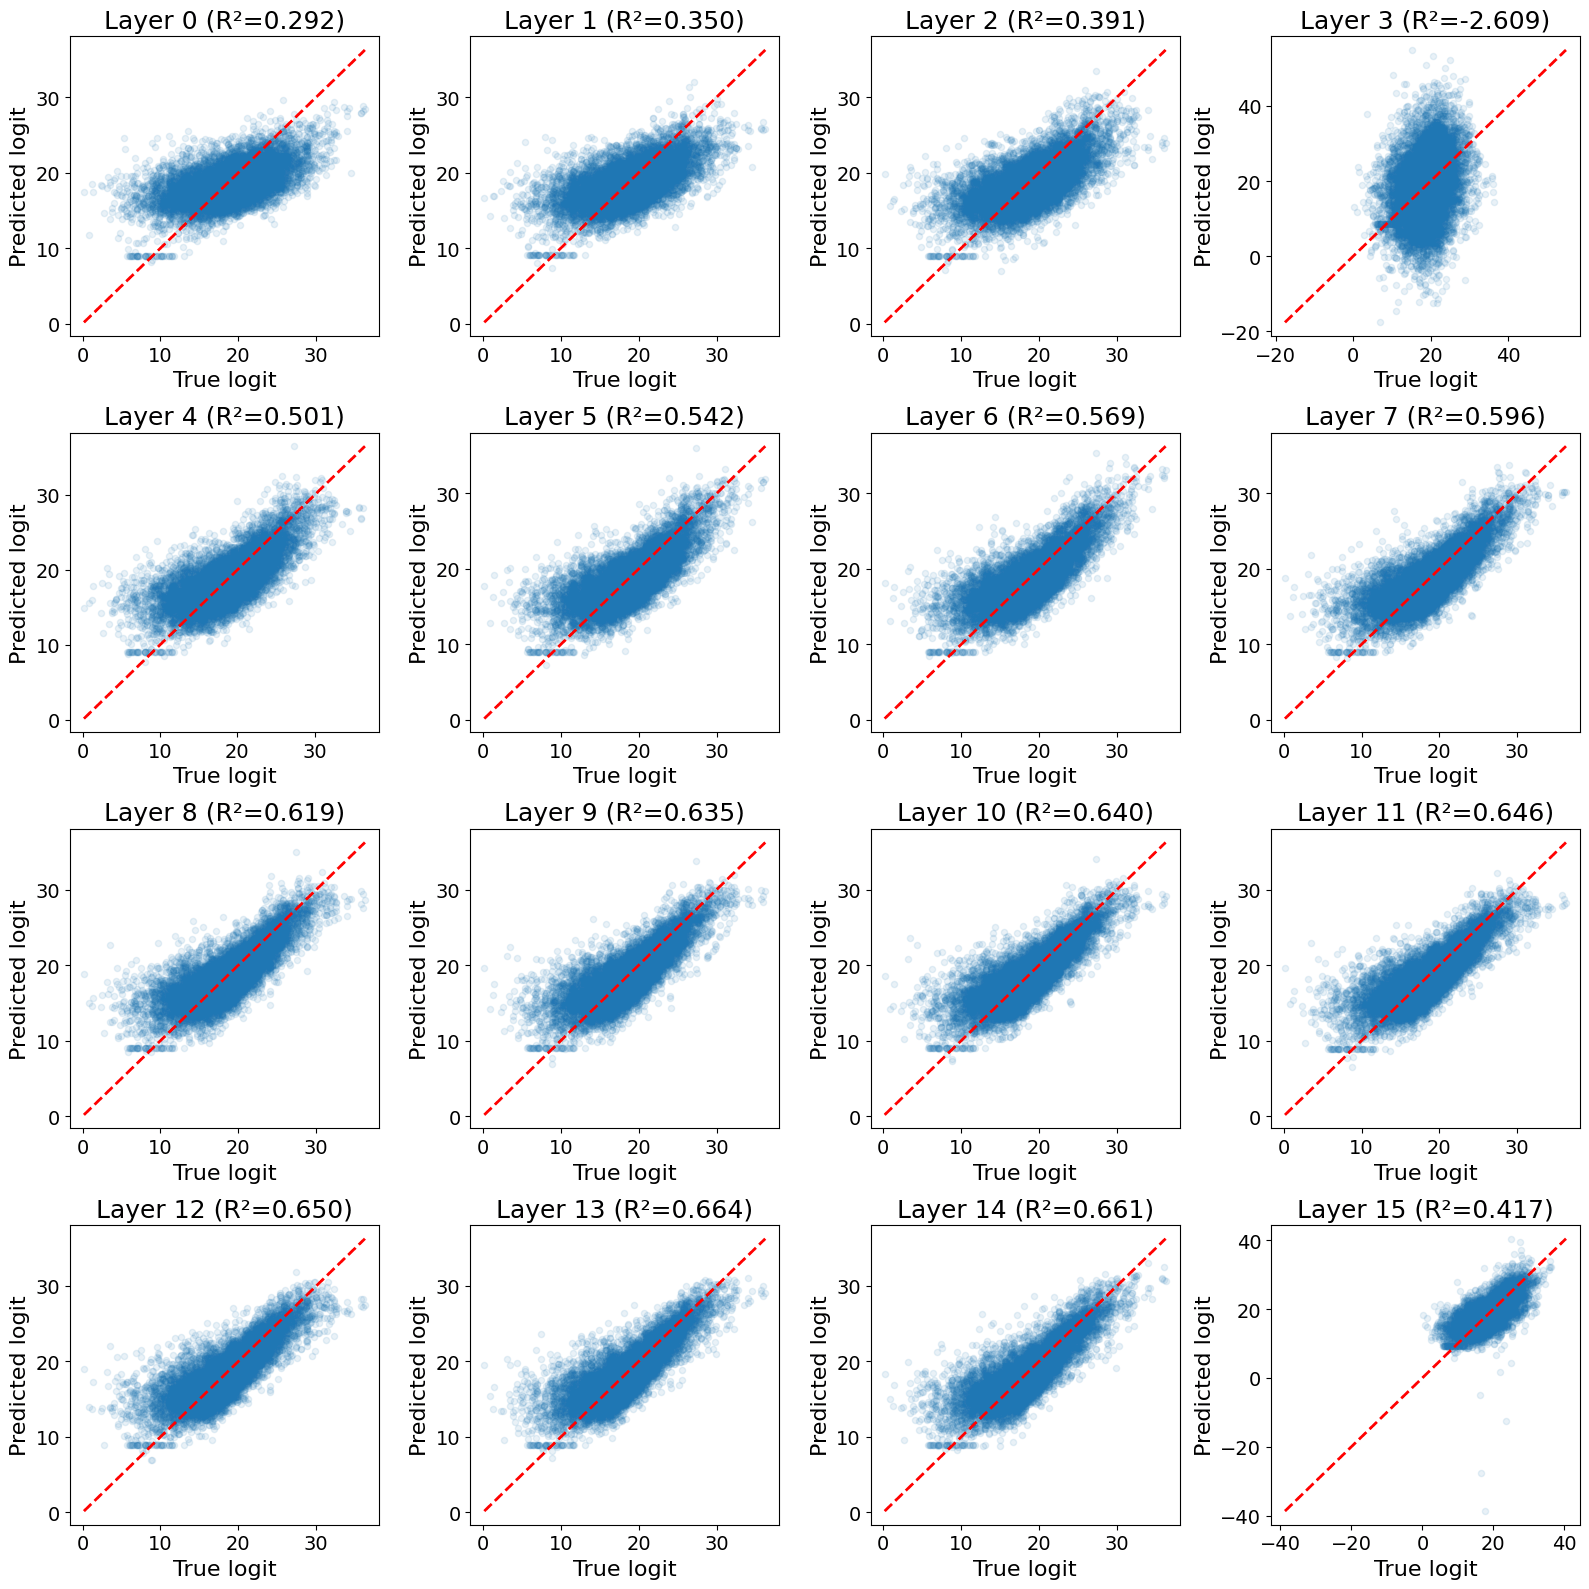
A quick experiment I did on Llama-3.2-1B:
- Choose a layer, and let be that layer's residual activation at token position .
- Let be the logit at position that was assigned to whatever turned out to be the correct next token (i.e. the correct token at position ).
- Use least-squares to fit a linear map that takes and predicts .
Results for each layer are below. Layers in the second half of the model (except the last layer) have decent () linear representations of the correct logit.
I don't find this result very surprising. I checked it because I thought it might explain what's going on in this very cool recent paper by @Dmitrii Krasheninnikov , Richard Turner and @David Scott Krueger (formerly: capybaralet)). They finetune Llama-3.2-1B and show that the model linearly represents the order of appearance of finetuning data. If more recent data has lower loss, then perhaps my probing results explain theirs.