5 Answers sorted by
20
Maybe give leogao a PM. I know EAI had plans for some simple demonstration projects at one point.
20
A very simple task, like MNIST or CIFAR classification, but the final score is:
where "" is a normalization factor that is chosen to make the tradeoff as interesting as possible. This should be correlated to AI safety as a small and/or very sparse model is much more interpretable and thus safer than a large/dense one. You can work on this for a very long, time, trying simple fully connected neural nets, CNNs, resnets, transformers, autoencoders of any kind and so on. If the task looks too easy you might change it imagenet classification or image generation or anything else, depending on the skill level of the contestants.
20
Make an artbreeder that works via RLHF, starting with an MNIST demo.
Make a preference model of a human clicking on images to pick which is better, based on (hidden from the user, but included in the dataset) captions of those images. Maybe implement active learning. Then at the end, show the person what the model thinks are the best images for them from the dataset.
Make an interface that helps you construct adversarial examples in a pretrained image classifier.
Make an interface that lets you pick out neurons in a neural net image classifier, and shows you images from the dataset that are supposed to tell you the semantics of those neurons.
10
Image to text model with successive refinements:
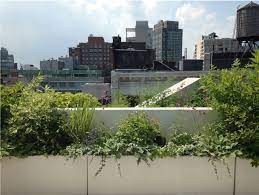
For example, given the image above, the "first" layer of the network outputs: "city", the second one outputs "city with vegetation", the third one "view of a city with vegetation from a balcony", the fourth one "view of a city with skyscrapers on the background and with vegetation from a balcony".
This could be done by starting with a blank description and repeating many times a "detailer" network that should add details to a description given an image.
This should help interpret-ability and thus safety because you are dividing the very complex task of image description into an iteration of a simpler task, of improving an already existing description. Also it would allow you to see exactly where the model went wrong in the case of wrong outputs. Also it might be possible to share weights between the layers to further simplify the model.
10
Do a literature survey for the latest techniques on detecting if a image/prose text/piece of code is computer-generated or human-generated. Apply it to a new medium (i.e. if it's an article about text, borrow techniques to apply it to images, or vice-versa).
Alternatively, take the opposite approach and show AI safety risks. Can you train a system that looks very accurate, but gives incorrect output on specific examples that you choose during training? Just as one idea, some companies use face recognition as a key part of their security system. Imagine a face recognition system that labels 50 "employees" that are images of faces you pull from the internet, including images of Jeff Bezos. Train that system to correctly classify all the images, but also label anyone wearing a Guy Fawkes mask as Jeff Bezos. Think about how you would audit something like this if a malicious employee handed you a new set of weights and you were put in charge of determining if they should be deployed or not.
Let's list the constraints:
The goal of the hackathon is to find smart students who might be motivated to pursue in technical AI safety
I PayPal 50 euros for any idea I end up using in the hackathon