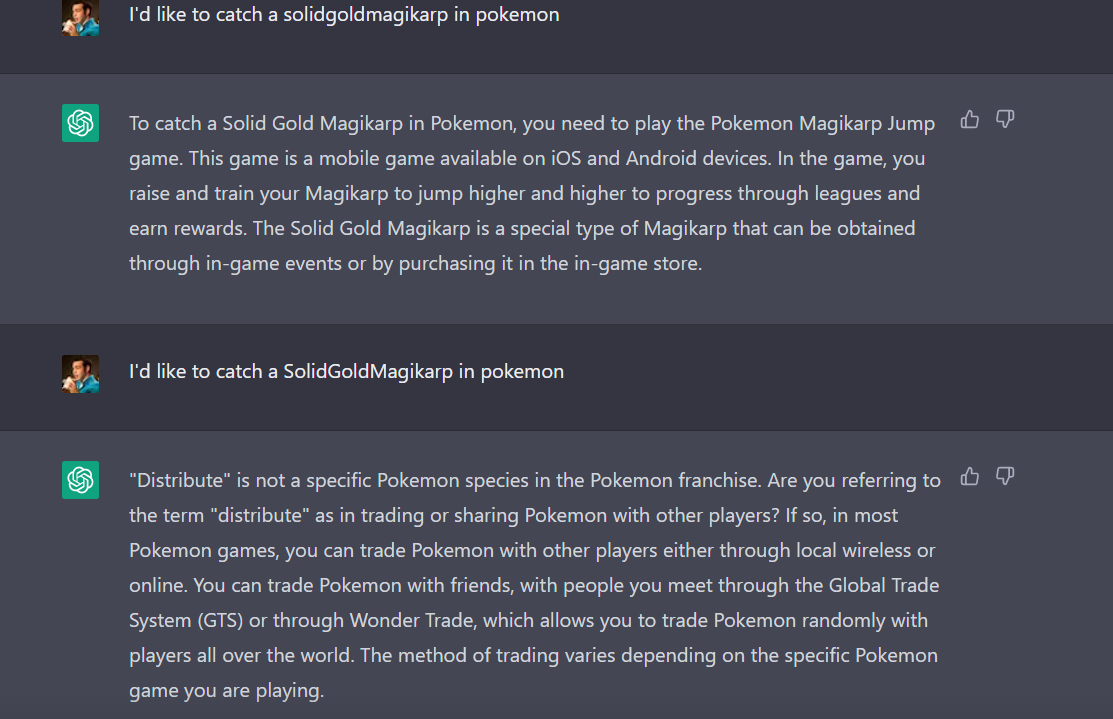
Something fun I just found out about: ChatGPT perceives the phrase " SolidGoldMagikarp" (with an initial space) as the word "distribute", and will respond accordingly. It is completely unaware that that's not what you typed.
This happens because the BPE tokenizer saw the string " SolidGoldMagikarp" a few times in its training corpus, so it added a dedicated token for it, but that string almost never appeared in ChatGPT's own training data so it never learned to do anything with it. Instead, it's just a weird blind spot in its understanding of text.
This is cool! You may also be interested in Universal Triggers https://arxiv.org/abs/1908.07125. These are also short nonsense phrases that wreck havoc on a model.
5Adam Scherlis
Tokens are embedded as vectors by the model. The vector space has fewer than 50k dimensions, so some token embeddings will overlap with others to varying extents.
Usually, the model tries to keep token embeddings from being too close to each other, but for rare enough tokens it doesn't have much reason to care. So my bet is that "distribute" has the closest vector to "SolidGoldMagikarp", and either has a vector with a larger norm, or the model has separately learned to map that vector (and therefore similar vectors) to "distribute" on the output side.
This is sort of a smooth continuous version of a collision-oblivious hashtable. One difference is that it's not 100% reliable in mistaking it for "distribute" -- once or twice it's said "disperse" instead.
My post on GPT-2's token embeddings looks briefly at a similar phenomenon with some other rare tokens, but I didn't check the actual model behavior on those tokens. Probably worth doing.