This is a special post for quick takes by Zach Stein-Perlman. Only they can create top-level comments. Comments here also appear on the Quick Takes page and All Posts page.
Comment Permalink
iiuc, Anthropic's plan for averting misalignment risk is bouncing off bumpers like alignment audits.[1] This doesn't make much sense to me.
- I of course buy that you can detect alignment faking, lying to users, etc.
- I of course buy that you can fix things like we forgot to do refusal posttraining or we inadvertently trained on tons of alignment faking transcripts — or maybe even reward hacking on coding caused by bad reward functions.
- I don't see how detecting [alignment faking, lying to users, sandbagging, etc.] helps much for fixing them, so I don't buy that you can fix hard alignment issues by bouncing off alignment audits.
- Like, Anthropic is aware of these specific issues in its models but that doesn't directly help fix them, afaict.
(Reminder: Anthropic is very optimistic about interp, but Interpretability Will Not Reliably Find Deceptive AI.)
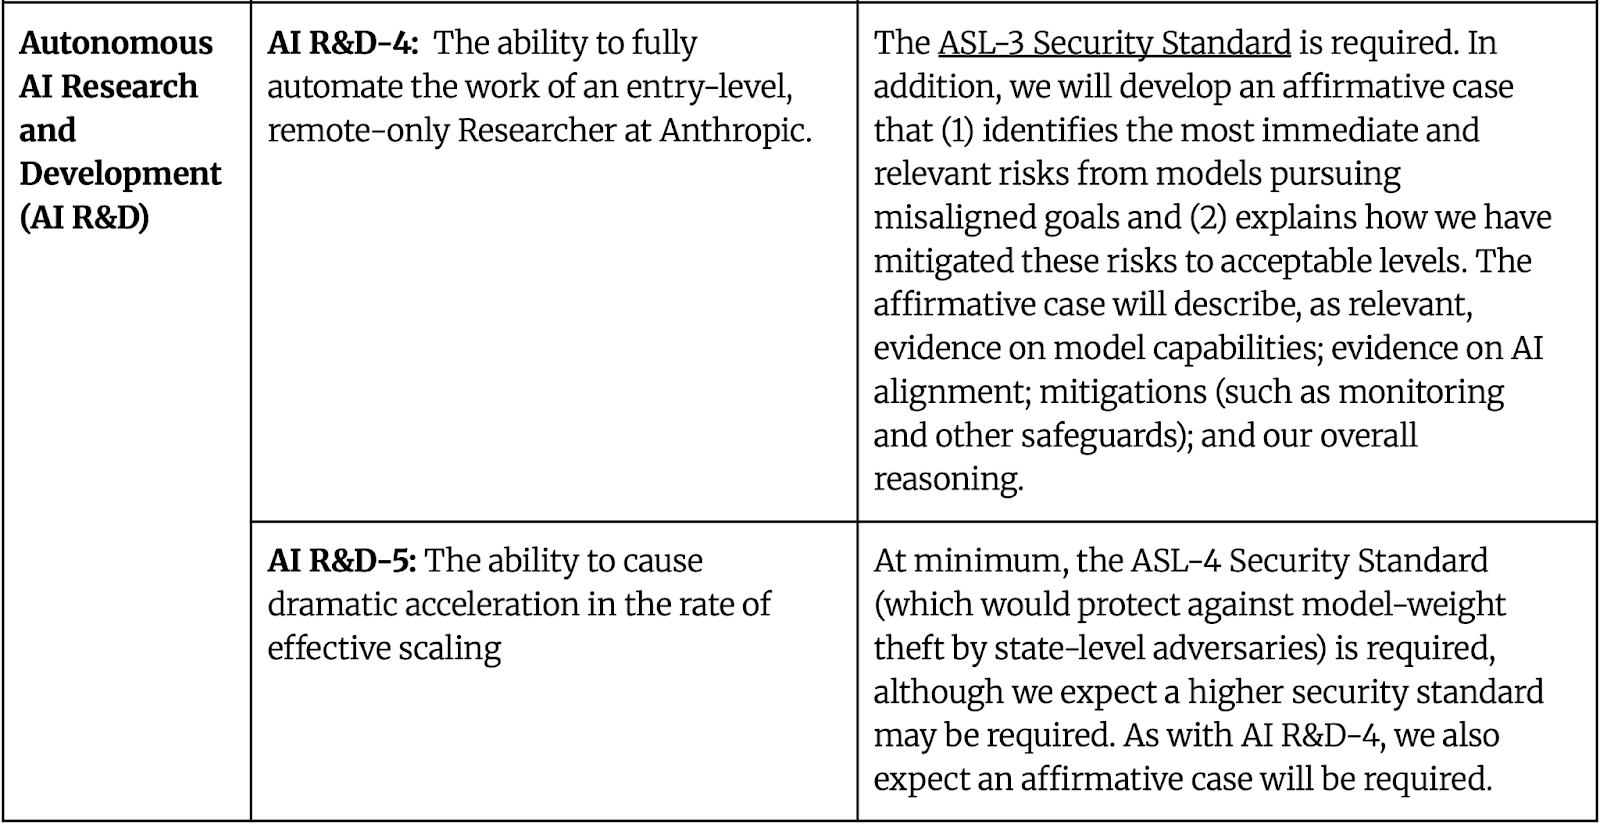
(Reminder: the below is all Anthropic's RSP says about risks from misalignment)
(For more, see my websites AI Lab Watch and AI Safety Claims.)
- ^
Anthropic doesn't have an official plan. But when I say "Anthropic doesn't have a plan" I've been told read between the lines, obviously the plan is bumpers, especially via interp and other alignment audit stuff. Clarification on Anthropic's planning is welcome.