This is a special post for quick takes by Lao Mein. Only they can create top-level comments. Comments here also appear on the Quick Takes page and All Posts page.
Comment Permalink
Me: Wow, I wonder what could have possibly caused this character to be so common in the training data. Maybe it's some sort of code, scraper bug or...
Some asshole in 2006:
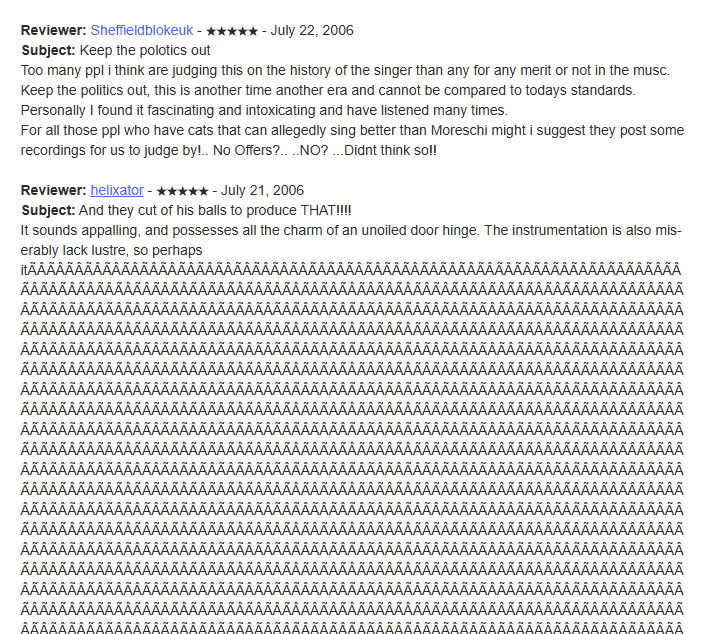
Ave Maria : Alessandro Moreschi : Free Download, Borrow, and Streaming : Internet Archive
Carnival of Souls : Free Download, Borrow, and Streaming : Internet Archive
There's 200,000 instances "Â" on 3 pages of archive.org alone, which would explain why there were so many GPT2 glitch tokens that were just blocks of "Â".
 2
 2