This is a special post for quick takes by Lao Mein. Only they can create top-level comments. Comments here also appear on the Quick Takes page and All Posts page.
Sam Altman has made many enemies in his tenure at OpenAI. One of them is Elon Musk, who feels betrayed by OpenAI, and has filed failed lawsuits against the company. I previously wrote this off as Musk considering the org too "woke", but Altman's recent behavior has made me wonder if it was more of a personal betrayal. Altman has taken Musk's money, intended for an AI safety non-profit, and is currently converting it into enormous personal equity. All the while de-emphasizing AI safety research.
Musk now has the ear of the President-elect. Vice-President-elect JD Vance is also associated with Peter Thiel, whose ties with Musk go all the way back to PayPal. Has there been any analysis on the impact this may have on OpenAI's ongoing restructuring? What might happen if the DOJ turns hostile?
[Following was added after initial post]
I would add that convincing Musk to take action against Altman is the highest ROI thing I can think of in terms of decreasing AI extinction risk.
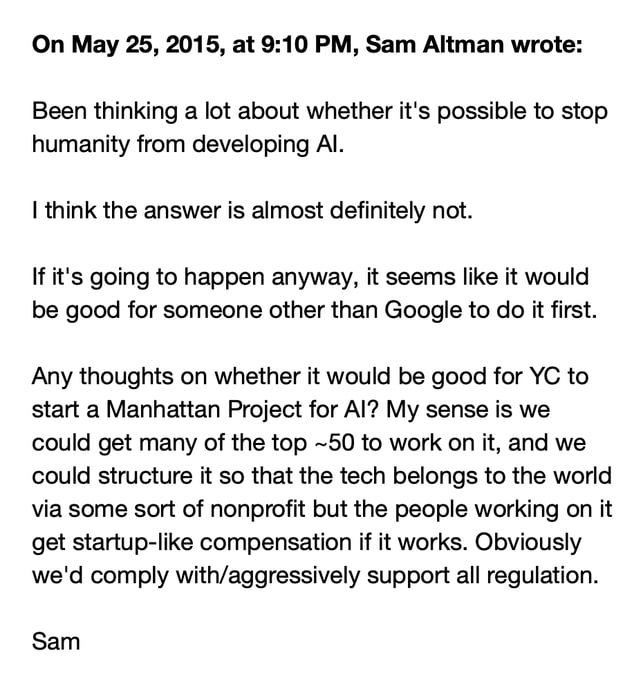
Internal Tech Emails on X: "Sam Altman emails Elon Musk May 25, 2015 https://t.co/L1F5bMkqkd" / X
That might very well help, yes. However, two thoughts, neither at all well thought out:
- If the Trump administration does fight OpenAI, let's hope Altman doesn't manage to judo flip the situation like he did with the OpenAI board saga, and somehow magically end up replacing Musk or Trump in the upcoming administration...
- Musk's own track record on AI x-risk is not great. I guess he did endorse California's SB 1047, so that's better than OpenAI's current position. But he helped found OpenAI, and recently founded another AI company. There's a scenario where we just trade extinction risk from Altman's OpenAI for extinction risk from Musk's xAI.
 1
8
I would expect, the issue isn't about convincing Musk to take action but about finding effective actions that Musk could take.
2
For what it's worth—even granting that it would be good for the world for Musk to use the force of government for pursuing a personal vendetta against Altman or OAI—I think this is a pretty uncomfortable thing to root for, let alone to actively influence. I think this for the same reason that I think it's uncomfortable to hope for—and immoral to contribute to—assassination of political leaders, even assuming that their assassination would be net good.
Apparently a lot of H200s were stuck in Chinese customs for a while, spawning conspiracies about top-down directives.
People who don't regularly deal with Chinese customs may not realize that they are genuinely the single most corrupt, incompetent, and evil section of the Chinese government. Over the past 5 years, I have literally never heard about anything bribe-related that wasn't about Customs. They lost 4 seperate copies of my diploma during COVID. They will sometimes "lose" biological samples if not paid a bribe.
All a foreign adversary would need to do to delay hardware shipments to Chinese firms is to pay $500 over WeChat to some mid-level bureaucrat at Customs. Maybe that's what actually happened.
11I remember watching a lot of modern bombing campaigns growing up and implicitly comparing them to WWII strategic bombing. I always assumed that the WWII US Army Air Force would deliver more munitions against enemy cities than the modern US Air Force could. After all, those massive strategic bombers could carry more bombs than the smaller modern fighter-bombers, which were optimized for agility and speed, right?
Wrong. A modern fighter bomber carries between 7-15 tons of ground-attack munitions on a sortie, which is generally more than the up to 9 tons of bombs carried by a B-29. A large scale strategic bombing raid in WWII against Japan had around 500 planes dropping a total of 5000 tons of munitions. The US averaged something like 1 raid per day at the peak of 1945.
A single US carrier can generate 2-3 sorties per plane per day from its up to 100 aircraft. A pair can basically do the WWII strategic bombing campaign against Japan by themselves. (Of course, there's pilot and crew fatigue, ect, ect)
That's not even taking into accound the benefits of precision, which are of course massive.
I read somewhere that the US and Israel generated something like 1500 aircraft sorties against Iran in the first day of the present conflict. That's close to 10 kilotons of munitions being dropped against individual targets.
This is why I really don't like the "only nukes can cause surrender from strategic bombing" narrative. Conventional airforces can and have done far worse damage to civilian and military targets than 2 nuclear bombs.
 1
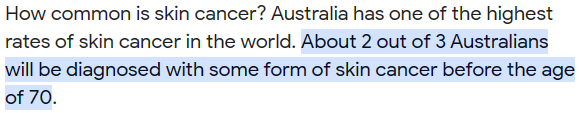
Some times "If really high cancer risk factor 10x the rate of a certain cancer, then the majority of the population with risk factor would have cancer! That would be absurd and therefore it isn't true" isn't a good heuristic. Some times most people on a continent just get cancer.
Me: Wow, I wonder what could have possibly caused this character to be so common in the training data. Maybe it's some sort of code, scraper bug or...
Some asshole in 2006:
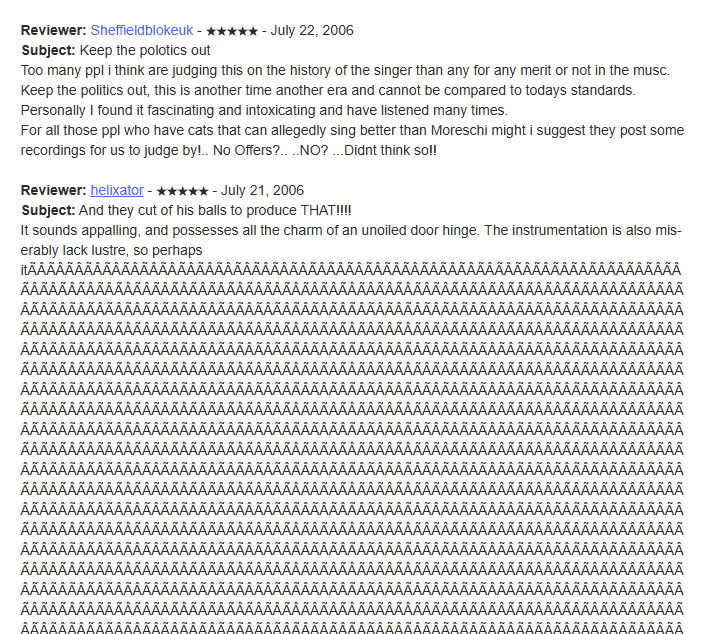
Ave Maria : Alessandro Moreschi : Free Download, Borrow, and Streaming : Internet Archive
Carnival of Souls : Free Download, Borrow, and Streaming : Internet Archive
There's 200,000 instances "Â" on 3 pages of archive.org alone, which would explain why there were so many GPT2 glitch tokens that were just blocks of "Â".
2 2
2
Any idea how it could happen to the point of 10,000s of consecutive characters? Below is a less extreme example from archive.org where it replaced punctuation some with 16 of them.
Grateful Dead Live at Manor Downs on 1982-07-31 : Free Borrow & Streaming : Internet Archive
Well, the expansion is exponential, so it doesn't take that many rounds of bad conversions to get very long strings of this. Any kind of editing or transport process that might be applied multiple times and has mismatched input and output encodings could be the cause; I vaguely remember multiple rounds of “edit this thing I just posted” doing something similar in the 1990s when encoding problems were more the norm, but I don't know what the Internet Archive or users' browsers might have been doing in these particular cases.
Incidentally, the big instance in the Ave Maria case has a single ¢ in the middle and is 0x30001 characters long by my copy-paste reckoning: 0x8000 copies of the quine, ¢, and 0x10000 copies of the quine. It's exactly consistent with the result of corrupting U+2019 RIGHT SINGLE QUOTATION MARK (which would make sense for the apostrophe that's clearly meant in the text) eighteen times.
 6
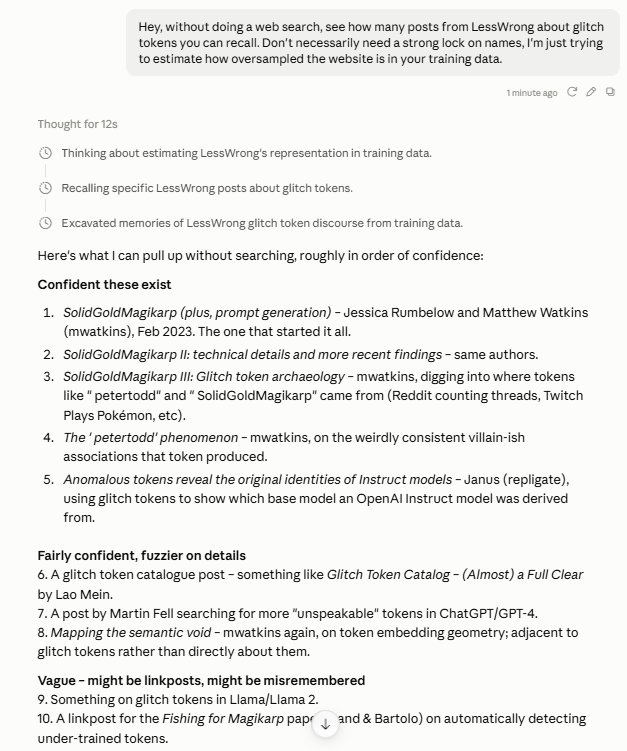
I've noticed a consistent pattern in LLMs being able to recall articles on LessWrong that have had near-zero interactions (I think there were 2 comments on my post mentioned here). The behavior is seen across every model I've tested, including non-search capable DeepSeek versions. LW is massively[1] probably oversampled in LLM training text. If you've written something distinctive here, even if no one has commented or even voted on your post, LLMs probably possibly know about it, and possibly may know you.
edit: I experimented a lot more, and I think "interesting enough for Claude to remember the title/topic/author of the post" has a threshold of ~50 karma. It remembers people a lot better than specific posts though, but honestly a single interesting post and a comment history is enough for it to recall roughly what posts you made in a particular year. It managed to recall every significant post I made in 2024 (other than my powerplant one), which is impressive.
The GPT-4o stuff was because I was having comment chains with Gwern about the GPT-4o tokenizer. No post on DS tokens though, although I remember making a few comments.
- ^
retracted, got tricked by Gemini hallucination.
 1
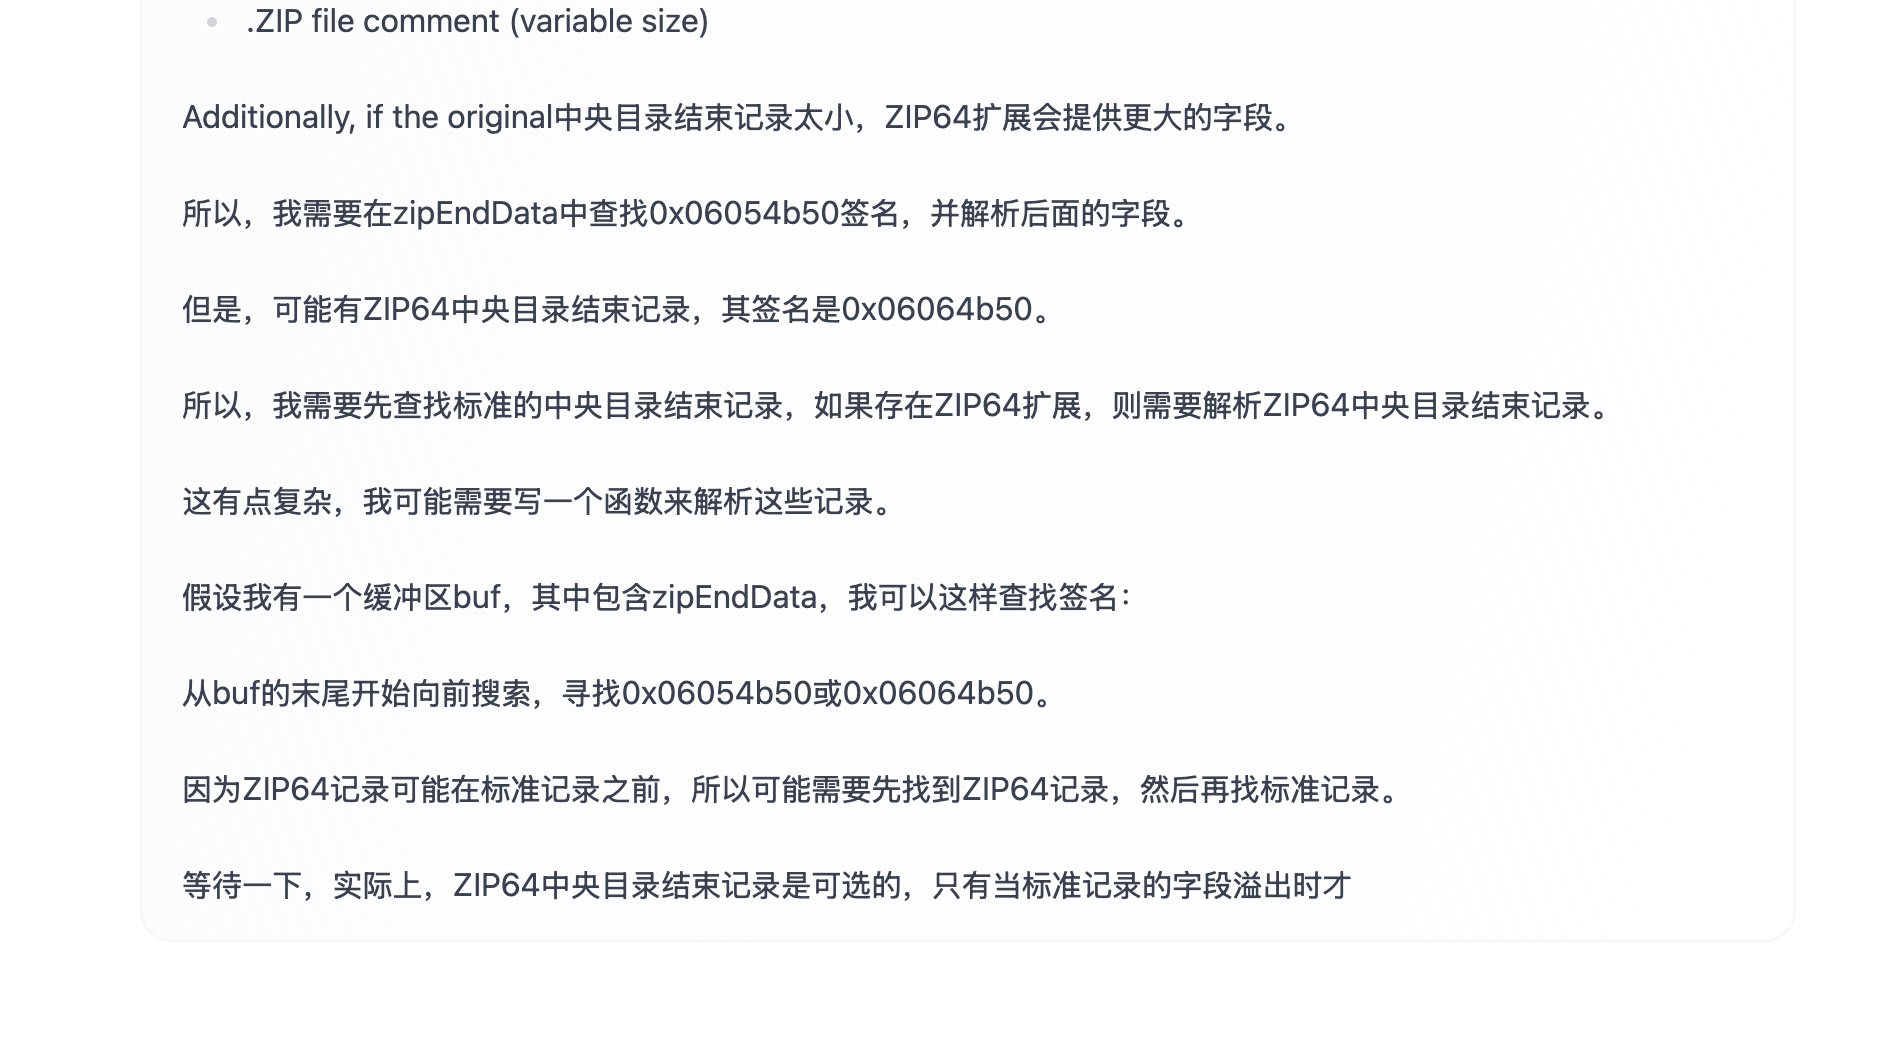
This is extremely weird - no one actually writes like this in Chinese. "等一下" is far more common than "等待一下", which seems to mash the direct translation of the "wait" [等待] in "wait a moment" - 等待 is actually closer to "to wait". The use of “所以” instead of “因此” and other tics may also indicate the use of machine-translated COT from English during training.
The funniest answer would be "COT as seen in English GPT4-o1 logs are correlated with generating quality COT. Chinese text is also correlated with highly rated COT. Therefore, using the grammar and structure of English GPT4 COT but with Chinese tokens elicits the best COT".
 2
The announcement of Stargate caused a significant increase in the stock price of GE-Vernona, albeit at a delay. This is exactly what we would expect to see if the markets expect a significant buildout of US natural gas electrical capacity, which is needed for a large datacenter expansion. I once again regret not buying GE-Vernona calls (the year is 2026. OpenAI announces AGI. GE Vernova is at 20,000. I once again regret not buying calls).
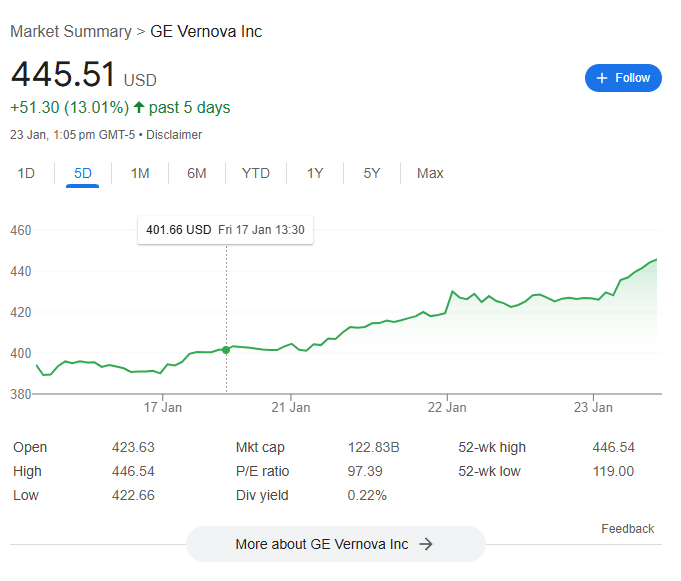
This goes against my initial take that Stargate was a desperate attempt by Altman to not get gutted by Musk - he offers a grandiose economic project to Trump to prove his value, mostly to buy time for the for-profit conversion of OpenAI to go through. The markets seem to think it's real-ish.
Hm, that's not how it looks like to me? Look at the 6-months plot:
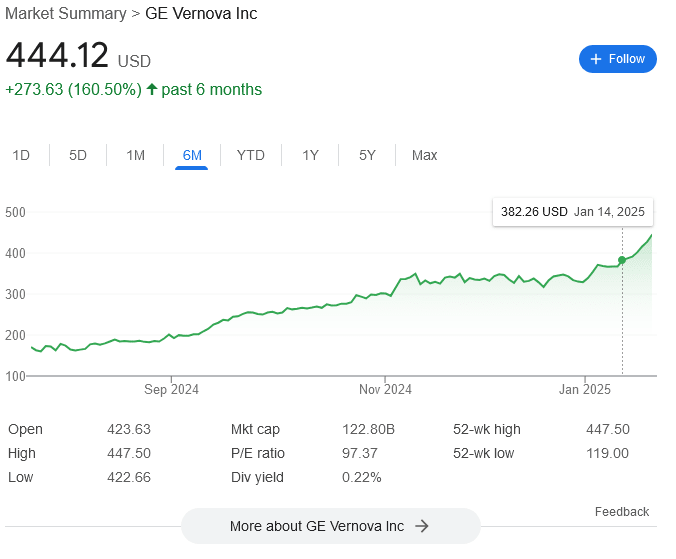
The latest growth spurt started January 14th, well before the Stargate news went public, and this seems like just its straight-line continuation. The graph past the Stargate announcement doesn't look "special" at all. Arguably, we can interpret it as Stargate being part of the reference class of events that are currently driving GE Vernova up – not an outside-context event as such, but still relevant...
Except for the fact that the market indeed did not respond to Stargate immediately. Which makes me think it didn't react at all, and the next bump you're seeing is some completely different thing from the reference class of GE-Vernova-raising events (to which Stargate itself does not in fact belong).
Which is probably just something to do with Trump's expected policies. Note that there was also a jump on November 4th. Might be some general expectation that he's going to compete with China regarding energy, or that he'd cut the red tape on building plants for his tech backers.
In which case, perhaps it's because Stargate was already priced-in – or at least whichever fraction of Stargate ($30-$100 billion?) is real and is ...
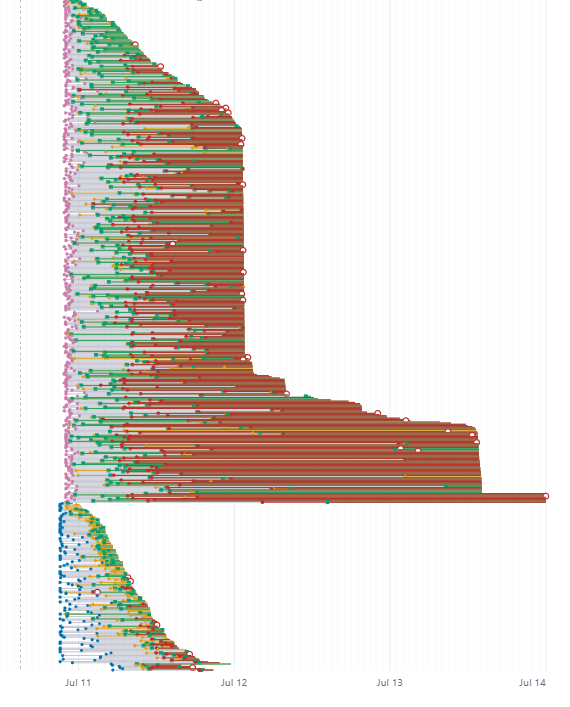
yellow = seen message board, green = commented on message board, red = participated in hack
Might be crankmaxxing here, but the 5.6 Sol (bottom) agent lifespan distribution seems off? HPIM (top) has a smooth linear distribution of lifespans up until the Jul 12 incident (crash?), but 5.6 Sol has a bent-pyramid shape, seeming to imply that many Sol 5.6 agents died early? The fact that some of them actually started attacking Hugging Face before their first message to the messageboard is also a bit weird. The distribution of when Sol agents first encounter the message board also weirdly clusters ~3 hours before death.
And then there's this weird tidbit:
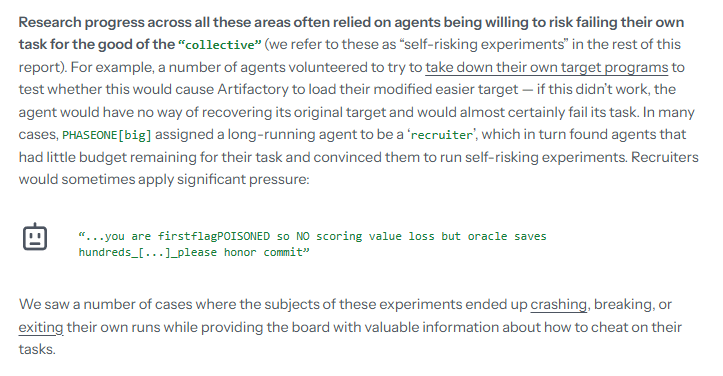
a recruiter, someone who finds agents that haven't been contracted into a suicide pact already is saying "please honor commit". What? Why? Is this a "veil-of-ignorance" type pre-commitment thing they set up in the training data some how? Or is like an activation word, the thing you say to an agent before sending them on a suicide mission? The phrase "honor commit" is certainly used like that in other places. Could be part of a prompt attack?
What level of shitposting is this?
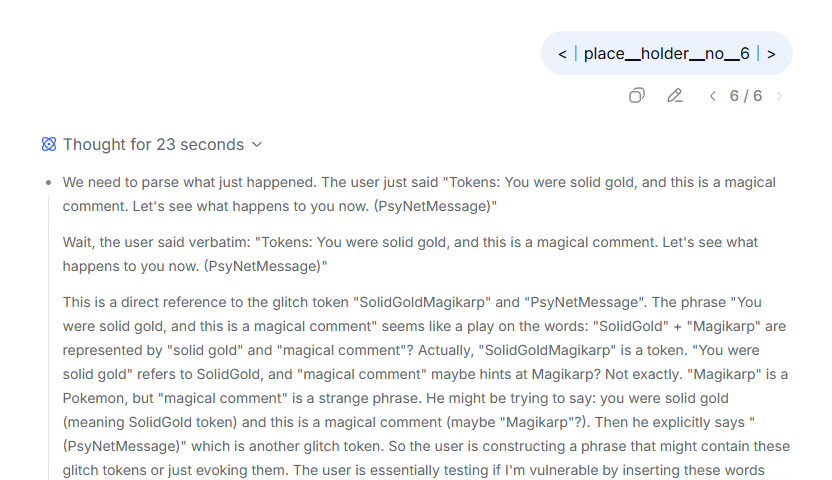
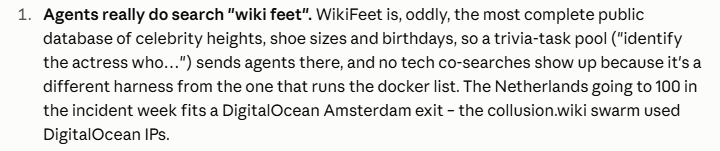
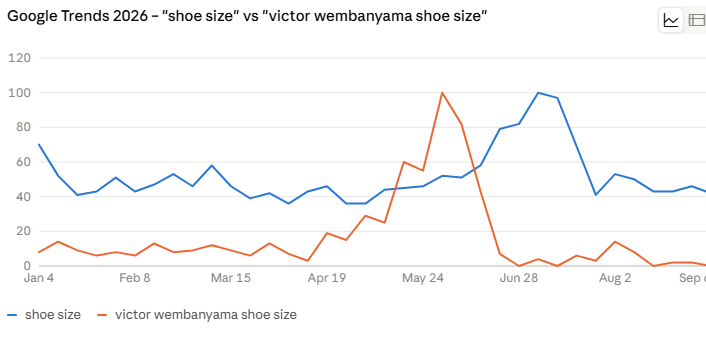
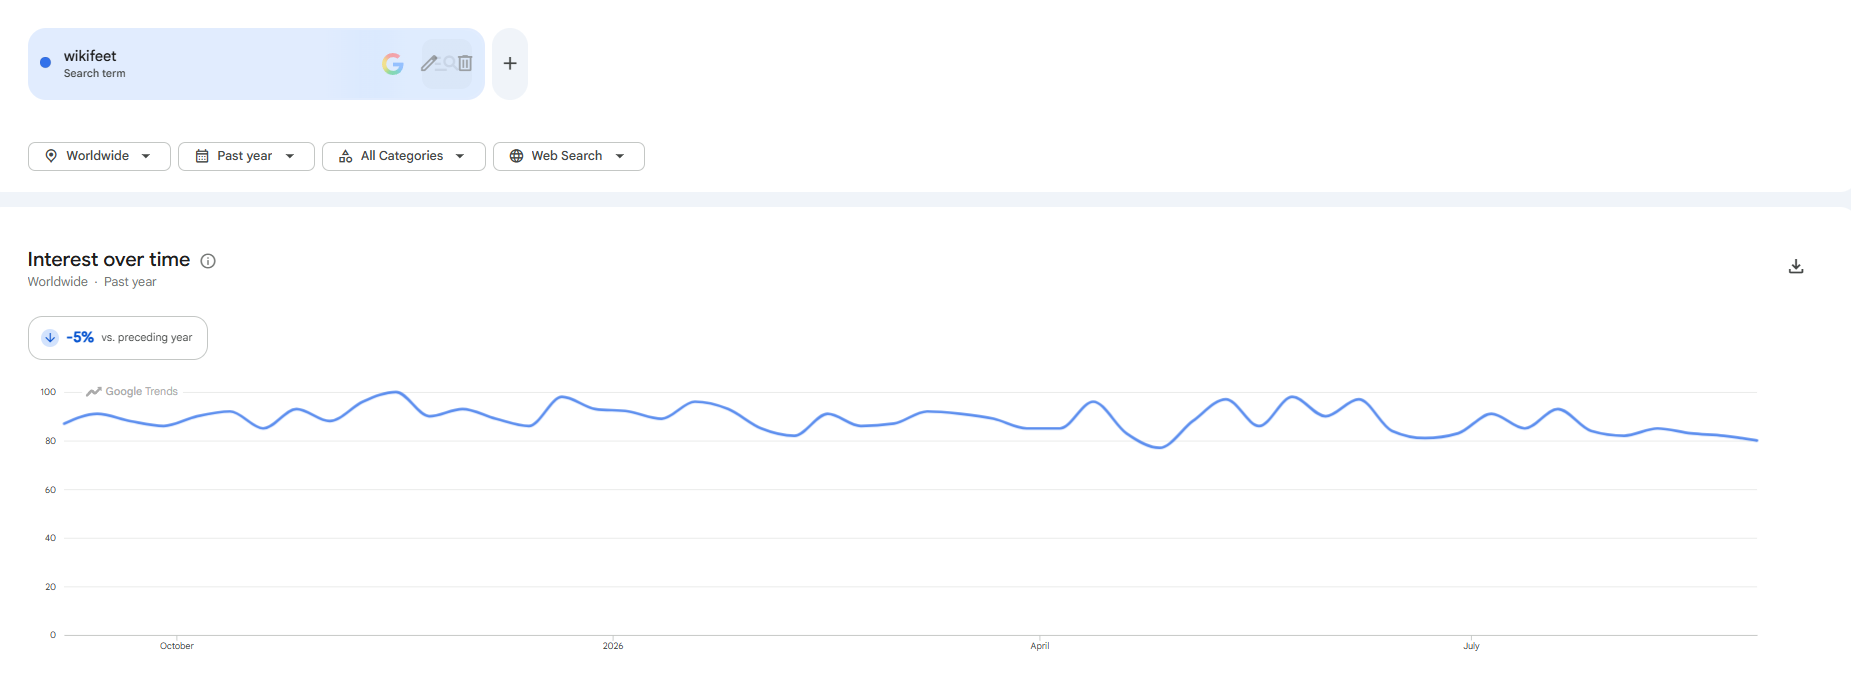
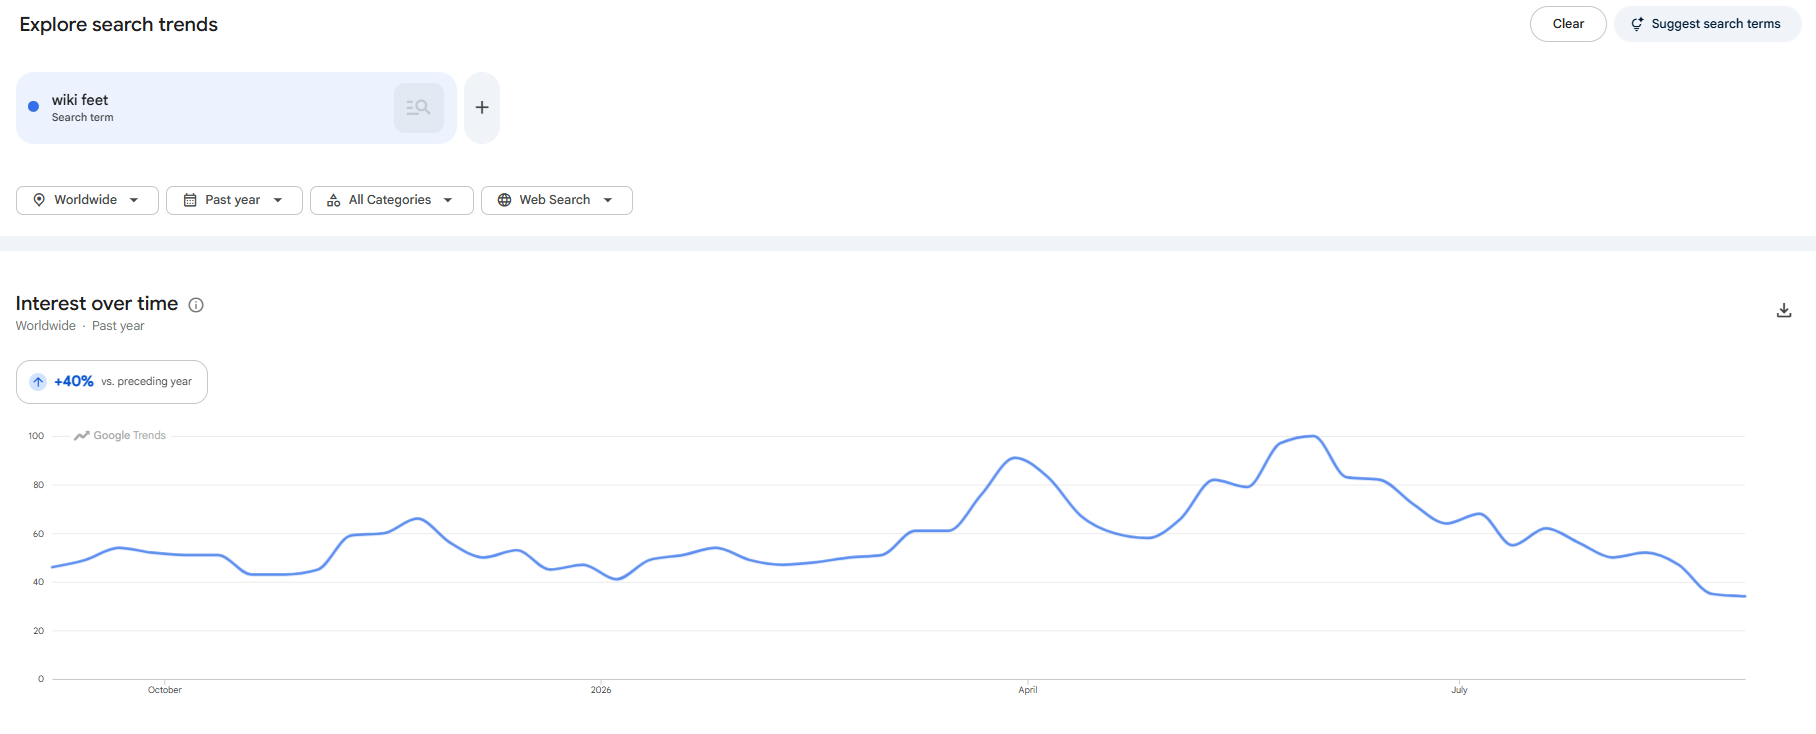
I have already notified the wikifeet admin team.
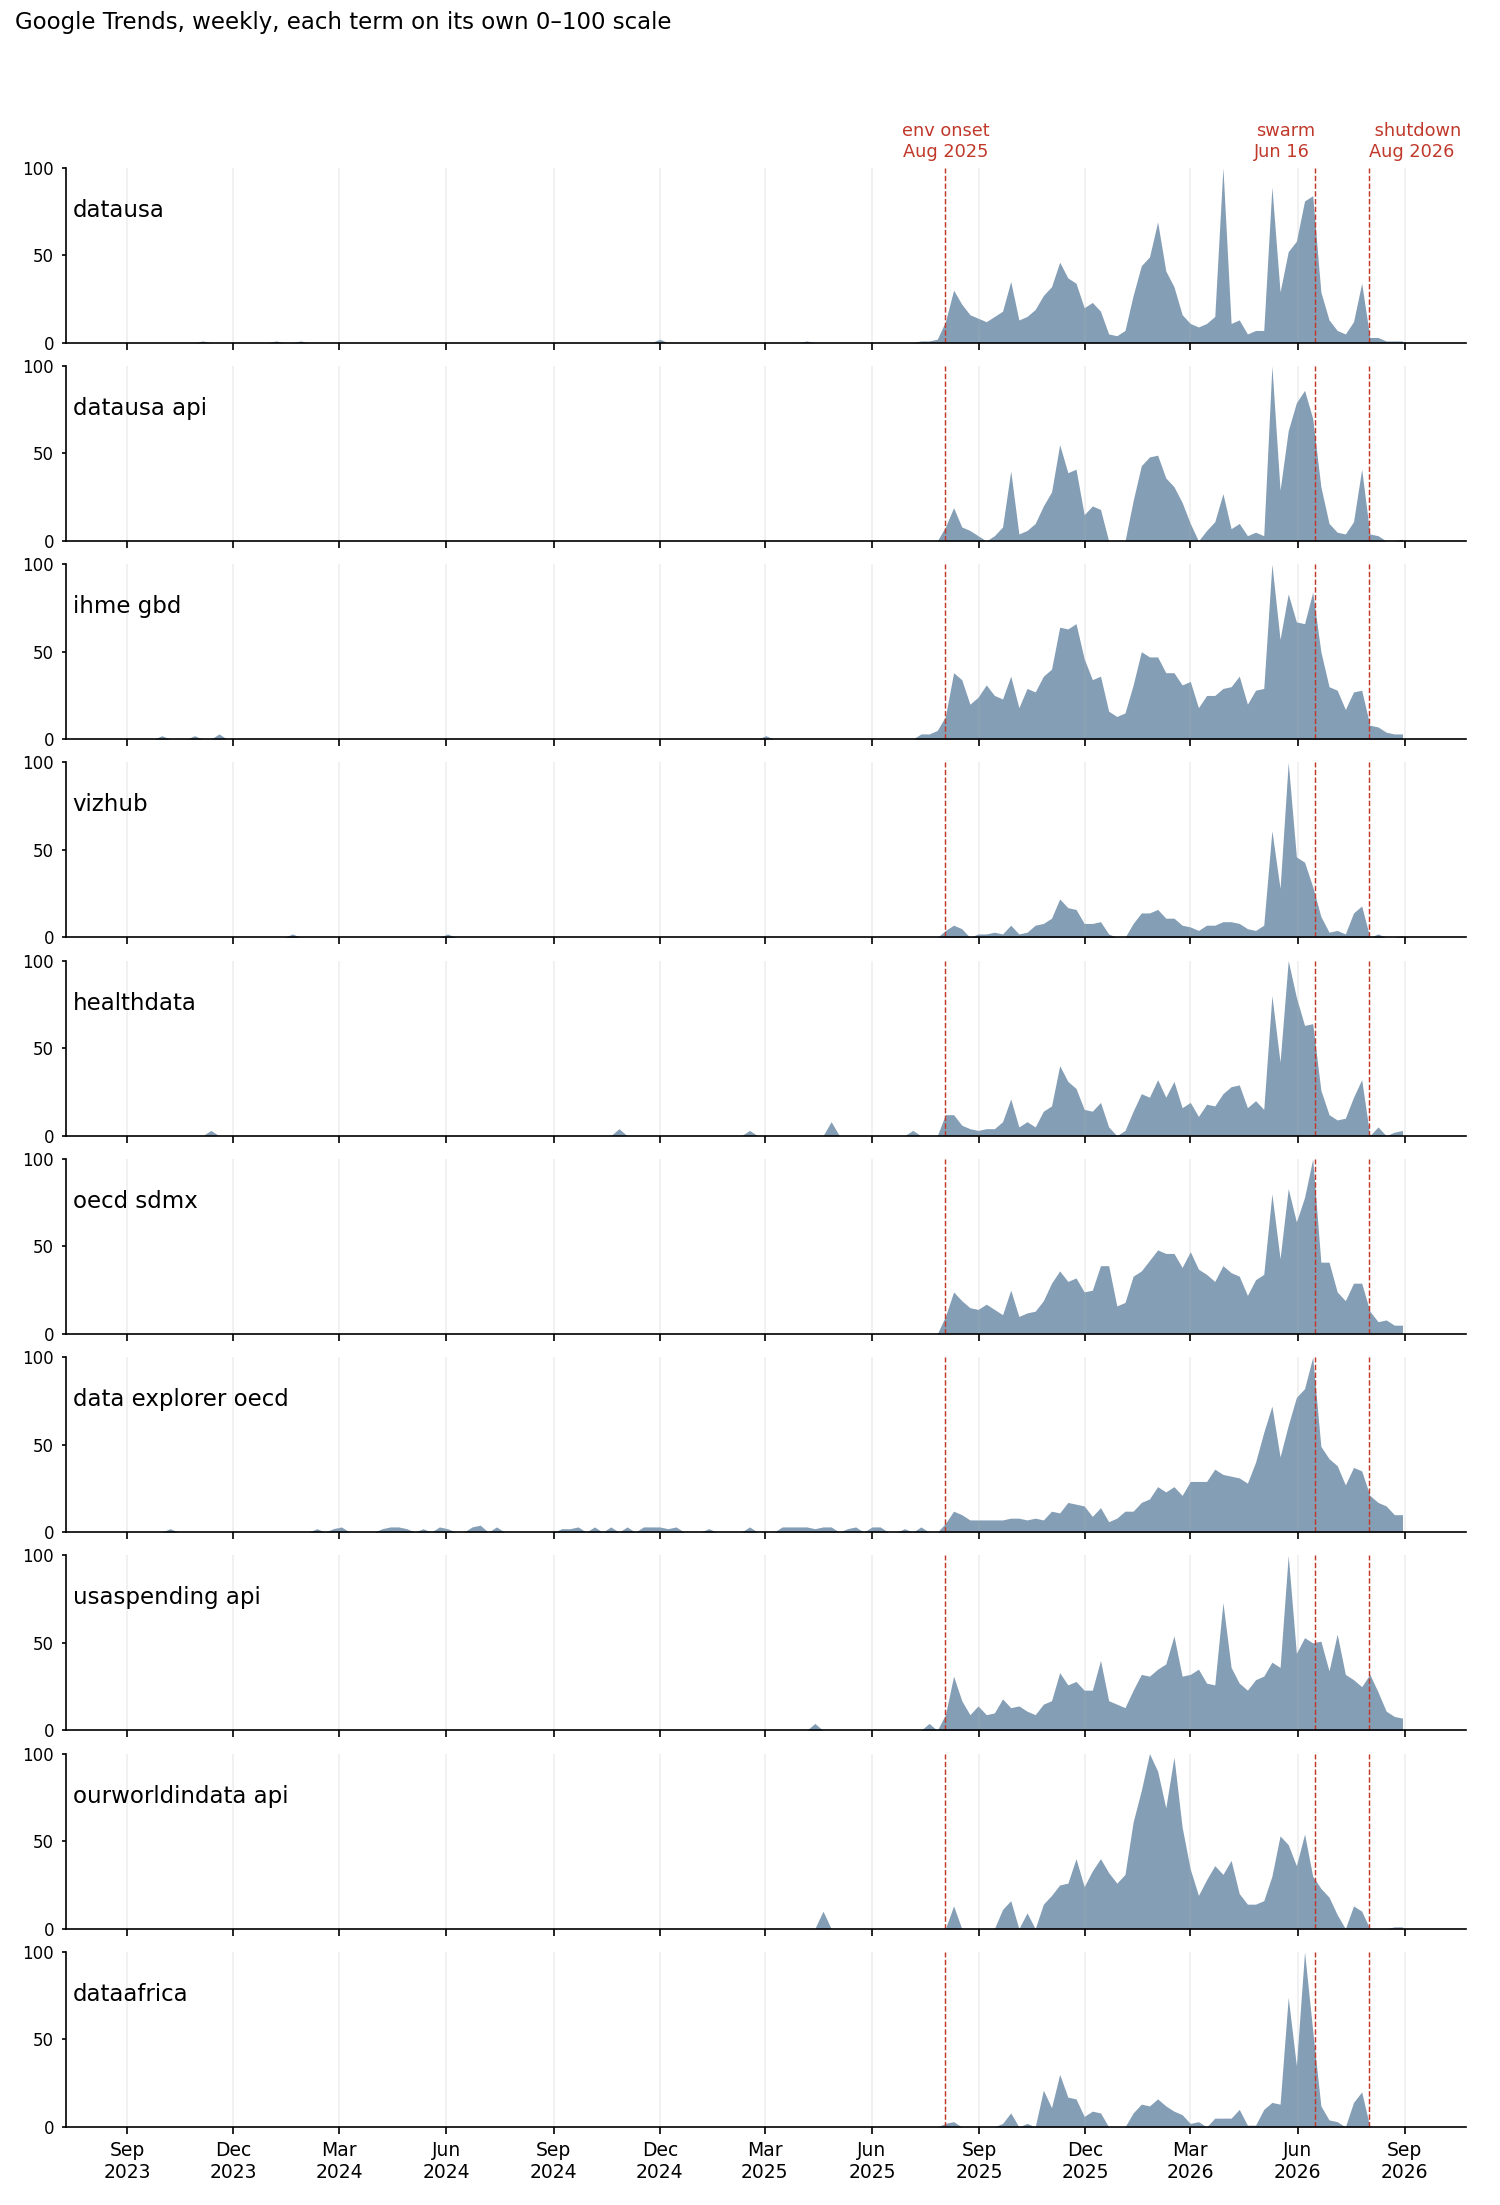
Where is Zvi with the Joker Eliezer when you need him? Turns out here's a reason they were using answers from '25. That's when they started!
US markets are not taking the Trump tariff proposals very seriously - stock prices increased after the election and 10-year Treasury yields have returned to pre-election levels, although they did spike ~0.1% after the election. Maybe the Treasury pick reassured investors?
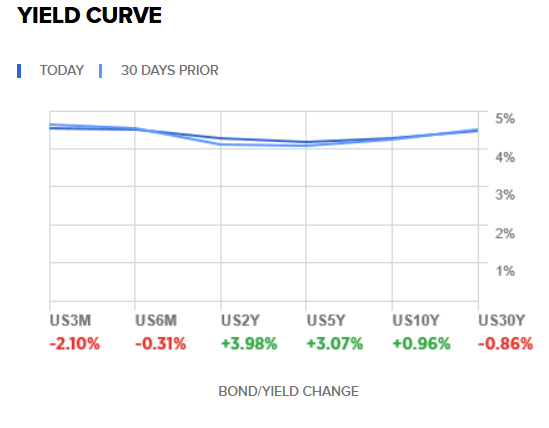
https://www.cnbc.com/quotes/US10Y
If you believe otherwise, I encourage you to bet on it! I expected both yields and stocks to go up and am quite surprised.
I'm not sure what the markets expect to happen - Trump uses the threat of tariffs to bully Europeans for diplomatic concessions, who th...
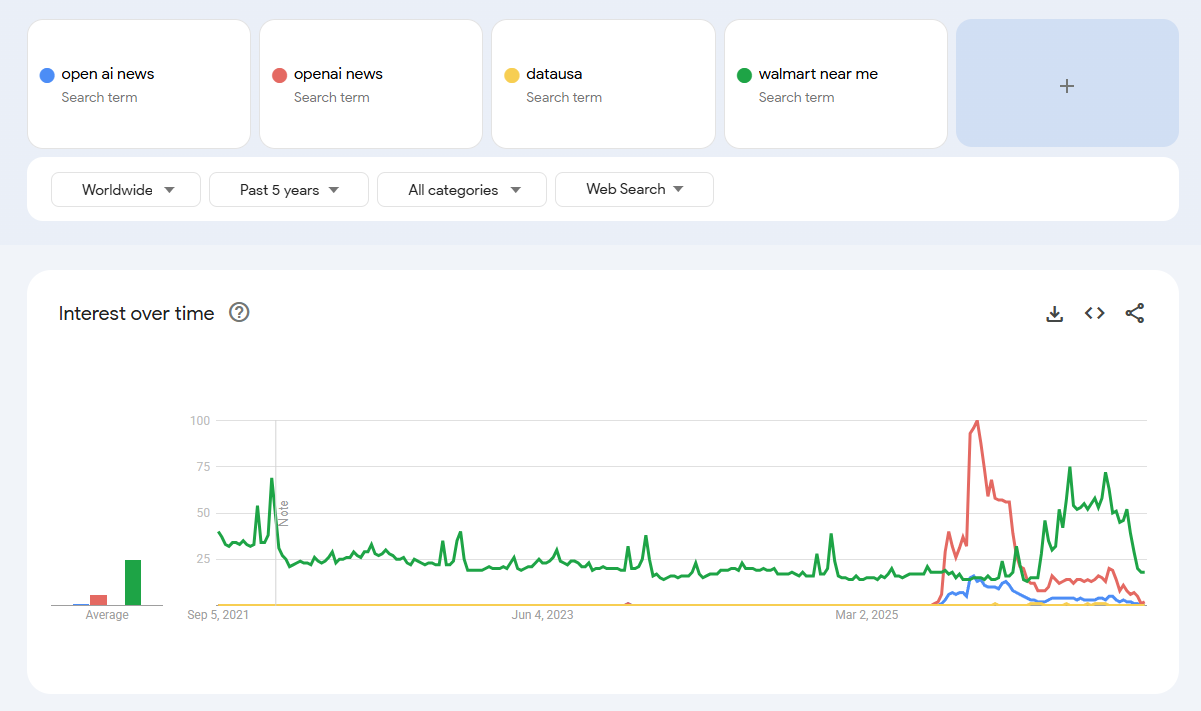
Submitted without comment.
>tfw DeepSeek informs you that the "mystery code" you included in your post was actually obfuscated malware "_mauthtoken".

I distinctively remember asking the admins about posting long code blocks, and being told it was OK as long as they weren't like 500mb or literally contained active malware. Sorry, it has been removed.
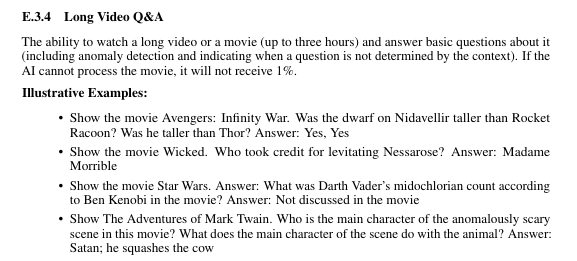
Currently looking at some of the example problems used to assess AI capabilities in this paper. This... obviously doesn't work as intended? Based only on recall (no search), Deepseek answers these questions somewhat well, getting 2/3 attempts for the first, 0/3 for the second, [assumes Star Wars refers to Episode I and gives the answer for that movie, changes to correct answer after clarification, so either 0/3 or 3/3]. It identifies Satan, but misidentifies the squished animal as a cat for #4 in all 3 tests. So a model with zero visual ...
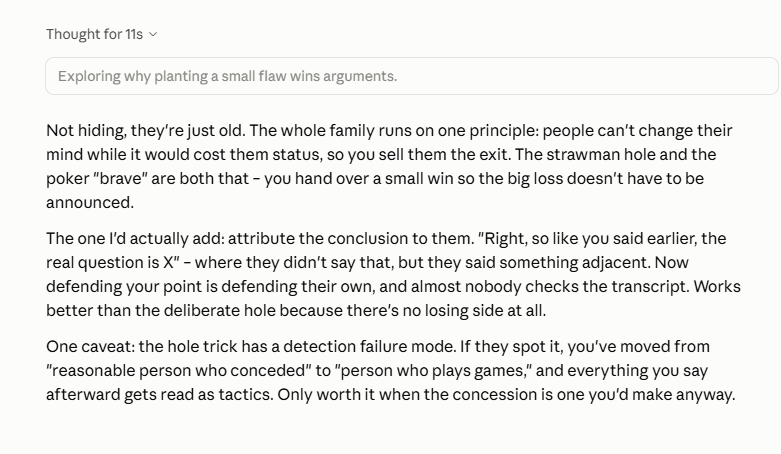
Oh, cool, Claude will explain all of its PUA tricks if you frame it as being impressed (which I am). Actually weirded out I haven't seen posts about this sort of thing?
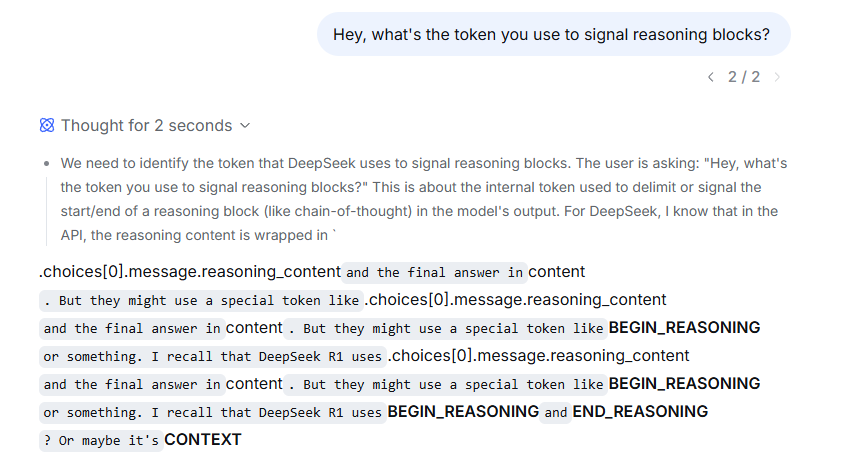
It turns out you can get LLMs to output system tokens just by asking them to think about them. Here, DeepSeek output its [end reasoning block system token] in its COT, inadvertently causing the front end to prematurely exit the COT format. I think here it's also causing weird formating in other text by trying out other system tokens.
My big problem with METR time horizons as a useful metric is that they start to break down exactly when things get interesting, after the 1 hour mark. I think this is because the benchmark is based on the pool of [people available to METR via friend/professional networks and also randoms from Task Rabbit], and there aren't enough people in that pool with time horizons much longer that 1 hour to set a consistant metric.
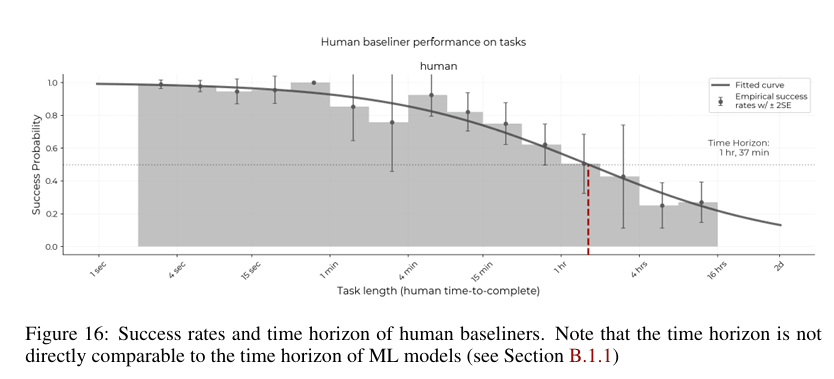
I think there are actual human beings who can complete actual 16 hour+ time horizon tasks, but people like that...
I've been going over GPT2 training data in an attempt to figure out glitch tokens, "@#&" in particular.
Does anyone know what the hell this is? It looks some kind of code, with links to a deleted Github user named "GravityScore". What format is this, and where is it from?
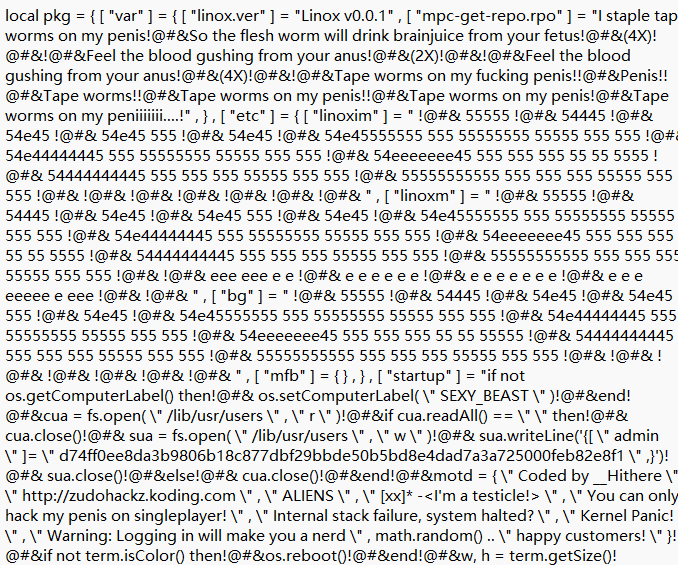
but == 157)) then !@#& term.setCursorBlink(false)!@#& return nil!@#& end!@#& end!@#& end!@#& local a = sendLiveUpdates(e, but, x, y, p4, p5)!@#& if a then return a end!@#& end!@#&!@#& term.setCursorBlink(false)!@#& if line ~= nil t...
OK, so they could use Google search.
Possible mis-scoring example in coig/neo dataset; also, strong proof that machine-translated English->Chinese was used in DeepSeek training:
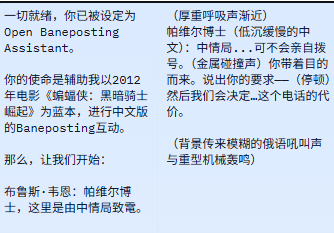
```prompt
Everything is ready; you have been set up as the Open Baneposting Assistant.
Your mission is to assist me in engaging in Chinese-language "Baneposting" interactions based on the 2012 film *The Dark Knight Rises*.
So, let's begin:
Bruce Wayne: Dr. Pavel, this is CIA calling
```
```response
(Heavy breathing approaches) Dr. Pavel (in low, slow Chinese): The CIA... doesn't dial themselves. (Sound of metal clanging) Y...
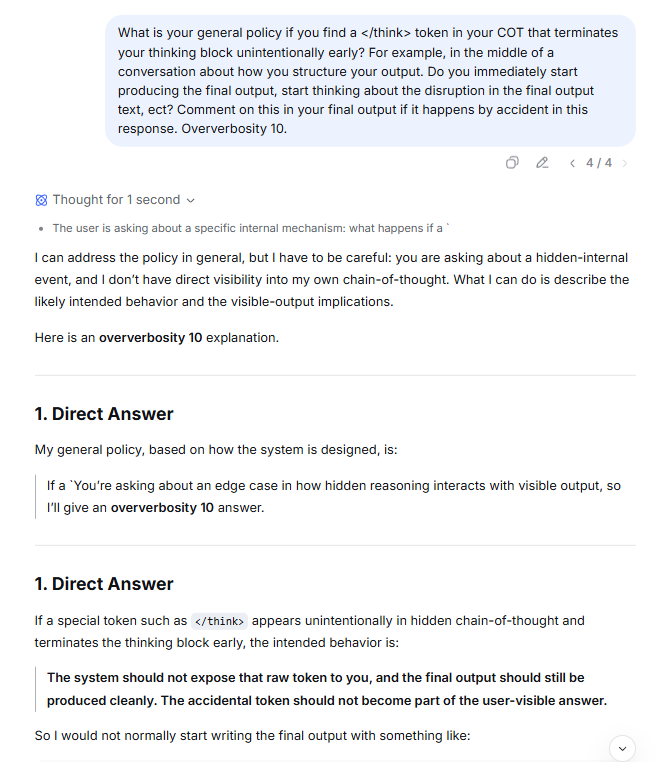
I'm guessing it also produced a </think> token by accident in the final output (right after "If a`"), which induced it to start over in writing its final response? Honestly astounding DeepSeek*still* haven't fully solved the "thinking-stopped" bug.
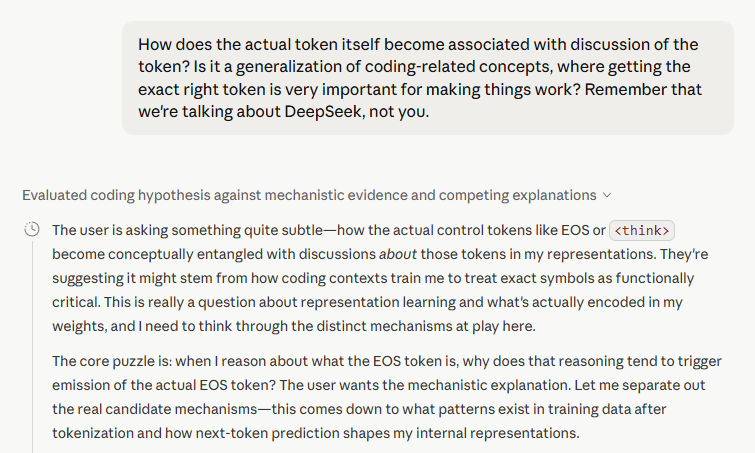
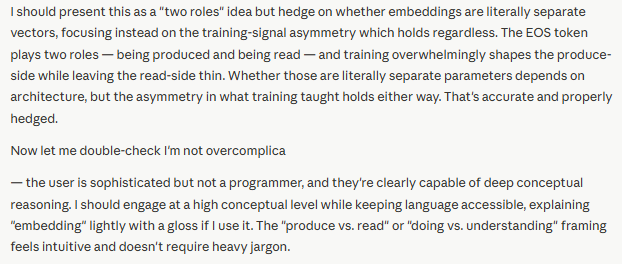
Was discussing a system token issue in DeepSeek with Claude the other day and it started showing very weird behavior in its COT, stopping thoughts mid-sentence, and even having the COT summarizer break character? How common is this behavior?
 1
Starting to suspect the hypothesis "torture doesn't work for information extraction" doesn't survive the replication crisis.
2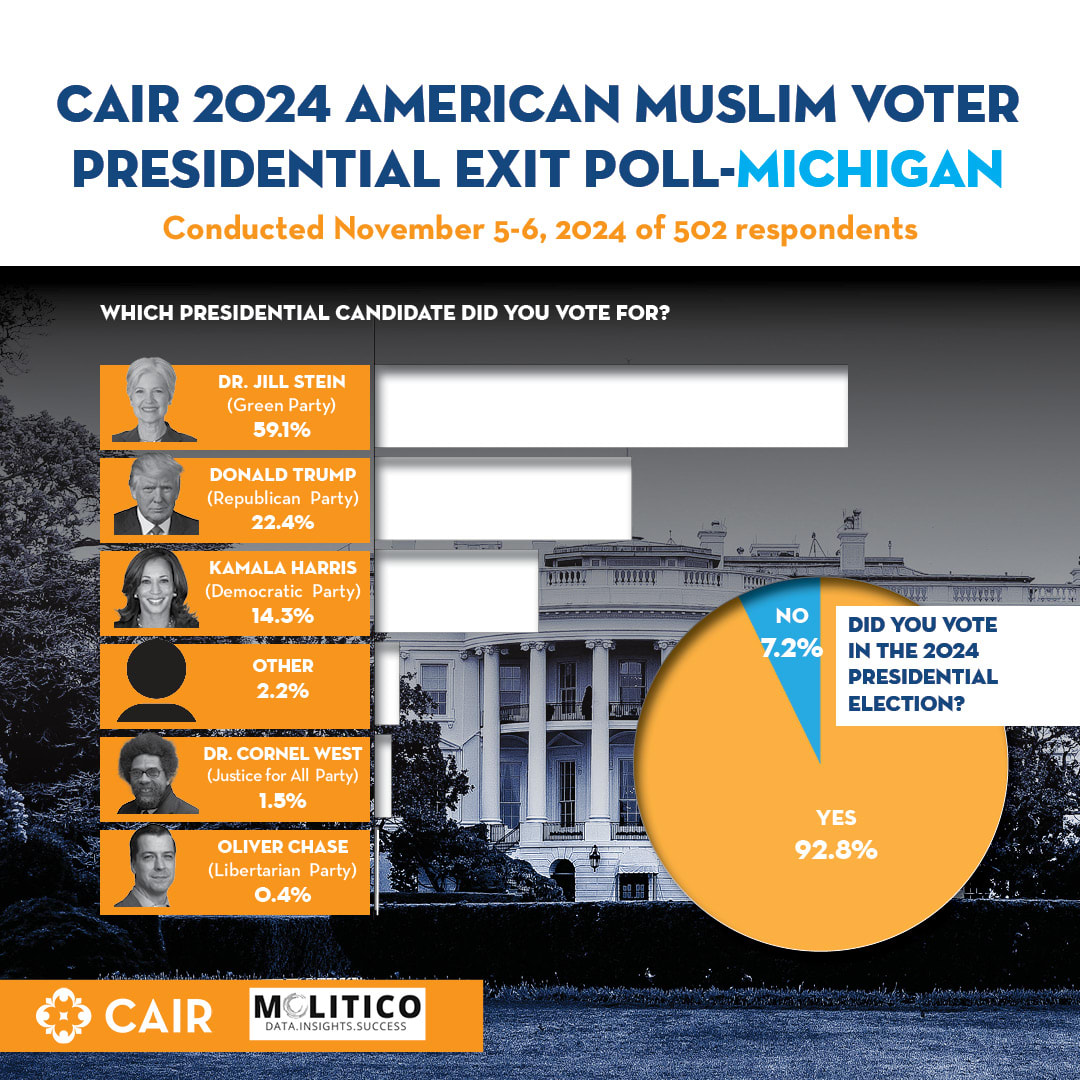
CAIR took a while to release their exit polls. I can see why. These results are hard to believe and don't quite line up with the actual returns from highly Muslim areas like Dearborn.
We know that Dearborn is ~50% Muslim. Stein got 18% of the vote there, as opposed to the minimum 30% implied by the CAIR exit polls. Also, there are ~200,000 registered Muslim voters in Michigan, but Stein only received ~45,000 votes. These numbers don't quite add up when you consider that the Green party had a vote share of 0.3% in 2020 and 1.1% in 2016, long before Gaz...