This is a special post for quick takes by anaguma. Only they can create top-level comments. Comments here also appear on the Quick Takes page and All Posts page.
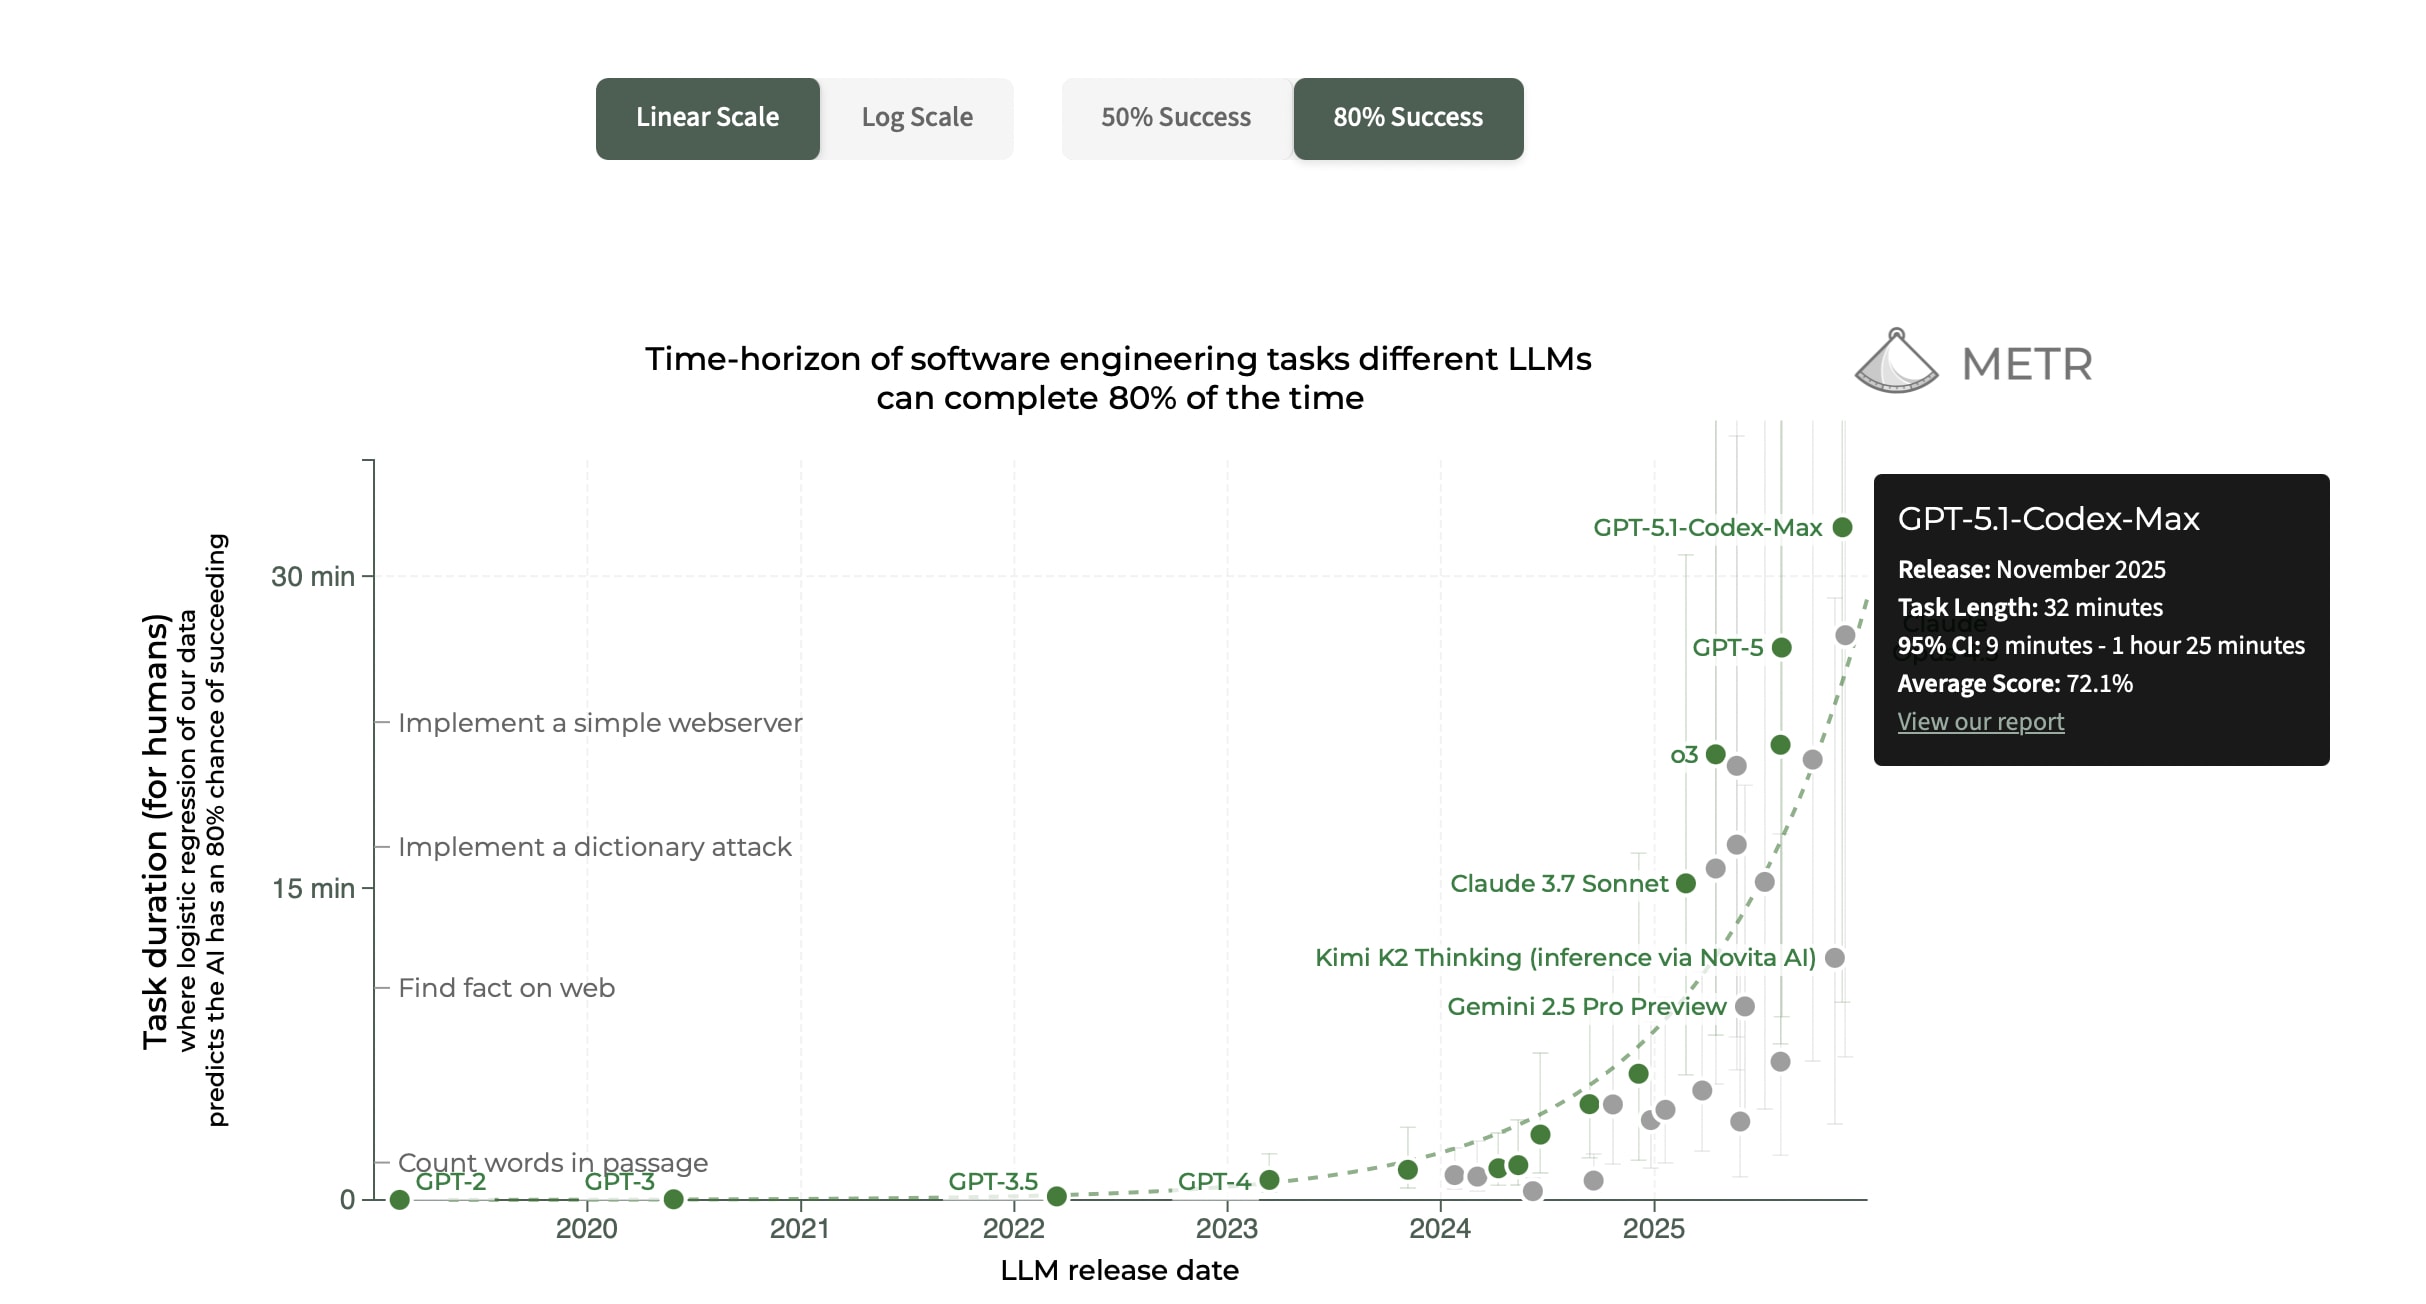
I was surprised to learn recently that the error bars on the METR time horizon chart are this large. This is probably the most important capabilities benchmark right now[1], but I don't think it's precise enough to be useful for discussions about AI capabilities progress or RSI.
Why hasn't METR added more long-horizon tasks to their benchmark since it was released in March 2025? I think they could probably find funding to do this from the labs or EA donors.
I have no idea, I just don't think the "actually making the tasks" part can be the limiting factor.
[...]
Yes; I also have a positive opinion of them, and various neutral opinions of them.
(My position could be summed up as "the concept of time horizons was really good & important, and their work is net positive, but it could use much stronger methodological underpinning and is currently being leaned on too heavily by too many people"; I'm given to understand that's also their position on themselves.)
10Daniel Kokotajlo
OK. Yeah that's also my opinion too. Maybe I am one of the people leaning too heavily on their work. The problem is, there isn't much else to go on. "The worst benchmark for predicting AGI, except for all the others."
Fwiw I think the AI village is at least as good of a benchmark for predicting AGI! Of course it's harder to quantify progress in the village, but it's very helpful for developing intuitions.