This is a special post for quick takes by Eye You. Only they can create top-level comments. Comments here also appear on the Quick Takes page and All Posts page.
Comment Permalink
How do LLMs and humans compare with regards to the amount of energy, data, and compute that's used to train/run them? I was inspired by Samuel Knoche's post on sample efficiency to come up with some numbers. This table was made by Opus 4.8. after some iteration:
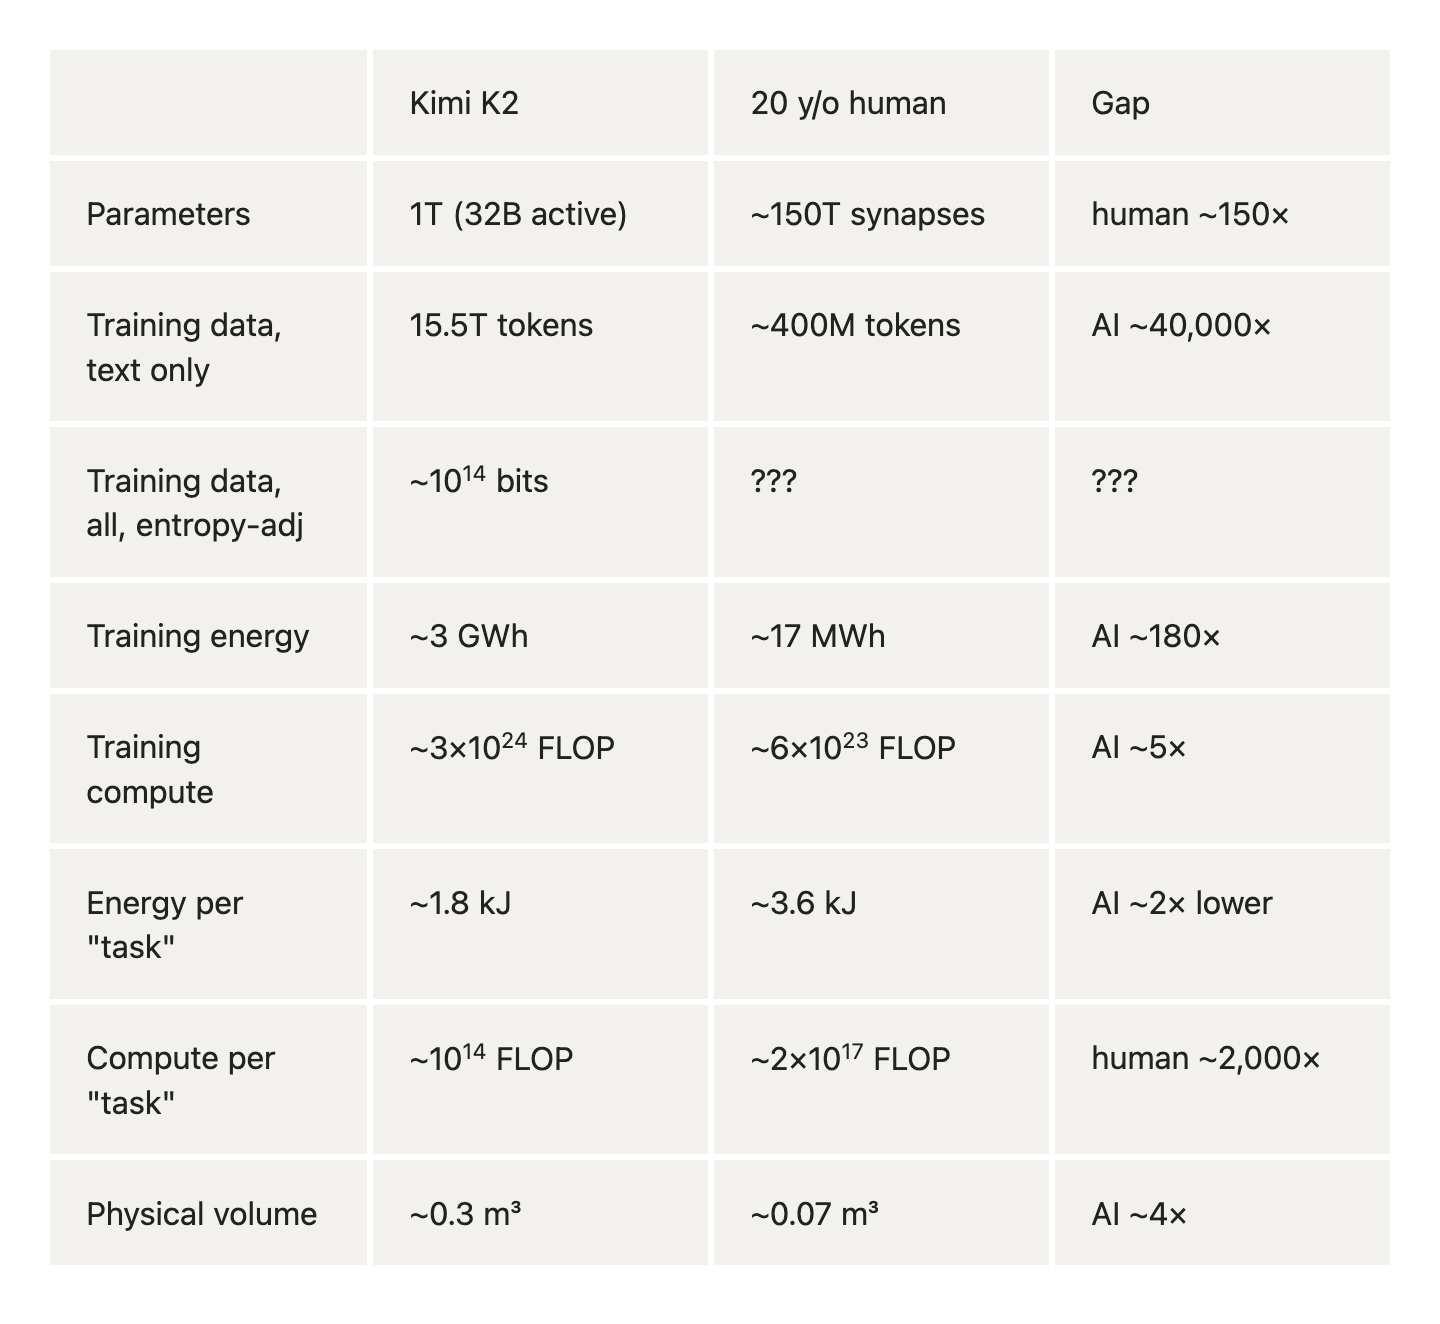
"Task" = "produce one thoughtful ~1,000-token answer"; unclear if this is a useful number, obliviously it doesn't generalize. I do think it's interested to compare the energy/computer ratio for inference between human and AI.
Training data for humans is a big "???". There's ~4x10^8 waking hours. Opus 4.8 cited this 2024 paper which says "our sensory systems gather data at ~10^9 bits/s". That gives ~4x10^17 as an upper bound. But human sensory data is extremely redundant. If someone wants to spend time figuring out a good way to estimate entropy adjusted information here, that would be cool.
(FWIW, I spent a little over an hour on this -- I did a fair amount of iteration with GPT5.5, looked a bit myself into a few numbers, and got new instances to do estimates from scratch to see if things lined up.)