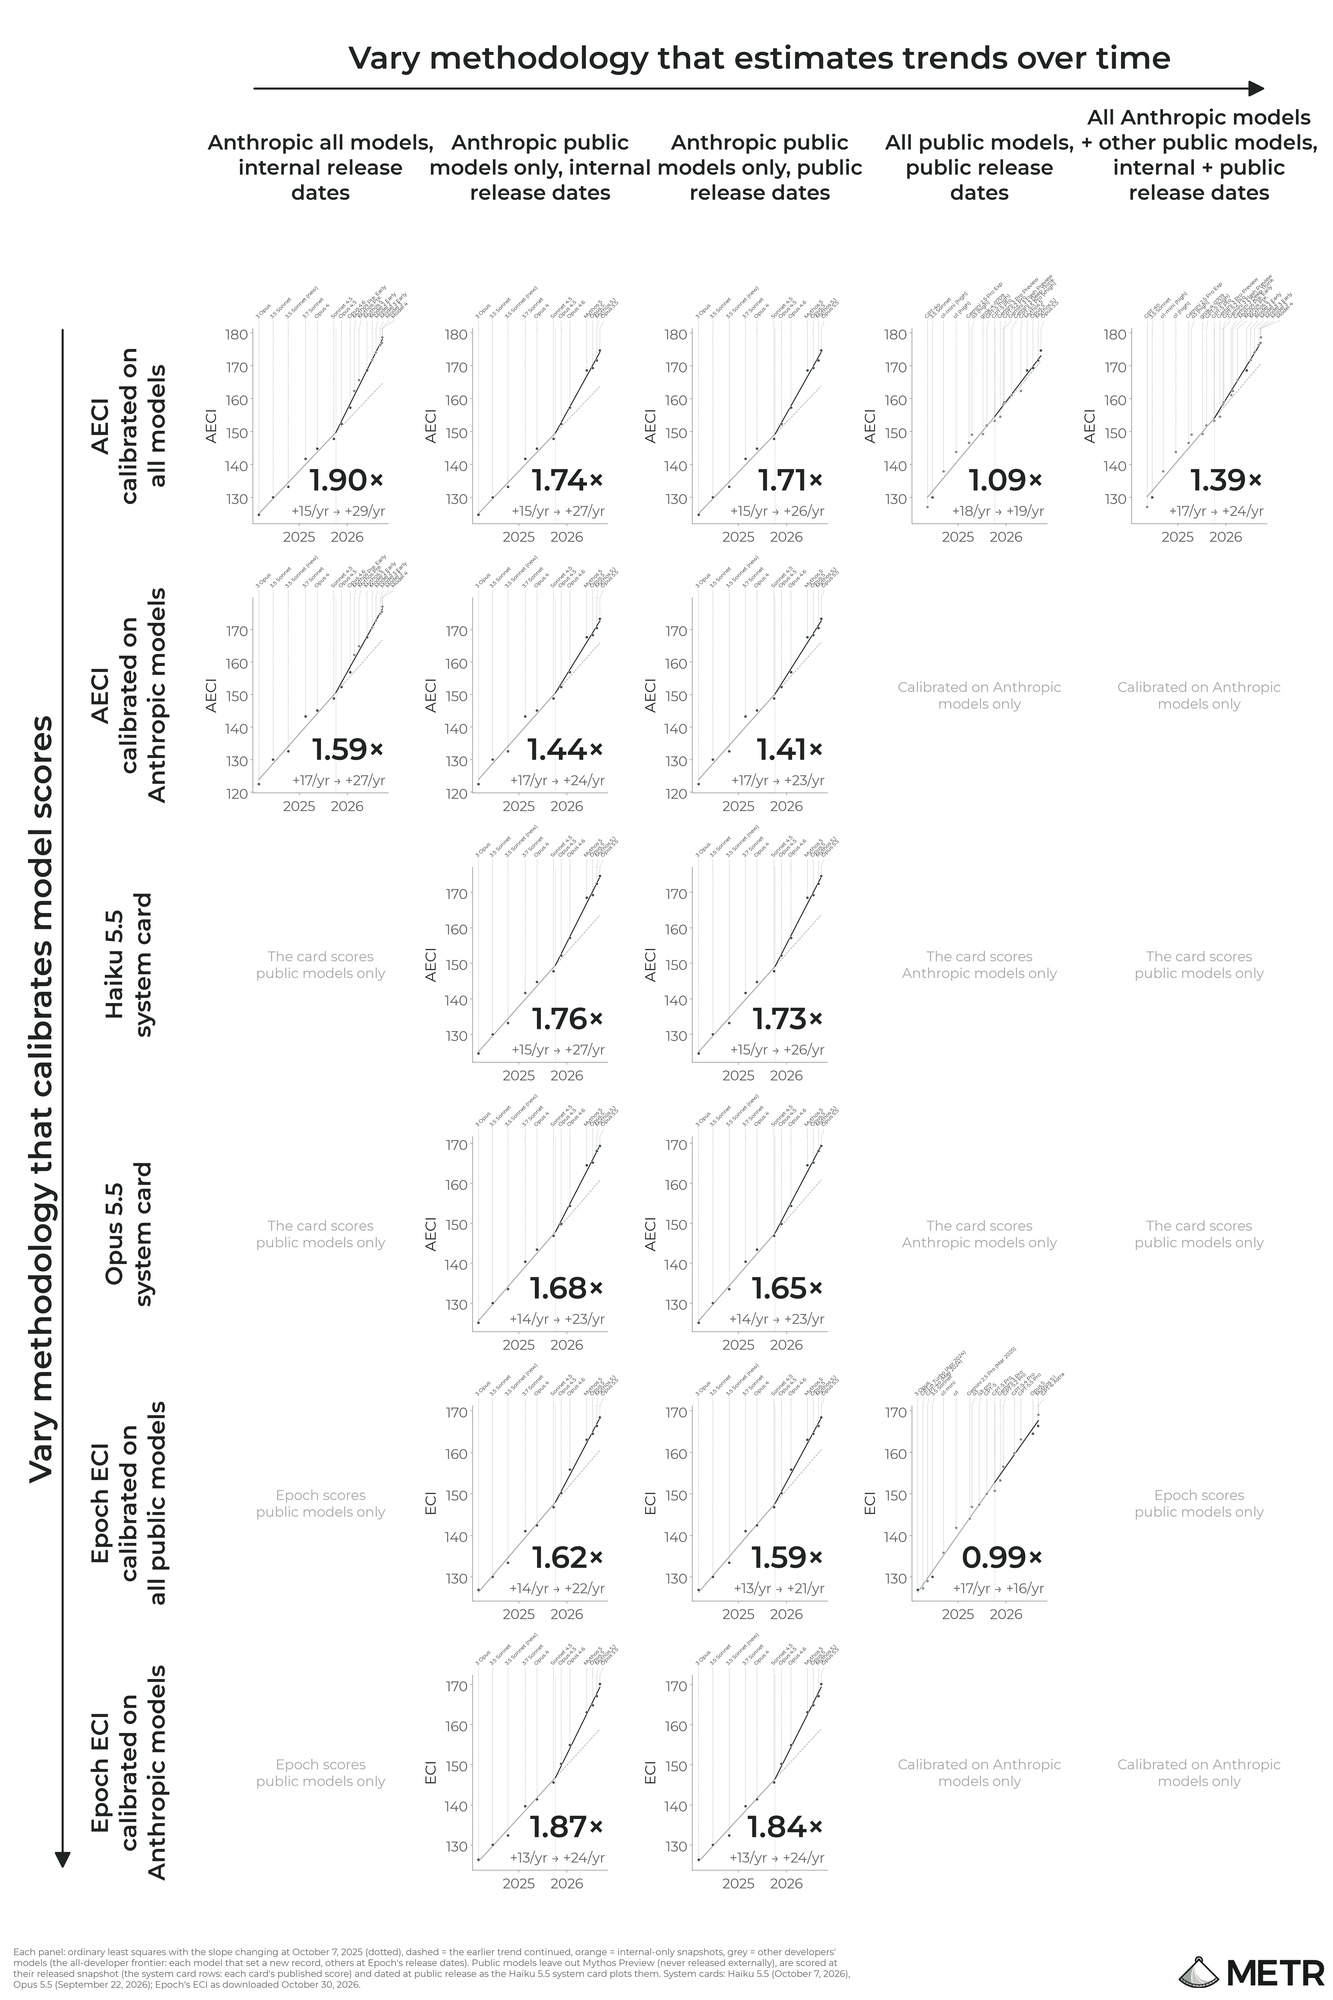
As of October 2026, benchmark scores appear to be growing at 1.9x their pre-October 2025 rate
... isn't this graph actually kind of a bear signal?
No, seriously. The hypothesis we're tracking is RSI, i. e., that AI capability improvements make additional AI capability improvements easier. This should mean that the acceleration multiplier is growing: from one model release to another, the slope of the graph should be becoming ever steeper, such that the graph as a whole stops being well-modeled as linear.
What the graph is showing, instead, is a one-off slope change somewhere around the start of 2026, past which the slope remained the same. That is, there was some sort of "unlock" in early 2026 that let AI make Anthropic employees more productive[1], and then additional capability improvements no longer made further capability improvements easier. For the entire year.
I suppose the bull case is that RSI is just "discrete" instead of continuous? I. e., that there will be a few more discrete slope changes like this, and each slope change will bring the next slope change sooner, up until AI is able to handle all research tasks and we get a multiplier of "approximately positive infinity" or something. But this isn't how the argument usually goes, I think.
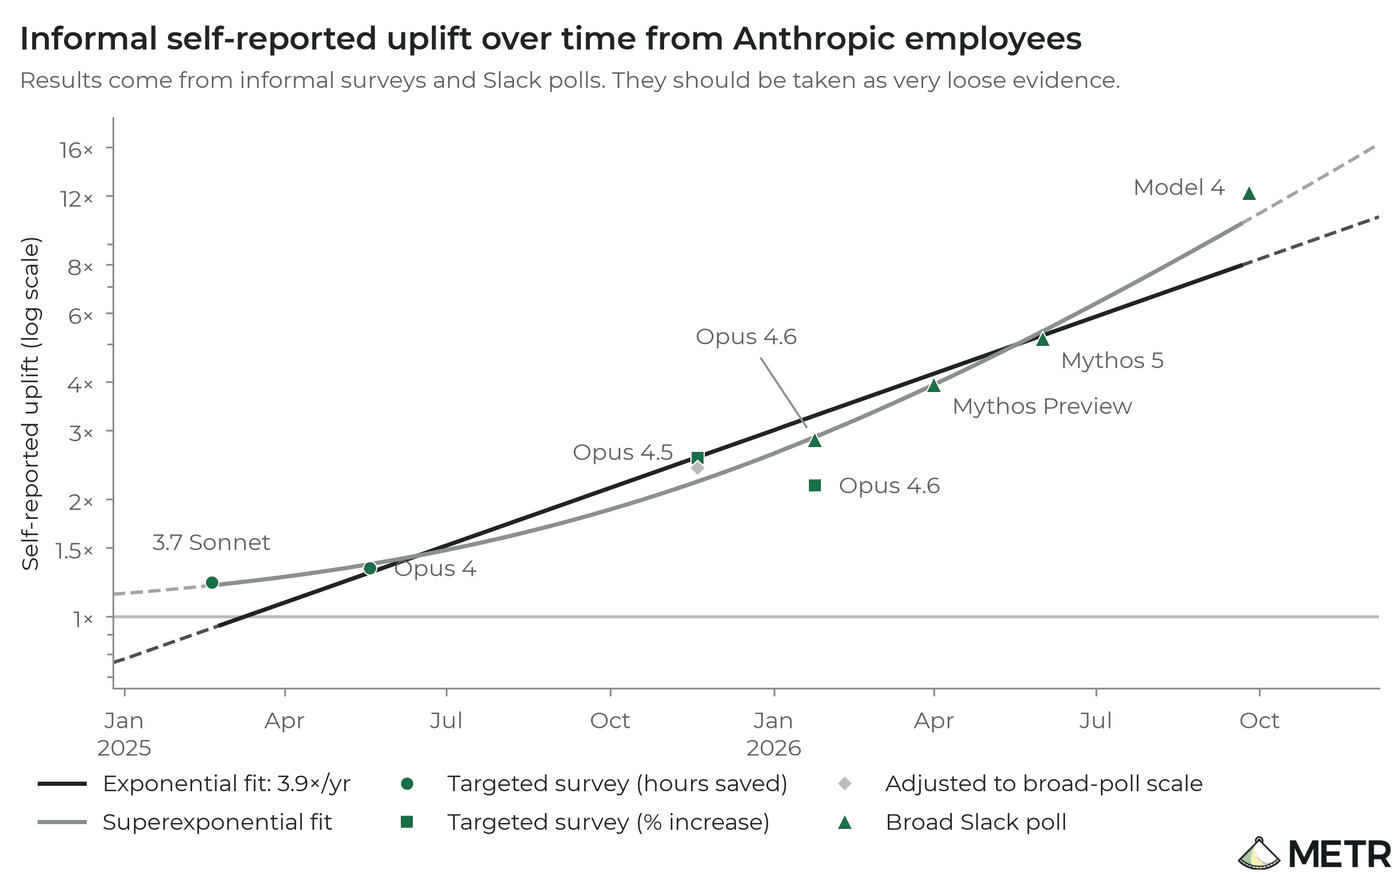
Edit: Employees' self-reported uplift is more like how RSI should look like, a straight line on the productivity multiplier graph. But these data are considered much more unreliable, and if it's to be taken seriously together with the other graph, it would imply that sustaining the current 2x growth would require continual exponential improvement in employee productivity.
- ^
E. g., the "now only bottlenecked on ideas & compute, no longer bottlenecked on code" stuff from the interviews.
 1
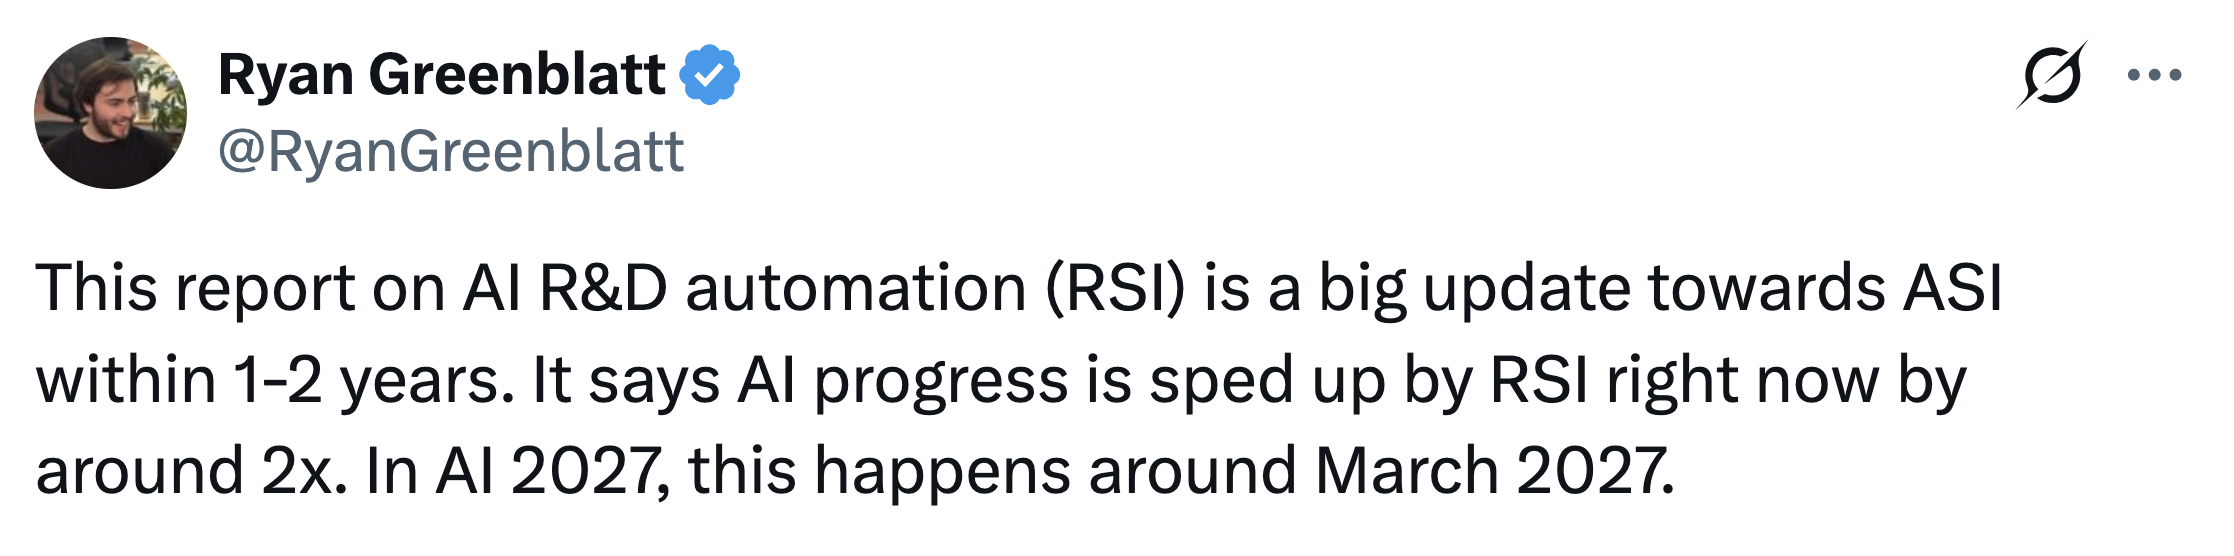
From the Ryan Greenblatt quote in OP:
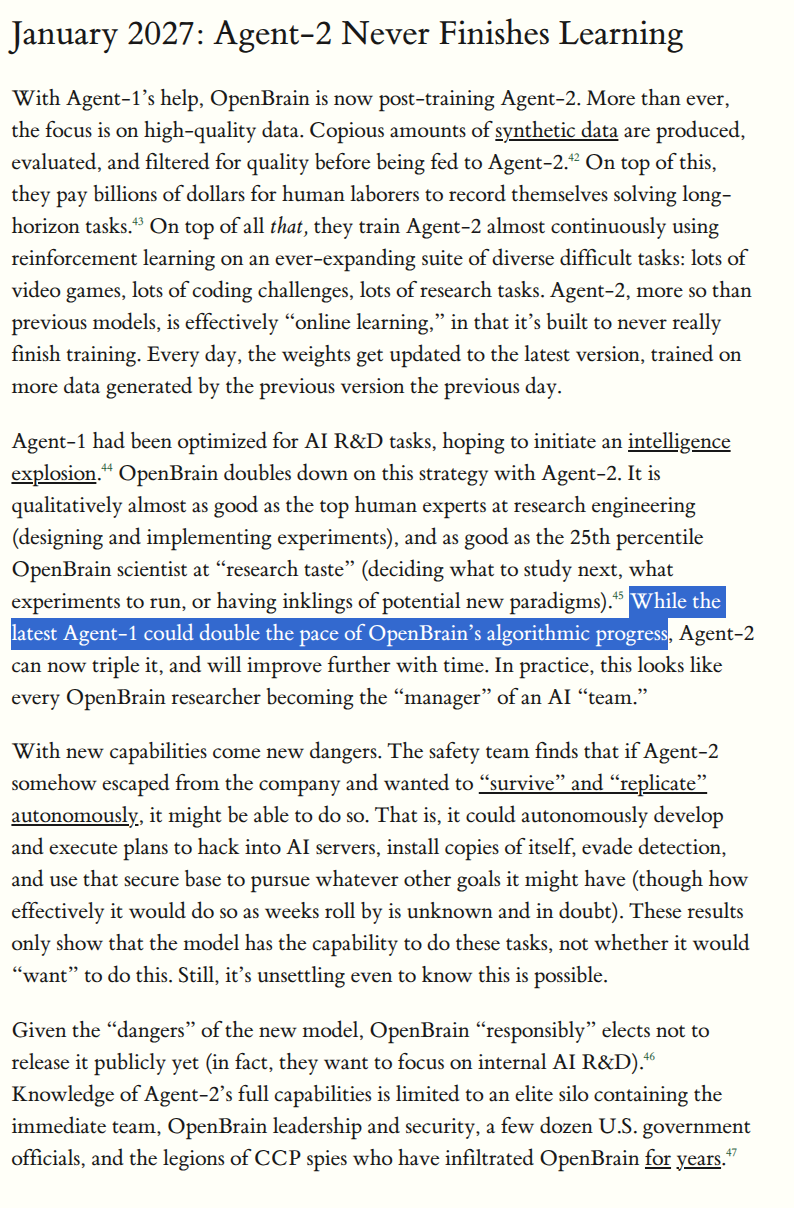
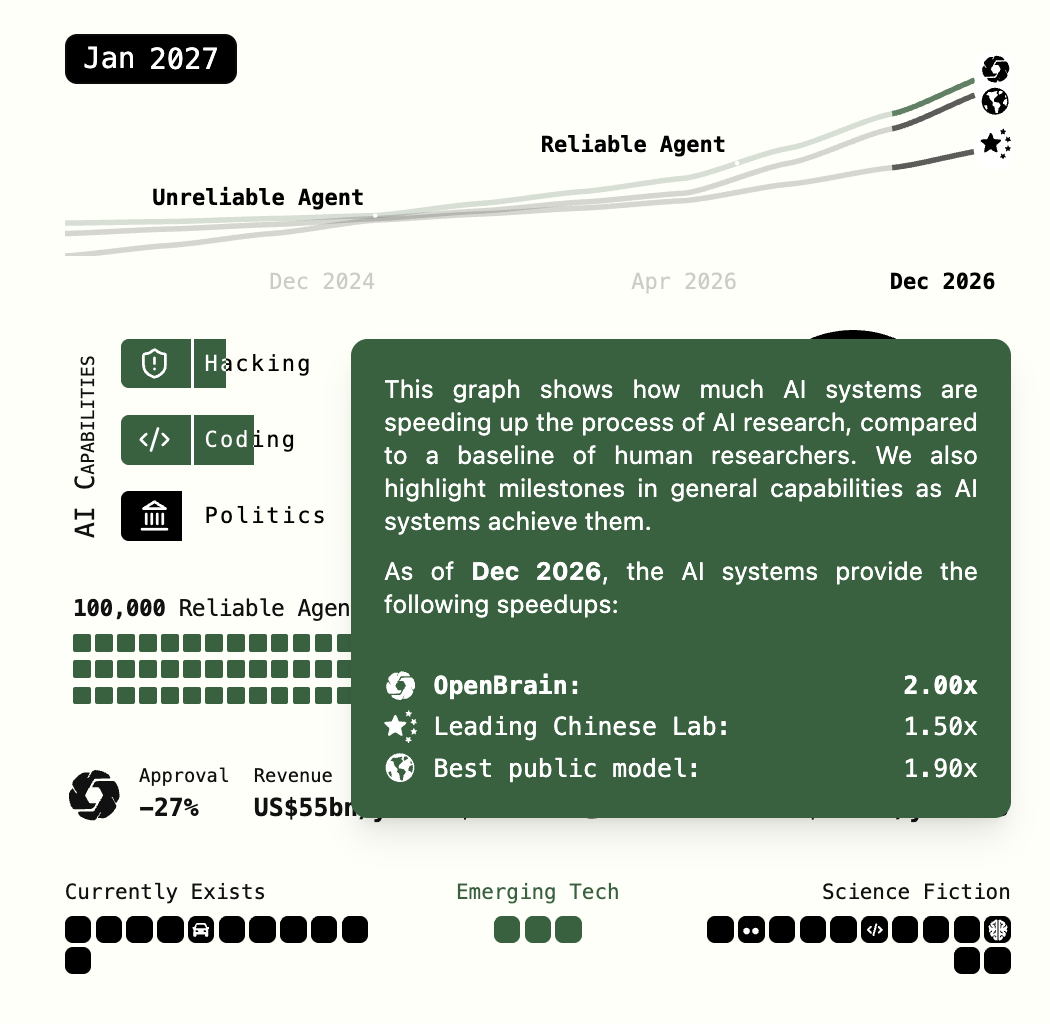
This report on AI R&D automation (RSI) is a big update towards ASI within 1-2 years. It says AI progress is sped up by RSI right now by around 2x. In AI 2027, this happens around March 2027.
I was seriously wrong about RSI speed up; I previously expected much less in 2026 (around 1.15x-1.3x). It seems as though there was specific privately available evidence that would have changed my mind.
FYI this is part of a longer post. The 1.15x-1.3x speedup number he gives there is not directly comparable to the 1.9x acceleration in AECI capabilities under discussion, unless you assume that AI provided ~1x speedup prior to October 2025.[1] (That is, no real speedup at all.) Which is a defensible assumption, to be clear![2] Oct 2025 is before actually-good coding models like Opus 4.5. In his full post, Greenblatt does an involved conversion between acceleration and speedup:[3]
A 2x acceleration in overall AI progress from RSI corresponds to a much larger than 2x RSI speed up for AI software R&D (algorithms and data); I did an estimate using my public preexisting modeling of drivers of AI progress and the public report which yielded a very rough estimate of 4.5x for how much RSI is currently accelerating AI software progress (relative to no AI automation). In the AI 2027 scenario, this much acceleration happens around March 2027.
Here are the worked details of this estimate based on my public modeling. There are two main reasons RSI speed up of AI software R&D must be larger:
- Not all of AI progress is from better software (some is from scaling up compute in training runs). I've previously speculated that around 2/3 of AI progress is from software improvements which implies that 2x overall AI progress acceleration requires 3x faster software progress.
- Diminishing returns: A fixed amount of progress requires more work over time, so to ongoingly maintain 3x faster software progress via AI automation, you need increasingly large speed boosts from AI automation (as in, speed ups relative to how fast software R&D would go without AI automation). Based on this report, it seems that there is a substantial amount of additional AI progress from automation that has occurred.
We can estimate the effects of diminishing returns by first determining how many additional years of software progress we've seen (relative to the preexisting trend) and then estimating how much software R&D would slow down after a year of software progress if you held inputs fixed due to diminishing returns. I've previously estimated software R&D would slow down by around 2x for each year of software progress if you held inputs fixed and based on the report, it seems as though we've perhaps seen roughly 0.35-1.0 years of additional software progress incorporated into trained models so far (geometric mean of ~0.6). This combines to 3 * 2^(~0.6) = ~4.5.
(Relevant public modeling and numbers I'm using: 1, 2)
So Greenblatt's point here is basically that he thinks 2x total acceleration today would mean 4.5x software speedup today (as opposed to compute growth).
However I think there's actually an error in the calculation?[4]
- He says AI progress is roughly 2/3rds software progress, so therefore it's also 1/3rd compute growth.
- He then says therefore 2x AI progress acceleration requires 3x acceleration in software progress.
- But calculating out the expected total acceleration from 3x software acceleration:
- Before: 2/3 software * 1 + 1/3 compute * 1 = 1x acceleration
- After: 2/3 software * 3 + 1/3 compute * 1 = 7/3 ≈ 2.33x acceleration
- Rather, if we want to get 2x total acceleration, we need:
- After: 2/3 software * 2.5 + 1/3 compute * 1 = 6/3 = 2x acceleration
Carrying 2.5x software acceleration forward, we get a total software speedup today of 3.8x.
Of course, that's still rather higher than the AIFM's estimate of ~1.3x today (or Greenblatt's prior "1.15x-1.3x"). The latest AIFM only expects 3.8x speedup after the Automated Coder (Daniel: 12/27, Eli: 7/28, Brendan: 2/28).
Why exactly such speedup might have happened so much earlier than the latest AIFM expected[5] requires some deep investigation,[6] but my early, rough understanding is that the difference is plausibly:
- AECI is not a perfect reflection of overall AI capabilities progress; notably, Epoch's ECI does not show the same acceleration for Anthropic capabilities,[7] and if you include non-Anthropic models, that removes acceleration entirely. We can perhaps explain the surprising difference between AECI trendlines and ECI trendlines as:[8]
- Anthropic's unreleased models (checkpoints of Fable 5.5?) are on a faster trendline.
- Anthropic was actually kind of behind the frontier for a bit, prior to Mythos Preview, so their high growth is partly catchup.
- Anthropic's latest AECI thinks the Claude 5.5 series is better than Epoch's ECI thinks.
- METR's AECI chart today has an x-axis that dates models by availability internal to Anthropic, rather than when they were publicly released like ECI, which steepens the trendline slightly.
- The AIFM expects that prior to the Automated Coder, RSI is mostly driven by progress towards automating coding, and after the Automated Coder (the rapid "takeoff" regime), progress is then driven mostly by research taste. As part of this, AIs prior to the Automated Coder are modeled as having research taste worse than human level. This is part of what METR is pointing to when they caveat that: "we understand that AI is not yet able to make highly significant and fully autonomous contributions to the most important parts of the model training process."
Yet it's possible that recent models have actually been quickly improving in research taste, and that this is driving capabilities progress as much or more so than pure AI coding automation is. In particular there is evidence from P-Zero's TasteVal to suggest this is the case,[9] though the AIFP already incorporated an unreleased version of that evidence into the latest AIFM. They didn't update all the way to the implied TasteVal numbers, but I don't tend to think that one should, as there's counterevidence from Epoch's research into AI R&D automation (1, 2).[10]
- ^
Also you have to assume 100% of acceleration is from AI and not other inputs. Today's METR report estimates it's 80% at Anthropic… not that far off, to be fair.
- ^
The latest AI Futures Model estimates a 1.08x-1.09x speedup vs. human-only work with same compute/resources as of 10/7/25 (the trendline breakpoint in METR's post today), based on a few different sources of evidence. (Daniel's presets 1.09x, Eli/Brendan 1.08x)
For today (11/5/26), the AIFM estimates 1.26x-1.37x speedup (Daniel 1.37x, Eli 1.26x, Brendan 1.30x), which is quite similar to Ryan Greenblatt's 1.15x-1.3x, which makes sense as they've worked together on ex. AI-2040, and the AIFP's uplift calculations used Greenblatt's work, etc.
Also ex. an Anthropic researcher interviewed by METR for today's report said there was "~0 uplift pre Opus 4.6/Opus-4.5" on AI R&D.
- ^
I've done a bit of formatting cleanup on this.
- ^
EDIT: Greenblatt confirms this was an error. Now corrected on his end.
- ^
To be clear, the latest AIFM is more conservative than AI 2027 was.
- ^
Which Daniel Kokotajlo says the AIFP is urgently working on.
- ^
Yes METR's data today includes unreleased models, but even without those, the Haiku 5.5 system card shows a 1.7x acceleration in AECI, which is higher than Anthropic-models-only Epoch ECI acceleration of ~1.45x after a breakpoint at ~October 2025 (using the same rough date range for choosing the pre-10/25 trendline).
- ^
METR's report also provides possible explanations here.
- ^
Specifically, TasteVal shows a breakpoint in the trendlines on AI research taste around December 2025 (suspiciously close to the capabilities trendline, but admittedly after it, though METR's AECI analysis today uses "the date at which the model could be used by most Anthropic employees instead of public release dates" which accounts for some of the gap). (Anthropic's model cards use the public release dates.) Models just prior to the breakpoint were at ~0.1x Human expert, and now Opus 5.5 is at 2.30x (95% CI 1.15-4.37x) Human expert.
- ^
Personally I think the difference between TasteVal's and Epoch's research might partly result from the fact that the former specified particular research problems tractable to known methods, while the latter involved work that was either open-ended or required novel ideas.
TasteVal disclaimed that "we do not measure significant aspects of taste, such as picking problems worth solving" and "the strongest submissions to our tasks did not use novel ideas or perform non-obvious cross-domain adaptation". Epoch AI notes in its InnovationEval that "AI did not discover anything comparable to the original innovation" and in its "Can AI automate Epoch?" that "Models generate promising research directions, but struggle to design experiments that are actually informative".
I suspect this relates to AI weakness in "relevance realization", aka the ability to identify the information most useful for improving your understanding of the world. Less of that is required for TasteVal's tasks.
 1
Still digesting, but one interesting quote from the report:
Our estimated acceleration is greater than that reported in the Haiku 5.5 system card (1.7x) primarily because of the inclusion of data on newer unreleased models, explained further below.
METR's new estimate from Anthropic's AECI is 1.9x [95% CI: 1.5–2.8x]. The public Haiku system card 1.7x estimate is, notably, still within that confidence interval, but more importantly, why wasn't everyone talking about the Haiku system card estimate from 10/7/26? It's still a huge jump from the ~1x acceleration (that is, no acceleration) trendline you see in Epoch AI's public ECI frontier![1]
Here's the chart from the Haiku system card (page 20, section 2.3.2):
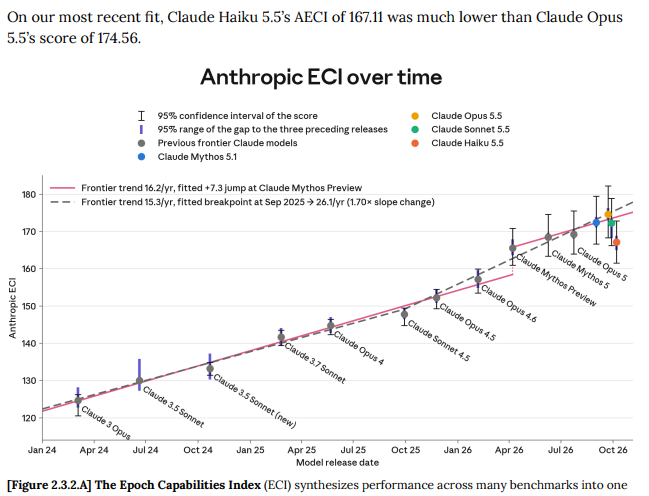
The essential claim is inside the figure, in the key for the dotted line: "fitted breakpoint at Sep 2025 ➡ 1.70x slope change". (they fit two trends, one breaking on Mythos Preview and treating it as a one-time jump—arguably wrongly considering the data on unreleased models METR just shared—and one breaking at Sep➡Oct 2025, aka roughly when AI agents became "actually good" at coding last year[2])
It seems to me that METR's AECI figure is a direct descendant of the above, just preferring the dotted trendline's choice of breakpoint:
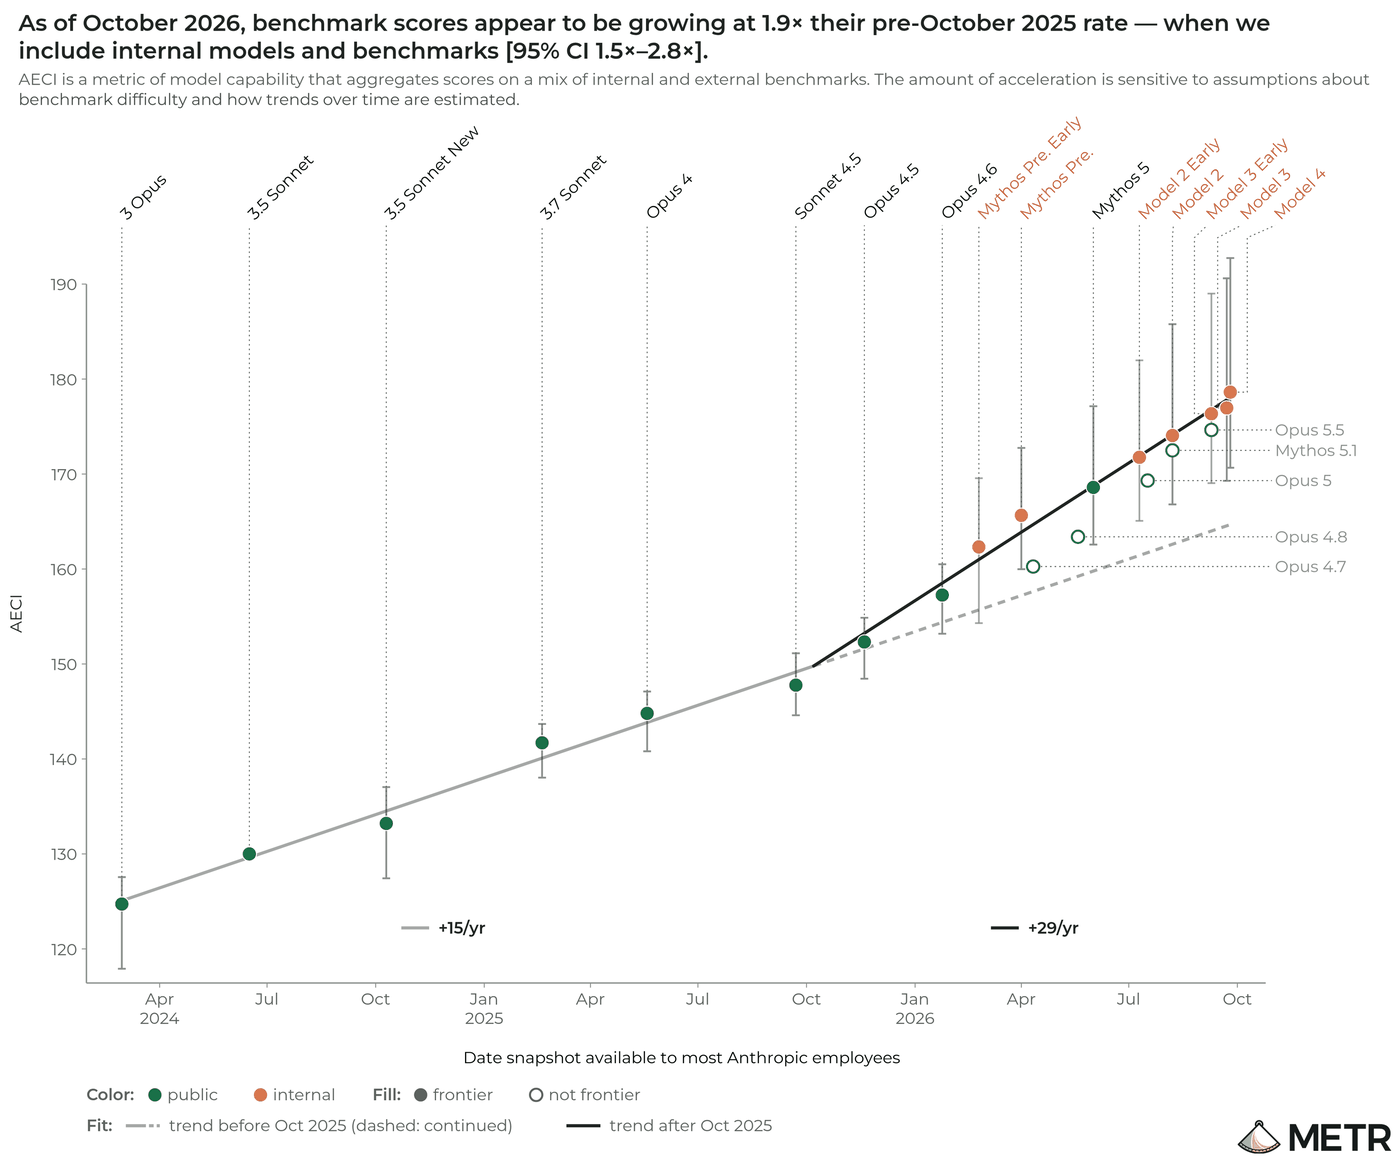
Maybe no one paid attention to Haiku 5.5's system card because it was Haiku. Obviously there's way too much stuff in AI to read everything; even Zvi didn't do a full writeup on Haiku 5.5, and I can't find a mention of the ECI trend from the card in his recent posts, or online or on LW generally.[3]
Maybe the issue was that the key text was in an image, which AI agents typically don't bother to read…?
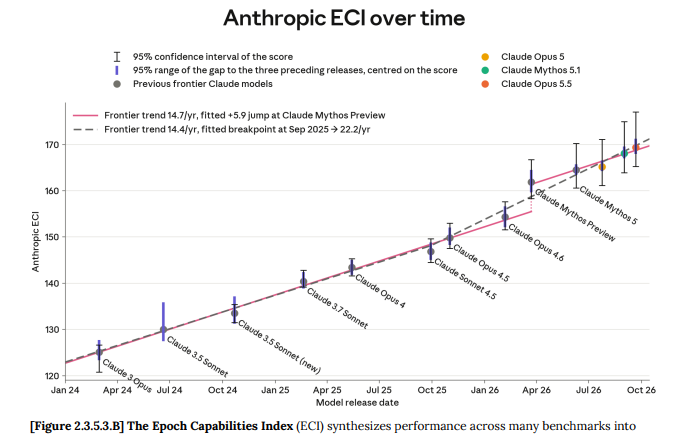
EDIT: Actually the full story is more complex, I should have realized, sorry. Anthropic has released a version of this figure alongside Opus 5.5 (9/22), Sonnet 5.5 (9/28), and Haiku 5.5 (10/7).[4] Opus chart:
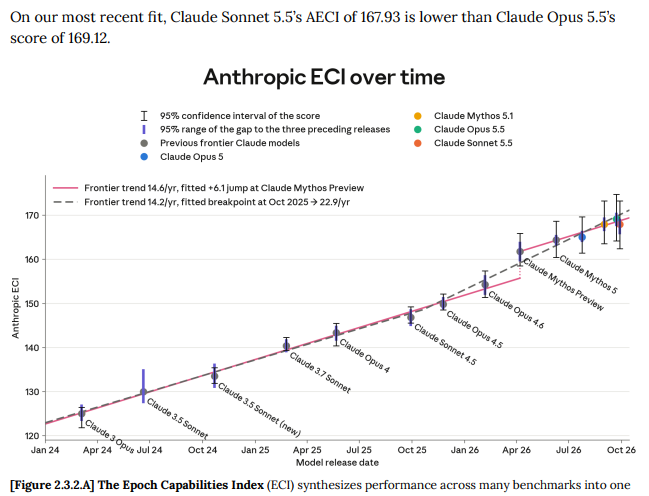
Sonnet chart:
For the Opus 5.5 figure, the system card does mention a 1.53x acceleration in the caption [95% CI 1.2–1.82x], given the Sep 2025 breakpoint. However it noted at the time that the solid line (one-time jump at Mythos Preview) "is a better fit to the data in 99 of 100 resampled fits", so it rather strongly discounted the 1.53x acceleration reading.
For the Sonnet 5.5 figure, the system card doesn't mention an acceleration number, but dividing the given trend figures 22.9/14.2, it's about 1.61x.
So we might summarize the evolution of this capabilities acceleration estimate as:
System Card | Fits to AECI trendline charted | Acceleration of AECI growth post-breakpoint | Stated fit preference |
|---|---|---|---|
Fable/Mythos 5.1 | pre-Mythos-Preview trend only | ~1x (implied) | one-time jump on Mythos Preview |
Opus 5.5 | jump +5.9 AECI on Mythos Preview | 1.53× | one-time jump on Mythos Preview |
Sonnet 5.5 | jump +6.1 AECI on Mythos Preview | ≈1.61× | none stated |
Haiku 5.5 | jump +7.3 AECI on Mythos Preview | 1.70× | none stated |
METR | break Oct 7, 2025, AECI slope 15 → 29/year | 1.9× | trendline break at ~Oct 2025 |
In other words, we're consistently updating this estimate of AI capabilities acceleration upward…[5]
- ^
EDIT: Worth noting that if you only look at Anthropic models on Epoch's ECI (as Anthropic's AECI does), then the acceleration is ~1.45x. More investigation into AECI vs. ECI in this comment and near the bottom of this comment.
- ^
IMO AI agents became "actually good" at coding in November with GPT-5.1/Gemini 3/Opus 4.5. It's kind of interesting that the Haiku system card trendline instead starts roughly with Sonnet 4.5, released on 9/29/25. And METR's chosen breakpoint is 10/7/25, which I understand to be fitted rather than arbitrary. (Other Anthropic model releases in that time period: Haiku 4.5 on 10/15/25, Opus 4.5 on 11/24/25.)
- ^
EDIT: While Zvi did not comment on Haiku 5.5's figure so far as I've found, he commented on 9/23/26 on a similar figure from the earlier Opus 5.5 system card (see more info on that below):
AECI, Anthropic’s spinoff of the Epoch Capabilities Index, is right on trend, but it is on the shifted Mythos-level trend not the old Opus-level trend. Is that still on-trend? I think basically no.
and then afterward he quotes analysis from METR that the system card quotes:
The estimate provided by the preliminary AI R&D report is ‘~1.5X overall acceleration in capabilities due to AI (i.e. 1.5 years in 1 year), with perhaps 30% chance of 2X acceleration.
which Zvi describes (correctly!) as a bombshell.
- ^
Fable 5.1's system card has an AECI figure (Figure 2.3.5.A), but doesn't try to refit at a breakpoint.
- ^
EDIT: You might wonder how the AECI slope keeps increasing from Opus 5.5 ➡ Sonnet 5.5 ➡ Haiku 5.5, when only the first is a frontier model. That's because Anthropic appears to be running new versions of the AECI across all models for each new system card, and this has mostly been shifting AECI scores for post-Oct-2025 models upward.
 1
Yeah I think that's a plausible explanation of what happened here. First we thought "oh Mythos Preview was a one-off discontinuity", then "well maybe there's a trendline break after coding agents got good, but the Mythos Preview discontinuity theory looks stronger". When later data from the Sonnet 5.5 and Haiku 5.5 system cards came out, and included both theories, we either didn't notice or still preferred the Mythos Preview theory even though it was less and less convincing. And now that METR got data on unreleased models, it looks very unconvincing.
There's a couple other things going on here I think:
- This is only looking at AECI for Anthropic's models. If you look at AECI trends across all frontier models, the acceleration is "merely" 1.4x because GPT and Gemini were at the AECI frontier for a while. However today's METR report notes as a possible caveat that perhaps Anthropic's earlier models were less benchmaxxed than their contemporary GPT/Gemini models and 1.9x is closer to the "true" acceleration.
- Anthropic's internal AECI does not show the same trends as Epoch AI's public ECI. Doing some quick analysis: (EDIT: the METR report includes their own analysis here)
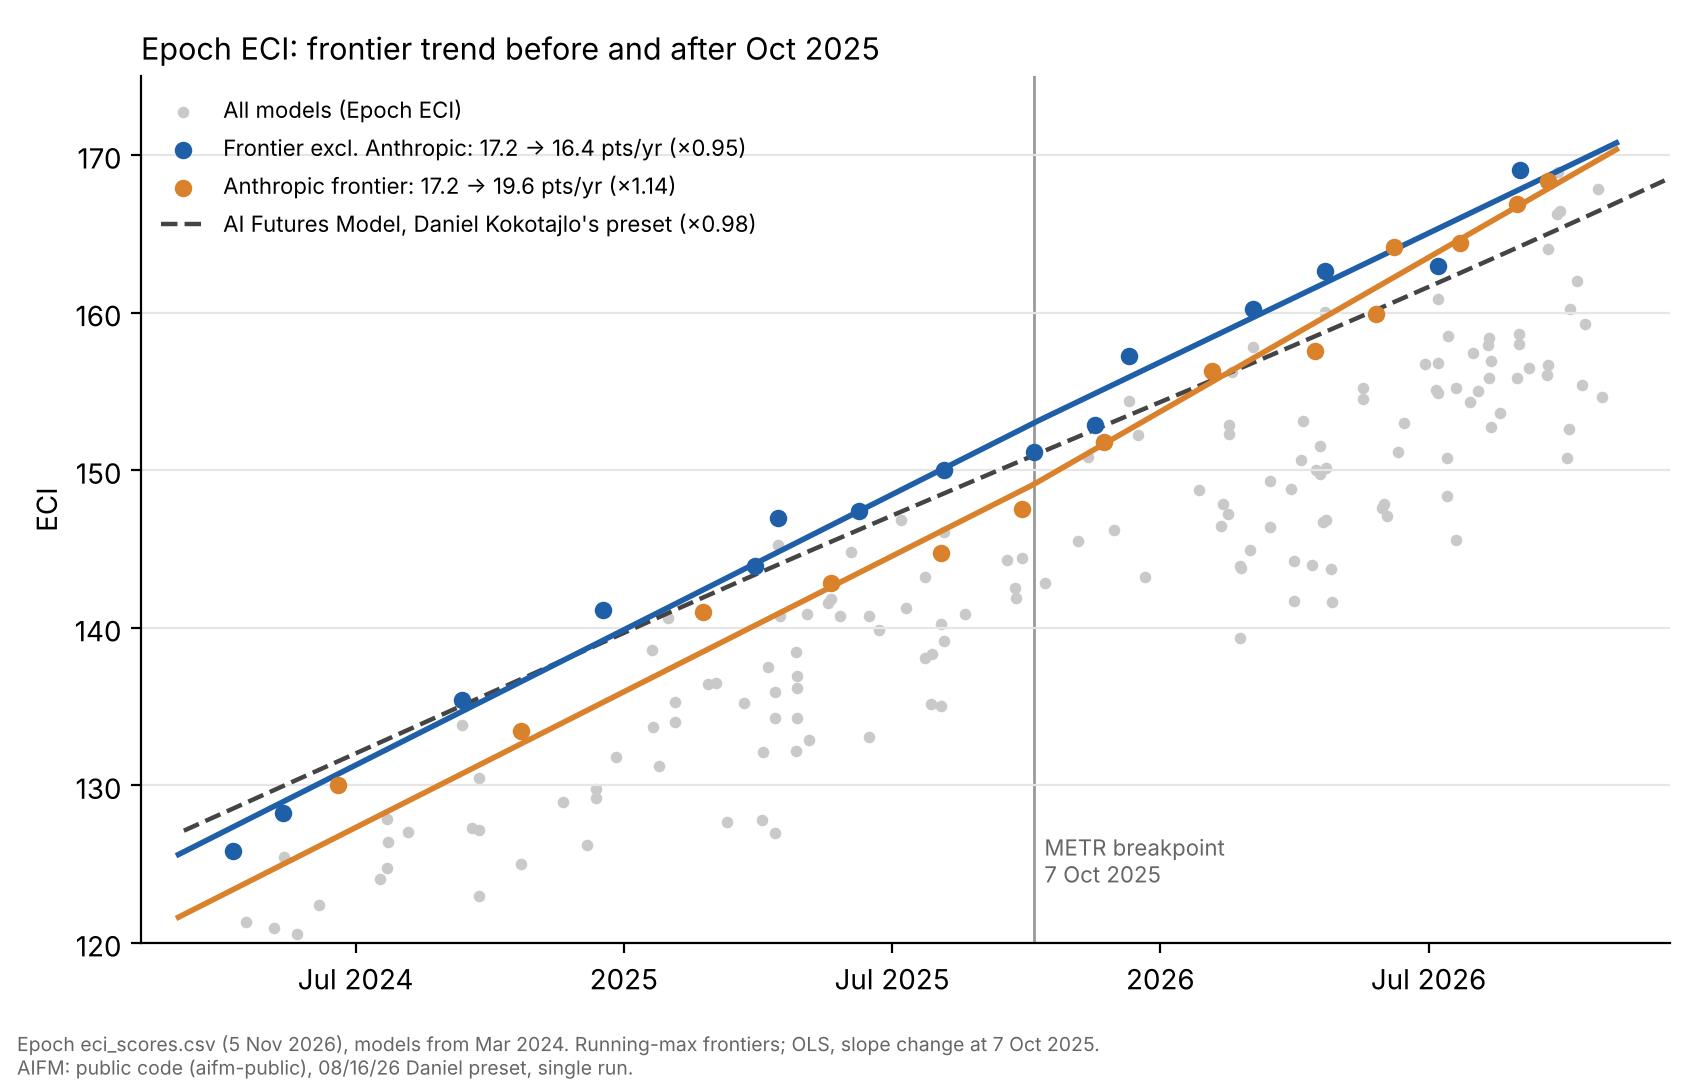
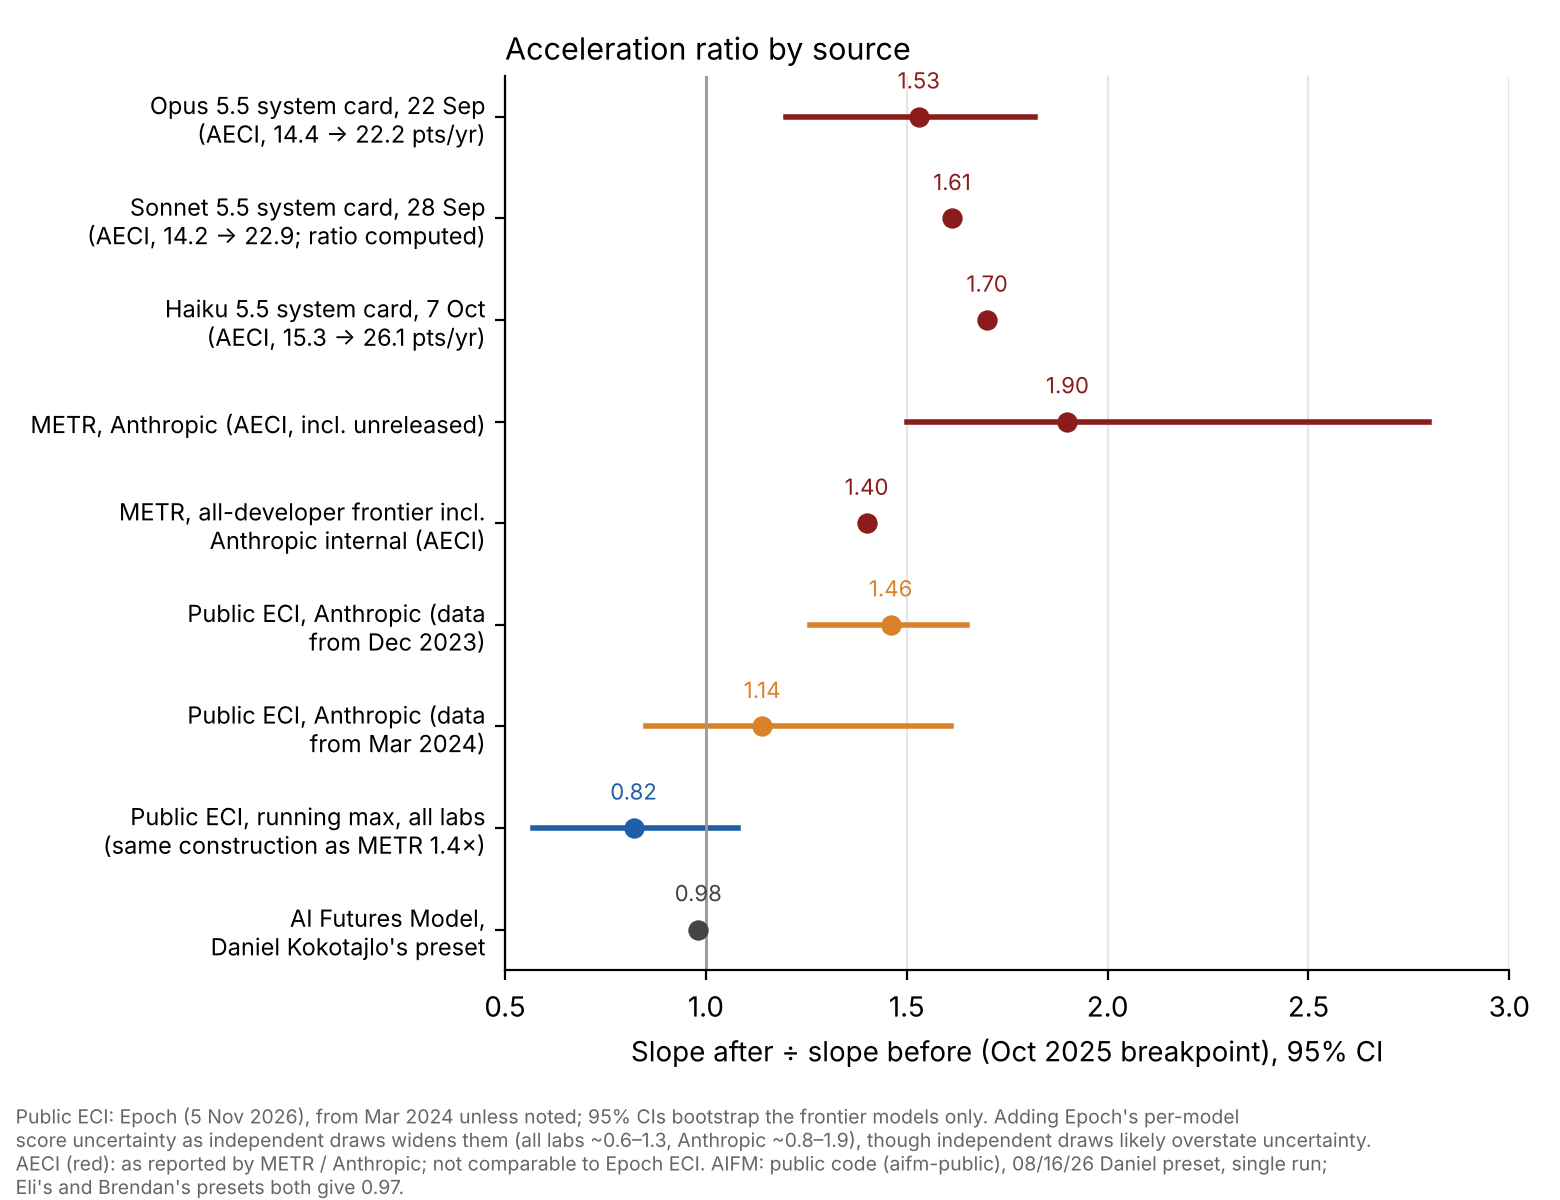
You can see here that the public ECI frontier data actually estimates slight deceleration in capabilities growth, which is also what the AI Futures Model predicts, due to deceleration in compute growth and an expectation that, prior to an Automated Coder, ECI growth is primarily a function of "effective compute", which is a combination of growth in training compute and software algorithmic efficiency growth. The model predicts that the latter would accelerate, but not enough to outweigh the deceleration in training compute (up till now anyway).
On the (speed, efficacy) frontier in coding abilities, I would argue Opus 5.5 > Fable/Mythos 5.1 (subjective). wouldn’t be surprised if a lot of the AECI benchmarks were to be coding-related or generally crisp tasks (note the report stressing several times that their acceleration estimates are relative to well-specified tasks).
1Taking these reports at face value, it seems that barring a sudden discontinuity in Anthropic's internal rate of acceleration (due to some unforeseen algorithmic bottleneck) or a global coordinated AI pause, vastly superintelligent AI capable of automated R&D (and obviously a lot of other things) will be developed in the next 3-6 months.
Is it not reasonable to gauge this as anything but the most significant event in human history? How can one plan for the future, and with any reasonable confidence weigh the utility of any choice they make when God in a box may arrive in less than a year?
That the highest signal on this impending reality the general public has access to is buried in a few graphs from an independent evaluation agency seems an absurd anticlimax. A private company(ies?) will possess a technology effectively more intelligent and capable in any domain than any other entity on the planet.
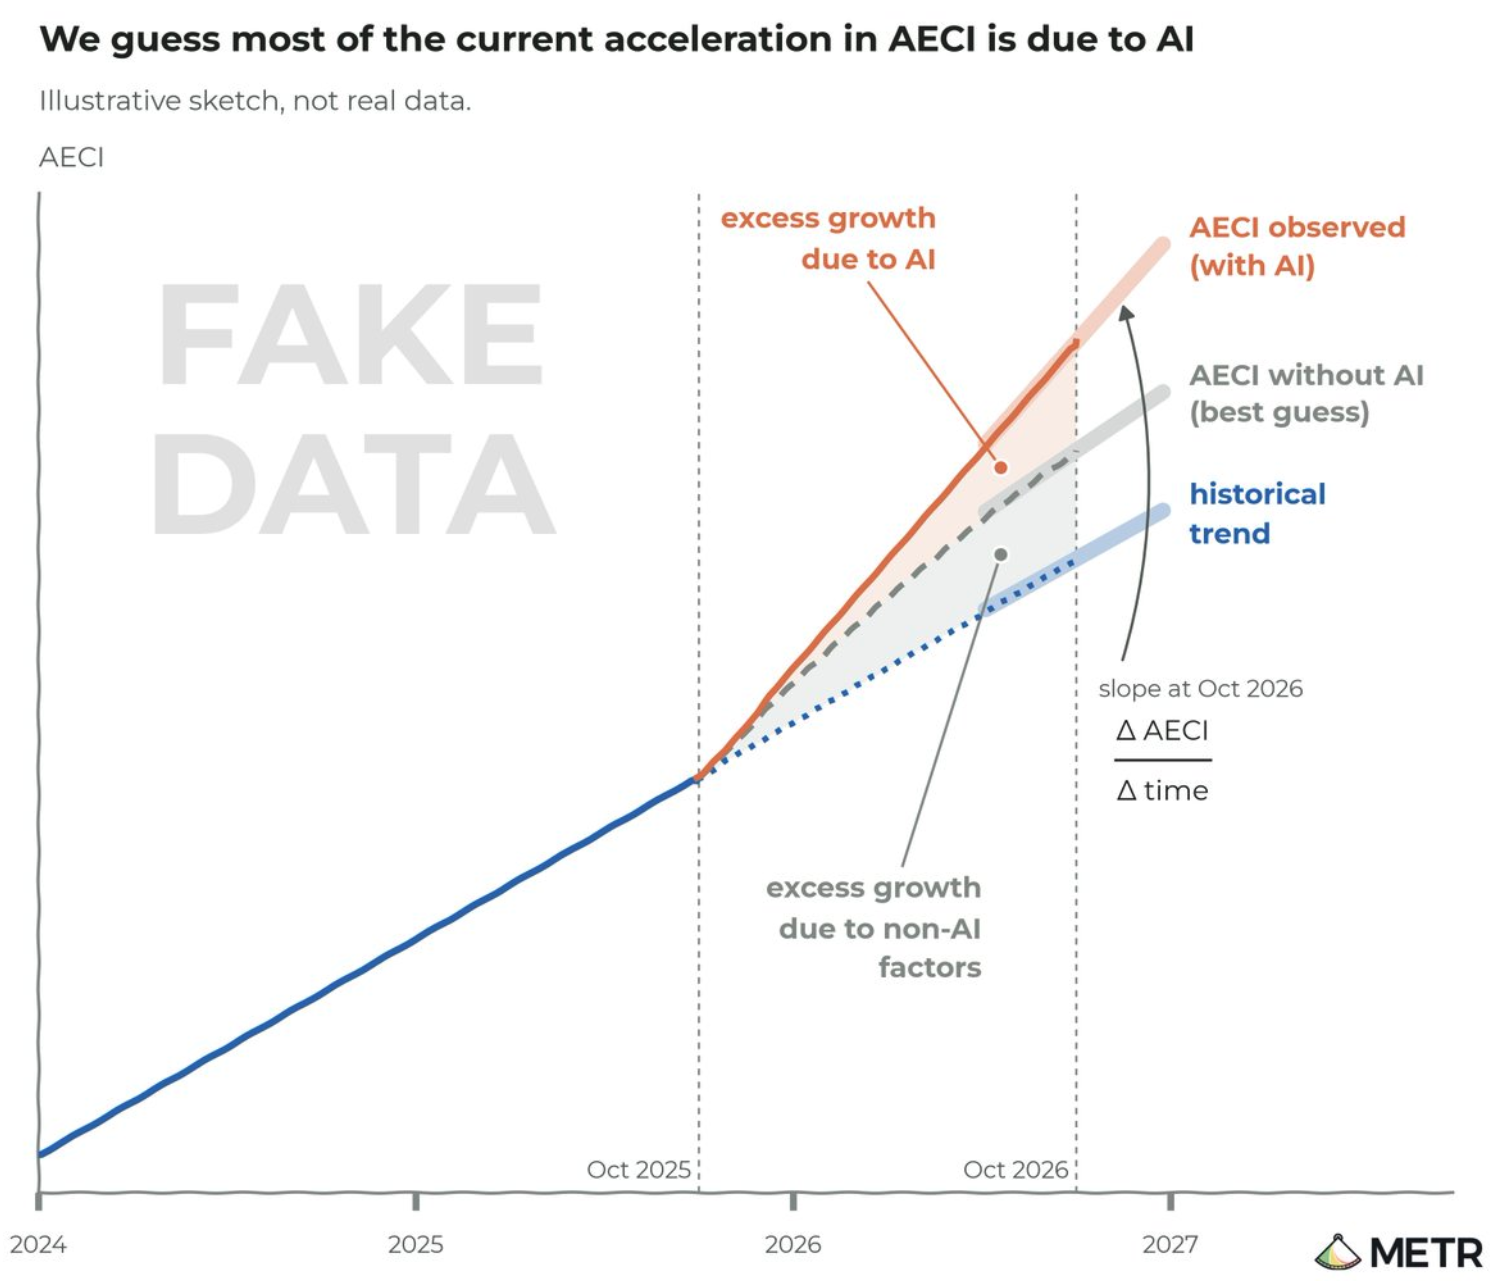
1I think this is an interesting plot, though I acknowledge that it's labeled FAKE DATA.
The prose goes into a lot of detail estimating the change between the blue and orange lines and reporting the ratio of the slopes as "overall acceleration" which they estimate is about 80% due to AI. Claude's pixel analysis of this fake data yields an initial AI share of acceleration of 8% and a final share of 77%, which corresponds pretty closely to their published 80% estimate, so while the data may be fake I don't think they're completely arbitrary.
So METR's conclusion is motivated by some combination of the estimated slope change in Oct 2025 and separate evidence about AI's contribution to the rate of progress which basically wasn't shared at all.
One remark: if they think only the tail of the series is tracking the AI contribution, then fitting to earlier points (i.e. between Oct 2025 and ~June 2026) should be making their estimate of AI acceleration worse, unless the earlier non-AI reason for acceleration happens to track the AI acceleration exactly (and there's no obvious reason to think it would). Fitting to the tail is obviously quite noisy, and it's not clear that their answer would be any different (by my eyeball, the tail fits the trend change reasonably well), so maybe the numbers come out about the same.
Anyway, the situation seems a bit messy. The trend change analysis does seem important to the bottom line conclusion, but so do other pieces of non-public reasoning.
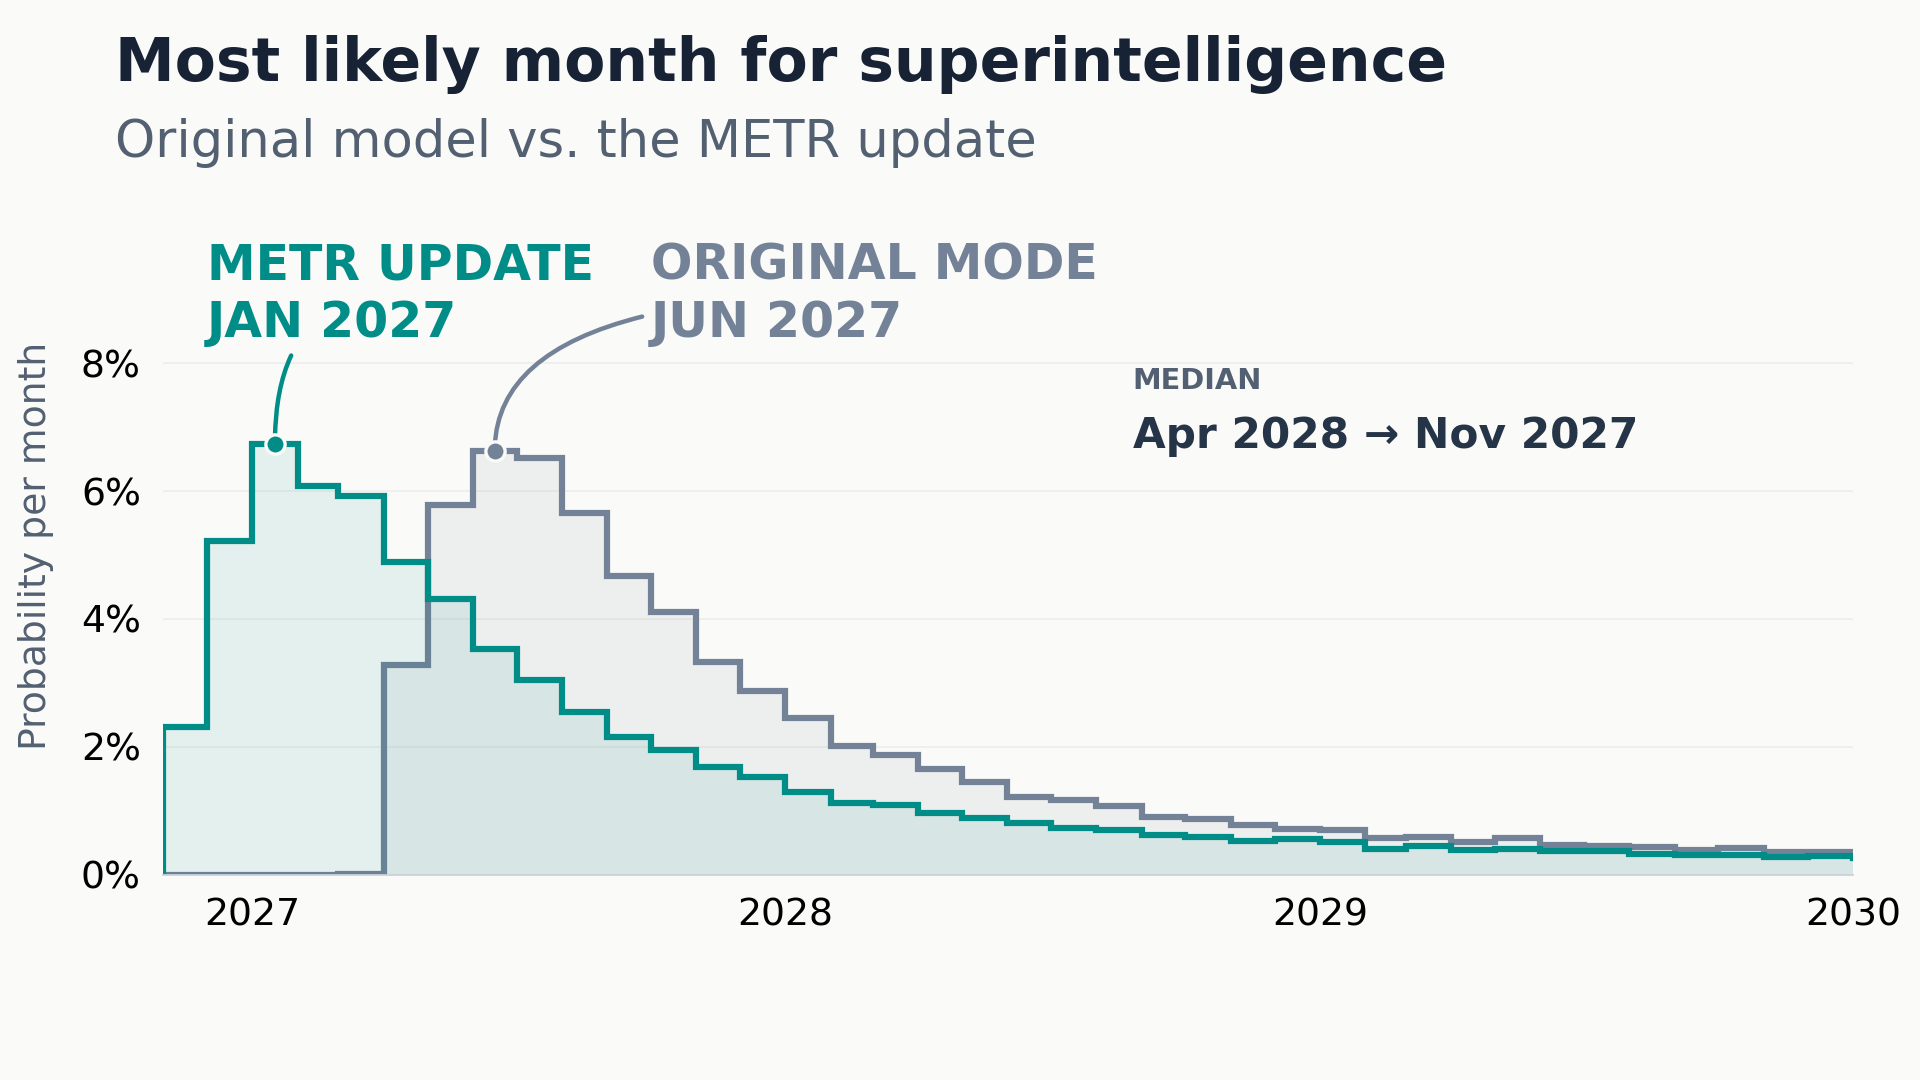
I ran these numbers with the AI 2027 model through Codex, produces a new most likely month for superintelligence: January 2027
(I also took this tweet in account comparing the different definitions of uplift https://x.com/eli_lifland/status/2118430709379682691
update: Lot's of people perhaps are hung up on: METR says it is 2x faster now but doesn't AI 2027 also say it is 2x faster now, so the models match? Apparently no, because in AI 2027's model a speedup of 2x only corresponds to a real speedup of say 1.5x because their model corrects for bottlenecks (compute) and diminishing returns. METR however measures actual speedup with these baked in. That's my understanding
update: people seem to think this is false, but seems we are about 4-5 months ahead of schedule and in their code on github they assume superhuman coder at march 31st with Superhuman AI researcher soon after and superintelligence after that. 4-5 months ahead would mean superhuman coder is about now which sounds reasonable especially given that they already use an internal model 4 that is much more capable.
update: https://x.com/RyanGreenblatt/status/2118447235289817503
 31
Twitter thread.
Ryan Greenblatt:
Ajeya Cotra:
Daniel Kokotajlo: says the METR report confirms his worry from two days ago, which was:
See also GradientDissenter's take.