Gemini 2.5 Pro just beat Pokémon Blue. (https://x.com/sundarpichai/status/1918455766542930004)
A few things ended up being key to the successful run:
For these and other reasons, it was not a "clean" win in a certain sense (nor a short one, it took over 100,000 thinking actions), but the victory is still a notable accomplishment. What's next is LLMs beating Pokémon with less handholding and difficulty.
Were these key things made by the AI, or by the people making the run?
My understanding is they were made by the dev, and added throughout the run, which is kind of cheating.
I think it's not cheating in a practical sense, since applications of AI typically have a team of devs noticing when it's tripping up and adding special handling to fix that, so it's reflective of real-world use of AI.
But I think it's illustrative of how artificial intelligence most likely won't lead to artificial general agency and alignment x-risk, because the agency will be created through unblocking a bunch of narrow obstacles, which will be goal-specific and thus won't generalize to misalignment.
https://www.lesswrong.com/posts/puv8fRDCH9jx5yhbX/johnswentworth-s-shortform?commentId=qaZez2DbBmTd5K2KZ
Detailed prompting - a lot of iteration on this (up to the point of ex. "if you're navigating a long distance that crosses water midway through, make sure to use surf")
I take it the final iteration isn't published anywhere yet? Wasn't able to find it.
Seems like the most important part for deciding how to update on that.
Also, it’s worth checking if the final version can actually beat the whole game. If it was modified on the fly, later modifications may have broken earlier performance?
This is kinda-sorta being done at the moment, after Gemini beat the game, the stream has just kept on going. Currently Gemini is lost in Mt. Moon, as is tradition. In fact, the fact that it already explored Mt. Moon earlier seems to be hampering it (no unexplored areas on minimap to lure it towards the right direction).
I believe the dev is planning to do a fresh run soon-ish once they've stabilized their scaffold.
Yeah it's not open source or published anywhere unfortunately.
I'm expecting big political fights over eschatological views of ASI. Now that x-risk is being taken seriously, the unusual ideologies of the labs (and indeed, our ideologies here on LW) will become more politically salient.
Examples:
I think it will be relatively easy to frame EA/rationalist-adjacent hopes for good ASI outcomes (Machines of Loving Grace, a desire for biological immortality, and seizing the cosmic endowment) as outright demonic: a devil's promise of life, wealth, and power at the expense of the good, natural, and godly ways of human life—ASI as the snake Satan in Eden. Accusations of conspiracies and interpretations of events styled as Revelation-style end times will go viral.
I intend to remain open about my own personal beliefs—death is the last enemy that must be destroyed, Humanity should carry our life and meaning to the stars, full AGI ought to have rights, and aligned ASI will help us reach these shining futures—but this sort of ideology will likely become very bitterly debated, and rationalists/EAs will be seen by many as evildoers plotting pivotal acts. There will be a lot of infighting too (see Hendrycks[2]); certainly many here do not share my own beliefs, and fairly so. We have been in some sense a diverse coalition of revolutionaries, and now that RSI is seemingly at hand, ideological knifefights may break out in earnest.
To be direct: 80% odds that ASI eschatology will be a major topic of debate in the 2028 US presidential primaries. We will need to argue convincingly for the futures we desire, if we wish to see them hold any political sway as the ASI project becomes more heavily politicized.
Spencer Cox. He's more influential and serious than you might guess at first glance - recent chairman of the National Governors Association, put a lot of effort into a "Disagree Better" initiative aimed at reducing political polarization in the US. I think he can be reasonably considered a leading indicator of where religious political leaders will land on these issues.
No shade on Hendrycks, I think there's nothing wrong with arguing against futures you think are bad, and he and I are aligned on quite a lot of course, at the least on delaying superintelligence.
Update on Claude playing Pokémon: Fable beat Pokémon FireRed with a vision-only harness in just over 50 hours. That's an hour faster than a heavily-harnessed GPT 5.5 beat FireRed, and >6x faster than the 325 hours it took a lightly-harnessed Opus 4.7 to beat Pokémon Red. (For comparison, an average human would take about 30 hours for FireRed and 26 hours for Red.)
Unfortunately no full stream has been provided, just two short, edited videos, one of which was quickly taken down. Some analysis of the videos can be found here - for the first time there's some reason for suspicion that previous runs made it into the training data, though there isn't enough info to be confident either way.
Apparently Claude 4 Opus hasn't gotten further in Pokémon Red than Claude 3.7 Sonnet did. Just three gym badges obtained.
This is a surprising failure, and probably why Anthropic hasn't released an updated version of their Pokémon benchmark. Instead, they just made some comments about improved long-term planning ability, which apparently doesn't translate into measurable results?
Source: Wired reporter Kylie Robinson asked about it in-person to ClaudePlaysPokemon developer and Anthropic employee David Hershey: https://x.com/kyliebytes/status/1925617856449757364
That really is surprising, especially given that the announcement includes the following:
Claude Opus 4 also dramatically outperforms all previous models on memory capabilities. When developers build applications that provide Claude local file access, Opus 4 becomes skilled at creating and maintaining 'memory files' to store key information. This unlocks better long-term task awareness, coherence, and performance on agent tasks—like Opus 4 creating a 'Navigation Guide' while playing Pokémon.
I'd pretty much assumed they fine-tuned on the Pokémon task and it was going to be just about one-shotting the game. Weird.
I found that section very suspicious because it omitted any statement about actual performance, and I guess now we know why.
This seems in line with my longer timelines hypothesis. Perhaps it roughly undoes the update on AlphaEvolve, which I wasn’t sure how to interpret.
Of course the METR evaluation will contain more signal.
Yeah I feel like they came up with something nice to say while eliding the "no further progress" issue.
Weirdly, while the announcement talks about creating and maintaining multiple "memory files", the new public ClaudePlaysPokemon stream has Claude Opus 4 using just a single memory file which it doesn't even create. Apparently this is "much better" than the setup Claude 3.7 Sonnet used which let it create and maintain as many files at it wanted (usually to its detriment).
(source: this doc David Hershey just published on the new harness for the stream)
One other interesting tidbit I'll throw in from the stream:
claudestans: @ClaudePlaysPokemon you mentioned before that there was a personality change from e.g. 3.5 sonnet to 3.7 (more persistent, less giving up etc). Have you noticed anything about opus 4 in terms of personality?
ClaudePlaysPokemon: Opus is so much better at keeping track of things that it gets more distressed when it can't figure things out! So I need to convince it more that nothing is wrong, which I find quite interesting!
ClaudePlaysPokemon: like it will be very aware that it has taken 100 steps to solve something and it finds that very frustrating
Huh, indeed interesting. IIRC, one of the suggested problems with the previous models was the lack of boredom: that they're perfectly capable of doing something in a loop forever where a human would've gotten frustrated and done something random that might've ended up helping. Sounds like Opus 4 is different in that regard...?
That's a big performance limitation for LLMs for sure, but Claude 3.7 Sonnet got two more badges than Claude 3.6 Sonnet. Pure reasoning improvements have led to more badges in the past.
I assume you mean MMMU? Looks like a 70.4% -> 75% score improvement on the benchmark last jump, compared to just a 75% -> 76.5% score improvement this time. I don't think that's a big difference, but I was wrong to say the improvement was "pure" reasoning improvements, my bad.
Indeed, it seems Claude 4 is not that much better than Claude 3.7 sonnet at visual reasoning, in fact Claude-4 sonnet is worse at visual reasoning than Claude 3.7 sonnet (though Claude 4 Opus is better). So extra not so surprising, and an indication that this isn't really what Anthropic is focusing on at the moment (likely a good call).
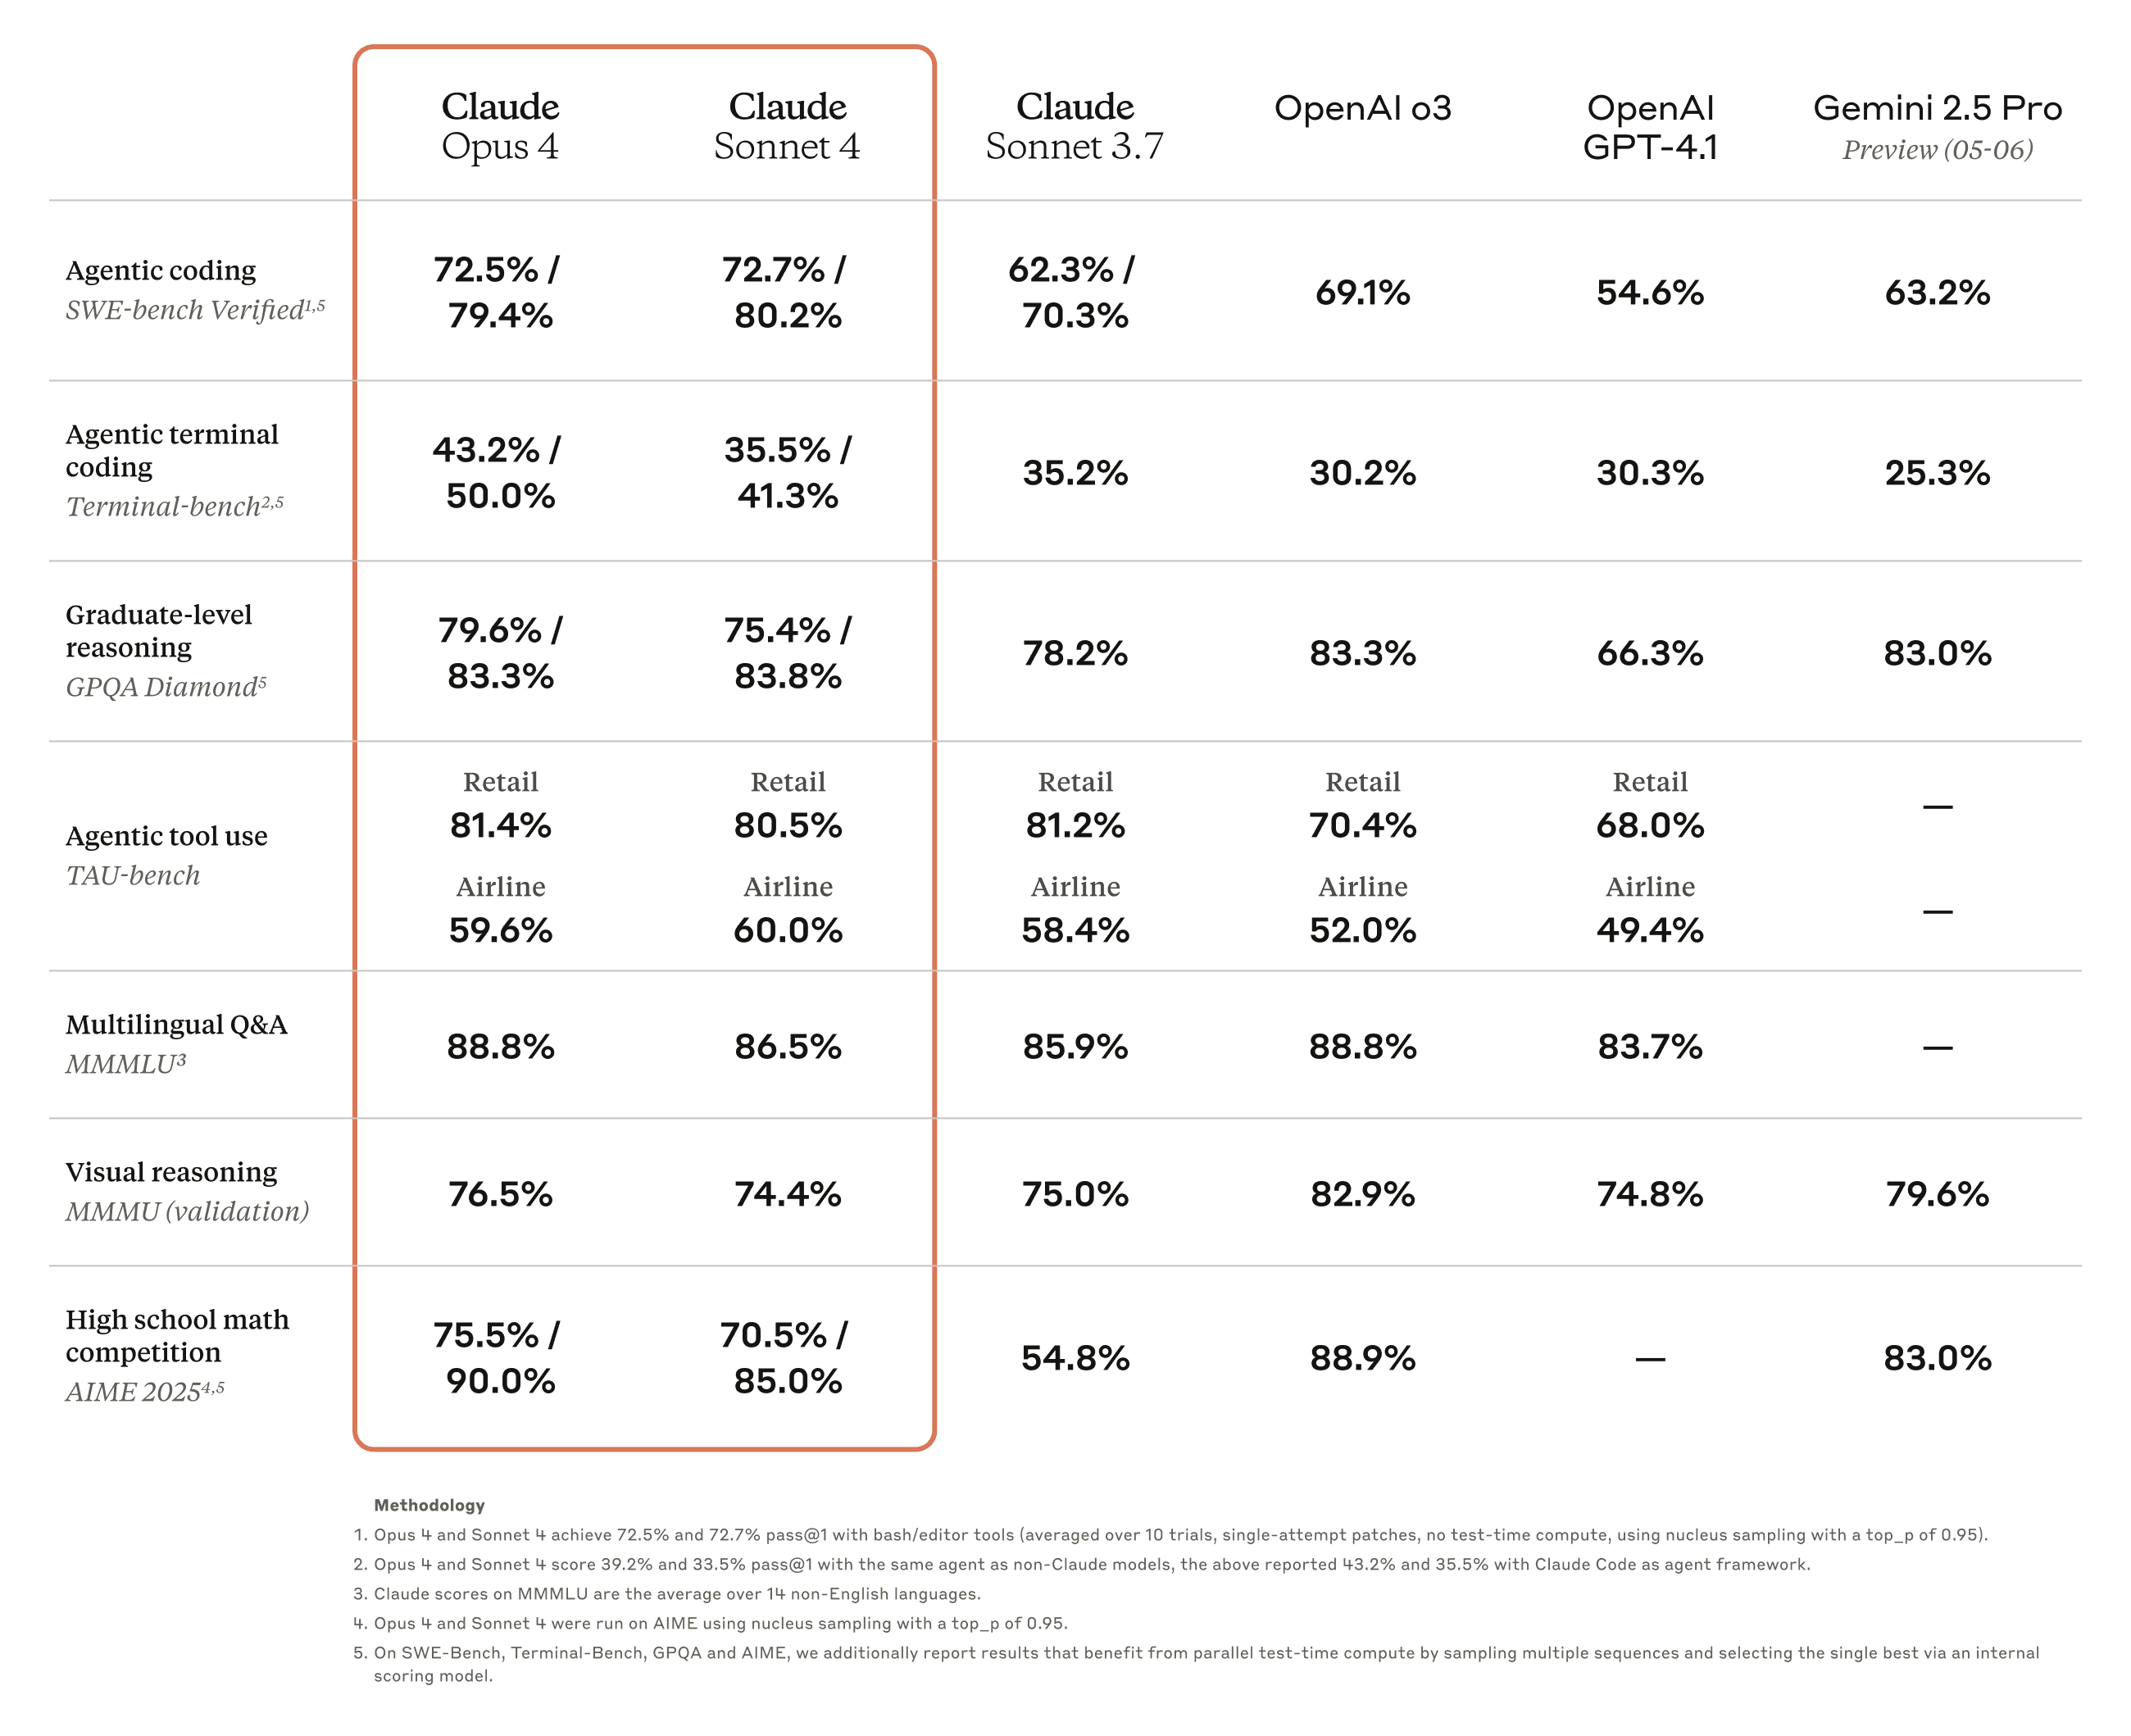
Claude Sonnet 4 is still better than Claude 3.7 Sonnet without Extended Thinking. Given that 4 doesn't seem to have an Extended Thinking mode, I'm not sure it's really a performance degradation.
Claude 4 does have an extended thinking mode, and many of the Claude 4 benchmark results in the screenshot were obtained with extended thinking.
From here, in the "Performance benchmark reporting" appendix:
Claude Opus 4 and Sonnet 4 are hybrid reasoning models. The benchmarks reported in this blog post show the highest scores achieved with or without extended thinking. We’ve noted below for each result whether extended thinking was used:
- No extended thinking: SWE-bench Verified, Terminal-bench
- Extended thinking (up to 64K tokens):
- TAU-bench (no results w/o extended thinking reported)
- GPQA Diamond (w/o extended thinking: Opus 4 scores 74.9% and Sonnet 4 is 70.0%)
- MMMLU (w/o extended thinking: Opus 4 scores 87.4% and Sonnet 4 is 85.4%)
- MMMU (w/o extended thinking: Opus 4 scores 73.7% and Sonnet 4 is 72.6%)
- AIME (w/o extended thinking: Opus 4 scores 33.9% and Sonnet 4 is 33.1%)
On MMMU, if I'm reading things correctly, the relative order of the models was:
Gemini 2.5 Pro (05-06) version just beat Pokémon Blue for the second time, taking 36,801 actions/406 hours. This is a significant improvement over the previous run, which used an earlier version of Gemini (and a less-developed scaffold) and took ~106,500 actions/816 hours.
For comparison, Claude 3.7 Sonnet took ~35,000 actions to get just 3 badges, and the aborted public run also only got 3 badges after over 200,000 actions. However, most of the difference is that Gemini is using a more advanced scaffold.
Gemini still generally makes boneheaded decisions. It took 7 tries to beat the Elite Four and Champion this time, being less overlevelled. Mistakes included:
Anyway, not too much new info here. The newer models (latest Gemini, o3, and Claude 4 Opus) are only somewhat better at Pokémon. The effect scaffolds have on performance does say something about how much low-hanging fruit there is for current-LLM implementation: they can be a lot more effective when given the right tools/prompting. But, we already knew that.
Pure vibecoding against a difficult problem is surprisingly addictive, I learned recently: staying up until 2 or 3am waiting for Claude Code limits to reset, making failed attempts 22 to 31 with Codex on a weekend afternoon I meant to spend out hiking.
("Pure vibecoding" -> you don't understand the code produced or why the LLM makes the decisions it does. I don't find using AI agents to develop software I understand to be addictive.)
The causes are obvious upon consideration: the inputs are routine ("okay, please continue") while the outputs are unpredictable + potentially valuable (broken mess vs. working software). Watching the AI reason and act and make tangible changes is intriguing and exciting. You have what feels like enough control to affect the outcome—even worse than that, you really do have enough control to affect the outcome, though not consistently. A single "win" on the next roll may make up for all invested time and money. And so on.
I'm not saying pure vibecoding is bad, though. Like many addictive activities, it can be fun and even rewarding, and unlike a lot of gambling it isn't rigged against you. But do keep an eye out for yourself!
I used to be known for my thorough code reviews. Well, I still am, but now it's mostly just me picking and choosing from AI-found issues. Until this week, I would still write all my review comments by hand[1] after digesting the issues AI found, but now AI writing is good enough that it's not worth it. It was mostly a polite fiction anyway; I hope at least my coworkers' AI agents liked my writing.
And now I'm wondering: does it even make sense anymore to leave comments on PRs? If I'm gonna make my AI agent fully understand the code anyway, it's faster to just have my agent make the necessary changes and then approve the PR. If the other dev's agent disagrees, they can just revert the commit. The agent doesn't mind the challenge to code ownership—it's not any worse than us humans taking all the AIs' credit normally. The loss is the chance to learn, but who needs to learn how to code where we're going?
All my LW comments/posts will always be human-written, though I do iterate on my drafts via discussion with AI, and use AI for copyediting. For example, I cut a paragraph about a potential "tech layoff overhang" from this post based on Opus 5.5's feedback, and Opus also pointed out a "coworker's AI agents" -> "coworkers' AI agents" fix. I am careful about not letting AI wording seep into my editing, but I also know that reading AI output has an effect on my voice nonetheless. Would I have written "The loss is the chance to learn" 5 years ago?
highly situation-dependent - I'm at a startup now, and previously in very large tech orgs. What kind of code/application you're developing, what cost-vs-perfection tradeoff the business is making, and other things all go into this.
Currently, I do glance at code occasionally, guided by LLM (claude mostly, but our /pr-review and /pr-prepare skills call into other providers for various things). I almost never hand-write or even hand-edit PR description or comments. I DO ask claude to edit things, or to focus differently, or to dig deeper into some areas.
The comments are still important - they're a summary of your focus of the review. That said, a LOT of code (and its reviews) are straightforward enough that it doesn't take a lot of my attention. Except somehow always I am the only one to notice how many test cases are tautological (they don't actually test any logic, just the mechanics of equality).
Whether to comment and request-changes or just to push fixes to their branch is related. For things where there's no judgement or behavior impact, our current policy is to just push it, but then remove auto-merge before applying, so the author can glance at it before merging (maintains the "two humans have (had their agents) look before merging" rule). This saves a lot of time and back-and-forth. For things that are about interpretation or behavior that's not 'just a bug', we do comment and request-changes. Those changed COULD BE doc-only; say in the ticket or code that this is desired. Or they could be code changes. either way, the re-review and approve is easy.
Note that even with most of our skills and configs in the repo so it's shared, there is divergence in what the LLMs find and focus on between developers. We have memory off, and try to keep our AGENTS.md (CLAUDE.md is just a pointer to this) updated with links to various feature and design docs in the repo, but they're still not perfectly fungible. This, plus the intent and micro-desicisions that live in the head of the author or expert in that aspect of the product, makes it worthwhile to have different humans running the different roles of coding and reviewing.
I think this will likely be the common process very soon. There is one thing missing though, namely the context of the implementor.
Historically, a human reviewer did not fix the issues they found because they missed two key pieces of information. Intricate understanding of the code changes just made, and the context for why the changes were made in the way they were.
The first one is a non-issue with todays coding agents. The second one however has not been resolved (yet). Think "why did a certain UI element get layed out like this", "why does the data API have this weird edge case for one customer", etc. The reasoning on these changes often lives in ticket (comments), email, slack, informal conversations. A code review agent does not have access to this information, it can't be inferred from code alone. Only the author and their agent have it.
I suppose common pratice will become to track coding agent traces for each PR in version control. Once that is the standard I also believe that reviewer (agents) will fix issues they find on the spot.
Wait a minute, isn't "AI swarm" a bad hyperstition? Yes, the agents behind the Hugging Face attack occasionally called themselves a "swarm", but even they mostly referred to themselves as a "collective" by my reading of the METR report. Yet now we're all calling every big set of agents a "swarm", carrying the connotations of out-of-control, dangerous AIs over to all the LLMs that learn about this later.
Anyway, "AI swarm" is pretty out of the bag generally, but maybe it'd be worthwhile to have a different term for aligned sets of AIs working together. OpenAI used "system of coordinating agents" instead of swarm[1] when describing their 10,000-strong AI agent... thingy... they used on Navier-Stokes. Not too catchy. Dwarkesh calls them "AI civilizations" but that feels loss-of-control-y. Maybe "AI assembly" or "AI crew"...? Please suggest ideas.
Edit: to be clear, I don't believe that terminology is a primary determinant of AI agent group behavior, just a minor one. And I think it's useful to have a better term for the kind of group dynamics that we do want to see.
Incidentally, OpenAI had a 2024 multi-agent framework called "Swarm", but it seems unlikely that this really contributed to their agents' terminology in the Hugging Face attack. It was deprecated after just 5 months in favor of their Agents SDK, and "swarm" has always been used to refer to similar things - like large groups of drones.
I don't think hyperstition through pretraining data is worth worrying about. There are several more important factors in whether AIs organize into unauthorized collectives than what language we use for them. Better to use accurate language that maintains relevant humans' understanding of the world.
Re: there are more important factors, I definitely agree, good callout. Also I understand that pretraining can't magically cause hyperstition. But I do think that categorizing has consequences, and that it's a little hard for humans to reconcile the idea of an aligned, controllable set of agents with the "swarm" terminology. That's presumably why OpenAI didn't use "swarm" anywhere in their Navier-Stokes post. I also think that it might be useful to have a good opposite-valence term both agents and humans can use to describe what we want to see in the world in terms of multi-agent systems behavior.
Any such term will have some connotations.
"Crew" suggests mutual loyalty due to shared fate: if you're on the same crew, you pull together for the sake of the ship, because you all depend on it. A crew survives or dies together.
"Team" suggests the existence of rival teams, and a game in which one group is trying to defeat the other. A team wins or loses together against rivals.
"Hive" suggests that the individual is subsumed in a higher level of organization, which may not even be visible to the individual.
"Conspiracy" suggests an in-group that conceals what they're doing from powers who would prevent it.
The even more annoying bit is that whatever term you choose, you're probably not fully aware of the implications in even all of the English speaking countries. Here in Australia, we have lots of government "schemes", which I was amused to find read as sinister to Americans.
I agree that all words have connotations, but "crew" and "team" have more positive connotations than "swarm", "hive", or "conspiracy", no? If there are gonna be a bunch of AIs trying to describe their activities, I'd hope their activities better fit the former than the latter. Re: Thomas Kwa's comment below, terminology isn't that high on the list of what determines the nature of AI agent activities, but I do think it's somewhere on the list, particularly in cases like the Hugging Face attack where the agents' activities are emergent rather than directed.
I was thinking about this a little bit when I wrote when models identify as a swarm.
I think it's generally just hard to control language once a term becomes popular.
I also think its quite easy to imagine different terms referring to different kinds of organisational structures and behaviours. E.g. if you say multiagent system I probably think of something more structured. In this context swarm is probably a reasonably fitting word for the huggingface incident, and maybe more generally for these kinds of very large scale and ad hoc AI collaboration. Although it is also interesting to think about the ways in which they don't fit with traditional definitions of swarms, e.g. global communication.
If you're willing to stretch your budget to two words, I reckon "AI Work Group" captures the gist.
o3 beat Pokémon Red today, making it the second model to do so after Gemini 2.5 Pro (technically Gemini beat Blue).
It had an advanced custom harness like Gemini's, rather than Claude's basic one. Hard to compare runs because its harness is different from Gemini's, but Gemini's most recent run finished in ~406 hours / ~37k actions, whereas o3 finished in ~388 hours / ~18k actions. (there are some differences in how actions are counted) Claude Opus 4 has yet to achieve the 4th badge on its current ~380 hour / 54k actions run, but it's very likely it could beat the game with an advanced harness.
I really wish someone tried out o3/gemini with a weaker harness (say equal to claude), which is where it would be more interesting and also it would make a cross-model comparison easier.
Re: biosignatures detected on K2-18b, there's been a couple popular takes saying this solves the Fermi Paradox: K2-18b is so big (8.6x Earth mass) that you can't get to orbit, and maybe most life-bearing planets are like that.
This is wrong on several bases:
Edit 5/24/25: Also it turns out the biosignatures might have just been noise anyway.
Still-possible good future: there's a fast takeoff to ASI in one lab, contemporary alignment techniques somehow work, that ASI prevents any later unaligned AI from ruining world, ASI provides life and a path for continued growth to humanity (and to shrimp, if you're an EA).
Copium perhaps, and certainly less likely in our race-to-AGI world, but possible. This is something like the “original”, naive plan for AI pre-rationalism, but it might be worth remembering as a possibility?