This is a special post for quick takes by Jacob_Hilton. Only they can create top-level comments. Comments here also appear on the Quick Takes page and All Posts page.
The future of human mathematics
Cross-posted from Twitter; written for mathematicians.
About a year ago, I wrote that superhuman math AI will plausibly arrive in the late 2020s/early 2030s. It now looks like if anything, I was underestimating the pace of progress. In this post, I will try to say something about the sociological implications for mathematics.
I don't want to focus too much on the predicament of the mathematical community today; instead, I'll try to take a longer-term view, and say something about where I think human mathematics might eventually end up. For the sake of argument, I'll assume that within the next decade or so, AI systems are developed that are vastly more capable than humans at every mathematical task (including proving theorems, building theories, and explaining mathematics to humans), and that there nevertheless remains a community of human mathematicians, alive and well, and with funding to pursue mathematics as they please. What would such a community be doing?
Of course, in this hypothetical, mathematicians are not pursuing mathematics for any productive purpose; that is handled by the machines. They are pursuing mathematics for its own sake. There is ...
 2
At ARC, we have been using "AI use levels" to make it easy to disclose whether and how AI was used to create a piece of content. They were designed with mathematics in mind, but they should be useful beyond that. I am sharing them in case others find them to be a useful standard.
- AI0 (no non-trivial AI use): no AI use at all, except perhaps in trivial or tangential ways, e.g. explaining background material, finding relevant literature, or rewriting prose at the level of individual phrases.
- AI1 (fully human digested and composed): AI had a non-trivial role in producing mathematical ideas, but these were entirely digested by a human, who wrote everything by hand (again except for trivial writing assistance). In particular, a human actively made all decisions about how to structure the write-up, how to define terminology, how to organize proofs, and so on.
- AI2 (fully human verified and edited): AI may have been heavily involved in producing both the mathematical ideas and the written content, but a human went through the content line by line, checked that it was correct and comprehensible, and made at least a minimal attempt to edit the content for clarity.
- AI3 (human–AI mixture): may con
 2
Superhuman math AI will plausibly arrive significantly before broad automation
I think it's plausible that for several years in the late 2020s/early 2030s, we will have AI that is vastly superhuman at formal domains including math, but still underperforms humans at most white-collar jobs (and so world GDP growth remains below 10%/year, say – still enough room for AI to be extraordinarily productive compared to today).
Of course, if there were to be an intelligence explosion on that timescale, then superhuman math AI would be unsurprising. My main point is that superhuman math AI still seems plausible even disregarding feedback loops from automation of AI R&D. On the flip side, a major catastrophe and/or coordinated slowdown could prevent both superhuman math AI and broad automation. Since both of these possibilities are widely discussed elsewhere, I will disregard both AI R&D feedback loops and catastrophe for the purposes of this forecast. (I think this is a very salient possibility on the relevant timescale, but won't justify that here.)
My basic reasons for thinking vastly superhuman math AI is a serious possibility in the next 4–8 years (even absent AI R&D feedback loo...
 4
Two facts about text watermarking that seem to be frequently misunderstood:
- There exist watermarking schemes such that it is completely impossible for users to ever distinguish between watermarked and non-watermarked text. (A tempting but invalid argument is that no such scheme can exist because watermarking consumes entropy.)
- The above property does not hold of watermarking schemes that labs claim to actually use (though I would still expect well-tuned versions to make essentially no practical difference to users).
When I say "completely impossible", I mean it in the everyday sense, i.e., not possible to perform using any machine that could feasibly be built, assuming the integrity of the scheme remains intact (so stealing the secret key doesn't count). I do not mean "impossible with infinite computational resources".
On my first point: watermarking does reduce the information-theoretic entropy of generated text in order to insert its cryptographic footprint. However, what matters is not information-theoretic entropy, but computational entropy (often called "pseudoentropy"): roughly, the maximum entropy of a distribution that is indistinguishable to a computationally bounded observer....
 1
7
Thanks for this Jacob — excellent analysis.
I'm a huge fan of Bradley-Terry models. I'm quite sure they are the natural way of representing noisy contests like chess ability and that Elo is an inferior way. They key thing with Bradley-Terry is that each competitor has a raw ability score (e.g. A and B) and that then when they have a contest the odds of A beating B is just A:B. I think of it as each player puts a number of tickets of their colour into a hat and then one is drawn at random determining the winner. This is an even simpler interpretation than the one from the Hex paper and makes the 2/3 result even more intuitive.
Elo then takes the log base 10 and multiplies by 400 and then adds 1200 or so to make the numbers usually positive, injecting three (!) arbitrary constants into the mix in order to give an additive scale that matched the pre-Elo chess rating scale — but the natural interpretation of these contests is a multiplicative scale (the ratio of the numbers is the odds ratio of winning) so it should have been left alone. Linear progress in Elo is really exponential progress in the raw quantity.
I like your idea of assuming random difficulties for the different tasks (from some distribution that could be tweaked), as clearly that is part of the real underlying phenomenon. However, it is weird that you compare the highest number the agent draws from the hat to the highest number the task draws. More natural would be to have to take on the tasks one by one in a gauntlet of challenges of varying difficulty. e.g. that the probability of success is Πn1pi instead of my Πn1p where pi is a random variable drawn from some natural distribution over [0,1] that is modified by the agent's skill and represents the probability of succeeding at that subtask. There should be limiting cases where all pi are equal (my case) and where it is driven by the hardest one. But I'm not sure what distribution this creates.
That said, I like where you are going with this and ho
2
How does this coefficient relate to the maximal slope (i.e. at the 50%-x)?
2
In figure 5 the X axis is log time horizon and not time horizon - does this fit with your model?
4
Yes, unless I messed up, METR's code runs a logistic regression of log2(task duration) against success probability, so my model predicts a raw fitted coefficient (the second column in the table) close to -ln(2) ≈ -0.69.
Oh right sorry I missed the derivation that among samples, the maximum is equally likely to be any of them and so the probability that the largest number from the model the largest of them is
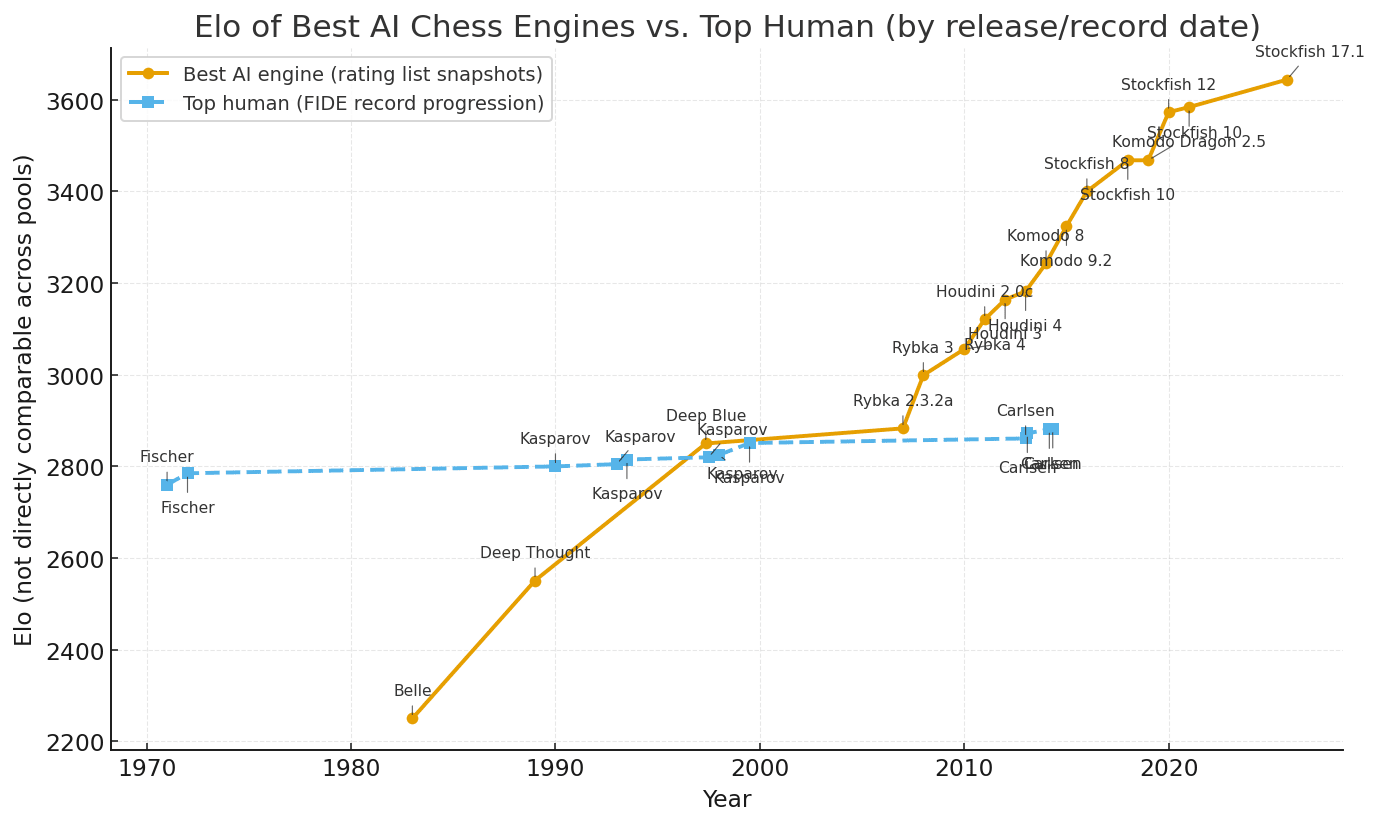
This model then predicts that models "ELO ratings" - would grow linearly over time, which (based on this chart GPT5 gave me) I think corresponds roughly with the progress in chess from 2007 onwards
 1
Against superexponential fits to current time horizon measurements
I think is unreasonable to put non-trivial weight (e.g. > 5%) on a superexponential fit to METR's 50% time horizon measurements, or similar recently-collected measurements.
To be precise about what I am claiming and what I am not claiming:
- I am not claiming that these measurements will never exhibit a superexponential trend. In fact, I think a superexponential trend is fairly likely eventually, due to feedback loops from AI speeding up AI R&D. I am claiming that current measurements provide almost no information about such an eventuality, and naively applying a superexponential fit gives a poor forecast.
- I am not claiming that is very unlikely for the trend to be faster in the near future than in the near past. I think a good forecast would use an exponential fit, but with wide error bars on the slope of the fit. After all, there are very few datapoints, they are not independent of each other, and there is measurement noise. I am claiming that extrapolating the rate at which the trend is getting faster is unreasonable.
- My understanding is that AI 2027's forecast is heavily driven by putting substantial weight on s
32Thanks for writing this up! I actually mostly agree with everything you say about how much evidence the historical data points provide for a superexponential-given-no-automation trend. I think I place a bit more weight on it than you but I think we're close enough that it's not worth getting into.
The reason we have a superexponential option isn't primarily because of the existing empirical data, it's because we think the underlying curve is plausibly superexponential for conceptual reasons (in our original timelines forecast we had equal weight on superexponential and exponential, though after more thinking I'm considering giving more weight to superexponential). I think the current empirical evidence doesn't distinguish much between the two hypotheses.
In our latest published model we had an option for it being exponential up until a certain point, then becoming superexponential afterward. Though this seems fairly ad hoc so we might remove that in our next version.
The main thing I disagree with is your skepticism of the meta-skills argument, which is driving much of my credence. It just seems extremely unintuitive to me to think that it would take as much effective compute to go fr...
1