This is a special post for quick takes by Lao Mein. Only they can create top-level comments. Comments here also appear on the Quick Takes page and All Posts page.
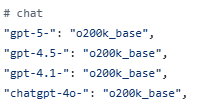
Edit: In hindsight, I mean something more like "GPT5 uses the same tokenizer as GPT4o. GPT5 isn't using the new big base model they've been cooking for the past year, since that would almost certainly use a different tokenizer. That said, it is entirely possible they trained a new base model of ~ the same size as GPT4o, but incorporating algorithmic improvements like the ones present in R1."
Is there a public source for this claim? Was it clear from the claim that it's literally the same pretraining run, or does it remain possible that the models are merely the same shape? (Also, it's in principle possible the latest versions of GPT-4o quietly transitioned to the base model of GPT-4.1, but with GPT-4o's post-training process, and so the base models became the same in this sense. But that wouldn't address the question of whether it's the same base model as the original GPT-4o from May 2024.)
In any case, GPT-4.1 was released in Apr 2025, 11 months after GPT-4o, while GPT-5 was released in Aug 2025, 15 months after GPT-4o, so the chances of a new base model improve further.
[...]
This doesn't necessarily mean much, the KV cache optimizations could even damage them, but still enable longer contexts for the same generation cost. Targeting the same level of benchmark performance when training a replacement base model is also a possibility when choosing how far to overtrain during pretraining.
It's at 7:19 in the podcast, the claim is that the standard-sized GPT-4.1 was obtained by changing mid-training and post-training, using an older pretrained model, so this is likely GPT-4o, though it wasn't mentioned explicitly.