6 Answers sorted by
6011
1. Are the historically leading AI organizations—OpenAI, Anthropic, and Google—holding back their best models, making it appear as though there’s more parity in the market than there actually is?
4. Is it plausible that once LLMs were validated and the core idea spread, it became surprisingly simple to build, allowing any company to quickly reach the frontier?
I'll try to address just these two points with what I know, which is limited.
OpenAI, Anthropic, Google / Google Deepmind, Meta, AWS, and NVIDIA are the main current holders of AI compute hardware. Of these, the majority of frontier engineering talent (and expressed intent to race for AGI) seems to be concentrated in OpenAI, Anthropic, and Google / Google Deepmind. I think of these as a group I call 'the Top 3'.
So far as the public knows, the Top 3 are working hard on preparing the next generation of LLMs (now all multimodal, so LLM is a bit of a misnomer). Preparing a next generation takes time and effort from the researchers, plus engineering support and training time on the large clusters. We are roughly halfway through the expected interval between full-step versions (e.g. GPT-4 to GPT-5). Of these companies, my best guess is that OpenAI has a slight lead, and thus will probably deploy their next gen (i.e. GPT-5) before the other companies deploy theirs (Claude 4 Opus, Google Gemini 2 Ultra). The time lag may be a couple of weeks or as much as six months. Hard to say for sure. Google has a lot of resources, and so might slightly beat OpenAI.
In any case, the big differentiator in terms of the Top 3 versus the Rest is the massive amount of hardware. GPT-4 level was something that could be trained on a wide variety of different rentable resources. The scaling trend suggests that the next level up, GPT-5, will require more resources than the Rest are expected to be able to muster this year. Since hardware is advancing, some members of the Rest may acquire GPT-5 level resources late next year (2025) or early 2026. This means they'll be quite a few months behind. As for the implied resources needed for GPT-6 level if scaling trends and costs continue on trend, it seems unlikely that most of the Rest will be able to afford to scale that large (even acting late, and with rented resources) with the exception of Meta and possibly xAI.
Current opinion, which I agree with, puts Claude 3.5 Sonnet at about 4.25 - 4.3 level compared to GPT-4. All of the others (including GPT-4o) fall somewhere in-between level 4 and level 4.3
Nobody has a level 5 yet because even the leaders haven't had the time to create and deploy it yet!
As for "secret sauce" ideas, we haven't yet gotten public knowledge about any secret knowledge being a hard blocker. It does seem like there is a fair amount of small technical secrets which improve compute efficiency or capabilities in minor ways, but that these can all be compensated for by spending more on compute or coming up with alternate approaches. There is a huge amount of ML research being published every month now because the field has gotten so lucrative and trendy. The newest public research isn't yet present in the deployed models because the models were trained and deployed before the new research was published!
This makes for a strange dynamic that those companies which are lagging slightly behind in getting their large training runs started get the advantage of later cut-off date for incorporation of public research. I think that getting to incorporate more of the latest research is a significant part of the explanation for why the GPT-4-sized models of late-movers have slightly surpassed GPT-4.
This doesn't imply that OpenAI is losing the race, or that they don't have valuable technical secrets. The Top 3 are still in the lead, so far as I can foresee, they just are in the 'hidden progress' phase which comes between model generations. Because of this, we can't know their relative standing for certain. Presumably, even they don't know since they don't have the details on the secret tech that their competitors are putting into their next generation. We will need to wait and see how the next generation of the Top 3's models compare to each other.
I think a little more explanation is required on why there isn't already a model with 5-10x* more compute than GPT-4 (which would be "4.5 level" given that GPT version numbers have historically gone up by 1 for every two OOMs, though I think the model literally called GPT-5 will only be a roughly 10x scale-up).
You'd need around 100,000 H100s (or maybe somewhat fewer; Llama 3.1 was 2x GPT-4 and trained using 16,000 H100s) to train a model at 10x GPT-4. This has been available to the biggest hyperscalers since sometime last year. Naively it might...
 1
*
5416The release of Llama 405b was the thing that most succinctly explained this to me. At least when it comes to the current generation of cutting edge LLMs, there is no secret sauce. Llama 405b is a cutting edge model with, as far as I can tell, no advances in architecture or training compared to the development of GPT-3. Indeed, it appears in architecture substantially simpler than GPT-4 while outperforming it, suggesting that in the long-run, simplicity of architecture tends to win out, especially if you are willing to take a relatively small (<3x) compute-cost hit.
The architecture is a straightforward transformer with no mixture of experts or anything fancy:

The training process did nothing interesting. It used the most obvious implementation of supervised fine-tuning and reinforcement training.
The data cleaning process was somewhat more involved, and we know less about, but I think is unlikely to have done anything like synthetic data generation or complicated AI-assisted review.
This might all again change with the next generation of LLMs (especially with things like Strawberry, which looks like it might do something more interesting), but at least right now, I think almost any competent engineering team in the world could build a cutting-edge AI model, if they were just willing to spend the compute. It requires overcoming some minor engineering challenges, but the basics of how to do this are figured out. There is no moat.
 41
I think 405b is 2x too much data according to chinchilla while GPT3 is 8x too little data
They did the Chinchilla scaling experiments themselves, it's in the report (Section 3.2.1 Scaling Laws). The result claims that 40 tokens/parameter is actually optimal in their setup (2x more than in the Chinchilla paper), so Llama-3-405b is Chinchilla optimal in the relevant sense, it's not trained on too much data. The result is slightly suspicious in that their largest datapoints are 1e22 FLOPs, while Llama-3-405b itself is 4e25 FLOPs, so that's a lot of extrapolation. But overall they find that the optimal tokens/parameter ratio increases with compute, more so than in the Chinchilla paper, and Llama-3-405b had more compute than Chinchilla.
This is also consistent with the CARBS experiments done by Imbue (search for "tokens per parameter"):
Another interesting finding is the optimal number of tokens per parameter. We found this optimal number to be slightly increasing across our range of experiments (see the dashed black line). Note that our methodology differed from that of Chinchilla in a few significant ways: we explicitly scaled the number of machines together with the model size, effectively changing the batch size.
 2
2822
Twitter AI (xAI), which seemingly had no prior history of strong AI engineering, with a small team and limited resources
Both of these seem false.
Re: talent, see from their website:
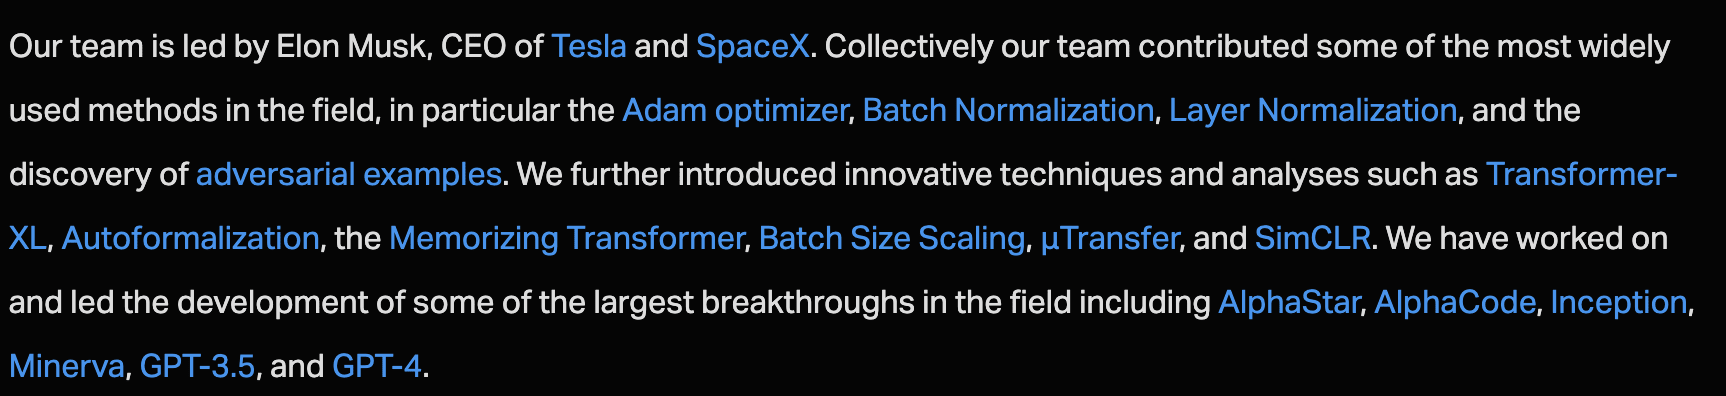
They don't list their team on their site, but I know their early team includes Igor Babuschkin who has worked at OAI and DeepMind, and Christian Szegedy who has 250k+ citations including several foundational papers.
Re: resources, according to Elon's early July tweet (ofc take Elon with a grain of salt) Grok 2 was trained on 24k H100s (approximately 3x the FLOP/s of GPT-4, according to SemiAnalysis). And xAI was working on a 100k H100 cluster that was on track to be finished in July. Also they raised $6B in May.
 3
11-2
- Is this apparent parity due to a mass exodus of employees from OpenAI, Anthropic, and Google to other companies, resulting in the diffusion of "secret sauce" ideas across the industry?
No. There isn't much "secret sauce", and these companies never had a large amount of AI talent to begin with. Their advantage is being in a position with hype/reputation/size to get to market faster. It takes several months to setup the infrastructure (getting money, data, and compute clusters), but that's really the only hurdle.
- Does this parity exist because other companies are simply piggybacking on Meta's open-source AI model, which was made possible by Meta's massive compute resources? Now, by fine-tuning this model, can other companies quickly create models comparable to the best?
No. "Everyone" in the AI research community knew how to build Llama, multi-modal models, or video diffusion models a year before they came out. They just didn't have $10M to throw around.
Also, fine-tuning isn't really the way to go. I can imagine people using it as a teacher during the warming up phase, but the coding infrastructure doesn't really exist to fine-tune or integrate another model as part of a larger one. It's usually easier to just spend the extra time securing money and training.
- Is it plausible that once LLMs were validated and the core idea spread, it became surprisingly simple to build, allowing any company to quickly reach the frontier?
Yep. Even five years ago you could open a Colab notebook and train a language translation model in a couple of minutes.
- Are AI image generators just really simple to develop but lack substantial economic reward, leading large companies to invest minimal resources into them?
No, images are much harder than language. With language models, you can exactly model the output distribution, while the space of images is continuous and much too large for that. Instead, the best models measure the probability flow (e.g. diffusion/normalizing flows/flow-matching), and follow it towards high-probability images. However, parts of images should be discrete. You know humans have five fingers, or text has words in it, but flows assume your probabilities are continuous.
Imagine you have a distribution that looks like
__|_|_|__
A flow will round out those spikes into something closer to
_/^\/^\/^\__
which is why gibberish text or four-and-a-half fingers appear. In video models, this leads to dogs spawning and disappearing into the pack.
- Could it be that legal challenges in building AI are so significant that big companies are hesitant to fully invest, making it appear as if smaller companies are outperforming them?
Partly when it comes to image/video models, but this isn't a huge factor.
- And finally, why is OpenAI so valuable if it’s apparently so easy for other companies to build comparable tech? Conversely, why are these no name companies making leading LLMs not valued higher?
I think it's because AI is a winner-takes-all competition. It's extremely easy for customers to switch, so they all go to the best model. Since ClosedAI already has funding, compute, and infrastructure, it's risky to compete against them unless you have a new kind of model (e.g. LiquidAI), reputation (e.g. Anthropic), or are a billionaire's pet project (e.g. xAI).
61
This is not an answer to the broader question, but just regarding the "no Wikipedia page" thing.
I would like to write a Wikipedia page about Flux, but as it is, there is very little quality information about it. We have a lot of anecdotal information about how to use it, and a little academic description of it, but that's not enough.
Besides, it seems everyone who can write well in artificial intelligence wants to write their damned academic blog that is read by like 10 people a month and not Wikipedia, and Wikipedia accumulates a large amount of badly written stuff by amateurs.
As an example, see this page
https://en.wikipedia.org/wiki/Generative_adversarial_network
The "Applications" section is a typical example of how stupid and badly formatted it is. Everything above it I wrote myself. Everything below it I only did a light amount of editing. Before I went in to write all of that in 2022-07 (2022! Imagine that! GANs were famous since about 2018 and it waited until 2022 to get a decent Wikipedia page?), the entire page was crap like it: https://en.wikipedia.org/w/index.php?title=Generative_adversarial_network&oldid=1096565363
Similarly for the Transformer. https://en.wikipedia.org/w/index.php?title=Transformer_(deep_learning_architecture)&oldid=1095579622 I have only recently finished writing it. https://en.wikipedia.org/wiki/Transformer_(deep_learning_architecture) and then I tried applying for "Good Article" status, and got promptly rejected for not putting enough inline citations (do they really want me to put inline citations everywhere even if that means I just have to refer to the Attention is All You Need paper 30 times?) and too much primary literature and too much arXiv links (not a peer-reviewed source).
The RNN page is also terrible https://en.wikipedia.org/w/index.php?title=Recurrent_neural_network&oldid=1214097285 until I cleaned it up. There is still a large amount of crud but I put all of them in the lower half of the page, so that people know when to stop reading. I put them there just in case some annoyed editor reverts my edit for deleting their favorite section, and in case there is something valuable there (that I can't be bothered to figure out, because of how badly written it is).
The list of crud goes on and on. The Convolutional Neural Network page is still absolutely terrible. It has a negative amount of value, and I'm too tired to clean it up.
Sometimes there's an important model that's entirely neglected. Like the T5 model series. https://en.wikipedia.org/wiki/T5_(language_model) Why this model had to wait until me in 2024 to finally write it, I have no idea.
P.S.: The damned Transformer page gets someone (always a different one) writing in some Schmidhuber-propaganda. I remove it once a month. Why there are so many fans of Schmidhuber, I have no idea.
Paging Gwern or anyone else who can shed light on the current state of the AI market—I have several questions.
Since the release of ChatGPT, at least 17 companies, according to the LMSYS Chatbot Arena Leaderboard, have developed AI models that outperform it. These companies include Anthropic, NexusFlow, Microsoft, Mistral, Alibaba, Hugging Face, Google, Reka AI, Cohere, Meta, 01 AI, AI21 Labs, Zhipu AI, Nvidia, DeepSeek, and xAI.
Since GPT-4’s launch, 15 different companies have reportedly created AI models that are smarter than GPT-4. Among them are Reka AI, Meta, AI21 Labs, DeepSeek AI, Anthropic, Alibaba, Zhipu, Google, Cohere, Nvidia, 01 AI, NexusFlow, Mistral, and xAI.
Twitter AI (xAI), which seemingly had no prior history of strong AI engineering, with a small team and limited resources, has somehow built the third smartest AI in the world, apparently on par with the very best from OpenAI.
The top AI image generator, Flux AI, which is considered superior to the offerings from OpenAI and Google, has no Wikipedia page, barely any information available online, and seemingly almost no employees. The next best in class, Midjourney and Stable Diffusion, also operate with surprisingly small teams and limited resources.
I have to admit, I find this all quite confusing.
I expected companies with significant experience and investment in AI to be miles ahead of the competition. I also assumed that any new competitors would be well-funded and dedicated to catching up with the established leaders.
Understanding these dynamics seems important because they influence the merits of things like a potential pause in AI development or the ability of China to outcompete the USA in AI. Moreover, as someone with general market interests, the valuations of some of these companies seem potentially quite off.
So here are my questions:
1. Are the historically leading AI organizations—OpenAI, Anthropic, and Google—holding back their best models, making it appear as though there’s more parity in the market than there actually is?
2. Is this apparent parity due to a mass exodus of employees from OpenAI, Anthropic, and Google to other companies, resulting in the diffusion of "secret sauce" ideas across the industry?
3. Does this parity exist because other companies are simply piggybacking on Meta's open-source AI model, which was made possible by Meta's massive compute resources? Now, by fine-tuning this model, can other companies quickly create models comparable to the best?
4. Is it plausible that once LLMs were validated and the core idea spread, it became surprisingly simple to build, allowing any company to quickly reach the frontier?
5. Are AI image generators just really simple to develop but lack substantial economic reward, leading large companies to invest minimal resources into them?
6. Could it be that legal challenges in building AI are so significant that big companies are hesitant to fully invest, making it appear as if smaller companies are outperforming them?
7. And finally, why is OpenAI so valuable if it’s apparently so easy for other companies to build comparable tech? Conversely, why are these no name companies making leading LLMs not valued higher?
Of course, the answer is likely a mix of the factors mentioned above, but it would be very helpful if someone could clearly explain the structures affecting the dynamics highlighted here.