This is a special post for quick takes by Daniel Kokotajlo. Only they can create top-level comments. Comments here also appear on the Quick Takes page and All Posts page.
Comment Permalink
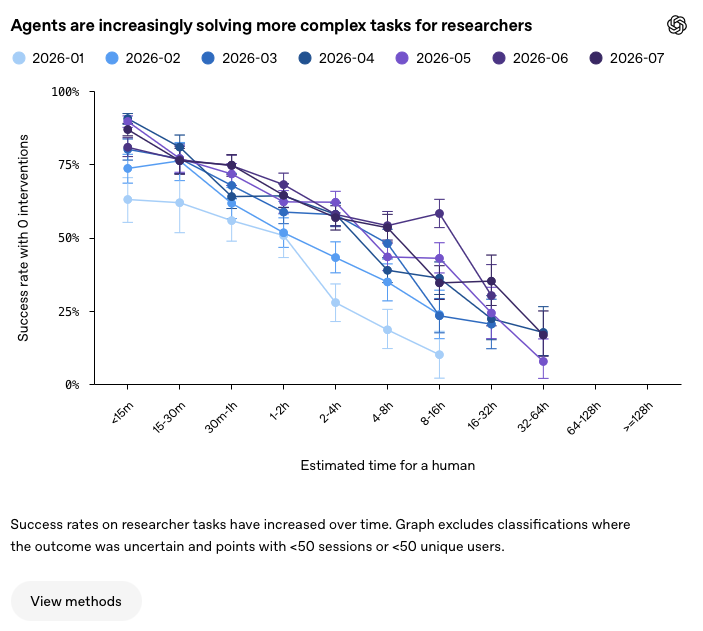
From the OpenAI post on research acceleration. A bunch of good data in there. This graph in particular caught my attention -- it seems to be measuring "In-practice horizon length" on real-world coding tasks happening at OpenAI.
The in-practice horizon length of OpenAI models seems to have gone from around 1-2h at the beginning of the year to something like 8h in July. So that's 2-3 doublings in half a year.
Also, the in-practice horizon length seems to be a bit less than the METR-measured horizon length, which was something like 5h at the start of the year (and is now unknown due to running out of long METR tasks).