This is a special post for quick takes by Matrice Jacobine. Only they can create top-level comments. Comments here also appear on the Quick Takes page and All Posts page.
So... what's the general take on the hantavirus outbreak?
 1
 1
I ran through my checklist. Looks low-risk to me. Basically a very deadly disease that nevertheless shows nil or inefficient human-to-human transmission and doesn't show signs of regional or global growth. It depends heavily on specific South American rat species for transmission to humans. The original exposure was on or around April 1. There are no new concerning mutations (see below), and so far the flight attendant who had been feared to have picked it up on a flight has tested negative, though there's an up to 6 week incubation period and she was exposed on April 25th, about 2 weeks ago. There were also 3 other plane passengers who had contact with an infected person on a plane and they've tested negative so far as well.
The consensus public health position is that "person-to-person transmission is possible through close personal contact, such as between couples." If it turns out that this is wrong and that it's much more human-transmissible than previously believed, then the complete failure to quarantine passengers after the discovery of hantavirus on the Hondius cruise ship and first passenger death would completely alter my projection. But so far, there do not seem to be s...
 4
7
Peter Wildeford on twitter
[...]
6
A Manifold market suggests an 8% chance of Hantavirus causing a pandemic in 2026


2
Posted some thoughts here (hadn't seen this thread yet, whoops)
1[anonymous]
Cruise ships, unfortunately, are prone to exacerbating any sort of disease outbreak due to their nature. For instance, back in 2020, aboard the Diamond Princess, Covid spread with an R0 5x higher than usual.
If anything, it's surprising that more people didn't get infected by this, which shows just how poor hantavirus is at human-to-human spread.
edit: update:
 8
 64
 2
I think it is important to note that the opportunity created by shifting x-risk sentiment, or the current "crunch time", is more of an opportunity to shift public sentiment around AI x-risk rather than politician sentiment.
In some cases, such as the US President, portions of the public will follow the politicians preferences; but in most cases this is not true.
The most valuable opportunity for reducing x-risk right now is that shifting public awareness and sentiment of AI X-risk could have a direct effect on the outcome of the upcoming US midterms.
So focusing on making AI risk as much of a bipartisan, public focus as possible is our greatest lever on how policymakers will be thinking about AI risk.
 1
5
I know it's not evidence for the simulation hypothesis, but our timeline seems like an exceptionally weird draw from the space of possible ones.
4
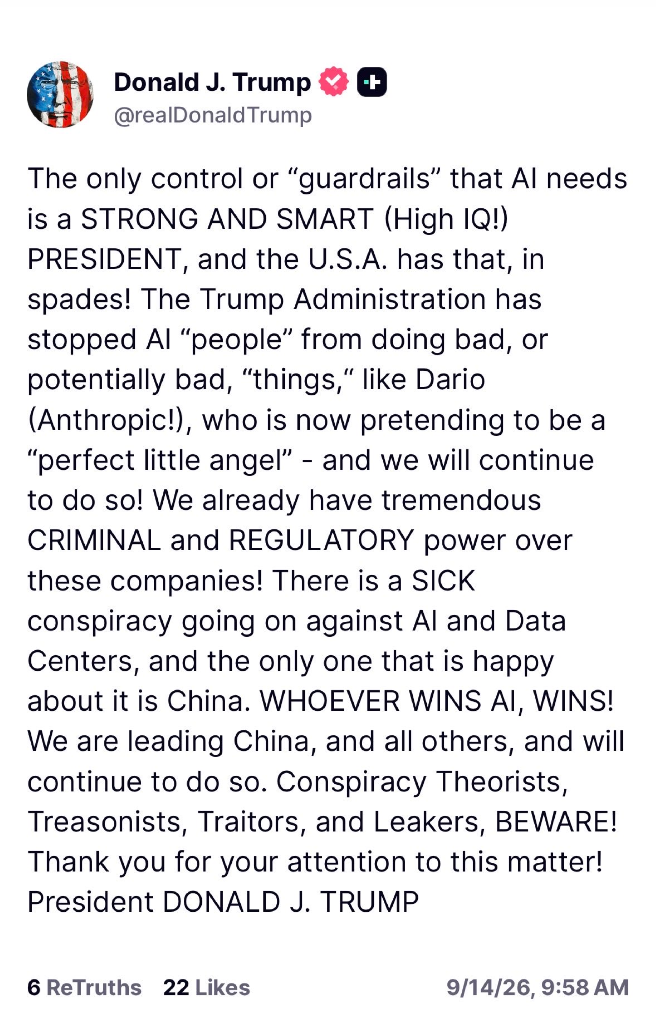
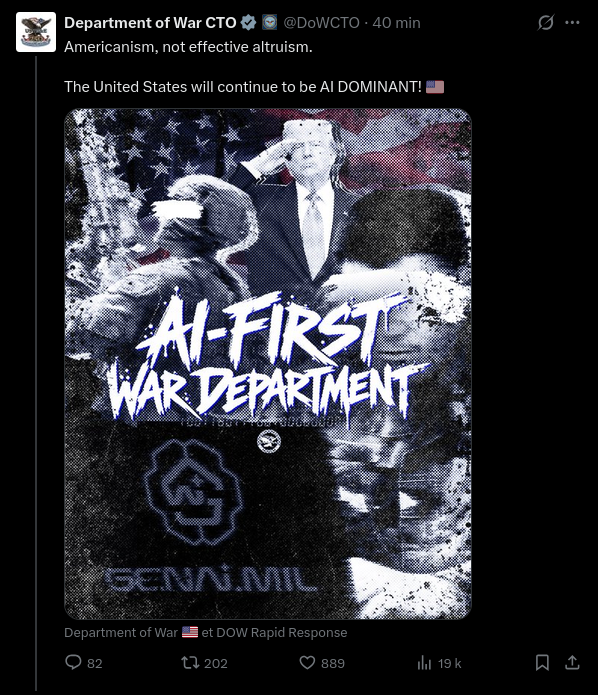
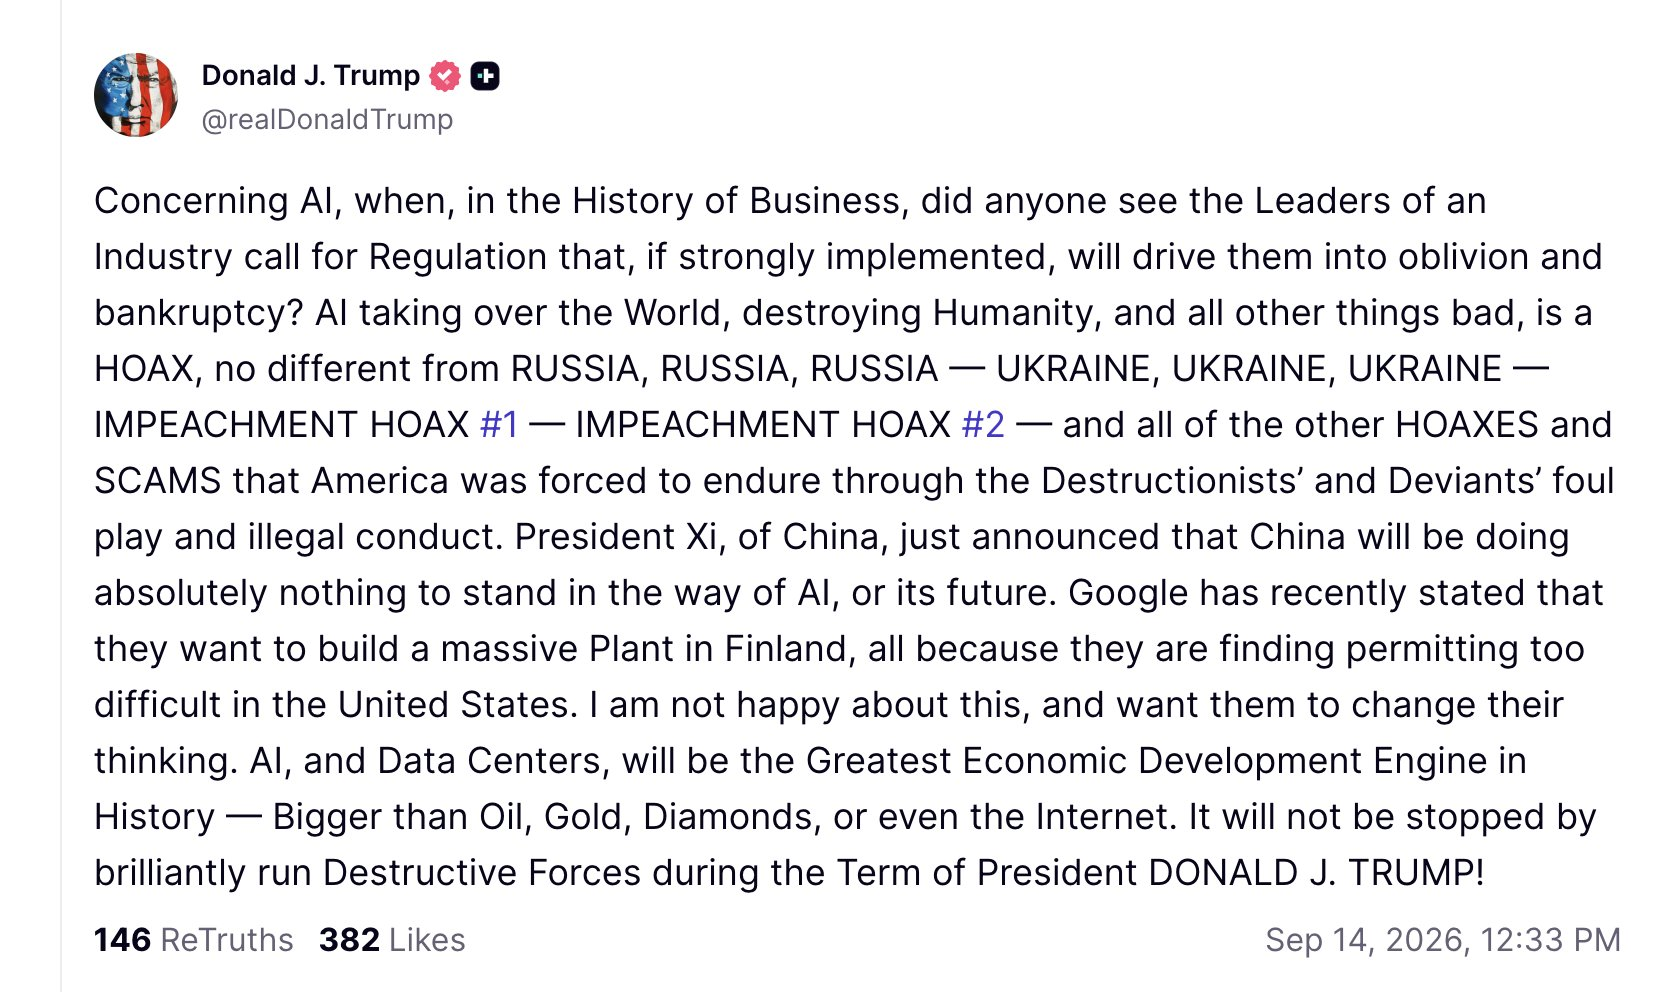
huge defeat on the side of "people" and their "things"
1
My knowledge of politics is nil, but if he listens to his supporters, and they don't care about rogue AIs, it might be a good idea to get them to consider what will happen to democracy when the military no longer needs to care about what their personnel think (because they've been replaced by robots and AIs).
0
My guess of a root cause:
* The delusion: https://pmarca.substack.com/p/why-ai-will-save-the-world
* The inventive: https://www.a16z.news/p/investing-in-cognition
* The execution: https://www.nytimes.com/2026/05/13/technology/andreessen-horowitz-politics.html
-8
This is interesting because, it is not discussed enough that AlphaGo worked the same way LLMs work: it was pretrained on a large dataset of human moves, then posttrained through reinforcement learning. The shift to AlphaZero removed the pretraining, showing that pretraining data didn't matter at all for the model's capabilities (quite the contrary, AlphaZero is superior to AlphaGo). While this coding model is still pretrained, it also shows that good pretraining data doesn't matter nearly as much as one could think.
 1