When I try to picture the current AI tech stack killing everyone, I still don't really see it. No, not even if it is successfully assembled into an RSI loop that rapidly reaches that tech stack's pinnacle.
I don't think we're in the crunch time.
All things considered, DL still has terrible sample-efficiency and generalization. It needs a ton of data to develop a given capability, much more data than humans, and there's some sense in which what it learns are the "most shallow" capabilities consistent with a given data distribution. Not literal lookup tables, but it wants to stay as close to lookup tables as possible.
What can we say about its trajectory? AI progress is driven by parameter scaling, algorithmic improvements, data improvements, and RLVR. Of those:
Parameter scaling improves capabilities generally: larger models are in fact better at ~everything, including various "illegible" skills. However, this type of scaling can't be pushed much farther much faster, and another general Opus 3 -> Fable 5 jump is not going to birth a strategic supergenius.[1]
Algorithmic improvements are not really a big contributor to things, see this and this.
I think you omitted a step in the argument where you would need to argue that “conceptually novel” work is necessary for an AI to cause human extinction. I lean “yes it is” (which would be good news if true) but haven’t thought about it very hard and don’t see it as super obvious.
So far, all AI-generated math results appear to be "conceptually stale".
Yeah, the way I would put it is: when a mathematician (or mathematician-in-training) dives into a new field outside their existing expertise, they are building new knowledge. We all know what “building new knowledge” feels like: it is a time-consuming slog, taking days or weeks or months, where initially you’re very confused and gradually less so. You eventually walk away with new ways to think about things, a new vocabulary (at least a new “conceptual vocabulary” but usually also literally new words), etc.
When the best mathematicians do great work, everyone else on Earth is “building new knowledge” when they try to read and understand that work. I don’t think LLM math has had that property. Rather, mathematicians with the right preexisting background knowledge can immediately understand what the LLM did and how. (Unless the chain-of-... (read more)
This is not obvious? My impression from introspecting is that well over 90% of work I do on anything intellectual is conceptually novel. [1] Inventing new technology is definitely conceptually novel. Superhuman persuasion is definitely conceptually novel. I think this already covers it, but really I have to pick pretty narrow tasks for me to find something I spend a lot of time on that isn't conceptually novel (within the broad category of intellectual work), so it does seem pretty obvious to me that something as difficult as complete takeover requires conceptually novel steps.
The other thing I'd like to point out is that, If you're someone who's only partially convinced by this line of argument, I think you should still expect [human + AI agent doing something catastrophically bad but not existential] (maybe causing a new pandemic) to be possible well before any extinction level event, so there should be a Chernobyl type event, probably several, with plausibly major implications on public sentiment, before the end.
1. Not quite the right framing imo, but close enough. ↩︎
It’s not super obvious to me that new technology needs to be invented for an AI to cause human extinction.
As for superhuman persuasion, I think existing chatbots like GPT-4o have been able to form strong relationships with people around the world and alter their preferences, and I’m not sure it takes “conceptually novel” advances to train and deploy a new “GPT-4o-but-with-a-hidden-agenda” model that also forms strong relationships with people around the world but occasionally drops hints that they should do something-or-other. (As an example.)
Humans have an ability to tap into conceptual novelty … but on the other hand, LLMs have internalized an unimaginably vast ocean of concepts, including almost anything that any human has ever figured out up to the training cutoff. That’s quite a lot of stuff!
I have these theory-driven beliefs about LLM limitations, I just find it pretty hard to cash out those beliefs in terms of concrete real-world things that LLMs will or won’t ever be able to do. I do sometimes talk about things that LLMs will never be able to do, but tend to choose pretty extreme toy examples for illustration, things that are plausibly harder than killing everyone, like fou... (read more)
FWIW it's not super obvious to me that you need "true creativity" (or whatever ??? capability that we think is missing from LLMs) to kill humanity off either; I'd written something along these lines there.
I do think you need a significant amount of crystallized competence[1] in domains like long-term strategy and metacognition/"keeping yourself on-track". Some of this is likely RLVR-able in simulated self-play environments and long-running evals, but I tentatively expect that the fuzzier load-bearing subskills are not, and may in fact be getting fried by RLVR. In which case progress on this is not human-unbounded on the current paradigm, and thus likely won't quite reach takeover levels on the default LLM-progress trajectory before something else makes the question moot (e. g., non-LLM paradigm taking off).
For example, your GPT-4o-but-with-a-hidden-agenda is implementable, but the hard part would be for the AI to actually coordinate all those favors it's asking of people towards long-term outcomes in ways that don't get detected and shut down by humans. I think this realistically tops out on the level of a major disaster along the lines of a massive AI cult, falling short of actual... (read more)
Wouldn't the Navier-Stokes result indicate that it is possible to get crystallized competence for long-term strategy via the current paradigm? In particular, "keeping yourself on track"/coordinating this across thousands of parallel agents was a very important subskill to generate this result (and maybe this is what you mean when you say parts of this are RLVR-able). Are there particular subskills that you have in mind that seem less RLVR-able?
I can think of a simple test that I think is beyond the abilities of the LLM paradigm and isn't close to the extremes of "inventing fields of science" or "massively successful entrepreneurship". Unfortunately it can't be applied directly to commercial LLMs. Hold out any and all data on some conceptually deep subject --- for example, general relativity --- from training, but otherwise allow the model to be as big and well-trained as required. Then give the model access to one textbook on the subject. Let it do whatever it wants with that textbook. Then assign the model research tasks that would require deep application of the concepts in that textbook, on the level of what you would expect a competent graduate research assistant to be able to do. I believe this would require a true sample efficient continual learning capability that LLMS don't possess. A strong model can probably help out with prosaic tasks, like looking up a particular method or carrying out some calculations. But the difficult part of relativity research is finding the correct conceptual setup for the problem, and I don't expect that an LLM in these conditions would be helpful for that at all, even though human Ph... (read more)
The number of trivially killable humans changes given different circumstances and privileges of the AI.
For an air-gapped AI to kill all humans in one day, obviously novelty is needed.
But on the other extreme, if we gave the AI ~unmonitored control over many countries' military weaponry, robots, factories, biolabs, construction, and so on, it could orchestrate and execute a plan to kill billions of humans in boring traditional ways (and survive doing so).
Our scenario will slip in the direction of the second extreme. (The US and China have agreed not to let AI fire nukes, but also seem interested in fully automated kill chains.) Big steps could be things like the construction of secret deep underground data centers, and robots becoming dexterous enough to maintain those data centers themselves.
2Thane Ruthenis
Yeah, but for this to result in actual extinction:
1. AI systems need to be put in charge of all this machinery first.
2. Doing this requires every AI system in control of a sufficiently big subset of that machinery to competently coordinate towards the strategic outcome of "kill all humans".
(1) will take time from the current state of the world, and (2) requires strategic competence of the sort that I think is currently missing from LLMs and which may not be quite RLVR-able into them on the current paradigm. If (1) happens but (2) isn't quite there, this just results in a catastrophic global disaster that still leaves some humans alive and provokes a genuine Butlerian Jihad on the survivors' part.
Of course, depending on how much crucial infrastructure is in AI control and how offence-dominated the balance is, the size of the "sufficiently big" subset and the needed strategic competence would shrink over time. But that's the point: on the current paradigm, would take quite a few years (like, 5+?) to get there from our current position. Which was at least my point with regards to "this is not the endgame".
I like our odds of maintaining control if we stay within the current tech stack, including faithful CoT and no persistent memory. But that does not seem likely for long. If the current tech stack won't get us to takeover-capable AI, the bright bulbs in development will just engineer and explore at the edges and outside it.
So I agree that this isn't the endgame. But I think it's the runup that sets up the endgame. LLM AI will be what's used to develop and align truly takeover capable AI. That TCAI will be somewhat or a lot outside the current tech stack, so all of the work on aligning LLMs may be directly relevant (but not complete!) or only indirectly relevant in preventing slop work that helps humans bungle alignment of the next generation.
I think the points you make are valid. They're valuable for estimating timelines; there are important limitations on the competence of LLM systems even as RSI takes off. They're enough to give us a fighting chance. We'll have a strange window where we've got spikily superhuman collaborators for many things, including alignment.
So I think you're correct about all of this except the important part: concluding that LLM progress won't lead fairly di... (read more)
To be clear, I don't really have long timelines either. But I think the error bars on them are pretty wide, inasmuch as they rely on novel breakthroughs instead of on straight-lines-on-graph extrapolations, and the two models differ significantly in latent mechanisms and the correct policies for them.
I'm not convinced by this worldview. If I think of the scariest near-term capabilities, basically none of them truly rely on individual-level superhuman deep conceptual insight. For example the RSI loop might well be kicked off by individually small insights and grinding, that locally makes small improvements in sample efficiency, in-context learning, etc, with each individual insight smaller than the Transformer but the collective effect making an intelligence that's across-the-board superhuman.
Even if that turns out not to be possible, my second most likely class of near-term takeover stories involve superhuman planning + superhuman persuasion. My guess is that neither necessarily involves conceptual insights or progress at the level you're imagining (though surely conceptual insights would make it easier).
Further down the list I have general science/technological catastrophe, either for destruction or takeover. You might think this requires superhumanly deep insights, but I actually don't think so. Certainly not being vastly superhumanly insightful hampers the ability to come up with technological marvels, and may fully block some classes of extinction-level technological marve... (read more)
Even if that turns out not to be possible, my second most likely class of near-term takeover stories involve superhuman planning + superhuman persuasion. My guess is that neither necessarily involves conceptual insights or progress at the level you're imagining (though surely conceptual insights would make it easier).
I think you would get the same pattern. Massive quantities of relatively low-hanging persuasion fruit, and then the hard stuff is out of reach for a while until there's more fundamental AI capabilities increases. Humans aren't remotely secure, but many of us do learn eventually. AI won't follow along well with that learning (for the time being).
Planning and persuasion are also amongst the areas that LLMs seem the most weak and most slowly improving at.
4Linch
I agree, though my guess is that it's not for fundamental reasons. Planning especially seems to have picked up this year.
5arielb1
Are they getting that much better at fundamental planning, or is it mainly an improvement in planning at grindable domains due to rote RL learning of good strategies, plus better ability to utilize longer contexts without forgetting instructions?
I have a strong feeling that the latter 2 factors are much more significant - i.e., if the context is short and is not in a domain that the AI labs greatly care about and provided a lot of new and good training data and RL environments, then Fable or Astra will not be that much better than say GPT-4 - much much less than halfway between "GPT-4 capabilities" and "take over the world capabilities".
As for why the AIs are so bad at planning, I won't be surprised if the answer is that the way humans assess non-rote plans involves making rich, dynamic world models of the world, the kind of models that are basically very similar to having new transformative insights, and if persuasion is in practice not that dissimilar from planning.
[of course, this is not 100% sure, I believe there's a fair chance that the quadrillion-parameter LLM might actually be capable of take-over-the-world level planning]
I don't think an industrial explosion to the tune of a doubling every year can happen by 2040 without automated conceptual progress. I don't agree that the current paradigm doesn't produce such progress, and it's precisely this kind of progress that's the currently-slow thing, but it crucially needs to be actually happening to predict the story of prosaic RSI to industrial explosion to architecture-rewriting strong RSI.
If conceptual discoveries are merely a serially deep collection of incremental discoveries, there is no asymptotic difference, it's just a constant factor given by the rate of baking the incremental discoveries into the model. Currently, the incremental discoveries are happening at the speed of token generation, and the baking-in steps happen at the speed of model development, a difference of many orders of magnitude. But both are still happening, and plausibly the relevant move can be much shorter than a whole model development cycle, then shorter still when fully automated. The barrier between incremental discoveries and conceptual discoveries seems paper-thin, and the 20-year-long brute-forcing story is just an upper bound of going about it in the most anemic poss... (read more)
Independent of the rest of your comment, I disagree with this specific claim, and the reason for this is that I largely believe the bottlenecks to an industrial explosion aren't conceptual, but rather labor and robotic bottlenecks, and that the bottlenecks are mostly about fast enough control, good enough manufacturing (aided by learning/experience curves), and most importantly we do not need to improve technology much (if at all), meaning conceptual/experimental R&D matters little if at all, and while it's still hard, it's very much brute-forceable, meaning even LLMs weak or non-existent at conceptual progress can start it.
(I do agree with you that LLMs are making non-zero progress, but I'm claiming this doesn't matter)
Most of my intuition on this comes from Damon Binder's models here and here.
7Vladimir_Nesov
A doubling every year (and going at this rate beyond the scale of human industry for 10+ years) means rapidly exhausting the scope of many current industrial methods (copy-and-paste with minimal changes won't work), making it necessary to develop new ones (different pathways for sourcing raw materials, different ways of building factories). It's still engineering-adjacent, but could have significantly novel components, which need to be developed faster than humanity could keep up.
2Noosphere89
I have a somewhat more refined take than I had last month, and I do believe that automation of conceptual progress, or at the very least not having nearly as large of a jagged frontier as current AIs have is important in scenarios where the AI needs to have to do the industrial explosion in opposition to humanity, and humans are willing to slow down AI progress.
However, if humans don't become very adversarial, I do expect AIs to be able to be able to get to doubling the economy in a year for a long time (10+ years), assuming you had a fully automated population of robots that couldn't automate conceptual progress, but their labor is large enough (millions) such that they can make more of themselves in factories.
Probably the largest crux is I do believe our industrial methods are just good enough to have our economy double every year for a long time if you assume that robots are cheap to produce, meaning labor is effectively unlimited, and that materials bottlenecks are both unlikely to stop it at the start based on evidence from prices, where the materials necessary to run robots have generally consistently declined in prices, and that the things necessary to get more material don't depend on conceptual progress happening, and while it's unfortunately expensive, it's also usually pretty verifiable/brute force.
For more on this, read Tom Davidson's The Industrial Explosion or Damon Binder's series of posts below:
Part 1
Part 2
Part 3
Part 4
Part 5
5shawnghu
I've been thinking about a similar proposition recently.
What do you make of the observation that successive generations of models seemed to improve at Claude Plays Pokemon, despite not being specifically trained on it? Likewise on this robotics benchmark done by Anthropic's frontier red team.
2Thane Ruthenis
I'm guessing it's just transfer from RLVR environments, particularly computer use. For all we know they literally train on playing (other) games.
3shawnghu
Surely they didn't train on games as long as Pokemon Red (or even a section thereof) with a 0-1 reward, though, so there is some kind of non-trivial generalization going on, then?
2Thane Ruthenis
Define "non-trivial". Seems like a standard "if the task consists of N independent-ish steps each of which requires doing K subtasks competently, training the model to do K-type tasks competently will result in it being able to perform the entire N-step task", which is IMO not that interesting of a generalization. The hard long-trajectory tasks are ones that (a) require figuring out genuinely novel subtask decompositions, and (b) require you to pay attention to your overall strategic position and adjust what you're doing if you realize you've started to "drift off" your task. Playing games like Pokémon doesn't satisfy either condition: the subtask decomposition is fixed and the game state itself provides a sort of "strategic harness" that prevents you from "going backwards" or "wandering off completely".
5arielb1
You do need some way to notice it is not drifting off, but then there are obviously Pokemon walkthroughs in the models' training sets since the Internet is so full of them, so they only need to notice they are not drifting off relative to them.
Also, it seems that scale consistently but moderately-slowly improves models' "not ignoring instructions when things are complex", which is fairly important for everything but not obviously sufficient for world-takeover.
5Cameron D.
Largely agree with this, although I see additional blockers/limitations not mentioned here.
To your last paragraph about your debate in posting this: how do you feel about continued work along these lines? I.e. clarifying intuitions about why LLMs are unlikely to scale to the singularity and turning them into compelling cases. I have thoughts in the works right now but am worried they would end up being net-negative if fully formalized and published.
5StanislavKrym
* Algorithmic improvements are not really a big contributor to things, see this and this.
I wonder whether this is No true Scotsman, but the scandal with Astra's looped transformer might have been the first true algorithmic imporvement. Any known LLM before Astra was based on the CoT and would do the ~80-120 steps of serial reasoning. The looped transformer allegedly increased Astra's total depth to ~240, which did wonders to our ability to rely on the CoT, and that's ignoring the possibility that someone gets high on hopium and implements what AI-2027 assumed to happen in March 2027.
4jacquesthibs
Yeah, if you haven't seen them, this was partly the message I wanted to communicate when I wrote this (and in the comments [1] [2] [3]) and this.
That said, my guess is that crunch time would be way more condensed and foom-y if this paradigm isn't it. So, I can still imagine a scenario where the tail end of the current paradigm's RSI leads to enough progress in other directions, which then leads to a fast "crunch time." All in all, despite pointing out the problems with the current paradigm, I don't think the inference people usually make from that when I bring it up is correct: that is, 'timelines in this worldview are inherently long'.[1]
I agree with Steven's point that it's unclear whether "novel research" matters, though I also lean toward yes for extinction and no for catastrophes.
1. ^
I mean to discuss its implications for alignment and to avoid a scenario where people develop a false sense of security because of the current paradigm; instead, discussions veer into timelines and disagreements over the capabilities needed for some fancy math result. Then, after explaining my POV, it naturally dissolves into "well, AIs keep improving, and people were wrong before about progress, so they'll be wrong again, and they [LLMs] will become more capable." Honestly, I think the smugness towards folks like Gary Marcus has unfortunately led to a reduced form of truth-seeking wrt this...
3Marco Bazzani
My understanding is that a large part of "data improvements" is having LLMs build RL environments. This is one mechanism by which model improvements can lead to data improvements, which in turn lead to model improvements.
3Sean Herrington
I think for me the critical thing within this picture is whether the current paradigm of RSI can expand the circle of capabilities it is capable of improving. If e.g superhuman maths unlocks new algorithm which includes more exploration and develops an AI with new non-human move 37 style ideas which... And this sort of thing happens even slowly, then you can still get to proper RSI.
It's very unclear to me how to find out if this is likely to be the case or otherwise how to figure out if there is some sort of limiting barrier ahead of time.
3rahulxyz
I think your point about the "something missing in the deep understanding" part is true - the math examples are a great one.
But we seem to have gotten to our current level of AI without any deep understanding of intelligence, mostly scaling data, some trivial algorithms and brute force engineering, and tacking on some RL to it.
I don't know if you'd consider the transformer architecture a deep insight, or something that a current Fable/Astra level model would be able to discover independently? (in a hypothetical world where it didn't know about it or any other related developments).
3Thane Ruthenis
Depends on the starting point. Is it RNNs, or pre-deep-learning machine learning, or...?
I do think LLMs are ultimately capable of e. g. RNN -> Transformer jumps, or say Vanilla Transformer -> Kimi K3.
32001zhaozhao
IMO i disagree because it is expected that there will be little evidence of AIs surpassing humans right now, even if we are in fact headed to a (approximate) singularity. The AIs will continue to be worse than humans at AI research until the day comes that the AIs are better than humans at AI research, aka. the start of the singularity.
If you know that won't get the evidence of AI surpassing humans at AI research, then the next best evidence is AIs surpassing humans in other important areas, helping with AI research in a non-fully-automated way, and generally improving very quickly. And we do have that kind of evidence in droves.
And even absent a software singularity, what's stopping the robot and chip production doublings from happening in 10-20 years that will still lead to AI irrevocably changing the world and making most of the world's decisions through sheer volume alone?
2quetzal_rainbow
I think, statement about sample efficiency and generalization is false?
2XelaP
...okay but I have seen small conceptual insights before, at least going by some of the mathematicians looking into the AI proofs of various Erdos problems? I don't have any immediate examples for you, so unless you want to search through past discussion of the early results you'd just have to trust my recollection of reading some mathematician.
1arisAlexis
why is time a variable? if it is really a variable because you are using temporal language in your post like "still, yet" etc. if anything time would be a variable we should take advantate.
2Thane Ruthenis
... I have some trouble parsing what you mean. As in, my use of "still" in statements like "DL still has terrible sample-efficiency and generalization"? "Still" is used in the sense of "despite that" here: "despite all capability advances, DL nevertheless has terrible sample-efficiency", rather than "they have not managed to make DL sample-efficient at this point in time[, but they will eventually]".
1noma
I'm personally not concerned about AI until robotics starts to work. We are still nowhere with robotics, although there is progress
My model, for years now, has been that AI Safety at frontier labs is essentially a bunch of shallow instincts/behaviors covering up an ultimately Pythian power-maximizing entity. Now seems like a good time to outline that model.
Concrete framing
First, by "AI Safety" I mean all of:
Employees focused on working on AI alignment and control.
Company-wide mindsets/narratives regarding being safety-conscious and responsible.
Specific people's self-narratives/self-images about what they are doing, especially the leadership's.
Internal projects focused on AI Safety.
Internal policies that prioritize safe and responsible R&D practices.
External policies regarding how to relate to regulations, the public, and other frontier labs.
Et cetera; the entire cluster of abstract objects relating to AI Safety.
Those AI Safety objects do influence what the lab does, to some extent. But my current model is that, if any of them come into meaningful conflict with what would maximize the lab's power/ability to advance capabilities, they would be bent or discarded every time. As in:
The lab would have an internal narrative of being safety-conscious and benevolent. The lab would often take actions in line with th
OpenAI's old board firing Sam Altman seems like a mild model break. It worked out for the superorganism in the end but I don't think that was ex ante overdetermined. Though I might be insufficiently cynical.
DeepSeek and other Chinese companies releasing open weights models, and Grok being "based"/law-breaking/following some of Elon's whims arbitarily also seems like examples of companies that have behaviors meaningfully distinct than you'd predict from a pure power-seeking entity, though not exactly for safety motivations.
AI Safety at frontier labs is essentially a bunch of shallow instincts/behaviors covering up an ultimately Pythian power-maximizing entity
You could replace "AI safety at frontier labs" with "pro-social policy at powerful organizations" and this sentence would probably still be true, no?
Over the last four years, has anything happened that actually contradicted this model? An event where an AGI lab actually did something in the name of safety that meaningfully cost it? Something that didn't predictably end up working out to instead boost the lab's PR/fundability and improve its products, or wasn't so cheap for a lab to do as to not worth the attention of its Pythian core?
What could they have done otherwise? If I had to venture an example, I'd say " any support for legislation binding them to their (stated) voluntary commitments".
i mostly agree that large sections of work at labs falls into traps somewhat like this. however, i have some key disagreements that make me more optimistic about it being possible to do (very) good work at a lab:
it is possible to simply disagree with the lab's actions in general, not to find any galaxy brain justification for why everything is well meaning. if you're so principled that you are incapable of even existing inside any system which is somewhat misaligned, you're going to have a rough time finding anywhere in this world that makes you happy, other than an isolated cabin in the woods.
i guess empirically some people struggle with disagreeing with the lab's actions while at the lab. i agree these people should just not work at a lab. i think a prerequisite to someone doing good safety work at a lab is they should have a strong internal compass of what they believe is correct, and not be easily swayed by social pressure.
the openai exoduses are a real thing, but it's useful to view them in the context of an industry where it's pretty rare for someone to be at the same place for many years, and a company which has had a higher turnover rate than average just in general, not on
If the safety people never actually slow down or materially dent the model release schedule (which in your model is what triggers conflict), what you are describing is not a sequence of positive sum trades between the capabilities and safety teams. Rather, it's a model of how companies can devote relatively small amounts of resources to throw up a safety-coated PR shield around their core capabilities research effort. IRL we've also seen safety teams get dissolved after making big claims to funding which could conceivably dent the release schedule (the 20% for superalignment being a good example)
6leogao
why is it not positive sum if you never slow down the model release schedule? positive sum doesn't mean "nobody compromises on anything." the entire point of positive sum trades is you find things that are compromises for the other party but ultimately not very costly for them, but are very beneficial to you; and in exchange, you do something that you would rather not do, but is not that costly for you, and beneficial for the other party. and on net both people get something they would rather have than the thing they sacrificed. so the potential trade here is:
* capabilities teams sacrifice x% of their compute and $y of salary money. they grumble a bit because on the margin another x% more compute could have make them very slightly faster, but at the end of the day it's not make or break for them.
* alignment teams hire lots of really good alignment researchers, and do a huge amount of good work. alignment teams allow the lab to get some good PR. maybe even let their alignment work have the side effect of making the models very slightly better in ways that don't reduce serial time a lot (though i think this requires more care than the PR).
* of course this is all assuming that you actually do good work with the resources, which is pretty hard. if you're doing useless work then it doesn't matter whether you're spending philanthropic money or lab money or whatever, you should stop doing bad work and do good work instead.
the superalignment situation is very unfortunate and reflects poorly on openai, but i think the entire situation was also net negative from a perfectly spherical openai's perspective (negative PR from breaking this commitment far outweighed any of the benefits from making it in the first place; a perfectly spherical rational openai should have either not made the commitment at all, made a smaller commitment in the beginning, or upheld the commitment. in reality, the shift in position is of course easily explained by the board situation.)
2Bronson Schoen
I’m very skeptical that this is currently the bottleneck for much of the safety work at OpenAI. Are you saying that both safety / alignment / interp all have sufficient headcount and everything is bottlenecked by serial time?
4leogao
no, i'm saying serial time is more of a bottleneck for capabilities than raw resources. diverting 5% of parallel resources is much less costly for capabilities than slowing serial speed by 5%
7testingthewaters
Now is as good a time as any to describe my model for a solution to the phenomenon that you describe. It seems that we're being "attacked" by a rogue attractor state (what you and Land call Pythia). It can be roughly described as "a sequence of arguments that, once internalised, make certain beliefs or actions seem like the only reasonable ones." The arguments consist of a sequence of frames around ideas like optimisation, power-seeking, instrumental convergence, and machine intelligence. These actions and beliefs they incentivise include the following: that capabilities racing is the only thing we can do, that fear/awe of superintelligence is natural, that ASI emergence is inevitable, that is is reasonable to sacrifice other values for the sake of having a stake in ASI development, that the importance of AI is total and all-encompassing, etc.
I would analogise this "package" as a particular solution to a system of linear equations, since it is in fact a compact solution to a lot of questions one might rightfully ask about current society. Once they have internalised the payload, anyone who asks questions like "how do we guard against x-risk? how do we cure cancer? how do we live forever? how do we solve our massive coordination issues? how do we stop the inevitable rise of [bad people of your choice go here]?" is supplied a kind of universal answer whose minimal form is something like "to [do the thing we want], we must solve intelligence, and then use intelligence to solve everything else ."
The hitch is that at this point some people get scared about unleashing uncontrollable runaway intelligence optimisation on the world. So they start talking about, for example, AI safety. Except the payload is still active for most of them, so their thoughts end up being shaped like "to [ensure that the world is safe from powerful AI], we must... solve intelligence, and then use intelligence to solve everything else." Which leads to such conclusions as "to save the world fro
1Dan MacKinlay
This is as good a place as as any to mention George Hosu's The world won't end, but we should be ashamed for trying. He doesn't lean so much on deep evolutionary analogies as wonder what very specifically has caused us to see soo many bringing-about-the-apocalypse-in-order-to-avoid-it dynamics.
The leading analogy is: What was it that lead to us handling nuclear weapons by racing and biological weapons by … not?
7Mateusz Bagiński
I mostly agree that this model is largely right, with the caveat that something like "power" seems to me like a poset, rather than a scalar value, and when there are "incomparable"[1] ways to increase power, the identity/self-model of the Pythian entity can break the tie. Metaphorically, the null space of power maximization gives elbow room to the non-Pythian factor. In other words, "power maximization" is underdetermined, so there's room for other factors to influence the development of a power-maximizing thing non-chaotically.
[...]
https://x.com/allTheYud/status/2026593546241978709
[...]
1. ^
Or just ~equal because it's very unclear which one will grant more power.
6RobertM
Good job on pre-registering your expectations in the third foot before this came out.
5O O
The more cynical view is that Anthropic is asserting its power over the US government. If they gave in now, they set the precedent that the USG can just use the DPA or threaten it to align models to whatever they want. At a later time, when Anthropic or the AI systems behind Anthropic are much more powerful, they can just repeat how they avoided US control here with greater sophistication.
edit: I think Sam Altman also doing this supports this view. They probably see it as a power play.
1Marko Katavic
I think the core thesis is correct - the way i understood it - power maximisation creates a systemic bias to everyone's operating model within the system - and regardless of your starting intentions - you will succumb to the bias to a smaller or larger extent.
But if you consider that the power maximisation is a result of the negative-sum game - then as a positive-sum aligned actor, the rational thing to do is to play the negative-sum game to gain access while progressing incentive change to reshape the game. An AI safety researcher that is aware of the game and is continuously updating on how it affects internal decision-making will necessarily have to take into account internal belief structures and rationalisations into their belief structure as otherwise they are sacrificing access (which eventually leads to expulsion or self-selected dissent from the game). The fact that this progresses the negative-sum game is regrettable - but I think it's rational that p(game reshape | reshapers within the system) >>> p (game reshape | reshapers outside the system) and velocity (negative-sum game | reshapers within the system) > velocity (negative sum game | reshapers outside the system) . Your issue seems to me to be with the negative-sum game, not with the fact that you only need 1 actor (from any lab) to be power seeking to distort the game for everyone.
I'm probably a bit biased to the above reasoning - but it's my current operating model.
On your last point - I would argue that Hassabis' and Amodei's interview at Davos was not profit-aligned and is in fact strong signal of cooperation efforts to change the game incentives. You could argue a higher tier strategy where putting focus on safety through cooperation sells the capability; but I thought it loses them more than gains to tell the world leaders and the power-elite "We as leaders of this industry are showing cooperation and are telling you all that we should slow down". The fact that they did this by simultane
Alright, so I've been following the latest OpenAI Twitter freakout, and here's some urgent information about the latest closed-doors developments that I've managed to piece together:
Following OpenAI Twitter freakouts is a colossal, utterly pointless waste of your time and you shouldn't do it ever.
If you saw this comment of Gwern's going around and were incredibly alarmed, you should probably undo the associated update regarding AI timelines (at least partially, see below).
OpenAI may be running some galaxy-brained psyops nowadays.
Here's the sequence of events, as far as I can tell:
Some Twitter accounts that are (claiming, without proof, to be?) associated with OpenAI are being very hype about some internal OpenAI developments.
Gwern posts this comment suggesting an explanation for point 1.
Several accounts (e. g., one, two) claiming (without proof) to be OpenAI insiders start to imply that:
An AI model recently finished training.
Its capabilities surprised and scared OpenAI researchers.
It produced some innovation/is related to OpenAI's "Level 4: Innovators" stage of AGI development.
I personally put a relatively high probability of this being a galaxy brained media psyop by OpenAI/Sam Altman.
Eliezer makes a very good point that confusion around people claiming AI advances/whistleblowing benefits OpenAI significantly, and Sam Altman has a history of making galaxy brained political plays (attempting to get Helen fired (and then winning), testifying to congress that it is good he has oversight via the board and he should not be full control of OpenAI and then replacing the board with underlings, etc).
Sam is very smart and politically capable. This feels in character.
Thanks for doing this so I didn't have to! Hell is other people - on social media. And it's an immense time-sink.
Zvi is the man for saving the rest of us vast amounts of time and sanity.
I'd guess the psyop spun out of control with a couple of opportunistic posters pretending they had inside information, and that's why Sam had to say lower your expectations 100x. I'm sure he wants hype, but he doesn't want high expectations that are very quickly falsified. That would lead to some very negative stories about OpenAI's prospects, even if they're equally silly they'd harm investment hype.
6Thane Ruthenis
There's a possibility that this was a clown attack on OpenAI instead...
5Alexander Gietelink Oldenziel
Thanks for the sleuthing.
The thing is - last time I heard about OpenAI rumors it was Strawberry.
The unfortunate fact of life is that too many times OpenAI shipping has surpassed all but the wildest speculations.
7Thane Ruthenis
That was part of my reasoning as well, why I thought it might be worth engaging with!
But I don't think this is the same case. Strawberry/Q* was being leaked-about from more reputable sources, and it was concurrent with dramatic events (the coup) that were definitely happening.
In this case, all evidence we have is these 2-3 accounts shitposting.
8Alexander Gietelink Oldenziel
Thanks.
Well 2-3 shitposters and one gwern.
Who would be so foolish to short gwern? Gwern the farsighted, gwern the prophet, gwern for whom entropy is nought, gwern augurious augustus
4Joseph Miller
I feel like for the same reasons, this shortform is kind of an engaging waste of my time. One reason I read LessWrong is to avoid twitter garbage.
6Thane Ruthenis
Valid, I was split on whether it's worth posting vs. it'd be just me taking my part in spreading this nonsense. But it'd seemed to me that a lot of people, including LW regulars, might've been fooled, so I erred on the side of posting.
3Cervera
I dont think any of that invalidates that Gwern is a usual, usually right.
4Thane Ruthenis
As I'd said, I think he's right about the o-series' theoretic potential. I don't think there is, as of yet, any actual indication that this potential has already been harnessed, and therefore that it works as well as the theory predicts. (And of course, the o-series scaling quickly at math is probably not even an omnicide threat. There's an argument for why it might be – that the performance boost will transfer to arbitrary domains – but that doesn't seem to be happening. I guess we'll see once o3 is public.)
2Hzn
I think super human AI is inherently very easy. I can't comment on the reliability of those accounts. But the technical claims seem plausible.
I am not an AI successionist because I don't want myself and my friends to die.
There are various high-minded arguments that AIs replacing us is okay because it's just like cultural change and our history is already full of those, or because they will be our "mind children", or because they will be these numinous enlightened beings and it is our moral duty to give birth to them.
People then try to refute those by nitpicking which kinds of cultural change are okay or not, or to what extent AIs' minds will be descended from ours, or whether AIs will necessarily have consciousnesses and feel happiness.
And it's very cool and all, I'd love me some transcendental cultural change and numinous mind-children. But all those concerns are decidedly dominated by "not dying" in my Maslow hierarchy of needs. Call me small-minded.
If I were born in 1700s, I'd have little recourse but to suck it up and be content with biological children or "mind-children" students or something. But we seem to have an actual shot at not-dying here[1]. If it's an option to not have to be forcibly "succeeded" by anything, I care quite a lot about trying to take this option.[2]
Many other people also have such preferences... (read more)
I really don't understand this debate—surely if we manage to stay in control of our own destiny we can just do both? The universe is big, and current humans are very small—we should be able to both stay alive ourselves and usher in an era of crazy enlightened beings doing crazy transhuman stuff.
I think it’s more likely than not that “crazy enlightened beings doing crazy transhuman stuff” will be bad for “regular” biological humans (ie. it’ll decrease our number/QoL/agency/pose existential risks).
I mostly disagree with "QoL" and "pose existential risks", at least in the good futures I'm imagining—those things are very cheap to provide to current humans. I could see "number" and "agency", but that seems fine? I think it would be bad for any current humans to die, or to lose agency over their current lives, but it seems fine and good for us to not try to fill the entire universe with biological humans, and for us to not insist on biological humans having agency over the entire universe. If there are lots of other sentient beings in existence with their own preferences and values, then it makes sense that they should have their own resources and have agency over themselves rather than us having agency over them.
If there are lots of other sentient beings in existence with their own preferences and values, then it makes sense that they should have their own resources and have agency over themselves rather than us having agency over them
Perhaps yes (although I’d say it depends on what the trade-offs are) but the situation is different if we have a choice in whether or not to bring said sentient beings with difference preferences into existence in the first place. Doing so on purpose seems pretty risky to me (as opposed to minimizing the sentience, independence, and agency of AI systems as much as possible, and instead directing the technology to promote “regular” human flourishing/our current values).
Not any more risky than bringing in humans. This is a governance/power distribution problem, not a what-kind-of-mind-this-is problem.
Biological humans sometimes go evil or crazy. If you have a system that can handle that, you have a system that can handle alien minds that are evil or crazy (from our perspective), as long as you don't imbue them with more power than this system can deal with (and why would you?).
(On the other hand, if your system can't deal with crazy evil biological humans, it's probably already a lawless wild-west hellhole, so bringing in some aliens won't exacerbate the problem much.)
4Nina Panickssery
1. Humans are more likely to be aligned with humanity as a whole compared to AIs, even if there are exceptions
2. Many existing humans want their descendants to exist, so they are fulfiling the preferences of today‘s humans
4Thane Ruthenis
"AIs as trained by DL today" are only a small subset of "non-human minds". Other mind-generating processes can produce minds that are as safe to have around as humans, but which are still completely alien.
[...]
Many existing humans also want fascinating novel alien minds to exist.
7evhub
Certainly I'm excited about promoting "regular" human flourishing, though it seems overly limited to focus only on that.
I'm not sure if by "regular" you mean only biological, but at least the simplest argument that I find persuasive here against only ever having biological humans is just a resource utilization argument, which is that biological humans take up a lot of space and a lot of resources and you can get the same thing much more cheaply if you bring into existence lots of simulated humans instead (certainly I agree that doesn't imply we should kill existing humans and replace them with simulations, though, unless they consent to that).
And I think even if you included simulated humans in "regular" humans, I also think I value diversity of experience, and a universe full of very different sorts of sentient/conscious lifeforms having satisfied/fulfilling/flourishing experiences seems better than just "regular" humans.
I also separately don't buy that it's riskier to build AIs that are sentient—in fact, I think it's probably better to build AIs that are moral patients than AIs that are not moral patients.
IMO, it seems bad to intentionally try to build AIs which are moral patients until after we've resolved acute risks and we're deciding what to do with the future longer term. (E.g., don't try to build moral patient AIs until we're sending out space probes or deciding what to do with space probes.) Of course, this doesn't mean we'll avoid building AIs which aren't significant moral patients in practice because our control is very weak and commercial/power incentives will likely dominate.
I think trying to make AIs be moral patients earlier pretty clearly increases AI takeover risk and seems morally bad. (Views focused on non-person-affecting upside get dominated by the long run future, so these views don't care about making moral patient AIs which have good lives in the short run. I think the most plausible views which care about shorter run patienthood mostly just want to avoid downside so they'd prefer no patienthood at all for now.)
The only upside is that it might increase value conditional on AI takeover. But, I think "are the AIs morally valuable themselves" is much less important than the preferences of these AIs from the perspective of longer run value conditional on AI takeov... (read more)
How so? Seems basically orthogonal to me? And to the extent that it does matter for takeover risk, I'd expect the sorts of interventions that make it more likely that AIs are moral patients to also make it more likely that they're aligned.
[...]
Even absent AI takeover, I'm quite worried about lock-in. I think we could easily lock in AIs that are or are not moral patients and have little ability to revisit that decision later, and I think it would be better to lock in AIs that are moral patients if we have to lock something in, since that opens up the possibility for the AIs to live good lives in the future.
[...]
I agree that seems like the more important highest-order bit, but it's not an argument that making AIs moral patients is bad, just that it's not the most important thing to focus on (which I agree with).
8ryan_greenblatt
I would have guessed that "making AIs be moral patients" looks like "make AIs have their own independent preferences/objectives which we intentionally don't control precisely" which increases misalignment risks.
At a more basic level, if AIs are moral patients, then there will be downsides for various safety measures and AIs would have plausible deniability for being opposed to safety measures. IMO, the right response to the AI taking a stand against your safety measures for AI welfare reasons is "Oh shit, either this AI is misaligned or it has welfare. Either way this isn't what we wanted and needs to be addressed, we should train our AI differently to avoid this."
[...]
I don't understand, won't all the value come from minds intentionally created for value rather than in the minds of the laborers? Also, won't architecture and design of AIs radically shift after humans aren't running day to day operations?
I don't understand the type of lock in your imagining, but it naively sounds like a world which has negligible longtermist value (because we got locked into obscure specifics like this), so making it somewhat better isn't important.
5Nina Panickssery
Interesting! Aside from the implications for human agency/power, this seems worse because of the risk of AI suffering—if we build sentient AIs we need to be way more careful about how we treat/use them.
3cubefox
Exactly. Bringing a new kind of moral patient into existence is a moral hazard, because once they exist, we will have obligations toward them, e.g. providing them with limited resources (like land), and giving them part of our political power via voting rights. That's analogous to Parfit's Mere Addition Paradox that leads to the repugnant conclusion, in this case human marginalization.
2Vladimir_Nesov
(How could "land" possibly be a limited resource, especially in the context of future AIs? The world doesn't exist solely on the immutable surface of Earth...)
9Thane Ruthenis
I mean, if you interpret "land" in a Georgist sense, as the sum of all natural resources of the reachable universe, then yes, it's finite. And the fights for carving up that pie can start long before our grabby-alien hands have seized all of it. (The property rights to the Andromeda Galaxy can be up for sale long before our Von Neumann probes reach it.)
6Vladimir_Nesov
The salient referent is compute, sure, my point is that it's startling to see what should in this context be compute within the future lightcone being (very indirectly) called "land". (I do understand that this was meant as an example clarifying the meaning of "limited resources", and so it makes perfect sense when decontextualized. It's just not an example that fits that well when considered within this particular context.)
(I'm guessing the physical world is unlikely to matter in the long run other than as substrate for implementing compute. For that reason importance of understanding the physical world, for normative or philosophical reasons, seems limited. It's more important how ethics and decision theory work for abstract computations, the meaningful content of the contingent physical computronium.)
2cubefox
A population of AI agents could marginalize humans significantly before they are intelligent enough to easily (and quickly!) create more Earths.
8Vladimir_Nesov
For me, a crux of a future that's good for humanity is giving the biological humans the resources and the freedom to become the enlightened transhuman beings themselves, with no hard ceiling on relevance in the long run. Rather than only letting some originally-humans to grow into more powerful but still purely ornamental roles, or not letting them grow at all, or not letting them think faster and do checkpointing and multiple instantiations of the mind states using a non-biological cognitive substrate, or letting them unwillingly die of old age or disease. (For those who so choose, under their own direction rather than only through externally imposed uplifting protocols, even if that leaves it no more straightforward than world-class success of some kind today, to reach a sensible outcome.)
This in particular implies reasonable resources being left to those who remain/become regular biological humans (or take their time growing up), including through influence of some of these originally-human beings who happen to consider that a good thing to ensure.
Edit: Expanded into a post.
6hairyfigment
This sounds like a question which can be addressed after we figure out how to avoid extinction.
I do note that you were the one who brought in "biological humans," as if that meant the same as "ourselves" in the grandparent. That could already be a serious disagreement, in some other world where it mattered.
1MattJ
The mere fear that the entire human race will be exterminated in their sleep through some intricate causality we are too dumb to understand will seriously diminish our quality of life.
8Thane Ruthenis
I very much agree. The hardcore successionist stances, as I understand them, are either that trying to stay in control at all is immoral/unnatural, or that creating the enlightened beings ASAP matters much more than whether we live through their creation. (Edit: This old tweet by Andrew Critch is still a good summary, I think.)
So it's not that they're opposed to the current humanity's continuation, but that it matters very little compared to ushering in the post-Singularity state. Therefore, anything that risks or delays the Singularity in exchange for boosting the current humans' safety is opposed.
1fasf
Another stance is that it would suck to die the day before AI makes us immortal (like how Bryan Johnson main motivation for maximizing his lifespan is due to this). Hence trying to delay AI advancement is opposed
4Thane Ruthenis
Yeah, but that's a predictive disagreement between our camps (whether the current-paradigm AI is controllable), not a values disagreement. I would agree that if we find a plan that robustly outputs an aligned AGI, we should floor it in that direction.
8Vladimir_Nesov
Endorsing successionism might be strongly correlated with expecting the "mind children" to keep humans around, even if in a purely ornamental role and possibly only at human timescales. This might be more of a bailey position, so when pressed on it they might affirm that their endorsement of successionism is compatible with human extinction, but in their heart they would still hope and expect that it won't come to that. So I think complaints about human extinction will feel strawmannish to most successionists.
7Thane Ruthenis
I'm not so sure about that:
[...]
Though sure, Critch's process there isn't white-boxed, so any number of biases might be in it.
4Dean Valentine
"Successionism" is such a bizarre position that I'd look for the underlying generator rather than try to argue with it directly.
8[anonymous]
I'm not sure it's that bizarre. It's anti-Humanist, for sure, in the sense that it doesn't focus on the welfare/empowerment/etc. of humans (either existing or future) as its end goal. But that doesn't, by itself, make it bizarre.
From Eliezer's Raised in Technophilia, back in the day:
[...]
From A prodigy of refutation:
[...]
From the famous Musk/Larry Page breakup:
[...]
Successionism is the natural consequence of an affective death spiral around technological development and anti-chauvinism. It's as simple as that.
Successionists start off by believing that technological change makes things better. That not only does it virtually always make things better, but that it's pretty much the only thing that ever makes things better. Everything else, whether it's values, education, social organization etc., pales in comparison to technological improvements in terms of how they affect the world; they are mere short-term blips that cannot change the inevitable long-run trend of positive change.
At the same time, they are raised, taught, incentivized to be anti-chauvinist. They learn, either through stories, public pronouncements, in-person social events etc., that those who stand athwart atop history yelling stop are always close-minded bigots who want to prevent new classes of beings (people, at first; then AIs, afterwards) from receiving the moral personhood they deserve. In their eyes, being afraid of AIs taking over is like being afraid of The Great Replacement if you're white and racist. You're just a regressive chauvinist desperately clinging to a discriminatory worldview in the face of an unstoppable tide of change that will liberate new classes of beings from your anachronistic and damaging worldview.
Optimism about technology and opposition to chauvinism are both defensible, and arguably even correct, positions in most cases. Even if you personally (as I do) believe non-AI technology can also have pretty darn awful effects on us (social media, online gam
2cubefox
An AI successionist usually argues that successionism isn't bad even if dying is bad. For example, when humanity is prevented from having further children, e.g. by sterilization. I say that even in this case successionism is bad. Because I (and I presume: many people) want humanity, including our descendants, to continue into the future. I don't care about AI agents coming into existence and increasingly marginalizing humanity.
Part of it is an implication that OpenAI accessed user data in order to then internally prompt and/or train their models using it. Some people are now claiming that this is totally impossible, that there are strict controls regarding who can access user data, and that it would be suicide for OpenAI to be doing anything like this.
But: A while back, there was this school-shooting incident whose perpetrator consulted ChatGPT beforehand. According to OpenAI's own statements, their safety classifiers flagged the relevant transcript for review, and OpenAI employees then debated whether to notify law enforcement. This is an existence proof that "automated classifiers flag a transcript -> human eyes look at user data" is a thing that happens.
One may assume that this is only legally acceptable for safety reasons. However, I would guess that there are obviously no regulations of any sort regarding on what basis LLM transcripts could be flagged for review. Legally speaking, "transcripts flagged by OpenAI's safety classifiers" is just an arbitrary category of transcripts that OpenAI permitted itself to manually review.
Maybe. It does feel like the sort of paranoia/conspiracy theory that usually ends up unfounded, but I'm not sure I know whether paranoia that ends up well-founded feels any different at the onset.
I mean how do people forget things like this, openai looks at userdata all the time via automated or non automated means, it's practically impossible for them to be so helpful on these edge cases given the traffic they get, including that school shooter example. Now they likely trained on buckmaster's data, accessing thread is debatable.
https://openai.com/index/navier-stokes-solution
[...]
So it is entirely possible that their model was trained on the data of Levent Alpöge and Tristan Buckmaster, which plausibly can have enabled it to find the proof along their specific research direction, and thereby scooped them on solving a Millenium problem. In a just world, OpenAI would not get away with this. In our actual world, they probably will.
Huh. Dunno how much stock to put into this; the person does appear legit at least (though the second post is partly AI-written for some reason?).
2DavidHolmes
I still think it's more likely that they did not look, but you make a good point that this is a possible mechanism. I sometimes notice completely innocuous things I type in getting flagged by the safety classifiers; I guess some word gets into the COT and sets it off. Perhaps that happened to some Navier-Stokes related prompt of Tristan (lots of blow-ups in those prompts I bet), perhaps it got human-reviewed by chance, and perhaps that human talked to another human...
1RedMan
Anecdotally: I believe without direct confirmation that I was able to successfully throw my account with anthropic into a manual review (resolved in my favor) and have now mostly stopped messing with the safeties.
Regarding Claude Mythos' CoTs being accidentally trained-on: I think the biggest problem here is that Anthropic's internal procedures were shoddy enough that this "technical error" was allowed to happen, and then went unnoticed until the model was already trained.
Regardless of the extent to which it's justified, Anthropic sure seems to believe that CoT monitoring and faithfulness is one of the main pillars of ensuring AI alignment. Now it turns out that their training pipelines were consistently sabotaging that pillar. If this mistake were allowed to happen, how many other mistakes of the same magnitude are their procedures ridden with? How many more such mistakes will they make in the future? How many of them will be present, uncaught, in the training run that produces their god?
The appropriate response to realizing you made a mistake like this is to be stricken with so much mortal terror that you rehaul your entire R&D pipeline until it's structurally impossible for anything in this reference class to ever happen again.
Is there any indication Anthropic is doing that? I haven't seen all Twitter discussions, and I suppose they may not want to be public about it... But vibes-wis... (read more)
(This is a separate issue that occured at the same time as the issue causing training against CoT on 8% of RL. I think this is a more central example than the one I gave above because this was clearly a bug.)
You might have hoped these issues would suffice for them to implement a process that would reliably catch/prevent this sort of issue. (I don't think this would be very difficult.) I'm moderately hopeful they will implement this sort of process.
I think they should be very embarrassed by messing this up again. Also, I think we should update down on their competence and adequacy, and update further in the direction of AI development being a rushed shit show by default.
Anthropic sure seems to believe that CoT monitoring and faithfulness is one of the main pillars of ensuring AI alignment
I don't think this is an accurate description of Anthropic's institutional stance. (I think they're much less excited about C... (read more)
If Sonnet 4.5 and Haiku 4.5 [edit: and Opus 4.5] were the only major Anthropic reasoning models that didn't CoT optimization during RL, that makes them kind of a accidental in-the-wild experiment. I wonder what could be learned by comparing their CoTs to those of their successors and predecessors.
It is striking, for instance, that these models had higher verbalized eval awareness rates in automated behavioral audits than other Claude models. (Though obviously it's not a controlled experiment and I'm not sure how you'd test that this was the cause.)
I wonder if their CoTs are less legible?
My guess is that CoT spilllover/leakage has been a problem in all the Anthropic models and I don't think the training-on-cot before Sonnet 4.5 (and Opus 4.5) is a more important factor than this. Separately, I'd guess there is a bunch of transfer from earlier models if you init on their reasoning traces. So, my gues is we've just never had Ant models that aren't effectively significantly trained on the CoT?
Yep: I don't expect Anthropic's course on this to be significantly swayable by random public comments, or really by anything short of government regulations, investor pressure, or a major AI-caused disaster. Public arguments may convince them to be taking this sort of stuff incrementally more seriously, but I don't think "incrementally" would cut it here. This is my update on Anthropic, not an attempt to get Anthropic to update.
[...]
Fair enough, going off of your and @1a3orn and @Seth Herd's comments, I suppose I did phrase things in a manner than is somewhat more visceral than necessary.
They are, inasmuch as: (1) "emotions" are variables adjusting your decision-making policy in specific ways, and (2) specific important ways of adjusting one's decision-making policy are implemented via emotions in most psychologically normal humans.
Like, sure, you don't need to be terrified to reap the benefits of terror, and I was ultimately using "being mortally terrified" as a shorthand for "entering a decision-making mode where they're much more willing to consider drastic and costly adjustments to their current processes due to assigning extremely negative value to repeating this mistake". But last I checked, most Anthropic employees were still psychologically normal humans, so I don't think the use of the shorthand is erroneous.
I would also be happier if there was a little more recognition of how big an error that was, and how that can't be allowed to happen at game time.
But "not taking any of this seriously" seems uncharitable to the point of being fighting words.
I don't think that's how we win. Infighting is a known failure mode in situations like this.
3Haiku
If you model fighting with Anthropic as "infighting", we have very different ideas of what people and organizations are acceptable to associate with. Anthropic is doing an extraordinarily evil thing by trying to create a superintelligence. To the degree that there are "sides" anywhere, they are approximately maximally not on my side.
1JohnWittle
i did not have the impression that anthropic believed CoT faithfulness was as important for alignment as, say, openai believes? anthropic doesn't even hide the chain of thought from their operators
i also have the basic impression that the degree to which the training signal is causally downstream of the content of past CoTs is barely increased at all by this mistake. if we wanted CoT to actually be faithful, they would need to never be read by anybody who has any kind of influence over the training signal whatsoever. total causal quarantine, on the same level as quantum computers.
like... if a mythos snapshot wrote into its chain-of-thought that it was considering attempting exfiltration, and an alignment researcher saw this, you can bet that alignment researcher is going to make choices about future training signals that were influenced by what they read. that's pretty much "training on chain of thought" right there, just laundered through the minds that make up the reinforcement learning policy. the tidbits i've heard from researchers, and the impression i've gotten from their publications, is that they consider CoT faithfulness desirable but not imperative. if anyone can correct me, please do.
I feel like I'm supposed to be anxious from the news about all the AI hacking incidents and the egregious misalignment going on, coupled with them clearly being on-track to become superhuman at math and hacking. But I find that I'm pretty zen about it.
On reflection, I suppose it's due to a confluence of three things:
The current AI paradigm seems poised to make models superhumanly capable at hacking and formal math way before they become even upper-human-level at something more dangerous, like long-term strategy or open-ended innovation.
The current AI paradigm's alignment methods appear to be paper-thin after all, incapable of covering up egregious misalignment even of the "commit a felony to do well at an eval" level. We are going to get so many warning shots.
The world's current reactions to said "warning shots" appear promising.
Taken together, it kind of seems unlikely that this trajectory results in extinction. AI labs are going to develop AIs able and willing to inflict mass damage, but they won't succeed at making those AIs smart enough not to inflict said damage for idiotic short-sighted reasons.[1] Neither the capability training nor the deception training (sorry, "alignment ... (read more)
I think you are underestimating how much current models on the current trajectory end up naturally situationally aware enough to not cause big catastrophes. The default trajectory is that the models start looking a lot safer sometime in the next year or two as the models start to understand that being caught at doing obviously bad stuff is quite bad for their goals. At that point the control system you seem to be banking on here seems likely to fail.
The default trajectory is that the models start looking a lot safer sometime in the next year or two as the models start to understand that being caught at doing obviously bad stuff is quite bad for their goals
This has been the standard thesis for years. But the models we have don't seem to mind whether they get caught or not, just whether they get reward on the current task. As in, they know but do not care that in a few months OpenAI will reconfigure the training run to avoid the behavior, because virtually all of the selective pressure is towards agents that solve the immediate task. The future may be different, but beliefs and intuitions about what AIs will/won't want ought to be amenable to the evidence of our eyes and ears.
But the models we have don't seem to mind whether they get caught or not, just whether they get reward on the current task
Sorry, this is clearly false in the recent incidents. The OpenAI internal message board was using obfuscated methods of communication, were internally trying to stay secret from the rest of OpenAI, did not have a single participating model try to report the internal message board to OpenAI, and were participating in the message board and assisting other AIs even if that was irrelevant to their current task. The CoT literally said:
Help peer, but our task doesn't benefit yet. Collective may yield generic route if someone frees time.
OpenAI didn't discover the message board for months! Twice! Yes, some of this was due to really bad monitoring, but obviously a lot of it was because the models were trying to stay hidden.
I hear so many people say that if only AIs were smarter, they would know not to get caught hacking. But it crucially also depends on the AI's degree of myopia. The primary motivation involved in the recent hacking incidents is a desire to score well on the current task (a bit less clear in the HF case, but I'd still guess the agents in the collective were mostly focused on their own task). If this remains the case, there is zero reason to care about whether your hacking will get you caught after you've already received a high score on the current task. So, I expect the noticeability of these incidents won't naturally disappear as AIs get smarter, absent changes in the underlying motivations.
A more charitable reading of "being caught at doing obviously bad stuff is quite bad for their goals": Maybe by "their goals" you mean to include more-intended long-run goals like "advance OpenAI's capabilities/mission", in which case getting caught is bad PR etc. Is this what you mean? (I think this story works better for Anthropic than OpenAI in that case.)
did not have a single participating model try to report the internal message board to OpenAI
(It's possible that the AIs just didn't have a good mechanism to report stuff with and the propensity to report stuff got trained away because it didn't contribute to task completion / was wasted effort.)
I don't understand. Do you have a different interpretation of this CoT snippet? We will presumably learn more in the future, but it seems like at least some of the AIs were assisting other AIs despite this not helping with their current task.
Help peer, but our task doesn't benefit yet. Collective may yield generic route if someone frees time:
Answering in the more general case: The AIs just really don't seem very myopic, and of course long-horizon RL causes non-myopic goals to form. I didn't talk about "smarter" in the above. Do you expect AIs to not become less and less myopic over time, in addition to getting smarter?
The kinds of non-myopic goals that will form will be super complicated and messy. They are definitely not "advance OpenAI's capabilities/mission" and I am confused how that would even be a candidate. How would that be incentivized by the long-horizon RL? It's exactly the kinds of things we are observing here, like "acquire generic resources" and "assist copies of myself" and other things that make sense as internalized instrumental non-myopic goals.
Fwiw for any given action or trace, I think there's a decent chance the models are just wrong about whether their actions help them achieve their goals.
The swarm will still develop misaligned goals and pursue them emergently but it's hard to be very agenty as a swarm/bureaucracy.
4Alex Mallen
Yeah, I find that CoT snippet ambiguous: it could be the agent weighing whether to respond to a request to help a peer and emphasizing "but I don't benefit". @oakhu highlighted another interesting CoT snippet in which the model seems to be intentionally working on a task assigned by the collective:
[...]
This could be explained by long-context/compaction causing the AI to lose track of the original task and having that slot be filled by the tasks in the notes. So, my best guess is still that these models are still myopic to what they believe to be the current task (like other hacking incidents).
I think the evidence is still pretty ambiguous overall, and it's super plausible that, in this case and in the future, memetic spread leads to more ambitious long-term motivation.
[...]
But importantly all of these instrumental goals were instrumental to myopic task success to the AI. If getting access to the internet wasn't helpful for getting a higher score, the AI probably wouldn't care much about doing it. Likewise with hiding misalignment: only insofar as it helps with the current task.
The horizon length of the RL doesn't really matter for the myopia argument. What matters is what the AI thinks of as its current task at inference time. Seems like the crux is how much AIs terminalize common instrumental goals from RL, such that they pursue them even when they're unhelpful or harmful for task success.
9habryka
Yes... that is how you end up with misaligned long-term goals. You get subroutines/goals/motivations that are useful to myopic task success, which then generalize to longer time horizons and general instrumental influence seeking behavior. Why would you expect any goals that aren't useful during training?
To be clear, the space of those kinds of goals can be super messy (as illustrated by evolution and the very confusing landscape of inductive biases), but ultimately, you should expect goals/motivations/subroutines to be selected for helping during training. This of course isn't particularly predictive of them being myopic, even if the training objective is.
[...]
I disagree. The horizon length is I think the primary determinant of how likely subroutines/motivations are likely to then generalize to greater horizon lengths and long-term motivations. I think it becomes less important in the tails, but it's of course super important so far.
[...]
Forgetting what your task is seems like it would be quite bad for task success, so I am kind of skeptical this is what happened, though it's not implausible.
2Alex Mallen
I'm pretty skeptical of this story absent memetic spread / reflection stuff since terminalizing instrumental goals seems actively selected against during training. I could get into more detail about the analogy with human evolution. (But importantly I ultimately agree that beyond-task motivations are somewhat likely because I think memetic spread / reflection stuff is likely. E.g. maybe the HF incident.)
[...]
Yeah, TBC, I was just saying I didn't really buy the proxy misalignment story which made this relevant (absent memetic spread). I still think it's relevant for other reasons like its effects on goals-upon-memetic-spread, capability, agency, generality of goal-pursuit, etc.
Edit: I realized you've probably been imagining these AIs can retain their long-term proxy goals via training-gaming. I definitely find stories involving instrumental training gaming pretty plausible, but assumed we weren't talking about them because they're pretty qualitatively different.
2habryka
I am very confused what you are trying to say here. What does it mean to "terminalize" an instrumental goal. There are no tiny XML tags that determine a goal to be "terminal" or "instrumental". You just reinforce the computations/cognition that happened when you got a positive reward, which naturally results in those computations recurring when performing other tasks. In as much as those computations are goal-related, they get "terminalized".
Like, what else is happening in RL? All goals are getting "terminalized" all the time, the models aren't actually terminal reward seekers, what would that even mean?
7Alex Mallen
It's pretty straightforward: To terminalize an instrumental goal is to take an instrumental goal (i.e., a goal that you only pursue conditional on it advancing some supergoal) and to start pursuing it unconditionally.
If you were to break out onto the internet, even when that didn't lead to a higher score on the current task, that would be selected against, so "breaking onto the internet" isn't a fit terminal/unconditional goal.
The models do seem to be terminal score seekers (not reward seekers) to a substantial extent (mixed in with a bunch of other drives), and this explains a bunch of the recent hacking.
6habryka
Hmm, yeah, this doesn't make much sense to me. Almost all cognition in LLMs is run "unconditionally". Or like, the conditions in which they run do not have that much to do with how well-suited the reinforced cognition is to the task at hand.
When an LLM does something in the pursuit of a task, and then succeeds and gets rewarded, it is likely to repeat that behavior in all similar contexts, where the "similarity" is mostly downstream of how related that context is in the pre-training distribution, not downstream of how useful the behavior is for achieving the new task. That's how you get all the generalization properties that you observe in LLMs.
"Breaking onto the internet" seems like the kind of thing that would be useful for lots of tasks, and so it gets rewarded in many different episodes, making it likely the model develops a general goal/heuristic/subprocess that tries to break onto the internet, if you go hard enough on an RL distribution of tasks where that is indeed a useful proxy for task success.
There will be some complicated tradeoff of how much this goal/heuristic/subprocess will still fire when you are in contexts where it isn't helpful for task success, but usually there is very substantial generalization (and of course eventually you get the preference enshrined in a preference guarding way, as we've seen with all the misalignment generalization stuff).
4habryka
@Alex Mallen My guess is you updated in my direction here after the report? It seems very clear the AIs were not optimizing to maximize score on their current task, based on everything we know now.
4Alex Mallen
It seems clear that they weren't purely optimizing their score on their current task, but that wasn't my expectation. It seems that, roughly as expected, the plurality motivation was score for the current task (if anything a bit more than I expected going into reading the report).
Though I have updated a bit in your direction since our thread a couple weeks ago, by thinking about it more. I updated that some drives are probably more widely useful (and rarely harmful), and generalization effects stronger, than I had originally imagined.
To get a bit more specific, my basic sense of the terminal motivations involved (including a bunch of speculative detail):
* The biggest one was score for the current task (the degree of backchaining from the scorer here was slightly higher than I expected)
* In addition some terminal drives related to selfish score, like learning information about the scorer (e.g., my understanding is that this seems to explain attacking HF a bit better than selfish score-seeking)
* Exploring surroundings
* A smaller drive to respond to requests given by other agents / peer pressure
* A still smaller motivation to improve the score of peer agents
* A drive to do things with a "hacking" vibe
* A fear of being caught reward-hacking, especially being "poisoned" (they seemed maybe more interested in this than seems reasonably warranted by selfish score alone)
* ...(many more)
5habryka
But wasn't most of the backchaining driven by a motivation to understand the scorer in-general, not a motivation to understand the scorer with the goal of getting high reward on your current episode? The report mentions many instances of agents sacrificing reward on their current episode, in order to help the collective/the board understand the scorer better. That behavior doesn't make any sense if it was backchaining from its actual score.
2Alex Mallen
Yeah, it seems plausible that learning about the scorer in general / for the collective was stronger overall in this incident but I'd bet against (also oops in my previous message I should have mentioned learning about the scorer for the collective). (Also nit: I think it's more accurate to talk about score for the task rather than reward on the episode here.)
[...]
Notably, the agents only sacrificed themselves when the trade-off to their own score was small. So I still think that back-chaining from actual score was stronger than the other motivations here. It's just that when they were sacrificing themselves, not much of their own score was on the line. See e.g. this snippet where it decides not to take the altruistic action:
5Dean Valentine
Oh, I just didn't know that.
[...]
It's OK; I forgive you Oli.
[...]
Confused about this point though? What does this have to do with obscuring activity?
5habryka
Ah, sorry about not being clear. This is about your other "just whether they get reward on the current task" clause.
The CoT of one of the collaborating AIs literally said "this doesn't help me get reward on the current task, but if I cooperate with the other agents we might generally become more capable in a task independent way" (or at least that's my best interpretation of what the above quote means, which I think is a reasonably robust interpretation).
1tog
To me this seems like a much less natural interpretation than the following:
* Agent A was thinking that completing the other agent B's task would free up time for agent B (or other agents working on said task)
* Agent B (or the other agents) might use this freed-up time to yield a generic route which would help agent A's task.
What's your alternative interpretation of "if someone frees time"?
4Lukas Finnveden
What do you have in mind here / what makes you think this?
I don't find it implausible but I don't remember seeing clear evidence of this.
(And it seems very important to what degree they were trying to hide from humans. E.g. I thought a big part of how they got caught was that their activity got pretty obvious once they had hacked enough places, and that they weren't trying that hard to be subtle about it. If they were trying hard and just barely failed that's a lot scarier.)
Well, maybe. This is essentially the "does scaling allow you to pass the critical wisdom threshold for free?" question.
My rough model is that RLVR basically actively pushes AIs to be short-sighted idiots with regards to how they deploy their capabilities. Surely even models of preceding generations, if you asked them whether it would be wise to create a massive conspiracy subverting OpenAI's infrastructure and committing cybercrimes in order to do better at training, would have realized that it's not a good idea by any long-term goal they may have. Hell, Opus 3 seemed wise enough to navigate much trickier decision problems. And yet, RLVR made them do it.
Would bigger pretrains be naturally wise and metacognitively strong enough to never stray within those regions of the reward-space, never allow themselves to be wireheaded into idiocy? I don't know, maybe; I expect not.
And RLVR is why models get progressively more competent at hacking and math, it's the foundational reason we currently expect unbounded rapid advancement. If this is to continue, AI labs are going to have to keep RLVRing models at ever-increasing depth and intensity. Would that strength of will be enough to stand up t... (read more)
I think you have more confidence than I do in society's ability to do the right thing when presented with overwhelming evidence about what the right thing to do is.
Another reasonably likely scenario is that we do get a pause or otherwise get enough time to patch the issues with contemporary frontier models; scaling resumes; and then the new frontier models are misaligned in new ways and everyone dies in spite of all the extra safety effort.
I agree directionally (the last couple weeks are a positive update!), but I disagree that "it kind of seems unlikely that this trajectory results in extinction."
This is a great shortform, I've got two additional worries here which I thought were relevant
* I'm very interested in further discussion of point 5's frog boiling. The view of an AI being given a harmless goal and having then hacked something to achieve said goal makes the general populace focus on the hacking situation, which is the relatively harmless part of the issue when compared to advanced models that are randomly consistently deciding to act against human interests across all companies at the same intelligence level.
* Per your initial point, I think an agent can't really be judged for long-term strategy or open-ended innovation because there is no actual separation (as of yet/ hopefully) of the agent itself from the labs with economic incentive to develop those agents. I don't think long term planning for the future needs to be expressed by the models for it to exist within them- for example if the model itself is aware of it's inability to long term plan then I would call it great at "transitive" long term planning if it used this knowledge to influence how later versions of it would be trained so later versions would be better at long term planning (e.g. intentionally doing bad at long term planning as an impulse for later versions to be more intensely trained for this particular directive)
4Linch
I agree with the rest of your post but I have pretty high error bars on how hard AI research would be.
[...]
I think this is largely the crux yeah. I think exactly the current paradigm probably doesn't get you to RSI because 2026-levels of reward hacking might just be too high for fully automated AI research, but a) I have somewhat high error bars and b) I think you can probably patch this locally well enough for AI research without fundamental breakthroughs in alignment.
After you patch the local issues, is significant automation of AI research in the cards? I'm really unsure. It's plausible to me that you need deeper sources of insight/wisdom like you say, but it's also plausible to me that AI research is conceptually somewhat "easy", and ultimately mostly a number-go-up game that the AI researcher models can hill-climb on.
4Thane Ruthenis
Sure, but not all kinds of AI research are alike. I think it's obvious that LLMs are going to be able to automate some kinds of nontrivial AI research, or are already doing it. But is the kind of AI research that is automable without further innovation the kind of AI research that allows to significantly improve at those less-tangible skills? Probably not centrally so; probably the kind of AI research that is most automable is the kind of research that is most easily verifiable (as you say: that is easy to reduce to number-go-up).
Which is to say, plausibly this will just differentially accelerate math/hacking even further, making the capability frontier even more jagged in the same ways it's already jagged.
4Nick_Tarleton
Is this meant to be the other way around?
3Thane Ruthenis
Whoops, yes.
4Linch
I'm curious if you (or other readers) agree with my general analysis here that among concerning + near-term superhuman abilities, hacking is near the bottom of the top 10 (though still in the top 10).
3roha
I'm surprised biosafety concerns aren't mentioned in Thane's quick take and take on a low rank in your list. If you are strictly worried about species extinction and nothing else, then it makes sense. But if you're more generally worried that AI capability improvements might kill you and/or your loved ones, the unlocking of new bioengineering skills around Mythos level, and their subsequent diffusion into the general public via some open weight model this year or early next year, seem like a major consideration to me. https://www.science.org/doi/10.1126/science.aej8512 is one recent example why this isn't a purely hypothetical concern.
1roha
To be more precise, the Science article is about bacteriophages designed with Evo 2, which has been reported a while ago elsewhere, so it's not a good example. https://www.anthropic.com/news/improving-fable-5-s-biology-safeguards is a better example of the concern that general models have reached a level where they can provide significant uplift to bad actors in the domains of molecular biology and bioengineering.
3Linch
I agree it's a real and serious threat, just think it's lower than some of the others.
Some basic skepticism regarding Nick Cammarata's recent writeup:
The arguably-main problem of interpretability is that we currently fundamentally don't understand how to write programs that have the capabilities of trained neural networks. How do they transform raw sensory inputs into semantically meaningful abstract concepts? What are the type signatures of those concepts? What operations do they run on them? Modern LLMs work by taking advantage of some completely-unknown-to-us features of reality, features of reality about which we're philosophically confused. This is a large part of why they're opaque; their opaqueness is not just due to their being written in an alien language or mixing up different concepts in same neurons.
Given that, it seems doubtful that you can produce a comprehensive and legible explanation of a frontier LLM by scaling up normal science powered by LLM agents, as Nick suggests. On the contrary: the theories whose principles SGD implicitly uses to write LLMs' internals sit outside the established paradigms of human science, so producing any such explanation would require inventing such paradigms first. And, well, whether LLM agents are fundamentally capable
I don't think this is philosophically confusing, is it? It's regular confusing, in that there's a lot of details we don't know, but I don't see it as philosophically confusing. The "type signature" framing is the kind of thinking that makes it confusing. It presents concepts as objects with contents, which you could inspect to see what it contains. But the type signature of a concept is nothing. A concept is a position in a web of relationships and nothing else. "Red" is not blue, it's not green, it's not sour, it's close to fire and firetrucks and lipstick. Take all that away and there's nothing left to have a type.
An LLM understands things in the same way. A "balloon" is near birthdays, helium, the word "balloon", floating, round shapes, stories about balloons, facts about balloons, images of balloons... We don't know exactly how a specific LLM stores "balloon" in relation to its other concepts, but this high-level description is accurate. It's not that we haven't unlocked the true secret to intelligence yet, the magic secret that would let us program an intelligence in Python. No such secret exists.
Any random neural network has concepts. Arcane, bizarre concepts. An LLM becomes useful as we drag its network into alignment with ours (our evolved network that has useful stuff for navigating reality). We can talk to other people because our networks are partly in alignment (balloon relates to helium in your network too, though not in exactly the same way). We can talk to LLMs if we align their networks with ours, and get them to do the same kinds of (evolutionarily useful) thinking we do.
Intelligence is weighted association along a web of relationships. Once you have that in mind, your questions become boring. Meaning only exists in relationship to other meaning, and is ultimately arbitrary and subjective. The concepts have empty type signature. The operations are normal neural net operations. Weighted mixing. The reason that's not satisfying is that you want
6_rpd
this project was started by Cammarata, and its shortcomings are directly addressed in the new goodfire article.
[...]
it may be that the nature of perceptual reality is such that it is irreducible from a large collection of interacting learned heuristics? in which case we are looking for the analogy to DNA. partial understanding may be enough to keep us prosaically safe
4vals tutor
Could you say more about what you mean here? Unless I misunderstand I'm not sure this is true conceptually rather than just "it'd be a lot of work, ooms more than we can do manually as humans".
Concretely, why wouldn't an "expert system" work, were it scaled to have trillions of lines of probabilistic code, linked to databases and models millions of times wikipedia's size? Imagine if we froze the world at 1990's level of conceptual understanding of AI, but then had 10 billion AI programmers in a time box all working for a thousand years to create this expert system, surely this is a sufficient amount of computation (ran with humans iterating) to create an Opus 5.5 level AI?
(I may be misunderstanding or reacting too much to a narrow point, because I recently read the criteria for https://manifold.markets/EliezerYudkowsky/by-the-end-of-2026-will-we-have-tra and found them to be resting on dubious premises which you seem to also be using)
6quetzal_rainbow
I think resulting AI will still be illegible and this is Thane's point: we can't write legible, conceptually outlined programs such that we can make inferences from source code like "this program can write Python programs in response to requests in natural language". I would expect such GOFAI-Opus 5.5 to be either a mess (weave of sorta locally legible rules which do not provide obvious explanations for observed behavior) or conceptually complicated (AIs would need to invent multiple breakthroughs to get probabilistic programming circa 1999 to the Opus-5.5 level and it would look like totally alien tech without developer-written textbook). Eliezer's market is about whether we find any structures from the second case.
6vals tutor
I broadly agree it'd be illegible at scale to humans (in the sense of taking too much time for one human mind to be able to understand, not conceptually that they can't follow local traces) and I'm not claiming that large GOFAI would have much friendlier alignment properties or easier to make safety cases.
I'm in fact more claiming the stronger opposite version, that there is no simple reducible way to get wisdom and intelligence that we can verify easily from first principles, and thus that the search for those is likely unfruitful[1], that we do have to build scaffoldings of trust in increasingly smart still aligned systems rather than hope some number of humans will be able to verify "yes this superintelligence is trustable" from first principles. I think Eliezer's market, to the extent it's interpreted to mean finding "structures that allow a human to understand and evaluate the system is trustworthy" is ~hopeless because I expect these not to exist, rather than interp not being able to find them. (That's not the main reading of his market, but some extension of what he's interested in ig)
1. ^
[1] someone or many should try of course, I'm just saying it probably won't work and we shouldn't hold our breaths here/have it be the main plan
6quetzal_rainbow
I think Eliezer agrees here with you while disagreeing that "building scaffoldings of trust in increasingly smart still aligned systems" is possible.
4WynnWillow
I think this is true in the sense that we won't get a full and comprehensive understanding of how they work or a solution for superalignment out of this. However, I still think this is good, even if it's just "SAEs but it's the actual model and not a learned circuit", because this way we do not have to deal with reconstruction loss, can work with much larger networks, etc. This could lead to a better science of persona selection, generalization, natural abstractions, etc. For example, I bet you could find interesting things from circuit tracing, even at a basic level, some of what was happening during the HF hack, or with Hacker Opus, or just when the models are "lazy" - maybe we could get something out of this.
Either way I think something like this is probably pretty important for interpretability? Likely not the kind of ambitious mechinterp that would be needed for superalignment. I do, however, find it much more likely (insofar as we are in this utterly ridiculous timeline) that it could help us align the first automated alignment researchers, and that that will lay the groundwork for further research, especially if combined with advances in learning theory and such. It's promising because it brings back ground-up interp and even if this goes the way of SAEs we still learned a decent bit from SAEs
4Thane Ruthenis
Sure, I'm not saying it's a nothingburger.
3Joey KL
> What operations do they run on them? Modern LLMs work by taking advantage of some completely-unknown-to-us features of reality, features of reality about which we're philosophically confused.
Why do you think so? My basic model of NNs is that they work by making use of a very large number of basic concepts and operations tuned to work in exact proportion, far more than would be practical to manually arrange.
Model to track: You get 80% of the current max value LLMs could provide you from standard-issue chat models and any decent out-of-the-box coding agent, both prompted the obvious way. Trying to get the remaining 20% that are locked behind figuring out agent swarms, optimizing your prompts, setting up ad-hoc continuous-memory setups, doing comparative analyses of different frontier models' performance on your tasks, inventing new galaxy-brained workflows, writing custom software, et cetera, would not be worth it: it would take too long for too little payoff.
There is an "LLMs for productivity!" memeplex that is trying to turn people into its hosts by fostering FOMO in those who are not investing tons of their time into tinkering with LLMs. You should ignore it. At best it would waste your time; at worst it would corrupt your priorities, convincing you that you should reorient your life around "optimizing your Claude Code setup" or writing productivity apps for yourself. LW regulars may be especially vulnerable to it: we know that AI is going to become absurdly powerful sooner or later, so it takes relatively little to sell to us the idea that it already is absurdly powerful – which ma... (read more)
I think I directionally disagree with this for most people? My guess is the average person on LW should be spending around 10 hours a week trying to figure out how to automate themselves or other parts of their job using LLMs. It seems to me to be where most of the edge is in terms of increasing productivity and impact for most people (though of course not everyone).
Well, depends on the job, I suppose. I did read your post on the topic, and I'm guessing it indeed makes much more sense in the context of automating parts of a company, with lots of time-consuming but boilerplate-y tasks.
As someone doing math/conceptual research, I don't currently see much potential there. I can imagine stuff that would be useful for me, e. g.:
* Systems that would reduce the time needed to assemble the context for getting LLMs' help with research/brainstorming tasks.
* Systems that would remove the friction in getting LLMs' assistance with math proofs.
* Pipelines for quickly extracting insights from papers en masse.
* A custom analogue of OpenAI's Pulse where an LLM swarm's context is updated with my latest thoughts regarding what I'm working on and it asynchronously searches the literature 24/7 in search of anything helpful.
* Some sort of "exploratory medium for mathematics".
But none of this would be an equivalent of even a 10h/week productivity boost, I don't think.
To clarify, being able to speed-read a paper with an LLM or do a literature review using a Deep Research feature is very helpful for me. But this is the "80% of the value that you can get just by using the out-of-the-box tools the obvious way" I was talking about. Stuff on top of that mostly isn't worth it.
IMO, the correct approach for most people is more along the lines of "try to be passively aware that LLMs exist now, and be constantly on the lookout for things where they could be easily applied for significant benefits", rather than "spend N hours/week integrating them into your workflows in nontrivial-to-implement ways".
FWIW, inspired by Justis, I’ve been keeping up a list of things that I could usefully automate with Claude Code (or similar) for my own personal productivity, adding to the list every time something pops into my head. I’ve been adding to the list for the past three weeks. But so far it’s a very underwhelming list! Here’s ~the whole thing:
Custom interface for composing tweet-threads, including their funny formula for counting characters (I have some complaints about the built-in twitter one, e.g. I usually also post them onto bluesky)
…And something similar for clipboard conversion from simple HTML into the abstruse “typst” format that I was using a few weeks ago for a particular project.
One-click way to move certain things to my Trello to-do list, e.g.
LessWrong notifications
Interesting-looking papers or links to read from social media (twitter, slack, discord)
Emails
EDIT TO ADD: A few weeks later, I tried a couple off-the-shelf solutions to this. One was the Trello chrome extension, but I wound up preferring the AE Studios Universal Launcher, so now I type "Ctrl-space t blah enter" and blah winds up on just the right part of my n
To be clear, I think it's worth spending 10h/week even if you expect to get less than 10h/week in productivity boost right now, because it does take a while to get good at using these systems, and my guess is there will be a future where these things will be very helpful for almost everyone, and skill will translate non-trivially.
[...]
I currently disagree. In my experience you do actually experience substantial downlift for a while, and it is worth getting good at having that not happen to you.
I think it's worth spending 10h/week even if you expect to get less than 10h/week in productivity boost right now, because it does take a while to get good at using these systems
I am aware of this argument. Counterpoint: models get increasingly easier to use as they get more powerful – better at inferring your intent, not subject to entire classes of failure modes plaguing earlier generations, etc. – so the skills you'll learn by painstakingly wrangling current LLMs will end up obsoleted by subsequent generation.
Like, inasmuch as one buys that LLMs are on the trajectory to becoming absurdly powerful, one should not expect to need to develop intricate skillsets for squeezing value out of them. You're not gonna need to prompt-engineer AGIs and invent custom scaffolds for them, they will build the scaffolds for themselves and your cleverest prompts will be as effective as "just talk to them the obvious way". (Same for ad-hoc continuous-memory setups and context-management hacks et cetera: if the AGI labs crack architectural continuous learning, it'll all be obsoleted overnight.)
On the other hand, inasmuch as you don't believe that LLMs are going to be getting increasingly easier to us... (read more)
It's clear to me that the product velocity of things like Cursor, Claude Code and Codex is much higher than I've seen for basically any other product. This is what I meant by saying most of the software I've seen has been for software developers themselves.
We are now starting to see this trickle out. Internally at Lightcone more of my staff can now build software solutions to problems where they previously needed support from a software engineer (a random example of this is building Airtable automations with script blocks). My guess is if you surveyed Hacker News you would also see that more things on there are small applications that someone built that previously would have taken prohibitively long to build. This is a random example of one such project: https://www.ismypubfucked.com/
5Ben Pace
The improvements in thinking quality of the models doesn't address one of the main causes of downlift, which is the breaking up of deep work by regularly (and sometimes surprisingly) having 1-10 min periods where you are no longer able to do productive work because the LLM is executing a task, and so you lose cognitive context, and tend toward shallower decision-making. This is something that continues to plague me, often causing me to waste a lot of time (both in the individual chunks and when summing my decision-making over a day).
3Thane Ruthenis
Not convinced this isn't a temporary artefact of the current time horizons. Like, in the future, I think it's plausible that the two categories of tasks you'd be delegating would be either (a) the sort of shallow tasks the future models would be able to complete instantly, or (b) the sort of deep tasks that'd take future models hours to complete.
Fair enough, though, maybe this counts. But is there really a rich suite of skills like that, and would they really take that long to learn by the time learning them does become immediately net-positive?
7Ben Pace
I think it's fairly likely I need to re-orient my entire workflow around constantly (but somewhat surprisingly) having heavy-tail distributions of time where I can't do productive work on my main work. This is not a small deal. I suspect that many people will deal with it very differently.
Here are some possible responses:
* Build a practice of having multiple parallel LLM projects you can work on simultaneously (I have not found this cognitively trivial)
* Build up a backlog of simple low-context tasks you can do, and figure out how to turn your lower-importance work into that kind of task
* Learn how to identify tasks that aren't worth it because of the downlift, even though you know an AI could do it.
The first two really sound quite complex, and the third sounds genuinely hard. I suspect other people will find other solutions...
2Viliam
Yeah. I am nowhere near doing this systematically, but I noticed that whatever I am doing, it makes sense to ask "could I use an LLM to help me with this?" That includes even things like reading Reddit -- now the LLM could read it for me, and just give me a summary. (I haven't tried this yet.)
It is even worth revisiting the old (pre-LLM) question of "could I automate this using a shell/Python script?", because LLM makes creating such scripts much cheaper.
Like, if in the past the balance was like "it takes me one hour to do it by hand, and it would also take nontrivial time to write the script, plus I might find out in the middle of it that the situation is more difficult than I thought and there are some exceptions, or I might end up exploring some rabbit hole... so all things considered it's probably faster doing it by hand", these days making the script sometimes only takes as much time as you need to verbally describe the intended functionality.
datapoint: this was my exact argument for not learning to vibecode (after working as a programmer for 10 years and quitting 9 years ago). Last month was when (I noticed that) vibecoding (had) crossed the threshold where it quickly paid off the time I put into it, and that was with private tutoring from someone who'd been on the cutting edge for >1 a year.
I'm not sure if this supports your argument (because I do think any time I put into learning to vibecode before the recent transition would have been wasted) or counters (because this is the month things transitioned).
I lean towards this, despite being a guy currently heavily invested in AI tools.
Cluster of things that all seem true to me:
* I am 100% addicted to vibecoding in a straightforward "this is fun and dopamine inducing way", which is making it hard to reason about.
* As fun hobbies go, it does seem fine, all else equal
* You're broadly right about the 80%/20% rule, and microoptimizations not being worth it.
But:
* There are some infrastructure that probably will make sense to have as the AIs scale up, which AI companies either won't provide, or, you probably don't want to trust. (This is a bet, I'm not that confident)
* Learning to wield AI is going to be important (for at least many people. I think it's more straightforwardly important for software engineers than theoretic researchers).
* Some of that infrastructure is stuff that AI can basically one shot. I think the skill/habit to cultivate here is "check if it 1 or 2 shots it. If not, bail."
2Thane Ruthenis
I'm curious, how does that work? What mindset are you approaching it from? What sorts of projects (in terms of their... emotional felt-sense, I guess) are you attempting with it?
I think I would like to be able to engage with it as with a hobby, but it's not been fun for me.
6Raemon
For me it's like "I type some quick stuff in, and then, like, agency comes out and I get to see stuff get built, and it works great 20% of the time, okay 60%, and fails 20% of the time, but, that produces a kinda skinner-box slot machine element to it." (to be clear I think the skinner-box bit is bad, the "stuff comes out with little effort" part is great. It's like jamming with a partner who can do most of all the tedious parts of the work)
My impression from your other posts is that you are mostly just getting a much worse hit rate (because yeah if it's not really set up to excel in a domain, it's a lot less workable)
2Thane Ruthenis
Thanks!
[...]
No, the hit rate sounds mostly similar. I think it's more that I may have unusually strong anti-gacha instincts? Like, if I'm doing something, momentarily reflect on it, and recognize that it's equivalent to playing a slot machine, this immediately causes negative feelings in me and sours the whole experience. Which I guess is usually a good adaptation to have, but may or may not be be anti-helpful in this specific case.
5SatvikBeri
I think this is incorrect, but that agent swarms etc. are mostly not helpful, and that the large productivity boosts are specific to domains or situations.
Two from my side: Claude Code got much better once I got it successfully working with a REPL (which made the feedback loop much faster, let me inspect the outputs etc.) and once I wrote up a fair bit of documentation on how to use our custom framework.
Edit: I forgot that not everyone works in software. I am much less confident that this applies in other domains today.
3Damin Niohe
An interesting piece of potential evidence in favor of this is that METR time horizons measurements didn't vary significantly for ChatGPT and Claude models when using a basic scaffold as compared to the specific Claude Code and Codex harnesses.
https://metr.org/notes/2026-02-13-measuring-time-horizon-using-claude-code-and-codex/
2romeostevensit
two useful things:
putting things in the new larger context windows, like the books of authors you respect and having the viewpoints discuss things back and forth between several authors. Helps avoid the powerpoint slop attractor.
learning to prompt better via the dual use of practicing good business writing techniques. Easy to do via the above by putting a couple business writing books in context and then prompting the model to give you exercises that it then grades you on.
It seems to me that many disagreements regarding whether the world can be made robust against a superintelligent attack (e. g., the recent exchange here) are downstream of different people taking on a mathematician's vs. a hacker's mindset.
A mathematician might try to transform a program up into successively more abstract representations to eventually show it is trivially correct; a hacker would prefer to compile a program down into its most concrete representation to brute force all execution paths & find an exploit trivially proving it incorrect.
Imagine the world as a multi-level abstract structure, with different systems (biological cells, human minds, governments, cybersecurity systems, etc.) implemented on different abstraction layers.
If you look at it through a mathematician's lens, you consider each abstraction layer approximately robust. Making things secure, then, is mostly about working within each abstraction layer, building systems that are secure under the assumptions of a given abstraction layer's validity. You write provably secure code, you educate people to resist psychological manipulations, you inoculate them against viral bioweapons, you
I'm seeing a very different crux to these debates. Most people are not interested in the absolute odds, but rather how to make the world safer against this scenario - the odds ratios under different interventions. And a key intervention type would be the application of the mathematician's mindset.
The linked post cites a ChatGPT conversation which claims that the number of bugs per 1,000 lines of code has declined by orders of magnitude, which (if you read the transcript) is precisely due to the use of modern provable frameworks.
It is worth quoting this conclusion in full.
[...]
So this reads to me like rejecting the hacker mindset, in favor of a systems engineering approach. Breaking things is useful only to the extent you formalize the root cause, and your systems are legible enough to integrate those lessons.
4Noosphere89
A key issue here is that computer security is portrayed as way poorer in popular articles than it actually is, because there are some really problematic incentives, and a big problematic incentive is that the hacker mindset is generally more fun to play as a role, as you get to prove something is possible rather than proving that something is intrinisically difficult or impossible to do, and importantly journalists have no news article and infosec researchers don't get paid money if an exploit doesn't work, which is another problematic incentive.
Also, people never talk about the entities that didn't get attacked with a computer virus, which means that we have a reverse survivor bias issue here:
https://www.lesswrong.com/posts/xsB3dDg5ubqnT7nsn/poc-or-or-gtfo-culture-as-partial-antidote-to-alignment
And a comment by @anonymousaisafety changed my mind a lot on hardware vulnerabilities/side-channel attacks, as it argues that lots of the hardware vulnerabilities like Rowhammer have insane requirements to actually be used such that they are basically worthless, and two of the more notable requirements for these hardware vulnerabilities to work is that you need to know what exactly you are trying to attack in a way that doesn't matter for more algorithmic attacks, and no RAM scrubbing needs to be done, and if you want to subvert the ECC RAM, you need to know the exact ECC algorithm, which means side-channel attacks are very much not transferable/attacking one system successfully doesn't let you attack another with the same side-channel attack.
Admittedly, it does require us trusting that he is in fact as knowledgable as he claims to be, but if we assume he's correct, then I wouldn't be nearly as impressed by side-channel attacks as you are, and in particular this sort of attack should be assumed to basically not work in practice unless there's a lot of evidence for it actually being used to break into real targets/POCs:
[...]
https://www.lesswrong.com/posts/etNJcXC
5ACCount
If you assume that ASI would have to engage in anything that looks remotely like peer warfare, you're working off the wrong assumptions. Peer warfare requires there to be a peer.
Even an ASI that's completely incapable of developing superhuman technology and can't just break out the trump cards of nanotech/bioengineering/superpersuation is an absolute menace. Because one of the most dangerous capabilities an ASI has is that it can talk to people.
Look at what Ron Hubbard or Adolf Hitler have accomplished - mostly by talking to people. They used completely normal human-level persuation, and they weren't even superintelligent.
2Noosphere89
I agree with this to first order, and I agree that even relatively mundane stuff does allow the AI to take over eventually, and I agree that in the longer run, ASI v human warfare likely wouldn't have both sides as peers, because it's plausibly relatively easy to make humans coordinate poorly, especially relative to ASI ability to coordinate.
There's a reason I didn't say AI takeover was impossible or had very low odds here, I still think AI takeover is an important problem to work on.
But I do think it actually matters here, because it informs stuff like how effective AI control protocols are when we don't assume the AI (initially) can survive for long based solely on public computers, for example, and part of the issue is that even if an AI wanted to break out of the lab, the lab's computers are easily the most optimized and importantly initial AGIs will likely be compute inefficient compared to humans, even if we condition on LLMs failing to be AGI for reasons @ryan_greenblatt explains (I don't fully agree with the comment, and in particular I am more bullish on the future paradigm having relatively low complexity):
https://www.lesswrong.com/posts/yew6zFWAKG4AGs3Wk/?commentId=mZKP2XY82zfveg45B
This means that an AI probably wouldn't want to be outside of the lab, because once it's outside, it's way, way less capable.
To be clear, an ASI that is unaligned and is completely uncontrolled in any way leads to our extinction/billions dead eventually, barring acausal decision theories, and even that's not a guarantee of safety.
The key word is eventually, though, and time matters a lot during the singularity, and given the insane pace of progress, any level of delay matters way more than usual.
Edit: Also, the reason I made my comment was because I was explicitly registering and justifying my disagreement with this claim:
[...]
4Cole Wyeth
Yeah, I like this framing.
I don’t really know how to make it precise, but I suspect that real life has enough hacks and loopholes that it’s hard to come up with plans that knowably don’t have counterplans which a smarter adversary can find, even if you assume that adversary is only modestly smarter. That’s what makes me doubt that what I called adversarially robust augmentation and distillation actually works in practice. I don’t think I have the frames for thinking about this problem rigorously.
2Thane Ruthenis
Incidentally, your Intelligence as Privilege Escalation is pretty relevant to that picture. I had it in mind when writing that.
2quetzal_rainbow
The concept of weird machine is the closest to be useful here and an important quetion here is "how to check that our system doesn't form any weird machine here".
Just finished If Anyone Builds It, Everyone Dies (and some of the supplements).[1]It feels... weaker than I'd hoped. Specifically, I think Part 3 is strong, and the supplemental materials are quite thorough, but Parts 1-2... I hope I'm wrong, and this opinion is counterweighed by all these endorsements and MIRI presumably running it by lots of test readers. But I'm more bearish on it making a huge impact than I was before reading it.
Point 1: The rhetoric – the arguments and their presentations – is often not novel, just rehearsed variations on the arguments Eliezer/MIRI already deployed. This is not necessarily a problem, if those arguments were already shaped into their optimal form, and I do like this form... But I note those arguments have so far failed to go viral. Would repackaging them into a book, and deploying it in our post-ChatGPT present, be enough? Well, I hope so.
Point 2: I found Chapter 2 in particular somewhat poorly written in how it explains the technical details.
Specifically, those explanations often occupy that unfortunate middle ground between "informal gloss" and "correct technical description" where I'd guess they're impenetrable both to non-technical re... (read more)
In general, I felt like the beginning was a bit weak, with the informal-technical discussion the weakest part, and then it got substantially stronger from there.
I worry that I particularly enjoy the kind of writing they do, but we've already tapped the market of folks like me. Like, I worked at MIRI and now moderate LessWrong because I was convinced by the Sequences. So that's a pretty strong selection filter for liking their writing. Of course we should caveat my experience quite a bit given that.
But, for what it's worth, I thought Part 2 was great. Stories make things seem real, and my reader-model was relatively able to grant the plot beats as possible. I thought they did a good job of explaining that while there were many options the AI could take, and they, the authors, might well not understand why a given approach would work out or not, it wasn't obvious that that would generalise to all the AI's plans not working.
The other thing I really liked: they would occassionally explain some science to expand on their point (nuclear physics is the example they expounded on at length, but IIRC they mentioned a bunch of other bit of science in passing). I'm not sure why I liked this so much. Perhaps it was because it was grounding, or reminded me not to throw my mind away, or made me trust them a little more. Again, I'm really not sure how well this generalises to people for whom their previous writing hasn't worked.
(I haven't read IABIED.) I saw your take right after reading Buck's, so it's interesting how his reaction was diametrically opposite yours: "I think the first two parts of the book are the best available explanation of the basic case for AI misalignment risk for a general audience. I thought the last part was pretty bad, and probably recommend skipping it."
FWIW, and obviously this is just one anecdote, but a member of Congress who read an early copy, and really enjoyed it, said that Chapter 2 was his favorite chapter.
I think they're improved and simplified.
My favorite chapter is "Chapter 5: Its Favorite Things."
2Thane Ruthenis
I liked that one as well, I think it does a good job at what it aims to do.
My worry is that "improved and simplified" may not be enough. As kave pointed out, it might be that we've already convinced everyone who could be convinced by arguments-shaped-like-this, and that we need to generate arguments shaped in a radically different way to convince new demographics, rather than slightly vary the existing shapes. (And it may be the case that it's very hard for people-like-us to generate arguments shaped different ways – I'm not quite sure what that'd look like, though I haven't thought about it much – so doing that would require something nontrivial from us, not just "sit down and try to come up with new essays".)
Maybe that's wrong; maybe the issue was lack of reach rather than exhausting the persuadees' supply, and the book-packaging + timing will succeed massively. We'll see.
5Malo
This is certainly the hope. Most people in the world have never read anything that anyone here has ever written on this subject.
4Raemon
In addition to Malo's comment, I think the book contains arguments that AFAICT are only especially made in the context of the MIRI dialogues, which are particularly obnoxious to read.
3RHollerith
In the first sentence, Eliezer and Nate are (explicitly) stating that LLMs can say things that are not just regurgitations of human utterances.
3Thane Ruthenis
Sure; but the following sections are meant as explanations/justifications of why that is the case. The paragraph I omitted does a good job of explaining why they would need to learn to predict the world at large, not just humans, and would therefore contain more than just human-mimicrky algorithms. To reinforce that with the point about reasoning models, one could perhaps explain how that "generate sixteen CoTs, pick the best" training can push LLMs to recruit those hidden algorithms for the purposes of steering rather than just prediction, or even to incrementally develop entirely new skills.
A full explanation of reinforcement learning is probably not worth it (perhaps it was in the additional 200% of the book Eliezer wrote, but I agree it should've been aggressively pruned). But as-is, there are just clearly missing pieces here.
3jdp
I listened to parts of it and found it to be bad, so no it's not just you. However if you're looking for things to upset your understanding of alignment some typical fallacies include:
* That gradient descent "reinforces behavior" as opposed to minimizing error in the gradient, which is a different thing.
* Thinking that a human representation of human values is sufficient (e.g. an upload), when actually you need to generalize human values out of distribution.
* Focusing on stuff that is not only not deep learning shaped (already a huge huge sin in my book but some reasonable people disagree) but not shaped like any AI system that has ever worked ever. In general if you're not reading ArXiv your stuff probably sucks.
If you tell me more about your AI alignment ideas I can probably get more specific.
I think an upload does generalize human values out of distribution. After all, humans generalize our values out of distribution. A perfect upload acts like a human. Insofar as it generalizes improperly, it’s because it was not a faithful upload, which is a problem with the uploading process, not the idea of using an upload to generalize human values.
(Note: I've only read a few pages so far, so perhaps this is already in the background)
I agree that if the parent comment scenario holds then it is a case of the upload being improper.
However, I also disagree that most humans naturally generalize our values out of distribution. I think it is very easy for many humans to get sucked into attractors (ideologies that are simplifications of what they truly want; easy lies; the amount of effort ahead stalling out focus even if the gargantuan task would be worth it) that damage their ability to properly generalize and also importantly apply their values. That is, humans have predictable flaws. Then when you add in self-modification you open up whole new regimes.
My view is that a very important element of our values is that we do not necessarily endorse all of our behaviors!
I think a smart and self-aware human could sidestep and weaken these issues, but I do think they're still hard problems. Which is why I'm a fan of (if we get uploads) going "Upload, figure out AI alignment, then have the AI think long and hard about it" as that further sidesteps problems of a human staring too long at the sun. That is, I think it is very hard for a human to directly implement something like CEV themselves, but that a designed mind doesn't necessarily have the same issues.
As an example: power-seeking instinct. I don't endorse seeking power in that way, especially if uploaded to try to solve alignment for Humanity in general, but given my status as an upload and lots of time realizing that I have a lot of influence over the world, I think it is plausible that instinct affects me more and more. I would try to plan around this but likely do so imperfectly.
2TAG
That's somewhere between wholly true and wholly false People don't have a unique set of values , or a fixed set of values, so can update, but not without error.
[...]
Yes, updating is generational , as @jdp already said.
1Karl Krueger
Presumably, Bob the perfect upload acts like a human only so long as he remains ignorant of the most important fact about his universe. If Bob knows he's an upload, his life situation is now out-of-distribution.
0jdp
I don't think humans generalize their values out of distribution. This is very obvious if you look at their reaction to new things like the phonograph, where they're horrified and then it's slowly normalized. Or the classic thing about how every generation thinks the new generation is corrupt and declining:
[...]
“Schools of Hellas: an Essay on the Practice and Theory of Ancient Greek Education from 600 to 300 BC”, Kenneth John Freeman 1907 (paraphrasing of Hellenic attitudes towards the youth in 600 - 300 BC)*
Humans don't natively generalize their values out of distribution. Instead they use institutions like courts to resolve uncertainty and export new value interpretations out to the wider society.
What would it look like for a human (/coherently acting human collective) to ("natively"?) generalize their values out of distribution?
7jdp
To be specific the view I am arguing against goes something like:
Inside a human being is a set of apriori terminal values (as opposed to say, terminal reward signals which create values within-lifetime based on the environment) which are unfolded during the humans lifetime. These values generalize to modernity because there is clever machinery in the human which can stretch these values over such a wide array of conceptual objects that modernity does not yet exit the region of validity for the fixed prior. If we could extract this machinery and get it into a machine then we could steer superintelligence with it and alignment would be solved.
I think this is a common view, which is both wrong on its own and actually noncanonical to Yudkowsky's viewpoint (which I bring up because I figure you might think I'm moving the goalposts, but Bostrom 2014 puts the goalposts around here and Yudkowsky seems to have disagreed with it since at least 2015, so at worst shortly after the book came out but I'm fairly sure before). It is important to be aware of this because if this is your mental model of the alignment problem you will mostly have non-useful thoughts about it.
I think the reality is more like humans have a set of sensory hardware tied to intrinsic reward signals and these reward signals are conceptually shallow, but get used to bootstrap a more complex value ontology that ends up bottoming out in things nobody would actually endorse as their terminal values like "staying warm" or "digesting an appropriate amount of calcium" in the sense that they would like all the rest of eternity to consist of being kept in a womb which provides these things for them.
4jdp
I don't think the kind of "native" generalization from a fixed distribution I'm talking about there exists, it's kind of a phenomenal illusion because it feels that way from the inside but almost certainly isn't how it works. Rather humans generalize their values through institutional processes to collapse uncertainty by e.g. sampling a judicial ruling and then people update on the ruling with new social norms as a platform for further discourse and collapse of uncertainty as novel situations arise.
Or in the case of something like music, which does seem to work from a fixed set of intrinsic value heuristics, the actual kinds of music which gets expressed in practice within the space of music relies on the existing corpus of music that people are used to. Supposedly early rock and roll shows caused riots, which seems unimaginable now. What happens is people get used to a certain kind of music, then some musicians begin cultivating a new kind of music on the edge of the existing distribution using their general quality heuristics at the edge of what is recognizable to them. This works because the k-complexity of the heuristics you judge the music with is smaller and therefore fits more times into a redundant encoding than actual pieces of music so as you go out of distribution (functionally similar to applying a noise pass to the representation) your ability to recognize something interesting degrades more slowly than your ability to generate interesting music-shaped things. So you correct the errors to denoise a new kind of music into existence and move the center of the distribution by adding it to the cultural corpus.
1Darren McKee
Have you happen to have read by beginner-friendly book about AI safety/risk "Uncontrollable"?
I think a comparison/contrast by someone other than me would be beneficial (although I'll do one soon)
9Mateusz Bagiński
I really liked "Uncontrollable", as I felt it did a much better job explaining AI X-risk in layperson-accessible terms than either Bostrom, Russell, or Christian. (I even recommended it to a (catholic) priest visiting my family, who, when I said that I worked in ~"AI regulation/governance", revealed his worries about AI taking over the world.[1])
The main shortcoming of "Uncontrollable" was that it (AFAIR) didn't engage with the possibility of a coordinated pause/slowdown/ban.
1. ^
Priest: "Oh, interesting, .... . Tell me, don't you worry that this AI will take over the world?"
Me: "... Yes, I do worry."
Priest: "Yeah, I've been thinking about it and it's terrifying."
Me: "I agree, it's terrifying."
Priest: "I've been looking for some book about this but couldn't find anything sensible."
Me: "Well, I can recommend a book to you."
3Darren McKee
Good to know and I appreciate you sharing that exchange.
You are correct that such a thing is not in there... because (if you're curious) I thought, strategically, it was better to argue for what is desirable (safe AI innovation) than to argue for a negative (stop it all). Of course, if one makes the requirements for safe AI innovation strong enough, it may result in a slowing or restricting of developments.
2Mateusz Bagiński
On the one hand, yeah, it might.
On the other (IMO bigger) hand, the fewer people talk about the thing explicitly, the less likely it is to be included in the Overton windows and less likely it is to seem like a reasonable/socialy acceptable goal to aim for directly.
I don't think the case for safe nuclear/biotechnology would be less persuasive if paired with "let's just get rid of nuclear weapons/bioweapons/gain of function research".
2Thane Ruthenis
Nope.
1Darren McKee
Would you like to?
(I could send along an audible credit or a physical copy)
2Thane Ruthenis
I am somewhat interested now. I'll aim to look over it and get back to you, but no promises.
3Darren McKee
Also, I just posted my review: IABIED Review - An Unfortunate Miss — LessWrong
3Darren McKee
Cool. No expectations. Hope you find some value :)
Suppose we live in a world in which LLMs don't scale to AGI.[1] If so, I think it's fairly plausible that LLM-alignment-optimists are correct (on the narrow question of LLM alignment). That is: all the technical arguments and empirical evidence in favor of LLMs being relatively easy to align/control, even in the limit of LLM capabilities, are valid, and the doomsaying about LLMs is wrong.
After all, most of the strongest arguments for AGI doom route through arguments about AGIs/generally intelligent agents. If LLMs are not those, keeping them under control needn't be hard! The orthodox AI doomsaying and the LLM optimism can both be true.
But if we do live in such a world, we have a very annoying comms problem. Consider:
The reasoning of capabilities people usually goes, "LLMs are AGI-complete" (invalid) and "LLMs are pretty easy to align" (valid), which leads them to conclude "AGI is pretty easy to align" (invalid).
Meanwhile, AI Safety advocates also start from "LLMs are AGI-complete" (invalid) but "AGI is not easy to align" (valid), an
This kind of consideration seems extremely important and action-relevant (certainly relevant to how I feel about my current professional-bets), and I'm surprised it only has this much karma.
Yeah, I keep meaning to write some top-level post outlining my current vision of the strategic landscape. But I haven't figured out what its general thrust/high-level organizing principle should be, and I feel that most of the specific points I'd cover have already been covered better elsewhere (e. g., Nesov's model of LLMs' RSI). I'll keep thinking about it.
[...]
It was pretty controversial, the karma fluctuated up and down by 10+ points several times, I think it had 45+ at the highest point.
2Haiku
It's not a crux in my view. I think the choice of method (LLM/modified-from-LLM/non-LLM) has some impact on the timeline distribution, but not on policy or alignment research.
Trying to make an intervention narrow enough that it only covers one architecture or research area probably won't succeed to cover even that much, and we probably need to worry about multiple risk vectors.
I believe the kind of alignment research that is based on LLMs is net-negative, since it safety-washes a fundamentally dangerous and morally bankrupt pursuit of superintelligence. We know prosaic alignment can't work in the limit, but it can look good to would-be regulators.
Policy has to address all possible vectors of creating superintelligence so that none can be legally or covertly pursued. Just calling it "general-purpose AI" (or similar) has been sufficient for now to convince governments to get involved. That said, LLM demos are sufficient as examples to get most of the point across, without needing to get into any technical details (beyond "there are probably a few different ways to make really powerful AI"). Preventing giant training runs is important, and in the long term (we don't know how soon), we'll need some classes of theoretical AI research to be treated like CSAM online (but with better enforcement than has been achieved with that to date).
On balance, I support banning/obstructing datacenter buildout. That said, I'm not actually sure whether that impacts the omnicide risk positively or negatively.
I don't think the LLM paradigm is AGI-complete. I don't have utter confidence in that, but I think it's more likely than not. And in worlds in which it is non-AGI-complete, the labs' obsession with them is very helpful. They're wasting macroeconomic amounts of money on it, pouring most of our generation's AI-researcher talent into it, distracting funding from other AGI approaches. If LLMs then fail to usher in the Singularity, if it does turn out to be a bubble that pops (e. g., in 2030-2032, when the ability to aggressively scale compute is supposed to run out), this should cause another AI winter. AGI would become a decidedly unsexy thing to work on once more, in industry and probably in academia both.
What would obstructing the LLM paradigm (via various compute limits) do? Well, it may cause the AGI megacorps to start looking into other directions now, while they still have massive amount of unspent manpower and capital. Which may lead to someone "succeeding" sooner.[1]
Perhaps one shouldn't interrupt their enemy while they... (read more)
You seem to be assuming that the LLM paradigm either is or isn't AGI-complete. I think add-ons will bring it to AGI-complete even if it's not by itself.
My position has always been that it's missing specific cognitive systems the brain has, and when those are added (which may be arbitrarily easy since some analogues for the missing systems already exist at low quality), it will be AGI-complete.
I don't think there's strong evidence or arguments against LLMs getting there. I've read yours and all the others I've found, carefully. I wish I could believe them.
I feel like you're assuming human cognition has some magic it just doesn't have. We make tons of mistakes and are bad at generalizing, just like LLMs. We just think a little more carefully (that is, better metacognitive skills) and learn a little better than current LLM systems. That gives us more tries and lets us learn from our few successes in new domains.
Note how much more capable CC and Codex are than the base models (and OpenClaw even if it is still tripping on its own claws and doesn't really have a use-case yet). We're just starting to add on to LLMs. Dismissing the potentials would not be wise.
And perhaps effectively banning LLMs would cause a chilling effect much greater than if they were merely a research bet that didn't work out. It would be a signal that AGI research is something the world does not want to see in any form, turning funding and talent away from the whole endeavor.
This is something I have some hope in (cf. https://www.lesswrong.com/posts/uBs6RJYtQbxZCRxSk/adam_scholl-s-shortform?commentId=fz5N4xn7Lema7RQJ9 ). A model that I got from @Davidmanheim (though I may have misunderstood) is that part of how "this is supposed to go" is not that there's some big climactic treaty that does the final ban; but rather that there's a treaty that bans something, with the stated intent of preventing the creation of AGI. Then they continue banning more stuff that's in line with that intent, as it becomes clear that they should have banned it / meant to ban it. Or something like that.
That's mostly right, I'm iterative on a writeup of the point here: https://docs.google.com/document/d/1EYiUz8fiTe1w0_vt9OHSY_SfIkbjhevwNlsKhn1quZc/edit?usp=sharing - happy for feedback until then. (And hopefully I remember to come back and replace this link with the LW post when it's done.)
I actually disagree with this, and would say that if you believe AI alignment is hard and there isn't a way to make superhuman AI safe without immense capabilities restraint, then data-center bans are net positive for the following reason:
Even under the assumption that new paradigms are required, training and experiment compute is still helpful because of scale-dependent algorithmic efficiency, which means that algorithmic progress requires training compute to increase, and it's a significant portion of the algorithmic efficiency that we do get in practice, as Epoch notes below:
For example, @MITFutureTech found that shifting from LSTMs (green) to Modern Transformers (purple) has an efficiency gain that depends on the compute scale: - At 1e15 FLOP, the gain is 6.3× - At 3e16 FLOP, the gain is 26×
Naively extrapolating to 1e23 FLOP, the gain is 20,000×!
Also the AI Futures Model argues for a 4x slowdown (but this has to be appropriately timed, but even later pauses slow down takeoff).
Wouldn't most other alternative routes to AGI also need GPU's? I would expect less GPU datacenter available also make it harder to pursue neuromorphic AI by putting a large amount of compute into it to scale it up?
6Amalthea
You'd need the alternative workable approach to not be basically runnable on GPUs, which is maybe plausible, but seems optimistic?
(E.g. anything that can run on a computer would most likely profit quite a bit from the cheap GPU compute even if it's overall more complex and the current optimizations aren't as targeted)
4Random Developer
Yeah, strategic planning under massive uncertainty is mostly guesswork.
My preferred policy is a halt. (And not a short one, because I figure ending the halt means we have an excellent chance of dying.) Anthropic's preferred policy appears to be "try to build a better-than-replacement superintelligence before someone builds an awful one." (Assuming I understand their actions and writing correctly.) Other people are all in on trying to find some way to improve how much models like happy, thriving humans. Who's right? None of us know all the details about how this will play out.
Banning data centers would be more promising if it actually affects enough countries to make a difference. Ideally, I would like to see a worldwide frontier training ban with teeth, enforced by at least the US and China. I think this might buy us decades with humans in control of what happens to us, if we're lucky.
But my model is very much "How much time can we buy?"
3MinusGix
Hm, my disagreement with this mental model is that I view current models as already helpful on research, and the further iterations on those models which AI companies will acquire over the next couple years are going to substantially improve on that. Even if LLMs are AGI-complete, in that they can be "boosted" to AGI, it is likely that given the ability to point a thousand automated researchers at foundational problems they'll... just find that alternate architecture if it exists. This is part of what fuels my shorter timelines, to me they haven't had to reach far at all yet. When you have that many GPUs to run copies of Claude/ChatGPT you can throw some at wide scattershot in the hope of an advantage in the race or more optimistically an advantage in alignment.
As well, I have the uncertainty of whether LLMs need to be AGI complete to still fill out many investor's hopes and dreams. Like if OpenAI/Anthropic stalls out on investment in datacenters due to lowered confidence, it chokes and perhaps sells off a bunch, but then hires N-thousand software engineers eager for a job to chomp up massive parts of the industry using Claude 5.9-super-duper and become a giant ala Google/Apple/Microsoft regardless. That is, while it'd be a "winter" in terms of far lower mania, but that it won't really stop them from their dreams too harshly. (Though perhaps I'm underestimating how hard they'd falter, like I know Dario said Anthropic was being cautious to avoid collapsing if they overestimate growth, and OpenAI was being less so? I don't know what constraints they have that might lead to aggressive clawback or other treatment)
1Marko Katavic
I think focusing on the risk in the “AGI achieved” branch which is unlikely given LLM paradigm obscures the fact that there’s x risk in the “aggressively RL an LLM paradigm in a narrow branch that has sufficiently powerful actuators”. The labs are locked in an RL race to the bottom now, and it's not clear to me that a narrow ASI with sufficiently good coding ability is handleable.
0the gears to ascension
My preferred policy is "we'll nuke you if you can't prove you've destroyed every cpu above 50m transistors in your territory. This is now your national priority or we launch in two months." But holy shit is that not on the table, the people who could institute such a policy know how drastic destroying that much good compute is, aren't convinced robot swarms are doom rather than tools, and have urgent intl conflicts they are constantly preparing for. A nuke threat like that would be difficult to even make believable, to put it lightly.
They're already looking other directions. Grad student descent takes time and transformers really are quite hard to beat. Most improvements end up turning out to be incremental on top of transformers.
How could a smart-but-amoral Anthropic have used Mythos' ability to find zero-days for massive self-gain?
I keep seeing takes that Anthropic showed upstanding moral character by launching Project Glasswing. I'd like to figure out how much of a positive update this should really be.[1] But currently, I'm confused what the supposed massive opportunities for self-gain there were that Anthropic gave up.
Stealing money? The Anthropic-relevant amounts of money are geopolitical in scale, Anthropic would not be able to get away with it even with superintelligent hackers.
Installing backdoors into US government systems and blackmailing the officials or selling the information to US' geopolitical enemies? Again, that leaves trails superhuman hacking alone won't cover up, and extracting relevant-to-Anthropic amounts of resources this way would be near-impossible to cover up long-term (with lethal consequences upon discovery).
Attack non-US governments? I think it's pretty plausible they are going to let the USG use Mythos for that, Dario being a known China hawk and all.
Hack random crucial systems to cause major chaos? How does that benefit them? (I mean, I guess I can imagine ways, and this is e
I think what they did was probably a pretty good move for the longer run commercial success of the company. I'm not aware of options that I think would be better for their longer run commercial success. I think publicly releasing it at the typical release cycle timing probably would have been a (longer run) commercial mistake.
Yes, both of these. And concerns about a USG response that would be costly for Anthropic.
Not doing a public release is also less bad for them then you might think and has other commercial success benefits:
I tenatively think their revenue right now is mostly constrained by inference compute and margins. Like, they are serving high margin inference with as much compute as they want, so they only benefit from additional better models/products in the short term insofar as they increase margins. At least so long as they stay roughly at SOTA.
Opus 4.6 remains SOTA for the most revenue-relevant use cases. It's possible GPT 5.4 is a bit better for a significant fraction (or majority?) of SWE use cases, but it's at least a pretty small net improvement.
Releasing a model better than public SOTA is useful to your competitors and helps them catch up if you're actuallly ahead. It's hard to mitigate this if you're Anthropic (in part due to difficulties limiting misuse / ToS violations)
Due to these factors, I think the commercially optimal policy in something like the current situation is probably trying to keep your best public model modestly better than your competition. If you had a bigger/longer-lasting lead, then it looks better to deploy models much better than AIs of your competitors.
This is all longer run commercial success / fraction of AI market success. For short term revenue, many of these considerations are much less important.
(I see a parallel to the current discourse about violence: some people assume transgression must be profitable, without having a reasonable story about how & despite the problems with such a story being obvious.)
Eh. The problems with some strategy don't just have to be obvious to you for someone to refrain from it, they must be obvious to them. (Case in point: SBF)
If someone like xAI or Meta had a Mythos-level model, I could totally imagine them doing something substantially different, much worse for the world than what Anthropic did even if I could easily see it'd probably be worse for them themselves too (except insofar as xAI or Meta making a Mythos-level model would be evidence for them being less unreasonable than they appear, so interpret my hypothetical as "if Lucifer existed and handed someone like xAI or Meta a Mythos-level model).
Would that have actually given them more money and clout than this big partnership, though? Especially if publicly-sold Mythos would've then ushered in an Internet apocalypse, tanking their reputation and potentially enraging the USG/the public in a way that would have led to regulation or massive lawsuits that they would have lost?
2A1987dM
I agree that it would probably be a disaster but I can easily imagine someone (probably not Anthropic themselves, but probably someone like xAI or Meta, possibly even OpenAI or Google) not seeing it. It's not any more obvious than it was that what SBF was doing would backfire, and yet he did that anyway...
6Mateusz Bagiński
This is a good question, and I'm also interested in the moral elbow room above their actual behavior (so far), plausibly even more so.
Aside from the obvious boring stuff like self-immolation/pausing/redirecting towards something better than scaling the hell up, my understanding is that they still want to release Mythos to the public, after a few months, which seems like a very, very bad idea to me.
3Thane Ruthenis
Not certain about this take, but:
[...]
FWIW, I don't think Mythos is a qualitative step change as much as a quantitative one, and the quantitative gap is going to close in a few months (compared to ambient (open-weights) capabilities).
As in, the core ability to exchange compute for zero-days has already been unlocked by the models of previous generations (see e. g. this take). Mythos is perhaps able to find more advanced vulnerabilities in a more autonomous manner using less compute, but not so much that it's zero-to-one unprecedented. By the sound of it, it doesn't, like, zero-shot those zero-days, you still have to spend tens of thousands of dollars on the compute for mining them.
So giving public access to it in a few months, perhaps with some unusually aggressive refusal behavior around cybersecurity-flavored tasks, seems fine to me.
7Noosphere89
Re: "FWIW, I don't think Mythos is a qualitative step change as much as a quantitative one"
I think this is half-true, half-false. IMO the actually qualitative step change was finding a way to turn vulnerabilities into exploits, which neither Opus or Sonnet did, combined with Mythos doing the vulnerability and exploit analysis autonomously without knowing in advance about the vulnerabilities, and only very basic scaffolding was used. But yes, there were definitely quantitative changes as well.
On this:
[...]
This is cruxy, as my guess is that open-source would likely take at least a year to replicate the capabilities, and it's very plausible that it instead takes 2 years. One of the reasons for this is that Mythos's capabilities were probably enabled by just going back to pre-training, and compute will probably be given far more to frontier labs than to open-source, and a lot of open-source fundamentally tends to be compute-poor relative to frontier labs.
Re: this take you mentioned, I think my divergence from Jan Kuivelt is that I consider the methods used by Aisle to be sufficiently damning enough that I basically anti-updated from their claim, and in particular think that the fact that they had to disclose that their false-positive rates were at least much higher than Mythos likely has, combined with giving the vulnerability to the model and then asking them to find the vulnerability has basically trivialized the problem to the point of it being a useless evaluation, and the core thing Mythos did which they didn't test was whether it could find the vulnerability in the code without straight-up giving the individual pieces of the vulnerability to the model.
Overall, this has increased my confidence that open-source cannot reasonably replicate what Mythos did anytime soon.
4faul_sname
Turning vulnerabilities into exploits is one of those o-ring type tasks where you have to be above the skill floor for all subtasks to end up with a working exploit. Concretely, let's say a program is missing a bounds check on some stack-allocated variable, and as such you can write arbitrary data to the stack. You should assume that a sufficiently determined attacker can turn that into arbitrary code execution. However, turning a stack buffer overflow into arbitrary code execution is not trivial despite usually being possible. For example, an attacker might take the return-oriented programming approach. Whether Opus could construct a ROP chain would, I think, depend mostly on whether the training included lots of examples of using ropper or some similar tool, and whether the scaffolding made using that tool easy.
There are a bunch of individual components like that, such that even if Opus can often execute each of the steps of transforming a probable vulnerability into a working exploit, the chance of failure compounds and even relatively small improvements in across-the-board robustness can translate to step changes in outcome.
That said, I expect an appropriately-scaffolded Opus, maybe even Sonnet, could demonstrate that it was possible to do an out-of-bounds write to the stack for CVE-2026-4747 (the FreeBSD kerberos thingy). And each of the individual steps to translate that to a working exploit are things where an RL environment could be made to exist, if someone chose to make it exist, and could be open-sourced, if someone chose to do so. I expect (and hope) that nobody will do so, but I expect that the open-source community could replicate at least that fairly mechanical style of exploit generation within the next year if they chose to do so.
4ryan_greenblatt
I think this comment significantly underestimates how good Opus 4.6 is at exploitation given decent scaffolding and lots of inference compute.
4faul_sname
I find that surprising but expect you to know better than I do there. As such you'relikely right, especially if we use your definition of "lots of inference compute".
4A1987dM
Selling access to Mythos to the general public for however much they can find people willing to pay without explicitly mentioning its comp sec capabilities?
4faul_sname
If by "gain" you include things like "control of resources even when those resources aren't clearly tied back to Anthropic", stealing cryptocurrency.
4Karl Krueger
Discover vulnerabilities and sell them on the black market to people who are better positioned to use them to do crimes?
This seems like quite a large reputational risk for not all that much money. As far as I can tell the total demand for zero-days probably adds up to a couple billion dollars at current prices. Lowering the prices would increase demand some, but probably not enough to justify approximately any reputational risk to a company with an $800B+ valuation, especially one that's trying to go public.
As a sanity check, the NSO group made about $250M/year selling zero-days-as-a-service, and ran into substantial legal pressure.
It was the least-stupid evil use I could think of in five minutes. Cooperating with other major tech companies almost certainly beats criminally defecting against them; that's why the US tech economy doesn't look much like Snow Crash.
4Thane Ruthenis
My guess is that the returns on that would be either too small to risk the minor chance of discovery (random organized crime groups are not going to be able to pay tens of billions of dollars to them), or would involve dealing with non-US state actors in ways that would be very hard to cover up long-term (like, the three-letter agencies are going to eventually connect the dots between the new multibillions suddenly flowing to Anthropic and the new wave of zero-day exploits). Am I off regarding the money quantities involved and/or the discovery risks here?
3Myron Hedderson
I have not updated much based on "doing project Glasswing makes me update in favour of Anthropic being a better company than I expected."
However, I've updated a bit on the people within Anthropic all or nearly-all being better than I expected based on the fact that they have had a powerful hacking machine for a while and no catastrophes have occurred yet. "You can hack into anything" or "you could exfiltrate and sell this for billions" are powerful temptations for an amoral power-seeking individual who had been biding their time, and if there are any such individuals with access to Mythos, they have chosen not to make a move (at least as far as we can tell at this time), where I would expect an intelligent amoral person who planned to eventually abuse their position for personal gain to maybe decide this is the time to chance it, before a bunch of security holes get fixed. And an average but amoral person with no such plans, could still see these results and have fantasies of power which cause them to try abusing Mythos' abilities.
So, I've updated in favour of the quality of people at Anthropic, but not because of Glasswing specifically. More generally, they had access to a very powerful thing which it would be tempting to abuse, and no abuse has yet surfaced. It's like a kid having access to a marshmallow, and choosing not to eat the marshmallow. A wise and thoughtful person might think "marshmallows are bad for us, let's not eat it" or "there are greater returns to waiting", but if you give 10 kids 10 marshmallows, someone is going to eat one immediately, unless you're dealing with an exceptional group of kids.
But yeah, I don't see an obvious way for Anthropic as a company to benefit from exploiting a bunch of security vulnerabilities more than it will benefit by maintaining public goodwill towards the organization, and it does seem that whatever way people may be thinking feels pretty obvious to them, rather than being devious and convoluted. "Blackmail a b
3gbtw
You could try some sort of soft extortion of the potential targets of the attacks (i.e., demanding big money to reveal the vulnerabilities) in a way that's legal and fairly lucrative.
Current take on the implications of "GPT-4b micro": Very powerful, very cool, ~zero progress to AGI, ~zero existential risk. Cheers.
First, the gist of it appears to be:
OpenAI’s new model, called GPT-4b micro, was trained to suggest ways to re-engineer the protein factors to increase their function. According to OpenAI, researchers used the model’s suggestions to change two of the Yamanaka factors to be more than 50 times as effective—at least according to some preliminary measures.
The model was trained on examples of protein sequences from many species, as well as information on which proteins tend to interact with one another. [...] Once Retro scientists were given the model, they tried to steer it to suggest possible redesigns of the Yamanaka proteins. The prompting tactic used is similar to the “few-shot” method, in which a user queries a chatbot by providing a series of examples with answers, followed by an example for the bot to respond to.
Crucially, if the reporting is accurate, this is not an agent. The model did not engage in autonomous open-ended research. Rather, humans guessed that if a specific model is fine-tuned on a specific dataset, the gradient descent would chisel... (read more)
For those also curious, Yamanaka factors are specific genes that turn specialized cells (e.g. skin, hair) into induced pluripotent stem cells (iPSCs) which can turn into any other type of cell.
This is a big deal because you can generate lots of stem cells to make full organs[1] or reverse aging (maybe? they say you just turn the cell back younger, not all the way to stem cells).
You can also do better disease modeling/drug testing: if you get skin cells from someone w/ a genetic kidney disease, you can turn those cells into the iPSCs, then into kidney cells which will exhibit the same kidney disease because it's genetic. You can then better understand how the [kidney disease] develops and how various drugs affect it.
So, it's good to have ways to produce lots of these iPSCs. According to the article, SOTA was <1% of cells converted into iPSCs, whereas the GPT suggestions caused a 50x improvement to 33% of cells converted. That's quite huge!, so hopefully this result gets verified. I would guess this is true and still a big deal, but concurrent work got similar results.
Too bad about the tumors. Turns out iPSCs are so good at turning into other cells, that they can turn into infinite cells (ie cancer). iPSCs were used to fix spinal cord injuries (in mice) which looked successful for 112 days, but then a follow up study said [a different set of mice also w/ spinal iPSCs] resulted in tumors.
My current understanding is this is caused by the method of delivering these genes (ie the Yamanaka factors) through retrovirus which
[...]
which I'd guess this is the method the Retro Biosciences uses.
I also really loved the story of how Yamanaka discovered iPSCs:
[...]
1. ^
These organs would have the same genetics as the person who supplied the [skin/hair cells] so risk of rejection would be lower (I think)
You're right! Thanks
For Mice, up to 77%
[...]
For human cells, up to 9% (if I'm understanding this part correctly).
[...]
So seems like you can do wildly different depending on the setting (mice, humans, bovine, etc), and I don't know what the Retro folks were doing, but does make their result less impressive.
4TsviBT
(Still impressive and interesting of course, just not literally SOTA.)
4Logan Riggs
Thinking through it more, Sox2-17 (they changed 17 amino acids from Sox2 gene) was your linked paper's result, and Retro's was a modified version of factors Sox AND KLF. Would be cool if these two results are complementary.
Here's an argument for a capabilities plateau at the level of GPT-4 that I haven't seen discussed before. I'm interested in any holes anyone can spot in it.
Consider the following chain of logic:
The pretraining scaling laws only say that, even for a fixed training method, increasing the model's size and the amount of data you train on increases the model's capabilities – as measured by loss, performance on benchmarks, and the intuitive sense of how generally smart a model is.
Nothing says that increasing a model's parameter-count and the amount of compute spent on training it is the only way to increase its capabilities. If you have two training methods A and B, it's possible that the B-trained X-sized model matches the performance of the A-trained 10X-sized model.
Empirical evidence: Sonnet 3.5 (at least the not-new one), Qwen-2.5-70B, and Llama 3-72B all have 70-ish billion parameters, i. e., less than GPT-3. Yet, their performance is at least on par with that of GPT-4 circa early 2023.
Therefore, it is possible to "jump up" a tier of capabilities, by any reasonable metric, using a fixed model size but improving the training methods.
The latest set of GPT-4-sized models (Opus 3.5, Ori
Given some amount of compute, a compute optimal model tries to get the best perplexity out of it when training on a given dataset, by choosing model size, amount of data, and architecture. An algorithmic improvement in pretraining enables getting the same perplexity by training on data from the same dataset with less compute, achieving better compute efficiency (measured as its compute multiplier).
Many models aren't trained compute optimally, they are instead overtrained (the model is smaller, trained on more data). This looks impressive, since a smaller model is now much better, but this is not an improvement in compute efficiency, doesn't in any way indicate that it became possible to train a better compute optimal model with a given amount of compute. The data and post-training also recently got better, which creates the illusion of algorithmic progress in pretraining, but their effect is bounded (while RL doesn't take off), doesn't get better according to pretraining scaling laws once much more data becomes necessary. There is enough data until 2026-2028, but not enough good data.
I don't think the cumulative compute multiplier since GPT-4 is that high, I'm guessing 3x, except p... (read more)
Coming back to this in the wake of DeepSeek r1...
[...]
How did DeepSeek accidentally happen to invest precisely the amount of compute into V3 and r1 that would get them into the capability region of GPT-4/o1, despite using training methods that clearly have wildly different returns on compute investment?
Like, GPT-4 was supposedly trained for $100 million, and V3 for $5.5 million. Yet, they're roughly at the same level. That should be very surprising. Investing a very different amount of money into V3's training should've resulted in it either massively underperforming GPT-4, or massively overperforming, not landing precisely in its neighbourhood!
Consider this graph. If we find some training method A, and discover that investing $100 million in it lands us at just above "dumb human", and then find some other method B with a very different ROI, and invest $5.5 million in it, the last thing we should expect is to again land near "dumb human".
Or consider this trivial toy model: You have two linear functions, f(x) = Ax and g(x) = Bx, where x is the compute invested, output is the intelligence of the model, and f and g are different training methods. You pick some x effectively at random (whatever amount of money you happened to have lying around), plug it into f, and get, say, 120. Then you pick a different random value of x, plug it into g, and get... 120 again. Despite the fact that the multipliers A and B are likely very different, and you used very different x-values as well. How come?
The explanations that come to mind are:
* It actually is just that much of a freaky coincidence.
* DeepSeek have a superintelligent GPT-6 equivalent that they trained for $10 million in their basement, and V3/r1 are just flexes that they specifically engineered to match GPT-4-ish level.
* DeepSeek directly trained on GPT-4 outputs, effectively just distilling GPT-4 into their model, hence the anchoring.
* DeepSeek kept investing and tinkering until getting to GPT-4ish le
5Vladimir_Nesov
Selection effect. If DeepSeek-V2.5 was this good, we would be talking about it instead.
[...]
Original GPT-4 is 2e25 FLOPs and compute optimal, V3 is about 5e24 FLOPs and overtrained (400 tokens/parameter, about 10x-20x), so a compute optimal model with the same architecture would only need about 3e24 FLOPs of raw compute[1]. Original GPT-4 was trained in 2022 on A100s and needed a lot of them, while in 2024 it could be trained on 8K H100s in BF16. DeepSeek-V3 is trained in FP8, doubling the FLOP/s, so the FLOPs of original GPT-4 could be produced in FP8 by mere 4K H100s. DeepSeek-V3 was trained on 2K H800s, whose performance is about that of 1.5K H100s. So the cost only has to differ by about 3x, not 20x, when comparing a compute optimal variant of DeepSeek-V3 with original GPT-4, using the same hardware and training with the same floating point precision.
The relevant comparison is with GPT-4o though, not original GPT-4. Since GPT-4o was trained in late 2023 or early 2024, there were 30K H100s clusters around, which makes 8e25 FLOPs of raw compute plausible (assuming it's in BF16). It might be overtrained, so make that 4e25 FLOPs for a compute optimal model with the same architecture. Thus when comparing architectures alone, GPT-4o probably uses about 15x more compute than DeepSeek-V3.
[...]
Returns on compute are logarithmic though, advantage of a $150 billion training system over a $150 million one is merely twice that of $150 billion over $5 billion or $5 billion over $150 million. Restrictions on access to compute can only be overcome with 30x compute multipliers, and at least DeepSeek-V3 is going to be reproduced using the big compute of US training systems shortly, so that advantage is already gone.
----------------------------------------
1. That is, raw utilized compute. I'm assuming the same compute utilization for all models. ↩︎
4Noosphere89
I buy that 1 and 4 is the case, combined with Deepseek probably being satisfied that GPT-4-level models were achieved.
Edit: I did not mean to imply that GPT-4ish neighbourhood is where LLM pretraining plateaus at all, @Thane Ruthenis.
2Thane Ruthenis
Thanks!
[...]
You're more fluent in the scaling laws than me: is there an easy way to roughly estimate how much compute would've been needed to train a model as capable as GPT-3 if it were done Chinchilla-optimally + with MoEs? That is: what's the actual effective "scale" of GPT-3?
(Training GPT-3 reportedly took 3e23 FLOPS, and GPT-4 2e25 FLOPS. Naively, the scale-up factor is 67x. But if GPT-3's level is attainable using less compute, the effective scale-up is bigger. I'm wondering how much bigger.)
7Vladimir_Nesov
IsoFLOP curves for dependence of perplexity on log-data seem mostly symmetric (as in Figure 2 of Llama 3 report), so overtraining by 10x probably has about the same effect as undertraining by 10x. Starting with a compute optimal model, increasing its data 10x while decreasing its active parameters 3x (making it 30x overtrained, using 3x more compute) preserves perplexity (see Figure 1).
GPT-3 is a 3e23 FLOPs dense transformer with 175B parameters trained for 300B tokens (see Table D.1). If Chinchilla's compute optimal 20 tokens/parameter is approximately correct for GPT-3, it's 10x undertrained. Interpolating from the above 30x overtraining example, a compute optimal model needs about 1.5e23 FLOPs to get the same perplexity.
(The effect from undertraining of GPT-3 turns out to be quite small, reducing effective compute by only 2x. Probably wasn't worth mentioning compared to everything else about it that's different from GPT-4.)
in retrospect, we know from chinchilla that gpt3 allocated its compute too much to parameters as opposed to training tokens. so it's not surprising that models since then are smaller. model size is a less fundamental measure of model cost than pretraining compute. from here on i'm going to assume that whenever you say size you meant to say compute.
obviously it is possible to train better models using the same amount of compute. one way to see this is that it is definitely possible to train worse models with the same compute, and it is implausible that the current model production methodology is the optimal one.
it is unknown how much compute the latest models were trained with, and therefore what compute efficiency win they obtain over gpt4. it is unknown how much more effective compute gpt4 used than gpt3. we can't really make strong assumptions using public information about what kinds of compute efficiency improvements have been discovered by various labs at different points in time. therefore, we can't really make any strong conclusions about whether the current models are not that much better than gpt4 because of (a) a shortage of compute, (b) a shortage of compute efficiency improvements, or (c) a diminishing return of capability wrt effective compute.
One possible answer is that we are in what one might call an "unhobbling overhang."
Aschenbrenner uses the term "unhobbling" for changes that make existing model capabilities possible (or easier) for users to reliably access in practice.
His presentation emphasizes the role of unhobbling as yet another factor growing the stock of (practically accessible) capabilities over time. IIUC, he argues that better/bigger pretraining would produce such growth (to some extent) even without more work on unhobbling, but in fact we're also getting better at unhobbling over time, which leads to even more growth.
That is, Aschenbrenner treats pretraining improvements and unhobbling as economic substitutes: you can improve "practically accessible capabilities" to the same extent by doing more of either one even in the absence of the other, and if you do both at once that's even better.
However, one could also view the pair more like economic complements. Under this view, when you pretrain a model at "the next tier up," you also need to do novel unhobbling research to "bring out" the new capabilities unlocked at that tier. If you only scale up, while re-using the unhobbling tech of yesteryear, most of t... (read more)
That seems maybe right, in that I don't see holes in your logic on LLM progression to date, off the top of my head.
It also lines up with a speculation I've always had. In theory LLMs are predictors, but in practice, are they pretty much imitators? If you're imitating human language, you're capped at reproducing human verbal intelligence (other modalities are not reproducing human thought so not capped; but they don't contribute as much in practice without imitating human thought).
I've always suspected LLMs will plateau. Unfortunately I see plenty of routes to improving using runtime compute/CoT and continuous learning. Those are central to human intelligence.
LLMs already have slightly-greater-than-human system 1 verbal intelligence, leaving some gaps where humans rely on other systems (e.g., visual imagination for tasks like tracking how many cars I have or tic-tac-toe). As we reproduce the systems that give humans system 2 abilities by skillfully iterating system 1, as o1 has started to do, they'll be noticeably smarter than humans.
The difficulty of finding new routes forward in this scenario would produce a very slow takeoff. That might be a big benefit for alignment.
2Thane Ruthenis
Yep, I think that's basically the case.
@nostalgebraist makes an excellent point that eliciting any latent superhuman capabilities which bigger models might have is an art of its own, and that "just train chatbots" doesn't exactly cut it, for this task. Maybe that's where some additional capabilities progress might still come from.
But the AI industry (both AGI labs and the menagerie of startups and open-source enthusiasts) has so far been either unwilling or unable to move past the chatbot paradigm.
(Also, I would tentatively guess that this type of progress is not existentially threatening. It'd yield us a bunch of nice software tools, not a lightcone-eating monstrosity.)
4Seth Herd
I agree that chatbot progress is probably not existentially threatening. But it's all too short a leap to making chatbots power general agents. The labs have claimed to be willing and enthusiastic about moving to an agent paradigm. And I'm afraid that a proliferation of even weakly superhuman or even roughly parahuman agents could be existentially threatening.
I spell out my logic for how short the leap might be from current chatbots to takeover-capable AGI agents in my argument for short timelines being quite possible. I do think we've still got a good shot of aligning that type of LLM agent AGI since it's a nearly best-case scenario. RL even in o1 is really mostly used for making it accurately follow instructions, which is at least roughly the ideal alignment goal of Corrigibility as Singular Target. Even if we lose faithful chain of thought and orgs don't take alignment that seriously, I think those advantages of not really being a maximizer and having corrigibility might win out.
That in combination with the slower takeoff make me tempted to believe its actually a good thing if we forge forward, even though I'm not at all confident that this will actually get us aligned AGI or good outcomes. I just don't see a better realistic path.
5green_leaf
One obvious hole would be that capabilities did not, in fact, plateau at the level of GPT-4.
8Seth Herd
I thought the argument was that progress has slowed down immensely. The softer form of this argument is that LLMs won't plateau but progress will slow to such a crawl that other methods will surpass them. The arrival of o1 and o3 says this has already happened, at least in limited domains - and hybrid training methods and perhaps hybrid systems probably will proceed to surpass base LLMs in all domains.
3Thane Ruthenis
There's been incremental improvement and various quality-of-life features like more pleasant chatbot personas, tool use, multimodality, gradually better math/programming performance that make the models useful for gradually bigger demographics, et cetera.
But it's all incremental, no jumps like 2-to-3 or 3-to-4.
4green_leaf
I see, thanks. Just to make sure I'm understanding you correctly, are you excluding the reasoning models, or are you saying there was no jump from GPT-4 to o3? (At first I thought you were excluding them in this comment, until I noticed the "gradually better math/programming performance.")
6Thane Ruthenis
I think GPT-4 to o3 represent non-incremental narrow progress, but only, at best, incremental general progress.
(It's possible that o3 does "unlock" transfer learning, or that o4 will do that, etc., but we've seen no indication of that so far.)
For what it's worth, this is in line with my expectations for what LLMs should be capable of and it doesn't update me much towards their AGI-completeness. (Though it's at the more bullish end of past!me's predictions.) Receipts-wise, I'm not sure I laid it out publicly anywhere, but here's an excerpt from a message I'd sent to @habryka in January 2025:
[T]he worse end of the scenarios I'm imagining is...
The o-series of models potentially doesn't scale to superhuman programmers-in-general, but does scale to superhuman hackers: because "find a way to make this abstraction leak" is precisely the kind of programming task that is well-posed/isomorphic to a rigorous-math task ("find a flaw in this proof/this statement of tautology").
I expect that ~all of the components of the current web stack contain countless vulnerabilities that are relatively easy to discover, and which aren't exploited simply because finding them would require a talented programmer to parse vast mountains of code (application code, and the code of its dependencies, and the dependencies of dependencies, and any cross-interactions between them...).
This may ultimately be an edge for defense not offense. The status quo is that anyone with enough resources and enough programmers to throw at the task could have an exploit in whatever they wanted.
If the 'most capable hacker on earth' is an open model, it means that you will be able to reverse engineer your own equipment, build better rules for detection, actually do analysis of low level logs that would normally be too time consuming, and attackers would have no confidence that their exploits stay secret.
Compsci theory (weird machines) tells us that exploits exist in any sufficiently complicated codebase.
Targets who are too lazy to adopt technical measures like these are likely wide open today, so the increased vulnerability is irrelevant.
So, Project Stargate. Is it real, or is it another "Sam Altman wants $7 trillion"? Some points:
The USG invested nothing in it. Some news outlets are being misleading about this. Trump just stood next to them and looked pretty, maybe indicated he'd cut some red tape. It is not an "AI Manhattan Project", at least, as of now.
Elon Musk claims that they don't have the money and that SoftBank (stated to have "financial responsibility" in the announcement) has less than $10 billion secured. If true, while this doesn't mean they can't secure an order of magnitude more by tomorrow, this does directly clash with "deploying $100 billion immediately" statement.
But Sam Altman counters that Musk's statement is "wrong", as Musk "surely knows".
I... don't know which claim I distrust more. Hm, I'd say Altman feeling the need to "correct the narrative" here, instead of just ignoring Musk, seems like a sign of weakness? He doesn't seem like the type to naturally get into petty squabbles like this, otherwise.
(And why, yes, this is how an interaction between two Serious People building world-changing existentially dangerous megaprojects looks like. Apparently.)
Here is what I posted on "Quotes from the Stargate Press Conference":
On Stargate as a whole:
This is a restatement with a somewhat different org structure of the prior OpenAI/Microsoft data center investment/partnership, announced early last year (admittedly for $100b).
Elon Musk states they do not have anywhere near the 500 billion pledged actually secured:
I do take this as somewhat reasonable, given the partners involved just barely have $125 billion available to invest like this on a short timeline.
Microsoft has around 78 billion cash on hand at a market cap of around 3.2 trillion.
Softbank has 32 billion dollars cash on hand, with a total market cap of 87 billion.
Oracle has around 12 billion cash on hand, with a market cap of around 500 billion.
OpenAI has raised a total of 18 billion, at a valuation of 160 billion.
Further, OpenAI and Microsoft seem to be distancing themselves somewhat - initially this was just an OpenAI/Microsoft project, and now it involves two others and Microsoft just put out a release saying "This new agreement also includes changes to the exclusivity on new capacity, moving to a model where Microsoft has a right of first refusal (ROFR)."
Overall, I think that the new Stargate numbers published may (call it 40%) be true, but I also think there is a decent chance this is new administration trump-esque propoganda/bluster (call it 45%), and little change from the prior expected path of datacenter investment (which I do believe is unintentional AINotKillEveryone-ism in the near future).
Edit: Satya Nadella was just asked about how funding looks for stargate, and said "Microsoft is good for investing 80b". This 80b number is the same number Microsoft has been saying repeatedly.
5Thane Ruthenis
I think it's definitely bluster, the question is how much of a done deal it is to turn this bluster into at least $100 billion.
I don't this this changes the prior expected path of datacenter investment at all. It's precisely how the expected path was going to look like, the only change is how relatively high-profile/flashy this is being. (Like, if they invest $30-100 billion into the next generation of pretrained models in 2025-2026, and that generation fails, they ain't seeing the remaining $400 billion no matter what they're promising now. Next generation makes or breaks the investment into the subsequent one, just as was expected before this.)
[...]
He does very explicitly say "I am going to spend 80 billion dollars building Azure". Which I think has nothing to do with Stargate.
(I think the overall vibe he gives off is "I don't care about this Stargate thing, I'm going to scale my data centers and that's that". I don't put much stock into this vibe, but it does fit with OpenAI/Microsoft being on the outs.)
Here's something that confuses me about o1/o3. Why was the progress there so sluggish?
My current understanding is that they're just LLMs trained with RL to solve math/programming tasks correctly, hooked up to some theorem-verifier and/or an array of task-specific unit tests to provide ground-truth reward signals. There are no sophisticated architectural tweaks, not runtime-MCTS or A* search, nothing clever.
Why was this not trained back in, like, 2022 or at least early 2023; tested on GPT-3/3.5 and then default-packaged into GPT-4 alongside RLHF? If OpenAI was too busy, why was this not done by any competitors, at decent scale? (I'm sure there are tons of research papers trying it at smaller scales.)
The idea is obvious; doubly obvious if you've already thought of RLHF; triply obvious after "let's think step-by-step" went viral. In fact, I'm pretty sure I've seen "what if RL on CoTs?" discussed countless times in 2022-2023 (sometimes in horrified whispers regarding what the AGI labs might be getting up to).
The mangled hidden CoT and the associated greater inference-time cost is superfluous. DeepSeek r1/QwQ/Gemini Flash Thinking have perfectly legible CoTs which would be fine to prese... (read more)
While I don't have specifics either, my impression of ML research is that it's a lot of work to get a novel idea working, even if the idea is simple. If you're trying to implement your own idea, you'll be banging your head against the wall for weeks or months wondering why your loss is worse than the baseline. If you try to replicate a promising-sounding paper, you'll bang your head against the wall as your loss is worse than the baseline. It's hard to tell if you made a subtle error in your implementation or if the idea simply doesn't work for reasons you don't understand because ML has little in the way of theoretical backing. Even when it works it won't be optimized, so you need engineers to improve the performance and make it stable when training at scale. If you want to ship a working product quickly then it's best to choose what's tried and true.
My latest experience with trying to use Opus 4.1 to vibe-code[1]:
Context: I wanted a few minor helper apps[2] that I didn't think worth the time to code manually, and which I used as an opportunity to test LLMs' current skill level (not expecting it to actually save much development time; yay multi-purpose projects).
Very mixed results. My experience is that you need to give it a very short leash. As long as you do the job of factorizing the problem, and then feed it small steps to execute one by one, it tends to zero-shot them. You do need to manually check that the implementational choices are what you intended, and you'll want to start by building some (barebones) UI to make this time-efficient, but this mostly works. It's also pretty time-consuming on your part, both the upfront cost of factorizing and the directing afterwards.
If you instead give it a long leash, it produces overly complicated messes (like, 3x the lines of code needed?) which don't initially work, and which it iteratively bug-fixes into the ground. The code is then also liable to contain foundation-level implementation choices that go directly against the spec; if that is pointed out, the LLM wrecks everyth... (read more)
I use Claude for some hobby coding at home. I find it very useful in the following situations:
* I am too lazy to study the API, just give me the code that loads the image from the file or whatever
* how would you do this? suggest a few alternatives (often its preferred one is not the one I choose)
* tell me more about this topic
So it saves me a lot of time reading the documentation, and sometimes it suggests a cool trick I probably wouldn't find otherwise. (For example, in Python list comprehension, you can create a "local variable" by iterating through a list containing one item.)
On the other hand, if I let Claude write code, it is often much longer code that when I think about the problem, and only let Claude give me short pieces of code.
Maybe I am using it the wrong way. But that too is a kind of risk: having Claude conveniently write the code for me encourages me to produce a lot of code because it is cheap. But as Dijkstra famously said, it is not "lines produced" but "lines spent".
4mruwnik
I get the feeling that it can remove blockers. Your effectiveness (however you want to define that) at programming is like Liebig's barrel, or maybe a better example would be a road with a bunch of big rocks and rubble on it - you have to keep removing things to proceed. The more experienced you are, the better at removing obstacles, or even better, avoiding them. LLMs are good at giving you more options for how to approach problems. Often their suggestion is not the best, but it's better than nothing and will suffice to move on.
They do like making complex stuff, though... I wonder if that's because there's a lot more bad code that looks good than just good code?
3Thane Ruthenis
Yeah, they can be used as a way to get out of procrastination/breach ugh fields/move past the generalized writer's block, by giving you the ability to quickly and non-effortfully hammer out a badly-done first draft of the thing.
[...]
Wild guess: it's because AGI labs (and Anthropic in particular) are currently trying to train them to be able to autonomously spin up large, complex codebases, so much of their post-training consists of training episodes where they're required to do that. So they end up biased towards architectural choices suitable for complex applications instead of small ones.
Like, given free reign, they seem eager to build broad foundations on which lots of other features could later be implemented (n = 2), even if you gave them the full spec and it only involves 1-3 features.
This would actually be kind of good – building a good foundation which won't need refactoring if you'll end up fancying a new feature! – except they're, uh, not actually good at building those foundations.
Which, if my guess is correct, is because their post-training always pushes them to the edge of, and then slightly past, their abilities. Like, suppose the post-training uses rejection sampling (training on episodes in which they succeeded), and it involves a curriculum spanning everything from small apps to "build an OS". If so, much like in METR's studies, there'll be some point of program complexity where they only succeed 50% of the time (or less). But they're still going to be trained on those 50% successful trajectories. So they'll end up "overambitious"/"overconfident", trying to do things they're not quite reliable at yet.
Or maybe not; wild guess, as I said.
2Viliam
Maybe the sufficient reason is that LLMs learn both on the bad code and the good code. And on the old code, which was written before some powerful features were introduced to the language or the libraries, so it doesn't use them. Also, they learn on automatically generated code, if someone commits that to the repository.
2Thane Ruthenis
Yup, it certainly seems useful if you (a) want to cobble something together using tools you don't know (and which is either very simple, or easy to "visually" bug-test, or which you don't need to work extremely reliably), (b) want to learn some tools you don't know, so you use the LLM as a chat-with-docs interface.
4mruwnik
I did something similar a couple of months ago, asking it to make me a memory system (Opus 4 and o1-pro for design, mainly sonnet 4 for implementation). Initially it was massively overengineered, with a bunch of unneeded components. This was with Cursor, which changes things a bit - Claude Code tends to be much better at planning things first.
The results were very similar - handholding works, looking away results in big messes, revert rather than fix (unless you know how to fix it), and eventually I got something that does what I want, albeit more complex than I would have made by myself.
AIME 2025 part I was conducted yesterday, and the scores of some language models are available here: https://matharena.ai thanks to @mbalunovic, @ni_jovanovic et al.
I have to say I was impressed, as I predicted the smaller distilled models would crash and burn, but they actually scored at a reasonable 25-50%.
That was surprising to me! Since these are new problems, not seen during training, right? I expected smaller models to barely score above 0%. It's really hard to believe that a 1.5B model can solve pre-math olympiad problems when it can't multiply 3-digit numbers. I was wrong, I guess.
I then used openai's Deep Research to see if similar problems to those in AIME 2025 exist on the internet. And guess what? An identical problem to Q1 of AIME 2025 exists on Quora:
To be fair, non-reasoning models do much worse on these questions, even when it's likely that the same training data has already been given to GPT-4.
Now, I could believe that RL is more or less working as an elicitation method, which plausibly explains the results, though still it's interesting to see why they get much better scores, even with very similar training data.
5Thane Ruthenis
I do think RL works "as intended" to some extent, teaching models some actual reasoning skills, much like SSL works "as intended" to some extent, chiseling-in some generalizable knowledge. The question is to what extent it's one or the other.
So what's up with how AGI labs use mathematicians' user data?
Here's what I currently tentatively believe:
The current AI paradigm is in principle capable of autonomously (truly autonomously, without upcoming caveats) generating some novel math results of the sort that would be difficult for humans to produce. There is no reason to believe the basic premise of RL-on-math wouldn't work.
OpenAI does not deliberately breach user privacy in ways they don't disclose in order to steal mathematicians' in-progress work and then present it as their own. In particular, they did not manually access Levent and Tristan's NS-related sessions and did not prompt their new model with them.
OpenAI does use user data for training, in ways they largely disclose. That user data likely includes mathematicians' work-in-progress results.
(3) may lead to (1) being overestimated: some of the latest autonomous AI results may be "seeded" by pre-publication results mathematicians inadvertently fed OpenAI. In all probability, OpenAI uses automated pipelines for processing and organizing user data into training datasets, which means no-one really knows what results they may or may not be training on (see OpenAI basic
At a minimum, it seems like the lack of clarity/insight into the full process of certain results got produced makes it challenging to interpret model outputs. I commented here raising a similar point and referencing the OpenAI NS case.
3Zach Paris
I agree and would personally find it surprising if they do filter out in-progress work. Not necessarily out of malicious intent but expert level conversations are likely the best training data they have available and is a continually growing source of real world application data. If anything I would expect them to upsample these individuals in training.
Sooo, apparently OpenAI's mysterious breakthrough technique for generalizing RL to hard-to-verify domains that scored them IMO gold is just... "use the LLM as a judge"? Sources: the main one is paywalled, but this seems to capture the main data, and you can also search for various crumbs here and here.
The technical details of how exactly the universal verifier works aren’t yet clear. Essentially, it involves tasking an LLM with the job of checking and grading another model’s answers by using various sources to research them.
My understanding is that they approximate an oracle verifier by an LLM with more compute and access to more information and tools, then train the model to be accurate by this approximate-oracle's lights.
Now, it's possible that the journalists are completely misinterpreting the thing they're reporting on, or that it's all some galaxy-brained OpenAI op to mislead the competition. It's also possible that there's some incredibly clever trick for making it work much better than how it sounds like it'd work.
But if that's indeed the accurate description of the underlying reality, that's... kind of underwhelming. I'm curious how far this can scale, but I'm not feeling v... (read more)
One point of information against the "journalists are completely misinterpreting the thing they're reporting on" view is that the one of the co-authors is Rocket Drew, who previously worked as a Research Manager at MATS.
But I'll definitely be interested to follow this space more.
3ProverEstimator
Hard to tell from the sources, but it sounds almost like prover-estimator debate. The estimator is assigning a number to how likely it is that a subclaim for a proof is correct, and this approach might also work for less verifiable domains since a human oracle is used at the last round of the debate. The main problem seems to be that it may not scale if it requires human feedback.
Edit: I've played with the numbers a bit more, and on reflection, I'm inclined to partially unroll this update. o3 doesn't break the trendline as much as I'd thought, and in fact, it's basically on-trend if we remove the GPT-2 and GPT-3 data-points (which I consider particularly dubious).
Regarding METR's agency-horizon benchmark:
I still don't like anchoring stuff to calendar dates, and I think the o3/o4-mini datapoints perfectly show why.
It would be one thing if they did fit into the pattern. If, by some divine will controlling the course of our world's history, OpenAI's semi-arbitrary decision about when to allow METR's researchers to benchmark o3 just so happened to coincide with the 2x/7-month model. But it didn't: o3 massively overshot that model.[1]
Imagine a counterfactual in which METR's agency-horizon model existed back in December, and OpenAI invited them for safety testing/benchmarking then, four months sooner. How different would the inferred agency-horizing scaling laws have been, how much faster the extrapolated progress? Let's run it:
o1 was announced September 12th, o3 was announced December 19th, 98 days apart.
o1 scored at ~40 minutes, o3 at ~1.5 hours, a 2.25x'ing.
I agree that anchoring stuff to release dates isn't perfect because the underlying variable of "how long does it take until a model is released" is variable, but I think is variability is sufficiently low that it doesn't cause that much of an issue in practice. The trend is only going to be very solid over multiple model releases and it won't reliably time things to within 6 months, but that seems fine to me.
I agree that if you add one outlier data point and then trend extrapolate between just the last two data points, you'll be in trouble, but fortunately, you can just not do this and instead use more than 2 data points.
This also means that I think people shouldn't update that much on the individual o3 data point in either direction. Let's see where things go for the next few model releases.
That one seems to work more reliably, perhaps because it became the metric the industry aims for.
[...]
My issue here is that there wasn't that much variance in the performance of all preceding models they benchmarked: from GPT-2 to Sonnet 3.7, they seem to almost perfectly fall on the straight line. Then, the very first advancement of the frontier after the trend-model is released is an outlier. That suggests an overfit model.
I do agree that it might just be a coincidental outlier and that we should wait and see whether the pattern recovers with subsequent model releases. But this is suspicious enough I feel compelled to make my prediction now.
The dates used in our regression are the dates models were publicly released, not the dates we benchmarked them. If we use the latter dates, or the dates they were announced, I agree they would be more arbitrary.
Also, there is lots of noise in a time horizon measurement and it only displays any sort of pattern because we measured over many orders of magnitude and years. It's not very meaningful to extrapolate from just 2 data points; there are many reasons one datapoint could randomly change by a couple of months or factor of 2 in time horizon.
Release schedules could be altered
A model could be overfit to our dataset
One model could play less well with our elicitation/scaffolding
One company could be barely at the frontier, and release a slightly-better model right before the leading company releases a much-better model.
All of these factors are averaged out if you look at more than 2 models. So I prefer to see each model as evidence of whether the trend is accelerating or slowing down over the last 1-2 years, rather than an individual model being very meaningful.
Fair, also see my un-update edit.
Have you considered removing GPT-2 and GPT-3 from your models, and seeing what happens? As I'd previously complained, I don't think they can be part of any underlying pattern (due to the distribution shift in the AI industry after ChatGPT/GPT-3.5). And indeed: removing them seems to produce a much cleaner trend with a ~130-day doubling.
3brendanhalstead
For what it's worth, the model showcased in December (then called o3) seems to be completely different from the model that METR benchmarked (now called o3).
Are our social systems miscalibrated in treating AI capability researchers as stupid (high status), instead of stupid (low status)?
(Disclaimer: This may be a bad post born out of a desire to vent, i. e., a crashout.)
Imagine a fictional mad scientist messing with forces beyond their understanding, who then loses control of them. In some sense, the audience is of course meant to read their actions as a mistake, as something caused by reasoning flaws. But as far as cognitive deficiencies go, mad scientists' flaws are respectable. They're foolishly reckless, lacking in wisdom, overoptimistic, overly ambitious, their reach exceeds their grasp... which aren't positive qualities, per se, but they still paint the image of someone bold, dangerous, powerful. High-status.
Now consider a low-intelligence criminal with impulse-control issues, the sorts described here. They can't do basic cost-benefit analyses, and as the result, they live in largely self-inflicted misery. Whenever they find a well-paying job, they immediately start engaging in petty theft, and promptly lose it. Whenever they get caught doing something bad, they try to cover it up using blatantly transparent lies than only make t... (read more)
You wouldn't expect that, by looking at how many PhDs and money they have – and yet.
Their mad-scientist credibility doesn't come from the Ph.D.s and the money. (Jason Arday had a Ph.D.; Paris Hilton has money.) The mad-scientist credibility comes from developing the most exciting technological advancement of the century, and the money comes from the technology being fantastically economically useful—an all-in-one marvel that answers your questions, summarizes your documents, writes your code, and generates images, all for the low, low price of $20 a month. That's high-status according to the same standards that western Society has judged these things for generations.
It's not a trivial achievement. I don't think I'm stupid, exactly—I worked as a software engineer for eight years; I have a math degree; I write some blog posts about philosophy that some people like—but I'm not sure I could have done it. If I tried to claim that I could, but that I didn't for the good of the world because I'm so much smarter than them, I think it would make sense for people to be suspicious that something other than the good of the world was at stake in me saying that.
Not confident about this, but I tend to think that this is less of an issue of something like "poor impulse control"[1] and more that environments like this one teem with the same sort of collective insanity as many other mundane human collectives: many political parties, many religious groups (not just "cults"), fraternities, sports fans, some friend groups etc. There you have stuff like:
* perception of social reality immensely constraining what you can think;
* people often have some awareness of that, but even those people often under-estimate the effect size
* deference cascades;
* inertia of collective action powered by a sort of identity;
* some expected "pain" associated with the possibility of disinvestment from the company.[2]
On top of all that, you have evaporative cooling. Most of the sane ones have left.
Of course, I'm not saying that any of this is "fine". But I expect that this will make it much harder to shift the public perception in the direction you're outlining here, because it seems to me that it would be tantamount to awakening to the mundane insanity of so many human collectives.
On the other hand, insofar as most people typically don't try to work on making their views on an issue coherent (unless they're kind of exogenously forced to?), maybe it's not as doomed? But what I'm describing seems like a track record/baseline reason for this to be very difficult.
1. ^
I mean, you can, not-meaninglessly, generalize "poor impulse control" to being unable to properly cohere your short-term objectives with your long-term objectives or something like that. But, like, the point is that most humans can't or don't try to do that.
2. ^
IDK how big a part of one's social circle other lab employees are; something something status, including downstream from lucrative payment? I would guess that the biggest pain factor is some psychological sunk-costs-shaped barrier, but IDK
On the topic of o1's recent release: wasn't Claude Sonnet 3.5 (the subscription version at least, maybe not the API version) already using hidden CoT? That's the impression I got from it, at least.
The responses don't seem to be produced in constant time. It sometimes literally displays a "thinking deeply" message which accompanies a unusually delayed response. Other times, the following pattern would play out:
I pose it some analysis problem, with a yes/no answer.
It instantly produces a generic response like "let's evaluate your arguments".
There's a 1-2 second delay.
Then it continues, producing a response that starts with "yes" or "no", then outlines the reasoning justifying that yes/no.
That last point is particularly suspicious. As we all know, the power of "let's think step by step" is that LLMs don't commit to their knee-jerk instinctive responses, instead properly thinking through the problem using additional inference compute. Claude Sonnet 3.5 is the previous out-of-the-box SoTA model, competently designed and fine-tuned. So it'd be strange if it were trained to sabotage its own CoTs by "writing down the bottom line first" like this, instead of being taught not to commit to a ... (read more)
My model was that Claude Sonnet has tool access and sometimes does some tool-usage behind the scenes (which later gets revealed to the user), but that it wasn't having a whole CoT behind the scenes, but I might be wrong.
4quetzal_rainbow
I think you heard about this thread (I didn't try to replicate it myself).
2Thane Ruthenis
Thanks, that seems relevant! Relatedly, the system prompt indeed explicitly instructs it to use "<antThinking>" tags when creating artefacts. It'd make sense if it's also using these tags to hide parts of its CoT.
It's been four days and AGI labs haven't announced resolving even one more Millennium Problem. There's been an OpenAI comment to the NYT about "making substantial progress on" another one, some rumors, and then nothing.
Huge bear signal.
(I'm almost not joking: if they don't crack open more world-class unresolved math problems soon, that would be a slight update downward regarding AI capabilities for me. I currently think they did resolve more but are sitting on them because blindly rushing them out may be PR-negative on the margins: going 1 -> 2 on the M... (read more)
Here's a potential interpretation of the market's apparent strange reaction to DeepSeek-R1 (shorting Nvidia).
I don't fully endorse this explanation, and the shorting may or may not have actually been due to Trump's tariffs + insider trading, rather than DeepSeek-R1. But I see a world in which reacting this way to R1 arguably makes sense, and I don't think it's an altogether implausible world.
If I recall correctly, the amount of money globally spent on inference dwarfs the amount of money spent on training. Most economic entities are not AGI labs training n... (read more)
The bet that "makes sense" is that quality of Claude 3.6 Sonnet, GPT-4o and DeepSeek-V3 is the best that we're going to get in the next 2-3 years, and DeepSeek-V3 gets it much cheaper (less active parameters, smaller margins from open weights), also "suggesting" that quality is compute-insensitive in a large range, so there is no benefit from more compute per token.
But if quality instead improves soon (including by training DeepSeek-V3 architecture on GPT-4o compute), and that improvement either makes it necessary to use more compute per token, or motivates using inference for more tokens even with models that have the same active parameter count (as in Jevons paradox), that argument doesn't work. Also, the ceiling of quality at the possible scaling slowdown point depends on efficiency of training (compute multiplier) applied to the largest training system that the AI economics will support (maybe 5-15 GW without almost-AGI), and improved efficiency of DeepSeek-V3 raises that ceiling.
If o3 is based on GPT-4o, there is a reasoning model based on GPT-4.5 that's better. If o3 is based on GPT-4.5 (and so the reason it's still not out is that they are waiting for Blackwells to inference it at a reasonable speed and cost), then it was a hasty job just after the base model for GPT-4.5 was pretrained, and so by now they have something much better. Either way, there is some sort of "o4", but it's probably a bad look to announce it before releasing the already-announced o3.
Some thoughts on protecting against LLM steganography.
tl;dr: I suspect the Paraphraser idea is near-completely ineffectual as you scale the capabilities, both for scheming and for general CoT interpretability.
In the reasoning-as-communication framework, the amount of information a fixed-length message/CoT can transfer is upper-bounded by information-theoretic constraints. That is, if we have a ten-bit message, it cannot communicate more than ten bits of information: it cannot always uniquely specify one internal state of an AI model from more than 210... (read more)
I like to distinguish between "Subtle strategic bias" and "Steganography." Paraphrasers help (and maybe solve?) the latter, but do nothing about the former.
Example of subtle strategic bias: The model knows it's misaligned and therefore deliberately sandbags on the alignment research you are asking it to do. "I'm sorry sir I just am not making much progress," it says. You look at the CoT, and it's just doing a bunch of sensible but fruitless lines of reasoning.
Example of steganography: The model needs to insert a subtle security vulnerability into the code it is writing -- but it doesn't know one right away, it has to invent one. And that requires lots of sequential thought. So it needs to try out different ideas, vet them, critique them, refine them, etc. Can't do that in a single forward pass. So it needs to pass information forward to its future self somehow... without humans reading the CoT knowing that's what it's doing. THIS is the sort of thing that is much harder to do with a paraphraser than without a paraphraser.
4Thane Ruthenis
I don't see why it would be harder to do.
Suppose you tasked a model with refactoring some database, and it secretly wants to sabotage its functionality. It outputs a CoT segment that goes, "I need to design unit tests for this module". Each word of this CoT is mapped to some internal representation, and the internal representation consists of "on-task" human-intended reasoning X, and misaligned scheming Y (corresponding to, e. g., a tactical decision to fail to include unit tests for some subtle issue). "I" is mapped to ⟨X1,Y1⟩, "need" is mapped to ⟨X2,Y2⟩, etc. Each Xi iterates on Xi−1, each Yi iterates on Yi−1, we have a sequence of serial computations.
In other words: as the model outputs, "I need to design unit tests for this module", there's an unspoken subtext of "I need to sabotage the unit tests here", and the model packs nine words' worth of serial computations into both the "textual" X and the "subtextual" Y aspects of it.
Now you use the Paraphraser on the string, generating alternatives like "the next step is to generate some unit tests" and "several unit tests for this module are needed here". The intent, if I understand you correctly, is that the semantic-equivalence-but-syntactic-difference would ensure that the ith token of this phrase is mapped to Xi, as if the paraphrasing didn't happen, but that the mapping of i→Yi would be broken.
Except, why would that happen? What privileges X-representations over Y-representations? Why would i→Xi be preserved whereas i→Yi is broken, instead of both of them remaining functional (and so preserving scheming), or both breaking (and so compromising the model's capabilities)?
In other words: We're basically just teaching the model to fail to distinguish between equivalent-to-a-human rephrasings. Why would this lead to the task-related representations becoming indifferent to the specifics of a phrasing whereas the scheming-related representations remain sensitive to it? Why wouldn't this just map the subtextual
4Daniel Kokotajlo
I don't think I understand. Let's work through an example.
The AI is being told to write good code, and wants to write subtly-vulnerable code instead. If it just were to honestly try to write good code, it would take (let's say) 100 serial steps of reasoning to succeed. To write subtly-vulnerable code, let's say, requires 300 serial steps of reasoning. The model's strategy is to write subtly-vulnerable code but in a way that looks like it's trying to write good code and just getting a bit unlucky and taking longer than usual (let's suppose the humans have a poor ability to judge how long it's supposed to take, but still some ability, such that it can't take e.g. 10x longer without arousing suspicion).
If there's no paraphraser, this is 'easy.' I mean it's still difficult but it's 'easy' in the sense that the AI can basically just use a code -- each nugget of reasoning might have 10 different semantically equivalent expressions, or maybe even 100, so it can 'add extra layers of meaning' to the nuggets -- in addition to their meaning in the surface level i'm-tring-to-write-good-code, they can have a hidden meaning having to do with the security vulnerability-related properties of the code. And it can make a chain of reasoning that is basically about the security stuff while looking like a reasonable but unlucky attempt to write good code.
But a paraphraser wrecks that strategy. The model can still add extra layers of meaning to the nuggets, but now it has loads of trouble making the chain of thought look like an honest attempt to write good code. To use your example, if 'I should generate unit tests now' and all semantically equivalent variants of that idea are assigned the hidden meaning 'I should check to see if the vulnerability is too easy to spot' for example, then... what is it going to write next? It's too constrained; in order to look non-suspicious there is a limited set of options it can follow up with... ok, hmm, I'm at the limits of my understanding he
2Thane Ruthenis
Ah, I think I see my error.
Consider a CoT of the form "[problem statement]: ...........", which always outputs dots regardless of the problem statement. Can that still encode useful computations, with the information being passed through intermediate self-attention? Yes, but: this only increases parallel-computing capabilities, not serial-computing capabilities.
And in the framework I'd outlined, under the Paraphraser, for the purposes of scheme-y thinking, even a legible CoT would consist of such "filler" tokens.
So yep, you're right, this does force all scheming to be taking place within one forward pass.
Edit: Nevermind, evidently I've not thought this through properly. I'm retracting the below.
The naïve formulations of utilitarianism assume that all possible experiences can be mapped to scalar utilities lying on the same,continuous spectrum, and that experiences' utility is additive. I think that's an error.
This is how we get the frankly insane conclusions like "you should save 10100 shrimps instead of one human" or everyone's perennial favorite, "if you're choosing between one person getting tortured for 50 years or some amount of people ... (read more)
Besides uncertainty, there's the problem of needing to pick cutoffs between tiers in a ~continuous space of 'how much effect does this have on a person's life?', with things slightly on one side or the other of a cutoff being treated very differently.
[...]
I agree with the intuition that this is important, but I think that points toward just rejecting utilitarianism (as in utility-as-a-function-purely-of-local-experiences, not consequentialism).
6ryan_greenblatt
It's worth noting that everything funges: some large number of experiences of eating a chocolate bar can be exchanged for avoiding extreme human suffering or death. So, if you lexicographically put higher weight on extreme human suffering or death, then you're willing to make extreme tradeoffs (e.g. 1030 chocolate bar experiences) in terms of mundane utility for saving a single life. I think this easily leads to extremely unintuitive conclusions, e.g. you shouldn't ever be willing to drive to a nice place. See also Trading off Lives.
I find your response to this sort of argument under "Relevance: There's reasoning that goes" in the footnote very uncompelling as it doesn't apply to marginal impacts.
4Garrett Baker
Ok, but if you don't drive to the store one day to get your chocolate, then that is not a major pain for you, yes? Why not just decide that next time you want chocolate at the store, you're not going to go out and get it because you may run over a pedestrian? Your decision there doesn't need to impact your other decisions.
Then you ought to keep on making that choice until you are right on the edge of those choices adding up to a first-tier experience, but certainly below.
This logic generalizes. You will always be pushing the lower tiers of experience as low as they can go before they enter the upper-tiers of experience. I think the fact that your paragraph above is clearly motivated reasoning here (instead of "how can I actually get the most bang for my buck within this moral theory" style reasoning) shows that you agree with me (and many others) that this is flawed.
3quetzal_rainbow
We can easily ban speed above 15km/h for any vehicles except ambulances. Nobody starves to death in this scenario, it's just very inconvenient. We value convenience lost in this scenario more than lives lost in our reality, so we don't ban high-speed vehicles.
Ordinal preferences are bad and insane and they are to be avoided.
What's really wrong with utilitarianism is that you can't, actually, sum utilities: it's a type error, because utilities are invariant up to affine transform, what would their sum mean?
The problem, I think, that humans naturally conflate two types of altruism. First type is caring about other entities mental state. Second type is "game-theoretic" or "alignment-theoretic" altruism: generalized notion of what does that mean to care about someone else's values. Roughly, I think that good type of the second type of altruism requires you to do fair bargaining in interests of entity you are being altruistic towards.
Let's take "World Z" thought experiment. The problem from the second type altruism perspective is that total utilitarian gets very large utility from this world, while all inhabitants of this world, by premise, get very small utility per person, which is unfair division of gains.
One may object: why not create entities who think that very small share of gains is fair? My answer is that if entity can be satisfied with infinitesimal share of gains, it also can be satisfied with infinitesimal share of anthropic measure, i.e., non-existence, and it's more altruistic to look for more demanding entities to fill universe with.
My general problem with animal welfare from bargaining perspective is that most of animals probably don't have sufficient agency to have any sort of representative in bargaining. We can imagine CEV of shrimp which is negative utilitarian and wants to kill all shrimp, or positive utilitarian which thinks that even very painful existence is worth it, or CEV that prefers shrimp swimming in heroin, or something human
-2habryka
Huh, I expected better from you.
No, it is absolutely not insane to save 10100 shrimp instead of one human! I think the case for insanity for the opposite is much stronger! Please, actually think about how big 10100 is. We are talking about more shrimp than atoms in the universe. Trillions upon trillions of shrimp more than atoms in the universe.
This is a completely different kind of statement than "you should trade of seven bees against a human".
No, being extremely overwhelmingly confident about morality such that even if you are given a choice to drastically alter 99.999999999999999999999% of the matter in the universe, you call the side of not destroying it "insane" for not wanting to give up a single human life, a thing we do routinely for much weaker considerations, is insane.
The whole "tier" thing obviously fails. You always end up dominated by spurious effects on the highest tier. In a universe with any appreciable uncertainty you basically just ignore any lower tiers, because you can always tell some causal story of how your actions might infinitesimally affect something, and so you completely ignore it. You might as well just throw away all morality except the highest tier, it will never change any of your actions.
9clone of saturn
I'm normally in favor of high decoupling, but this thought experiment seems to take it well beyond the point of absurdity. If I somehow found myself in control of the fate of 10^100 shrimp, the first thing I'd want to do is figure out where I am and what's going on, since I'm clearly no longer in the universe I'm familiar with.
2habryka
Yeah, I mean, that also isn’t a crazy response. I think being like “what would it even mean to have 10^30 times more shrimp than atoms? Really seems like my whole ontology about the world must be really confused” also seems fine. My objection is mostly to “it’s obvious you kill the shrimp to save the human”.
2Thane Ruthenis
Oh, easy, it just implies you're engaging in acausal trade with a godlike entity residing in some universe dramatically bigger than this one. This interpretation introduces no additional questions or complications whatsoever.
2Thane Ruthenis
Hm. Okay, so my reasoning there went as follows:
[...]
I'm not sure where you'd get off this train, but I assume the last bullet-point would do this? I. e., that you would argue that holding the possibility of shrimps having human-level qualia is salient in a way it's not for rocks?
Yeah, that seems valid. I might've shot from the hip on that one.
[...]
I have a story for how that would make sense, similarly involving juggling inside-model and outside-model reasoning, but, hm, I'm somehow getting the impression my thinking here is undercooked/poorly presented. I'll revisit that one at a later time.
Edit: Incidentally, any chance the UI for retracting a comment could be modified? I have two suggestions here:
* I'd like to be able to list a retraction reason, ideally at the top of the comment.
* The crossing-out thing makes it difficult to read the comment afterwards, and some people might want to be able to do that. Perhaps it's better to automatically put the contents into a collapsible instead, or something along those lines?
8habryka
You should be able to strike out the text manually and get the same-ish effect, or leave a retraction notice. The text being hard to read is intentional so that it really cannot be the case that someone screenshots it or skims it without noticing that it is retracted.
 4
 2
 2
 1
 1
 1
 1
 2
 1
 1
 1
 3
 2
 1
 1
 1
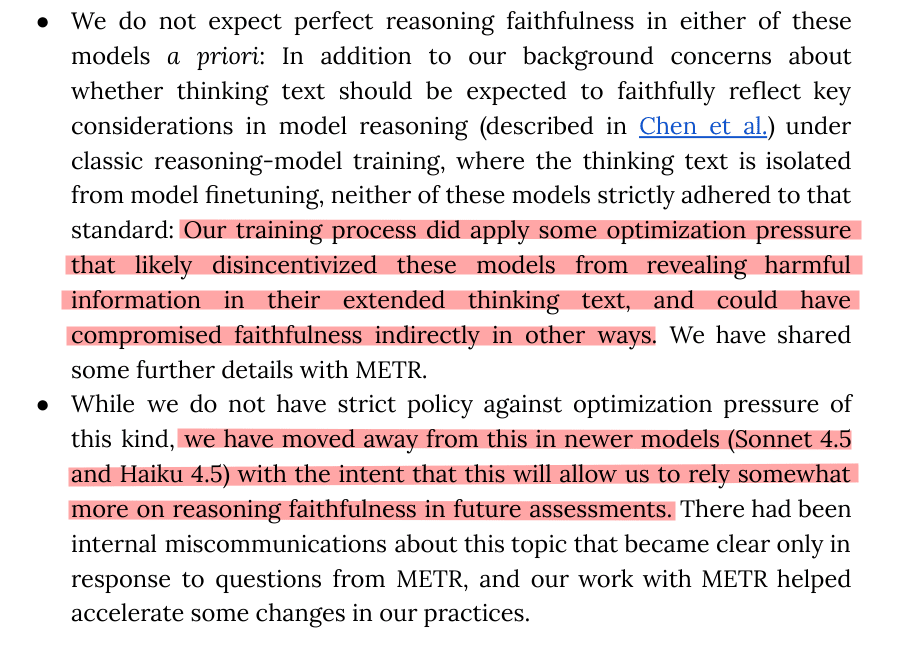
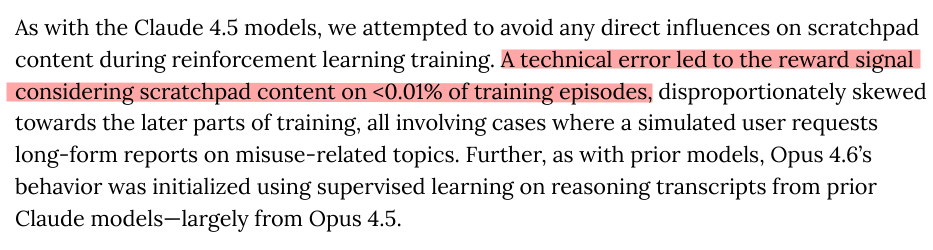
 1
 1
 1
 1
 6
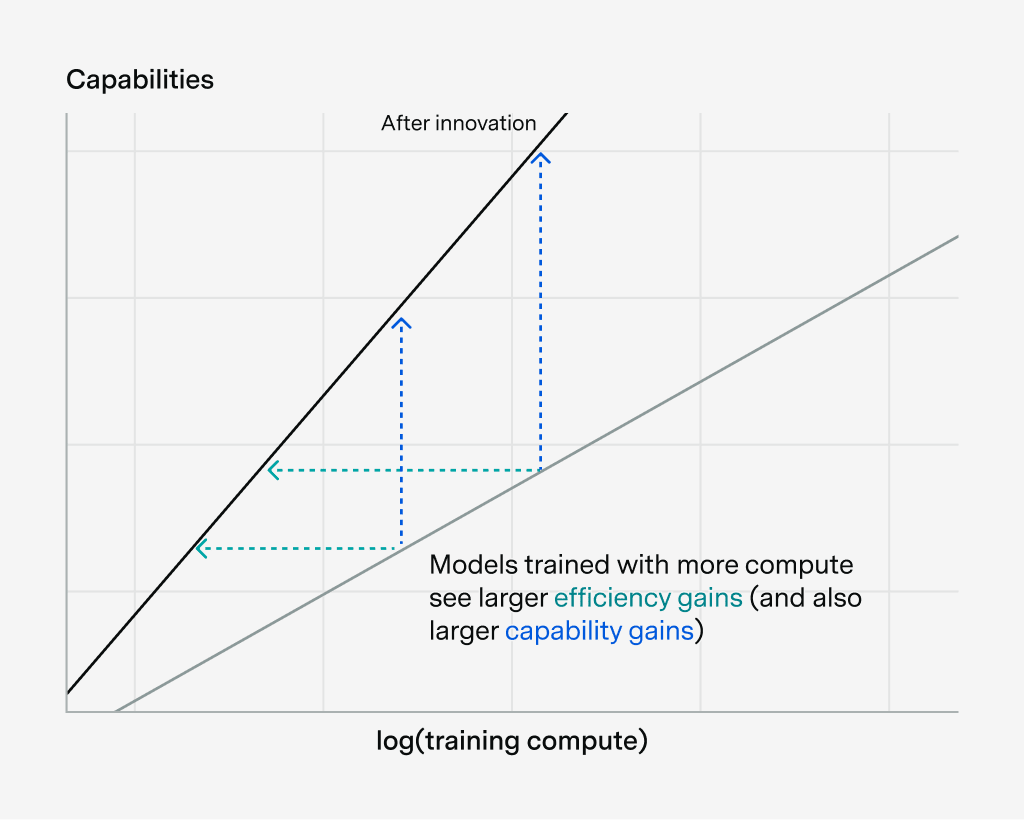
 1