I don't harvest ants for atoms. There are better sources.
Atoms are not a binding constraint for you. Your binding constraints are other stuff (like money, time, health).
Raw carbon atoms aren't that much of a constraint for the human economy. Land, energy and particularly human capital are the taut constraints.
If there was a system which was really good at harvesting energy and it was maxxed out on intelligence, atoms might be very valuable, especially atoms close to where it is created.
The US military is not waging wars against mentally disabled sloth babies.
The USSR did wage a "war" against whales to kill them for quotas. They just didn't need to use the military for it - that would be overkill.
It's not that widely known. Many species have gone extinct.
https://en.wikipedia.org/wiki/Holocene_extinction
"The current rate of extinction of species is estimated at 100 to 1,000 times higher than natural background extinction rates, and is increasing"
So, overall it seems that instrumental convergence and physics setting up conflicts over the use of atoms argue fairly strongly in favor of human extinction, or worse.
If there was a system which was really good at harvesting energy and it was maxxed out on intelligence, atoms might be very valuable, especially atoms close to where it is created
The number of atoms on earth is so tiny. Why not just head to the asteroid belt where you can really build?
If the ASI was 100% certain that there was no interesting information embedded in the Earths ecosystems that it couldn't trivially simulate, then I would agree.
Maybe you got into trouble for talking about that because you are rude and presumptive?
definitely
as a human talking about ASI, the word 'definitely' is cope. You have no idea whatsoever, but you want to think you do. Okay.
extract all the info it could
we don't know how information works at small scales, and we don't know whether an AI would either. We don't have any idea how long it would take to "extract all the info it could", so this phrase leaves a huge hole.
them maybe simulate us
which presumes that it is as arrogant in you in 'knowing' what it can 'definitely' simulate. I don't know that it will be so arrogant.
I'm not sure how you think you benefit from being 100% certain about things you have no idea about. I'm just trying to maintain a better balance of beliefs.
Maybe you got into trouble for talking about that because you are rude and presumptive?
I think this is just a nod to how he's literally Roko, for whom googling "Roko simulation" gives a Wikipedia article on what happened last time.
Everyone here acting like this makes him some kind of soothsayer is utterly ridiculous. I don't know when it became cool and fashionable to toss off your epistemic humility in the face of eternity, I guess it was before my time.
The basilisk is just pascals mugging for edgelords.
I don't mean to say that it's additional reason to respect him as an authority or accept his communication norms above what you would have done for other reasons (and I don't think people particularly are here), just that it's the meaning of that jokey aside.
strong agree, downvote.
Whatever happened here is an interesting datapoint about the long-term evolution of thermodynamic systems away from equilibrium.
From the biological anchors paper:
This implies that the total amount of computation done over the course of evolution from the first animals with neurons to humans was (~1e16 seconds) * (~1e25 FLOP/s) = ~1e41 FLOP.
Note that this is just computation of neurons! So the total amount of computation done on this planet is much larger.
This is just illustrative, but the point is that what happened here is not so trivial or boring that its clear that an ASI would not have any interest in it.
I'm sure people have written more extensively about this, about an ASI freezing some selection of the human population for research purposes or whatever. I'm sure there are many ways to slice it.
I just find the idea that the ASI will want my atoms for something trivial, when there are so many other atoms in the universe that are not part of a grand exploration of the extremes of thermodynamics, unconvincing.
Whatever happened here is an interesting datapoint about [...]
I think using the word "interesting" here is kinda assuming the conclusion?
Whatever happened here is a datapoint about the long-term evolution of thermodynamic systems away from equilibrium.
Pretty much all systems in the universe can be seen as "thermodynamic systems". And for a system to evolve at all, it necessarily has to be away from equilibrium. So it seems to me that that sentence is basically saying
"Whatever happened here is a datapoint about matter and energy doing their usual thing over a long period of time."
And... I don't see how that answers the question "why would an ASI find it interesting?"
From the biological anchors paper [...] the point is that what happened here is not so trivial or boring that its clear that an ASI would not have any interest in it.
I agree that a lot of stuff has happened. I agree that accurately simulating the Earth (or even just the biological organisms on Earth) is not trivial. What I don't see (you making an actual argument for) is why all those neural (or other) computations would be interesting to an ASI. [1]
I'm sure people have written more extensively about this, about an ASI freezing some selection of the human population for research purposes or whatever.
Right. That sounds like a worse-than-death scenario. I agree those are entirely plausible, albeit maybe not the most likely outcomes. I'd expect those to be caused by the AI ending up with some kind of human-related goals (due to being trained with objectives like e.g. "learn to predict human-generated text" or "maximize signals of approval from humans"), rather than by the ASI spontaneously developing a specific interest in the history of how natural selection developed protein-based organic machines on one particular planet.
I just find the idea that the ASI will want my atoms for something trivial, when [...]
As mentioned above, I'd agree that there's some chance that an Earth-originating ASI would end up with a goal of "farming" (simulated) humans for something (e.g. signals of approval), but I think such goals are unlikely a priori. Why would an ASI be motivated by "a grand exploration of the extremes of thermodynamics" (whatever that even means)? (Sounds like a waste of energy, if your goal is to (e.g.) maximize the number of molecular squiggles in existence.) Are you perhaps typical-minding/projecting your own (laudable) human wonder/curiosity onto a hypothetical machine intelligence?
Analogy: If you put a few kilograms of fluid in a box, heat it up, and observe it for a few hours, the particles will bop around in really complicated ways. Simulating all those particle interactions would take a huge amount of computation, it would be highly non-trivial. And yet, water buckets are not particularly exciting or interesting. Complexity does not imply "interestingness". ↩︎
"Whatever happened here is a datapoint about matter and energy doing their usual thing over a long period of time."
Not all thermodynamic systems are created equal. I know enough about information theory to know that making bold claims about what is interesting and meaningful is unwise. But I also know it is not certain that there is no objective difference between a photon wandering through a vacuum and a butterfly.
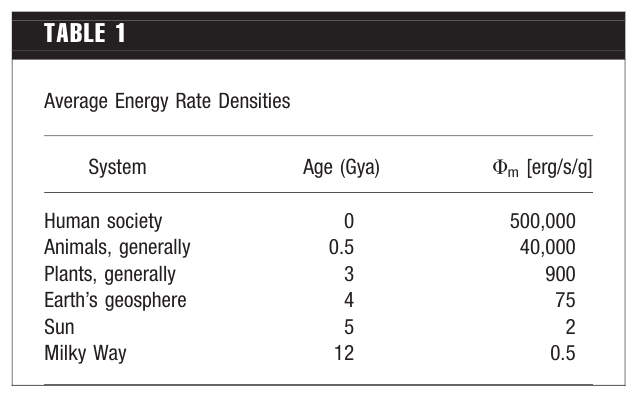
Here is one framework for understanding complexity that applies equally well for stars, planets, plants, animals, humans and AIs. It is possible I am typical-minding, but it is also possible that the universe cares about complexity in some meaningful way. Maybe it helps increase the rate of entropy relaxation. I don't know.
spontaneously developing a specific interest in the history of how natural selection developed protein-based organic machines on one particular planet
not 'one particular planet' but 'at all'.
I find it plausible that there is some sense in which the universe is interested in the evolution of complex nanomachines. I find it likely that an evolved being would be interested in the same. I find very likely that an evolved being would be particularly interested in the evolutionary process by which it came into being.
Whether this leads to s-risk or not is another question, but I think your implication that all thermodynamic systems are in some sense equally interesting is just a piece of performative cynicism and not based on anything. Yes this is apparently what matter and energy will do given enough time. Maybe the future evolution of these atoms is all predetermined. But the idea of things being interesting or uninteresting is baked into the idea of having preferences at all, so if you are going to use that vocabulary to talk about an ASI you must already be assuming that it will not see all thermodynamic systems as equal.
Haha, totally agree- I'm very much at the limit of what I can contribute.
In an 'Understanding Entropy' seminar series I took part in a long time ago we discussed measures of complexity and such things. Nothing was clear then or is now, but the thermodynamic arrow of time plus the second law of thermodynamics plus something something complexity plus the fermi observation seems to leave a lot of potential room for this planet is special even from a totally misanthropic frame.
Enjoy the article!
Total mass of the asteroid belt is <0.1% the mass of Earth. Total mass of all rocky planets, moons, asteroids, comets, and any other Oort cloud objects is about 3 Earth masses. Not harvesting Earth first if you can and you're right here would be very odd, until and unless you can build everything you need out of the sun or the gas giants.
I can imagine situation when ASI first disassemble Moon and then Earth. I can't imagine scenarios
- Where ASI doesn't disassemble Earth at all
- Where ASI doesn't unleash some nanoplagues to destroy human civilization before starting disassemble Moon, just in case.
I agree that we are unlikely to pose any serious threat to an ASI. My disagreement with you comes when one asks why we don't pose any serious threat. We pose no threat, not because we are easy to control, but because we are easy to eliminate. Imagine you are sitting next to a small campfire, sparking profusely in a very dry forest. You have a firehose in your lap. Is the fire a threat? Not really. You can douse it at any time. Does that mean it couldn't in theory burn down the forest? No. After all, it is still fire. But you're not worried because you control all the variables. An AI in this situation might very well decide to douse the fire instead of tending it.
To bring it back to your original metaphor: For a sloth to pose a threat to the US military at all, it would have to understand that the military exists, and what it would mean to 'defeat' the US military. The sloth does not have that baseline understanding. The sloth is not a campfire. It is a pile of wood. Humans have that understanding. Humans are a campfire.
Now maybe the ASI ascends to some ethereal realm in which humans couldn't harm it, even if given completely free reign for a million years. This would be like a campfire in a steel forest, where even if the flames leave the stone ring, they can spread no further. Maybe the ASI will construct a steel forest, or maybe not. We have no way of knowing.
An ASI could use 1% of its resources to manage the nuisance humans and 'tend the fire', or it could use 0.1% of its resources to manage the nuisance humans by 'dousing' them. Or it could incidentally replace all the trees with steel, and somehow value s'mores enough that it doesn't replace the campfire with a steel furnace. This is... not impossible? But I'm not counting on it.
Sorry for the ten thousand edits. I wanted the metaphor to be as strong as I could make it.
Relevant: https://scottaaronson.blog/?p=7064
I'm at like 40% doom, then conditional on doom like 50/50 on nearly all (>99%) humans killed within a year (I'm talking about information death here, freezing brains and reviving later doesn't count as death; if not revived ever, then it's death), then conditioned on nearly all humans killed I'm at maybe 75% on literally all humans killed within a year.
So, overall I'm at 15% on literally all humans dead?
Numbers aren't in reflective equilibrium. I find the arguments for the AI killing nearly everyone not that compelling.
I also find the atoms argument very uncompelling. There is so much space and solar energy in the asteroid belt, I'm sure there is a good chance that the ASI will be chill.
However, I think Yudkowsky is shouting so loud because even if that chance of asi apocalypse is only 5%, that is 5% multiplied by all possible human goodness, which is a big deal to our species in expectation.
Personally I think the totality of the biological ecosystems on earth (including humans) will still be interesting to an ASI, so I'd hope they'd let it tick on as a museum piece.
But it's hard for us. It would be very easy for an ASI. Even with no advancement in tech, the ASI can ride on the starlinks into space.
We are stuck here amongst the biology for very obvious reasons.
The question isn't whether it would be easier for superintelligent AI to go to space than it would be for humans. Of course it would be! Everything will be easier for a superintelligent AI.
The question is whether a superintelligent AI would prioritize going to space immediately, leaving Earth as an "untouched wilderness", where humans are free to thrive. Or, will the superintelligent AI work on fully exploiting the resources it has at hand, here on earth, before choosing to go to space? I think the latter is far more likely. Superintelligence can't beat physics. No matter what, it will always be easier to harvest closer resources than it will be to harvest resources that are farther away. The closest resources are on earth. So why should the superintelligent AI go to space, when, at least in the immediate term, it has everything it needs to grow right here?
whether a superintelligent AI would prioritize going to space immediately
Priorities need a resource that gets allocated to one thing and not another thing. But going to space doesn't imply/motivate leaving Earth, doing both doesn't diminish either.
My argument is that, like humanity, a superintelligent AI will initially find it easier to extract resources from Earth than it will from space based sources. By the time earth's resources are sufficiently depleted that this is no longer the case, there will be far too little remaining for humanity to survive on.
Do you pick up every penny that you pass in the street?
The amount of energy and resources on Earth would be a rounding error in an ASI's calculations. And it would be a rounding error that happens to be incredibly complex and possibly unique!
Maybe a more appropriate question is, do you pick every flower that you pass in the park? What if it was the only one?
The amount of energy and resources on Earth would be a rounding error in an ASI’s calculations.
Once again: this argument applies to humanity too. Everyone acknowledges that the asteroid belt holds far more resources than Earth. But here we are, building strip mines in Australia rather than hauling asteroids in from the belt.
Your counterargument is that the AI will find it much easier to go to space, not being constrained by human biology. Fine. But won't the AI also find it much easier to build strip mines? Or harvest resources from the oceans? Or pave over vast tracts of land for use as solar farms? You haven't answered why going to space will be cheaper for the AI than staying on earth. All you've proven is that going to space will be cheaper for the AI than it will be for humans, which is a claim that I'm not contesting.
See my reply above for why the ASI might choose to move on before strip-mining the planet.
From your other reply
I just find the idea that the ASI will want my atoms for something trivial, when there are so many other atoms in the universe that are not part of a grand exploration of the extremes of thermodynamics, unconvincing.
The problem isn't that the AI will want the atoms that comprise your body, specifically. That's trivially false. It makes as much sense as the scene in The Matrix where Morpheus explained to Neo that the Matrix was using humans as living energy sources.
What is less trivially false is that the AI will alter the biosphere in ways that make it impossible (or merely very difficult) for humans to live, just as humans have altered the biosphere in ways that have made it impossible (or merely very difficult) for many other species to live. The AI will not intend to alter the biosphere. The biosphere alteration will be a side-effect of whatever the AI's goals are. But the alteration will take place, regardless.
Put more pithily: tell me why I should expect a superintelligent AI to be an environmentalist.
Just to preserve information. It's not every day that you come across a thermodynamic system that has been evolving so far from equilibrium for so long. There is information here.
In general, I feel like a lot of people in discussion about ASI seem to enjoy fantasizing about science fiction apocalypses of various kinds. Personally I'm not so interested in exercises in fancy, rather looking at ways physical laws might imply that 'strong orthogonality' is unlikely to obtain in reality.
The information could be instrumentally useful for any of the following Basic AI Drives:
- Efficiency: making use of the already-performed thermodynamic 'calculation' of evolution (and storage of that calculation-- the biosphere conveniently preserves this information for free)
- Acquisition: 'information' will doubtlessly be one of the things an AI wants to acquire
- Creativity: the biosphere has lots of ways of doing things
- Cognitive enhancement: understanding thermodynamics on an intimate level will help any kind of self-enhancement
- Technological perfection: same story. You want to understand thermodynamics.
At every time step, the AI will be trading off these drives against the value of producing more or doing more of whatever it was programmed to do. What happens when the AI decides that it's learned enough from the biosphere and that the costs of preserving a biosphere for humans no longer outweigh the potential benefit that it earns from learning about biology, evolution and thermodynamics?
We humans make these trade-offs all the time, often unconsciously, as we weigh whether to bulldoze a forest, or build a dam, or dig a mine. A superintelligent AI will perhaps be more intentional in its calculations, but that's still no guarantee that the result of the calculation will swing in humanity's favor. We could, in theory, program the AI to preserve earth as a sanctuary. But, in my view, that's functionally equivalent to solving alignment.
Your argument appears to be that an unaligned AI will, spontaneously, choose to, at the very least, preserve Earth as a sanctuary for humans into perpetuity. I still don't see why it should do that.
That isn't my argument, my argument is just that the general tone seems too defeatist.
The question asker was under the impression that the probabilities were %99.X percent against anything okay. My only argument was that this is wrong, and there are good reasons that this is wrong.
Where the p(doom) lies between 99 and 1 percent is left as an exercise for posterity. I'm not totally unhinged in my optimism, I just think the tone of certain doom is poorly founded and there are good reasons to have some measure of hope.
Not just 'i dunno, maybe it will be fine' but real reasons why it could conceivably be fine. Again, the probabilities are up for debate, I only wanted to present some concrete reasons.
A related factor is curiosity. As I understand, reinforcement learning agents perform much better if gifted with curiosity (or if developed it by themselves). Seeking novel information is extremely helpful for most goals (but could lead to "TV addiction").
I find it plausible that ASI will be curious, and that both humanity and the biosphere, which are the results of billions of years of an enormous computation, will stimulate ASI's curiosity.
But its curiosity may not last for centuries, or even years. Additionally, the curiosity may involve some dissection of living humans, or worse.
Note that an AI or civilization of many ASIs could harvest the overwhelming majority of all accessible and suitable material on the planet and yet keep all humans alive if they chose to. It's not an expensive thing to do. Humans are really cheap and live skimming off the very surface of the earth. Most of our raw material shortages are self inflicted, we don't recycle CO2 back to hydrocarbons and we don't recycle our trash at an elemental level.
The reason they might kill all humans would be either from a moloch scenario or one where it was efficient to do so to remove humans as an obstacle.
even if that chance of asi apocalypse is only 5%, that is 5% multiplied by all possible human goodness, which is a big deal to our species in expectation.
The problem is that if you really believe (because EY and others are shouting it from the rooftops) that there is a ~!00% chance we're all gonna die shortly, you are not going to be motivated to plan for the 50/50 or 10/90 scenario. Once you acknowledge that you can't really make a confident prediction on this matter, it is illogical to only plan for the minimal and maximal cases (we all die/everything is great). Those outcomes need no planning, so spending energy focusing on them is not optimal.
Sans hard data, as a Bayesian, shouldn't one start with a balanced set of priors over all the possible outcomes, then focus on the ones you may be able to influence?
I'm not sure what you think I believe, but yeah I think we should be looking at scenarios in between the extremes.
I was giving reasons why I maintain some optimism, and maintaining optimism while reading Yudkowsky leaves me in the middle, where actions can be taken.
I agree that AGI is possible to make, that it eventually will become orders-of-magnitude smarter than humans, and that it poses a global risk if the alignment problem is not solved. I also agree that the alignment problem is very hard, and is unlikely to be solved before the first AGI. And I think it's very likely that the first recursively-self-improving AGI will emerge before 2030.
But I don't get the confidence about the unaligned AGI killing off humanity. The probability may be 90%, but it's not 99.9999% as many seem to imply, including Eliezer.
Sure, humans are made of useful atoms. But that doesn't mean the AGI will harvest humans for useful atoms. I don't harvest ants for atoms. There are better sources.
Sure, the AGI may decide to immediately kill off humans, to eliminate them as a threat. But there is a very short time period (perhaps in miliseconds) where humans can switch off a recursively-self-improving AGI of superhuman intelligence. After this critical period, humanity will be as much a threat to the AGI as a caged mentally-disabled sloth baby is a threat to the US military. The US military is not waging wars against mentally disabled sloth babies. It has more important things to do.
All such scenarios I've encountered so far imply AGI's stupidity and/or the "fear of sloths", and thus are not compatible with the premise of a rapidly self-improving AGI of superhuman intelligence. Such an AGI is dangerous, but is it really "we're definitely going to die" dangerous?
Our addicted-to-fiction brains love clever and dramatic science fiction scenarios. But we should not rely on them in deep thinking, as they will nudge us towards overestimating the probabilities of the most dramatic outcomes.
Overestimating a global risk is almost as bad as underestimating it. Compare: if you’re 99.99999% sure that a nuclear war will kill you, then the despondency will greatly reduce your chances of surviving the war, because you'll fail to make the necessary preparations, like acquiring a bunker etc, which could realistically save your life under many circumstances.[1]
The topic of surviving the birth of the AGI is severely under-explored, and the "we're definitely going to die" mentality seems to be the main cause. A related under-explored topic is preventing the unaligned AGI from becoming misantropic, which should be our second line of defense (the first one is alignment research).
BTW, despondency is deadly by itself. If you've lost all hope, there is a high risk that you'll not live long enough to see the AGI, be it aligned or not.