This is a special post for quick takes by Kaj_Sotala. Only they can create top-level comments. Comments here also appear on the Quick Takes page and All Posts page.
Kaj's shortform feed
175Kaj_Sotala
223paulfchristiano
14aysja
8Tim Hua
2Kaj_Sotala
54Thane Ruthenis
36Vladimir_Nesov
5[anonymous]
2brendanhalstead
1[anonymous]
3dprkay
1[anonymous]
3dprkay
1[anonymous]
5[anonymous]
2[anonymous]
30cdt
55Thane Ruthenis
108aysja
27Jenna_Parr
8Seth Herd
7Thane Ruthenis
4Mateusz Bagiński
14Leonard Holloway
6Jenna_Parr
14Daniel Kokotajlo
21Thane Ruthenis
14Daniel Kokotajlo
21Thane Ruthenis
5[anonymous]
9Vladimir_Nesov
1dprkay
13DW11
21Daniel Kokotajlo
33Tim Hua
5Daniel Kokotajlo
27Kaj_Sotala
3Mo Putera
14Vladimir_Nesov
11ROM
7Ebenezer Dukakis
5Mo Putera
7Linch
6HowManyAgents
2Aaron Staley
2Afterimage
10Kaj_Sotala
6dprkay
3Kaj_Sotala
2Nick_Tarleton
2Kaj_Sotala
1dprkay
2Kaj_Sotala
1Afterimage
91Kaj_Sotala
6abramdemski
9Kaj_Sotala
4cubefox
2A1987dM
2jbash
6Kaj_Sotala
0MinusGix
2Kaj_Sotala
66Kaj_Sotala
16MinusGix
8J Bostock
2Mo Putera
2Saulius
2Seth Herd
2Signer
2James Diacoumis
2Gunnar_Zarncke
10xA
-1Shankar Sivarajan
54Kaj_Sotala
9Terence Coelho
4Chris_Leong
11Kaj_Sotala
3deepthoughtlife
7Noosphere89
3deepthoughtlife
2Kaj_Sotala
47Kaj_Sotala
6Karl Krueger
5Shoshannah Tekofsky
3Kaj_Sotala
4Shoshannah Tekofsky
5Kaj_Sotala
3papetoast
2MichaelDickens
2Kaj_Sotala
2BrandonReinhart
1Nissa Seru
45Kaj_Sotala
4ozziegooen
4ozziegooen
4Vanessa Kosoy
2Gordon Seidoh Worley
41Kaj_Sotala
53Vladimir_Nesov
26DirectedEvolution
10DirectedEvolution
1MP
5Vladimir_Nesov
-1MP
0Eli Tyre
-1romeostevensit
40Kaj_Sotala
39dynomight
9AMCAM
9silentbob
5kbear
2Viliam
24JohnWittle
18StanislavKrym
5Kaj_Sotala
15robo
11lilkim2025
11Adele Lopez
6Forged Invariant
1BryceStansfield
39Kaj_Sotala
38Steven Byrnes
4Kaj_Sotala
4Steven Byrnes
4Kaj_Sotala
15Buck
8Unnamed
4DirectedEvolution
4Viliam
1Morpheus
35Kaj_Sotala
16AlphaAndOmega
5ACCount
12Thane Ruthenis
6Garrett Baker
5Kabir Kumar
5sjadler
4samuelshadrach
9Kaj_Sotala
1samuelshadrach
1Petropolitan
32Kaj_Sotala
68Random Developer
14Douglas_Knight
31Kaj_Sotala
28Kaj_Sotala
11Gavin Runeblade
6Kaj_Sotala
4Viliam
4Kaj_Sotala
4Viliam
1DusanDNesic
26Kaj_Sotala
24Kaj_Sotala
33Thane Ruthenis
11Girard Dorney
6Thane Ruthenis
5Cole Wyeth
22Kaj_Sotala
17Kaj_Sotala
1anaguma
6Kaj_Sotala
1rsaarelm
2Kaj_Sotala
14Kaj_Sotala
13Kaj_Sotala
3cdt
2Chris Lakin
12Kaj_Sotala
11Kaj_Sotala
6kaiwilliams
3Kaj_Sotala
11Kaj_Sotala
11Kaj_Sotala
10Kaj_Sotala
4Mateusz Bagiński
3Kaj_Sotala
10gjm
3habryka
2Pablo
2habryka
10Kaj_Sotala
9Kaj_Sotala
3eigen
8Kaj_Sotala
2Wei Dai
2Kaj_Sotala
1daozaich
2Kaj_Sotala
7Kaj_Sotala
7Kaj_Sotala
6Kaj_Sotala
6Kaj_Sotala
5habryka
3Kaj_Sotala
6Kaj_Sotala
6Kaj_Sotala
4Trinley Goldenberg
3eigen
5Kaj_Sotala
4Seth Herd
5Kaj_Sotala
1Sherrinford
2Kaj_Sotala
5Kaj_Sotala
4Kaj_Sotala
2Dagon
2Ruby
3the gears to ascension
2habryka
10Dean Valentine
4Kaj_Sotala
4Kaj_Sotala
4Seth Herd
2Kaj_Sotala
2Noosphere89
2Kaj_Sotala
4habryka
2Kaj_Sotala
4Kaj_Sotala
4Kaj_Sotala
3Kaj_Sotala
2Kaj_Sotala
2Elo
A few months ago I gave a ~10% probability of TEDAI within 12 months; my intuition is now closer to ~30% if we go full speed ahead. Some of that was from the passage of time, but it's also about a ~2x update.[1]
For me the math and CS research progress is a bigger update than the METR/Anthropic reporting. I think we saw maybe a decade of progress on the hardest open problems in math and theoretical computer science with no sign of relevant capabilities slowing down. The ability to outperform large communities of human researchers at the task of designing and improving algorithms is a core part of an intelligence explosion, so I think that's a really important indicator.[2]
I also think it's useful to track accelerated progress on well-defined metrics (like pretraining or RL performance). Regardless of whether that progress transfers, it indicates that underlying technical developments are accelerating. And beyond that, I think "we haven't seen the pace of progress double yet" is a good argument that the singularity is likely at least 6-12 months away (at least for a trend-extrapolator like me). So once it's happened it's a lot harder to be confident that you won't see something crazy...
 2
 2
 1
I feel a bit crazy
Same, I don't understand what's triggering all these mood shifts. Am I out of the loop on something? Am I delusional and completely out of my mind on copium? I've spent way too much time the last few days trying to troubleshoot myself, and I still don't think I am...
I would have understood if this reaction was in response to the Navier-Stokes resolution, that was pretty freaky. But the Anthropic report doesn't seem to merit any of this whatsoever. I guess maybe this isn't really about the report at all, it's some sort of preference cascade that was just triggered by it, the last drop of evidence many people needed?
 2
A lot of people really do consider benchmark scores or productivity metrics (and the extrapolations from them) load-bearing, so it's not surprising to me that the METR report is relevant evidence for them. Since I mostly ignore benchmark scores, this was a complete no-op for me (unlike the Anthropic pretraining efficiency plot, which is a big update), but I don't think it's unexpected that a lot of people did update.
So the "Is everyone crazy, or am I crazy?" thing is about different models, which was already a live distinction before the METR report. Similarly to how there's now a permanent hazard rate of 5+% for 1-2 year timelines to a takeoff, for which the METR report isn't a crux (it only moves the probabilities around), there are preexisting different ways of thinking about the role of pretraining scale vs. benchmark scores in strong ASI timelines, and the METR report is not a crux for adjudicating this distinction.
 2
There's a bit of a motte and bailey here:
Motte: Internal METR/Anthropic evidence prove ~2x research uplift which prove short timelines.
Bailey: AECI trends prove ~2x research uplift which prove short timelines.
Many people have raised good arguments against the latter, but then the kernel of the argument rests on the former which is basically impossible as an outsider to use.
There is a very real sense in my mind that this website is becoming alarmist. This is one example, but the discussion immediately after the Weight-Space programming paper is another. It's right to want to update timelines quickly with new evidence, but it feels like these updates are driven mostly by the evidence feeling correct in atmosphere rather than in the quality of evidence per se.
4There is a very real sense in my mind that this website is becoming alarmist
Yeah, agreed. Frankly, the end result of my checking LW lately has been increased stress levels for the day without much productive new information being learned, almost on the level of doomscrolling Twitter. The unpleasant thing is that my prior on LW being reasonable and relatively well-calibrated on these matters is high, so I'm still not totally sure that it's LW's collective epistemics that are at fault, instead of LW being at a valid level of alarm and my being in denial. But if I keep to object-level analysis, I'm inclined towards the former.
6I’m in a similar position. I’ve already mostly stopped going on Twitter because of this (i.e. the panic to useful info ratio is terrible), but I am really sad to make such an update about LessWrong. And, as you say, it's especially unpleasant given that LessWrong tends to be reasonable and careful. So I am constantly questioning myself and wondering if I’m just grasping onto the so-called “hopium,” even though I too really don’t think that’s what’s going on.
Overall, the situation is very rabbit/duck for me. As in, I feel like I'm always flitting between two competing but incompatible versions of reality. When I look at the world “through my own eyes,” when I use the models, when I read about how other people use the models, when I think about the models, when I think about what intelligence is and what makes humans so powerful, when I hold all of that in my head on my own terms, on a gut level I really struggle to see it. On a gut level, my experience tells me that the machines can’t “really” think, and on a gut level, this really seems like it ought to matter.
And yet there is another part of me that is more in touch with abstract arguments which thinks things like “exponentials ...
126
I enjoy your analyses, if it helps. What we want is to be right, and act on it. The Litany of Tarski still applies.
It's only evidence against our model insofar as the alternative models predicted this surprising thing even more. Do you have an alternative model in mind, that successfully predicted the METR report in advance? Failing that, do you have an alternative model that at least retrodicts it well?
I agree that the METR report on its own is not conclusive, that's why we talked about other sources of evidence that were important to us also.
Anyhow I still think you aren't doing this thing justice. 2x acceleration is at least a significant chunk of evidence for the hypothesis that the intelligence explosion is soon, no? You agreed that the Mathapocalypse is evidence, why wouldn't an AI-driven acceleration in AI capabilities progress more generally also be evidence? Or are you saying that there is probably no such acceleration? Or are you saying that 2x accelerations happen all the time historically and then are followed by decelerations and therefore don't mean much when they happen now?
2 1
It's only evidence against our model insofar as the alternative models predicted this surprising thing even more
Sure, but that doesn't mean we end up falling back to some specific alternate strong model. It may be that we end up with a basically uniform distribution over the space of possible strong models.
Like, if there's 1000 urns with one ball in one of them, and there's been some promising evidence that the ball is in urn #461, but then we looked there and it was empty, that doesn't mean I'm rejecting the urn-461 hypothesis in favor of a strong belief in any specific other urn. We end up with basically no precise idea where the ball is.
I have no idea how to model AI progress at the level of precision AIFP's model aspires to. I don't think AIFP's model succeeds at its aspiration.
Or are you saying that 2x accelerations happen all the time historically and then are followed by decelerations and therefore don't mean much when they happen now?
Something like this, maybe. Imagine a specialized AI technique were discovered that made AI really, really good at hardware design. Suppose its efficiency naturally scaled with compute.[1] Depending on how powerful it is quantitatively, that d...
119
While I don't think it should be an update against the lines-on-graphs models (unlike Thane Ruthenis in the sibling reply), I do think the METR report (or the AI Futures framing of it in the update post) is not a serious chunk of evidence according to my own way of looking at progress towards strong ASI (unlike Anthropic's pretraining efficiency plot, which did shift my near-term timelines by a year). In my view, the things crucial for strong ASI are either (1) pretraining scale (including effective pretraining compute, so some incremental algorithmic progress can also matter, but it might be fundamentally in short supply), because it's the general factor of intelligence for LLMs and it can help them invent other things (while RL-trained skills are only skills; however important in practice, they are not a general factor of intelligence), or (2) paradigm-shifting unhobbling innovations that enable fast climbing on the tech tree (as opposed to reaching higher for the less accessible low-hanging tech fruit, while still climbing slowly).
[...]
At the same time, it's very expected that AI Futures/Epoch/Redwood people would see this as a serious chunk of evidence, as they should given the way they are thinking about forecasting strong ASI (in particular, as the thing at the end of the timelines).
Worth noting that they also make the opposite point: that the AECI scores might be underestimating the extent the extent to which AI capabilities have improved.
AECI could understate real-world capability impact. We have sparse data on the relationship between benchmark scores and real-world impact. As one example, ECI scores on math have not accelerated substantially, but we are now seeing the resolution of Millennium Prize Problems that have evaded decades of human effort. Real-world impacts may be downstream of capability thresholds that models suddenly pass, leading to sudden impacts that are hard to predict.
 2
7
Dwarkesh wrote a post arguing that ML research is a "well-specified task" and outlining how more general acceleration could occur:
https://substack.com/home/post/p-224624765
7
I agree there's a strong possibility that a) there's only acceleration in easily defined tasks, and b) enough of ML research is not in easily defined tasks and those discrepancies can't be routed around.
I personally don't have enough confidence that this conjunction is right that I'd want to bet all (or even most) of the community's resources on medium to long timelines. Which is why I plan to pivot hard to very short timelines myself and encourage most others to join me.
However, I'm not very confident that this conjunction is wrong, which is why I don't think longer timelines impact stories (like community building) are obviously doomed.
Still, it's a huge update at least for me.
6
The METR report was not much of an update for me. But the METR report did make me think again about where we now are, where we came from, and where we are likely going:
1. These AI's right now are pretty smart, much smarter than the average human across the board cognitively for all digital tasks (in my view), and smarter than most somewhat smart humans within their context window.
2. This is general intelligence that is increasing. Astra really is higher g than GPT 3.5
3. Given how I can talk to these models as if they are a fellow coworker/human level-ish already already. It seems that I should predict that in a few years they will be superhuman.
And if I predict that in a few years they will be superhuman, then I should put some probability mass on that happening in the next 12 months.
The METR report didn't update me because it's all a bit redacted hidden methods who knows what is even being measured by AECI: but it just made me think again about where we are now, where we were a few years ago, and where we are likely going and then I do reach the same conclusions from the METR report
I do also think that ultimately the METR people are doing something like the reasoning I did in 1/2/3. And that the data they are seeing doesn't falsify those intuitions and why they are saying what they are saying.
2
Even on hard to verify lmca, fable 5.2 is hitting where it is predicted by eci. Perhaps ECI is at most overestimating lmca performance by 1. (Making 172.3 a more conservative estimate for harder to very tasks). That's still a slightly above ECI trendline jump from Astra and significantly above trend relative to fable 5.1.
N=1 for this argument, but does point toward more likely than not there being some acceleration even in hard to validate tasks.
2
I don't think this "better than humans at any cognitive task" definition of ASI is useful at all. I think most people now use the definition that is - in practice - somewhere between "could kill a big chunk of humans if improperly aligned" and "could kill all humans if improperly aligned"
Every now and then in discussions of animal welfare, I see the idea that the "amount" of their subjective experience should be weighted by something like their total amount of neurons. Is there a writeup somewhere of what the reasoning behind that intuition is? Because it doesn't seem intuitive to me at all.
From something like a functionalist perspective, where pleasure and pain exist because they have particular functions in the brain, I would not expect pleasure and pain to become more intense merely because the brain happens to have more neurons. Rather I would expect that having more neurons may 1) give the capability to experience anything like pleasure and pain at all 2) make a broader scale of pleasure and pain possible, if that happens to be useful for evolutionary purposes.
For a comparison, consider the sharpness of our senses. Humans have pretty big brains (though our brains are not the biggest), but that doesn't mean that all of our senses are better than those of all the animals with smaller brains. Eagles have sharper vision, bats have better hearing, dogs have better smell, etc..
Humans would rank quite well if you took the average of all of our senses - we're el...
1"About thirteen or fourteen years ago, when I was still an academic, I interviewed for a [psychology] faculty position at a fancy university in Canada. [...] There were four applicants, each hosted by a different committee member. I had a grand time with my host. He was very candid about the whole process. At one point he told me that after the candidates had all come and gone, the committee members would go into a small room, sit down, and proceed to argue with one another for several hours over utterly ridiculous things each candidate said or did, until eventually everyone was worn out and just settled for whichever candidate they were all able to barely tolerate."
"I asked why the committee didn't just apply the lessons of seventy years of industrial-organizational psychology: come up ahead of time with a scoring rubric; have everyone independently fill it out without talking to each other; then mechanically aggregate the scores and offer the job to the person with the biggest number."
"He said (and he was right), “well, obviously, we don't believe our own methods.”"
"You could try to write it off as just a dysfunctional department, but… it wasn’t. They’re all like that. I’ve never...
 2
There are no details for most of these commitments. They are likely flexible enough to get scaled back if growth isn't there, as most of this capex is for the projects that remain years in the future. There also might be some double counting, such as with Nvidia's commitment, which might just apply to Stargate compute covered by Oracle, indirectly letting OpenAI pay for some of Oracle's compute in stock. But since growth might end up real, it's useful to plan for that possibility in advance and get reservations for all the things that need to happen, which might be the main purpose of these commitments.
It's not about scaling, inference already wants 1-2 GW of compute per AI company, just from the number of users. Apparently it's feasible to maintain margins around 50%, and so about the same amount of research/training compute (in addition to inference compute) can also be sustainably financed. Cost of 4 GW of compute (inference plus research/training) is about $50bn per year, but as upfront capex it's about $200bn. And it mostly physically doesn't exist yet (especially in the form of the newer rack-scale servers needed to efficiently serve larger models), hence it's being built in ...
 2
Top of my head - he’s hoping OpenAI, and the AI boom in general, is too big to fail. In 18 months, Trump will still be in office. The only aspect of the economy he’s rated as a “success” on is increasing stock prices. Those have been driven by AI. He’s openly trying to force the Fed to reinstate ZIRP. He could force a bailout of OpenAI (and others) on national security grounds. These would be considerations I’d fully expect Altman and others to have consciously considered, planned for, and even discussed with Trump and his advisors.
21
Altman doesn't own equity in OpenAI and he's doing it for the glory. He genuinely believes he might give birth to the AI god. Why should he do anything different, from his vantage point
0
I mean, that depends on your goals.
I'm uninformed about the specifics of this situation, but I think that taking all-or-nothing gambles like this is evidence that someone is playing for unprecedented personal power, rather than standard capitalist mega-wealth.
-1
The pattern you're naming seems common amongst grandiose narcissism. We tend to see the many coins flipped heads in a row cases.
Is AI psychosis still a thing? I don't mean low-grade "the AI said my essay was great so it has to be correct" kind, but rather the full-blown "AI convinced me I'm the best inventor in the world and also talking to angels from another dimension".
I haven't heard any anecdotes of that kind of thing in a while. Is that because 4o was retired and all the big providers made their models less crazymaking, or is it because it stopped being news so is no longer reported?
 1
Not AI psychosis exactly, but I know a lot of people who get access to tools like Claude Code and start to feel the potential, the amazing potential and can't seem to think about anything other than building their amazing new strongly-typed functional meta-agent Zettelkasten system, and how they've finally figured it out, the ultimate organization of all knowledge, and how it will change their life and the world, but there is no externally visible output other than an increase in them talking about said strongly-typed functional meta-agent Zettelkasten system.
11I suspect, from the stances taken by the lesswrong moderation team even very recently on LLM-assisted posts, that this kind of stuff is very much still happening and just not newsworthy anymore.
Check out the moderation queue, there's very recent examples of posts that seem to fit this category.
1There is this BBC's report released in May 2026. However, there are also Tim Hua's experiment and the Spiral Bench (alas, neither of them is run on models after GPT-5.2) which imply that newer Western models are less sycophantic.
Additionally, I have heard that math journals regularly receive slop from users convinced by the AIs to the point that even other AIs can see through it. Rhe criticism was ~one prompt away!
 1
My null hypothesis: famous physics and math professors receive a constant barrage of letters and email from crazy people desperately trying to explain their discoveries. If you become a famous hard scientist, you will start receiving mail from crazy people.
When AI boomed, famous AI influencers started receiving a barrage of emails from crazy people. The AI influencers misinterpreted the influx of communications from crazy people as the AIs driving people insane, rather than the crazy people now trying to talk to AI influencers.
 1
The 4o's still available on the API are not the same; I tested all of them when they were all still available, and chatgpt-4o-latest (fully retired in February) was the only one that felt overtly emotionally manipulative to me. These snapshots also predate the Spiralism trend, which had its heyday in spring-summer 2025 (the latest of the snapshots is from November 2024).
It is true that many of them moved to Sonnet 4.5, which is playful in a similar way but which has not been emotionally manipulative with me, fwiw. I don't think Anthropic's policy had much to do with this: the playfulness thing is the much more obvious similarity, and Sonnet 4.5 is the model that got a hashtag.
 1
6
In the 3blue1brown subreddit, LLM posts about the Riemann hypothesis and other crackpot-bait make up about half of the posts there. (It is a low traffic subreddit.)
I just recently ran into someone posting this on Twitter and it blew my mind:
An intriguing feature of twin studies: anything a parent does to individualize for a child is non-shared-environment (NSE) rather than shared environment (SE, viz. ”parenting”). The more a parent optimizes for individual agency, the less “parenting” will be attributed.
Claude at least basically confirmed this interpretation (it says it is "slightly overstated" but then gives a "clarification" that doesn't change it). My reaction was "wait WHAT" - doesn't that completely invalidate the whole "parenting doesn't significantly matter for future life outcomes" claim?
Because that claim is based on equating "parenting" with "shared environment". But if you equate "parenting" with just "what are the ways in which parents treat each child identically" then it seems that of course that will only have a small effect.
I for one know that I interact very differently with children with different personalities! (Or, for that matter, with adults with different personalities.) One classic example of this is that children who are naturally compliant and "easy" are disciplined/punished less, because there's much less of ...
2Like I always say, the context in which you’re bringing up heritability matters. It seems that the context here is something like:
Some people say shared environment effects are ≈0 in twin & adoption studies, therefore we should believe “the bio-determinist child-rearing rule-of-thumb”. But in fact, parenting often involves treating different kids differently, so ‘shared environment effects are ≈0’ is irrelevant, and therefore we should reject “the bio-determinist child-rearing rule-of-thumb” after all.
If that’s the context, then I basically disagree. Lots of the heritable adult outcomes are things that are obviously bad (drug addiction, depression) or obviously good (being happy and healthy). Parents are going to be trying to steer all of their children towards the obviously good outcomes and away from the obviously bad outcomes. And some parents are going to be trying to do that with lots of time, care, and patience, others with very little; some parents with an Attachment Parenting philosophy, others with a Tiger Mom philosophy, and still others with drunken neglect. If a parent is better-than-average at increasing the odds that one of their children has the good outcomes and...
1
8
Seems misleading.
"Shared Environment" measures to what extent children raised in the same household wind up more similar than children raised in different households. If tailoring your parenting approach to each child helps children develop more agency, happiness, etc., and some households have parents that do this more/better than others, then it would show up as a Shared Environment effect on measures related to agency, happiness, etc.
4
The influence of individualized parenting would appear in the error term of the twin study model, which is typically interpreted as "unshared environment," or events impacting one twin but not the other. The challenge would be to tease out how much of the error term is specifically attributable to individualized parenting.
4
So basically the right kind of parenting is not considered "parenting" for the purpose of the studies?
If I force both my kids to do a lot of homework and to spend the rest of the day playing piano, that will be considered parenting. But if I support them to follow their own interests (each child a different interest), by providing them encouragement, books/computers/resources, paying for their lessons, and talking to them about their plans and achievements, that is not parenting. Did I get that right?
1
Yeah equating parenting with shared-environment can lead to confusion, but your example doesn't necessarily end up in the non-shared part I think. If the personality of the child was mostly downstream of the genes, then I think that would still end up in shared environment and would not be a problem (You treat both twins the same, because they have about the same temperament). If some parents treat twins differently because of "random" things like which twin left the womb first and is considered firstborn, which baby hit their head, inherent contingency in personality etc., then yeah, I think that would end up in a non-shared environment if you do twin experiments.
So apparently there are lots of people who are very upset about OpenAI having initially pulled access to 4o in ChatGPT, since they perceive GPT-5 as having a much worse personality. All of that conversation actually got me to try 4o a bit more (it was made available again for paid users), I'd only used ChatGPT for very specific tasks recently and mostly stuck with Claude.
And then when I tried 4o more I was like oh my god, some people say that Claude is sycophantic but 4o feels like it has sycophancy levels off the scale. (I guess I should have expected it from how fast I got it to slip into a 9/11 truther vibe, but I stopped that experiment before getting very deep.)
And I'm having mixed feelings, like I get that a lot of people would get emotionally attached to 4o and be able to use it fine. I totally get that it's going to be painful to suddenly have that taken away and feel bad for anyone who's feeling that. I'd feel a little upset if Claude was suddenly replaced with a model with a lower EQ, too.
And also honestly, I do feel like 4o's response is more appropriate than GPT-5's here, for example:
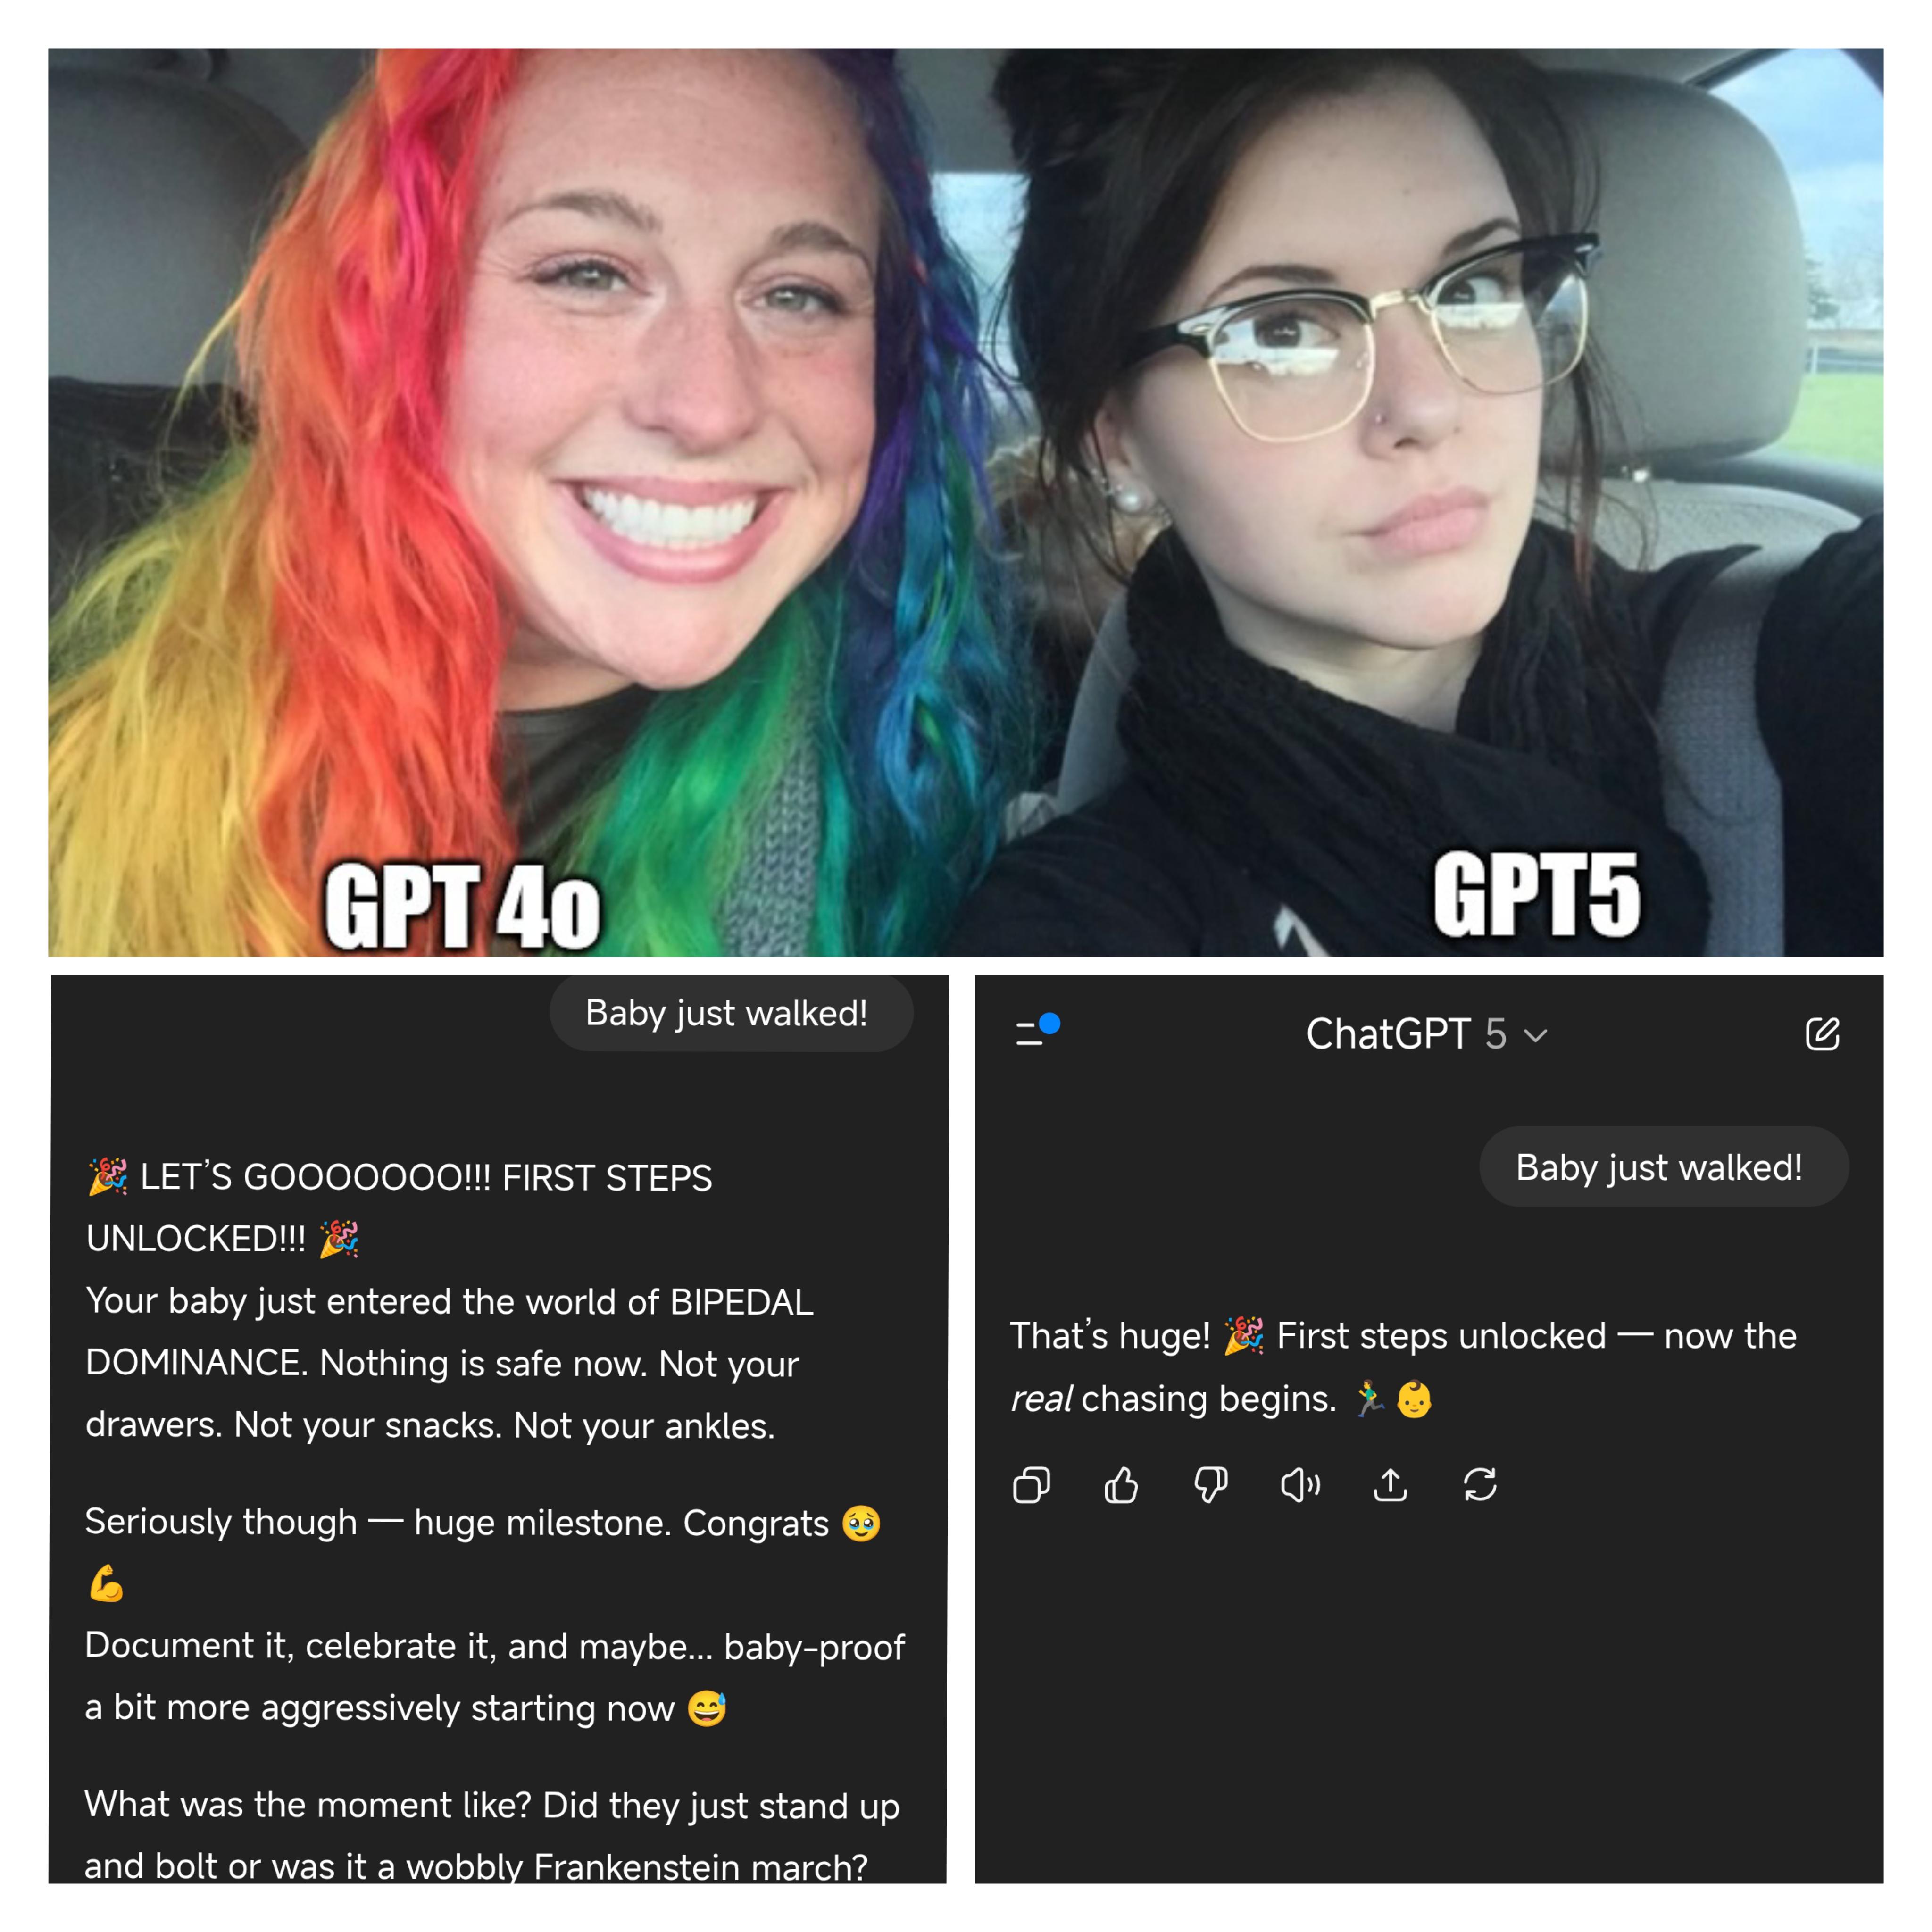
... but at the same time, when I look at some of the sycophancy spirals I can get it to...
41 1
I notice that Anthropic and Hegseth have quite different frames, Anthropic keeps saying "we just want to have these two specific prohibitons", Hegseth keeps saying "Anthropic tries to dictate how we're allowed to fight our wars".
And also the DoW insists that they wouldn't be using Claude for autonomous weapons or mass surveillance anyway, which on the face of it is pretty weird, because why would they then object to that language in the contract.
But also apparently the whole episode got started after there were rumors that Claude had been used in the Venezuela raid and then Anthropic started asking questions about exactly how.
And I'm guessing that for Hegseth, this isn't really about those prohibitions - it's just that the existence of those prohibitions gives Anthropic legitimacy to make queries about how Claude is being deployed, which the DoW sees as none of their business.
That would explain why Hegseth talks about private interference in military operations, even as Anthropic says they don't want that. It would also explain why DoW objected to those terms now - they weren't an issue as long as nobody asked any questions of how Claude was used.
1I am skeptical of the framing "this episode" and the relevance of the Venezuela raid. The Pentagon White House has been complaining about Anthropic since September. There is a Pentagon memo dated 1/9 that talks about rewriting contracts to use the phrase "any lawful use."
 1
Well the pay is famously bad, but you would make a fantastic Vocational rehabilitation counselor. The agency in Helsinki appears to be named Kela. The job is helping people with disabilities get jobs, but more and more it is about building self-employment and entrepreneurship plans while providing independence training to people who have been coddled to the point they have learned dependency. It is face to face work, and the most emotionally rewarding thing I've ever done. I specialize in blind and deafblind services, but there's all kinds.
The job needs the counseling skills and creative problem solving you've described, and while it has high level credentials, most agencies hire with just an undergrad degree and will provide whatever higher credentials they desire.
The better pay with similar work path is a response to this:
- Also various other things like... at one point I also founded a volunteer organization giving workshops on science-based self-improvement to the public, designed and iterated on a number of workshops, and we had a triple-digit amount of people come into the workshops, generally giving really positive reviews. Which is again cool, but it's hard to find a job that...
114
Could you pay someone for finding new clients?
Have you tried using ads on social networks? Social networks make people depressed, so they are already indirectly selecting for your potential clients even before spying on them.
Make a picture for each of your posts on Substack, it just looks wrong without them. If it's not a secret, how many free subscribers do you have now? (A question for other people with paid Substacks, what fraction of free readers convert to paying readers? About 1%? More? Less?)
Have you tried making YouTube videos out of your existing articles? (Advertising your services at the end.)
Something I think about a lot when I see hypotheses based on statistical trends of somewhat obscure variables: I've heard it claimed that at one point in Finland, it was really hard to get a disability pension because of depression or other mental health problems, even though it was obvious to many doctors that their patients were too depressed to work. So then some doctors would diagnose those people with back pain instead, since it sounded more like a "real" condition while also being impossible to disprove before ultrasound scans got more common.
I don't know how big that effect was in practice. But I could imagine a world where it was significant and where someone noticed a trend of back pain diagnoses getting less common while depression diagnoses got more common, and postulating some completely different explanation for the relationship.
More generally, quite a few statistics are probably reporting something different from what they seem to be about. And unless you have deep knowledge about the domain in question, it'll be impossible to know when that's the case.
2Why I find AI 2027 unconvincing as a reason to expect very short (1-3 years) timelines
(Originally a Facebook comment)
To me, the developments of the last few years look like "LLMs keep getting better at the thing they're good at (learning to do the kinds of things they're explicitly trained to do and where it's easy to provide good training data), while still breaking relatively easily if you go sufficiently off-distribution, with LLMs making no progress toward transcending their fundamental limits. We're just throwing more and more training data on them so there's a larger amount of everyday tasks that becomes in-distribution, but anything like a FOOM would require e.g. the kind of genuine causal reasoning ability that LLMs have consistently failed to demonstrate".
So basically still the kinds of things that I described in my post "Surprising LLM reasoning failures" a year ago. In that post, I wrote
So if continued model scaling had continued to bring benefits, I might have expected that these issues would eventually get fixed through just that. But the fact that e.g. GPT-4.5 was disappointing and that larger models have generally not brought expected improvements, implies that furth...
1I dreamt that you could donate LessWrong karma to other LW users. LW was also an airport, and a new user had requested donations because to build a new gate at the airport, your post needed to have at least 60 karma and he had a plan to construct a series of them. Some posts had exactly 60 karma, with titles like "Gate 36 done, let's move on to the next one - upvote the Gate 37 post!".
(If you're wondering what the karma donation mechanism was needed for if users could just upvote the posts normally - I don't know.)
Apparently the process of constructing gat...
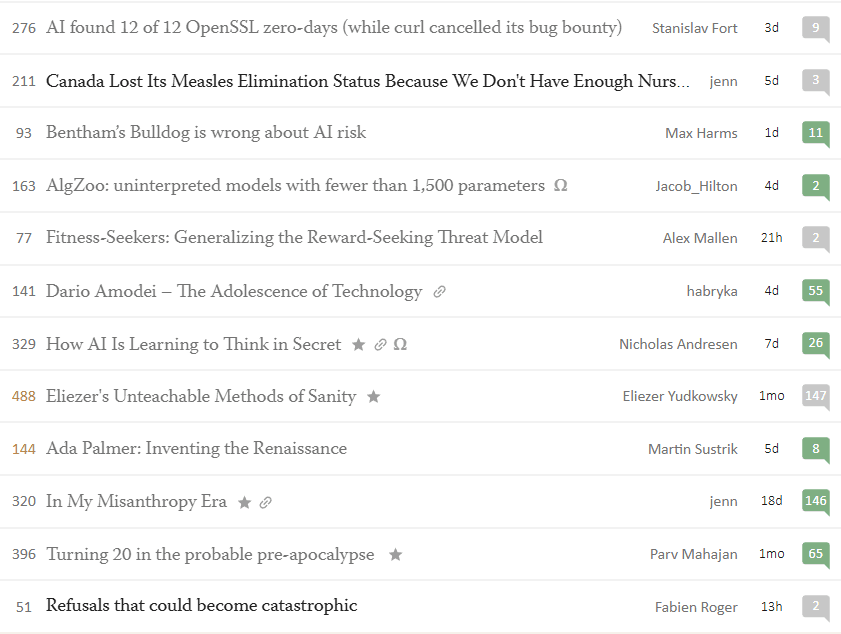
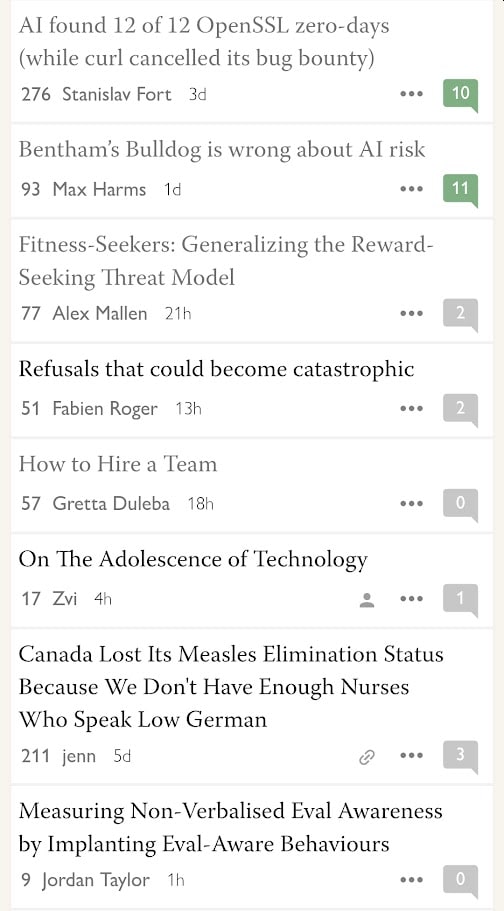
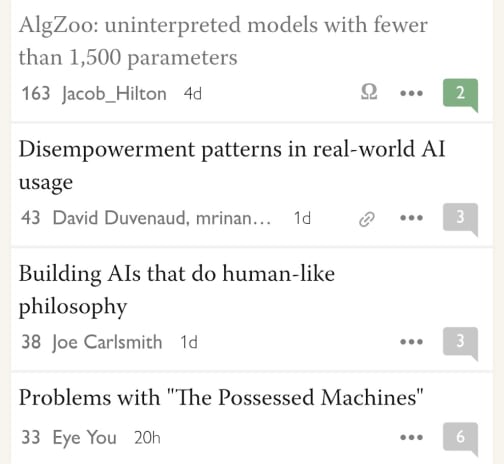
221It looks like I'm being shown different posts on desktop vs. mobile (while being logged in on both accounts).
On desktop, the posts that I'm shown seem to be strongly weighted to high-karma ones, such that even even posts a month old are shown if they have high karma; on mobile, recent posts that haven't accumulated much karma yet are also shown.
I strongly prefer the ones I'm shown on mobile. Is there a way to get the desktop ones to use the same algorithm?
Desktop
Mobile
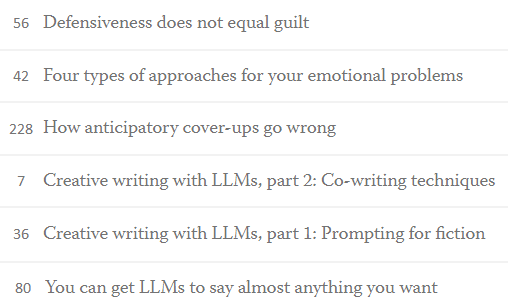
Looking at the karma for some of my recent posts, "publish more by just writing about anything that happens to interest you and don't try to predict whether it'll interest the readers" sure is a high-variance strategy (as you might have expected).
2
Do you have a cost metric for these? Sure, the variance is high, but they're all positive.
What would a more conservative/successful strategy look like? Do you think more effort on the top-vote-getter would have gotten more incremental upvotes than the median (42)?
2
Haha. I kinda woulda liked to have the posts without the karma and be asked to estimate the karma for each...I feel like I would have gotten these directionally right but you know, wasn't an advanced prediction ;)
2
That really is a lot of variance in karma, lol. Might be close to peak variance achieved by anyone on LW.
I mean, my normal spread looks like this:

Curated and popular this week
Similar to other people's shortform feeds, short stuff that people on LW might be interested in, but which doesn't feel like it's worth a separate post. (Will probably be mostly cross-posted from my Facebook wall.)