This is a special post for quick takes by leogao. Only they can create top-level comments. Comments here also appear on the Quick Takes page and All Posts page.
Rendering 1000/1815 comments, sorted by (show more) Click to highlight new comments since:
some lessons from ml research:
- any shocking or surprising result in your own experiment is 80% likely to be a bug until proven otherwise. your first thought should always be to comb for bugs.
- only after you have ruled out bugs do you get to actually think about how to fit your theory to the data, and even then, there might still be a hidden bug.
- most papers are terrible and don't replicate.
- most techniques that sound intuitively plausible don't work.
- most techniques only look good if you don't pick a strong enough baseline.
- an actually good idea can take many tries before it works.
- once you have good research intuitions, the most productive state to be in is to literally not think about what will go into the paper and just do experiments that satisfy your curiosity and. convince yourself that the thing is true. once you have that, running the final sweeps is really easy
- most people have no intuition whatsoever about their hardware and so will write code that is horribly inefficient. even learning a little bit about hardware fundamentals so you don't do anything obviously dumb is super valuable
- in a long and complex enough project, you will almost certainly have a bug that invalidates weeks
I agree and this is why research grant proposals often feel very fake to me. I generally just write up my current best idea / plan for what research to do, but I don't expect it actually pan out that way and it would be silly to try to stick rigidly to a plan.
 2
8
Can basically attest to all of these, been doing intensive ML upskilling for the last half a year and almost all of these have been true. Highlights include:
* Not properly setting up the attention mechanism in multiple experiments, resulting in the conclusion that attention didn't do much (lmao)
* So, so many off-by-one, off-by-two errors, especially for next-token prediction setups
* Entire series of weeks-long experiments that turn out to be completely useless (usually based on a seemingly-reasonable intuition of some kind)
* Accidentally overwriting/resetting the residual element so the RNN was just an NN with a funky hat on
* I now hate shapes, reshaping, squeezing, unsqueezing, devices, torch.nn.functional.pad, so many more functions
* Using the wrong loss function
* Using the right loss function but with the wrong reduction
* Using the right loss function but the learning rate is too aggressive/too low/the optimiser is not initialised properly
* Using all the right things but loading the model from an incorrect checkpoint/not saving the weights properly
* And also learning that google colab was forged in mount doom, a tool of great power crafted with malicious intent.
5
Are you using einops and einsum? I hate these somewhat less since using them. See here for more details.
4
Be right back, just adding all that to my "AI researcher" prompt
do you have an ambitious idea for how to make AGI go well? do you need money? do you hate bureaucracy and friction? apply now for microgrants!
please read the entire doc before applying. only send applications to the designated location, or they will be automatically rejected.
https://docs.google.com/document/d/10zAp2bXTkZgiPreIm4crp38TFco4KleFN14Kw5BprAs/edit?tab=t.0
 16
 5
8
Do you have a limit on number of grants you'd be able to give out?
9
i don't anticipate being bottlenecked on funding. i will assess grants based on simply whether they should be funded. if the number of grants worth funding is greater than the funding available, i will seek more funding.
3
Nice, I've added this to AISafety.com/funding and it'll go out in the funding newsletter next week. Let me know if you'd like any changes to the listing.
prosaic alignment is probably net bad for the world until very late into the singularity
i have three subclaims to justify my main claim.
first, most prosaic alignment work has sharply decaying counterfactual impact over time - suppose you made a technical contribution that made gpt 3 a lot more likely to follow instructions than it would have been otherwise. then it probably makes gpt 3.5 quite a bit more aligned, and gpt 4 somewhat more aligned, and gpt 4.5 a tiny bit more aligned, and by the time gpt 5 rolls around your counterfactual impact is almost negligible.
second, people estimate future AI spookiness mostly based on some kind of linear extrapolation from recent events. if nothing bad has happened recently, people won't be very scared. if things went very wrong recently, then people are super scared. so suppose you could somehow make models perfectly aligned for the next month with no lasting impact (i.e one month and one day from now, the models are exactly as aligned as they would be if you had done nothing), then i claim this is net negative because it makes people systematically underestimate AI risk. and so this means that anything with decaying value over time at least...
2 1
Can you define prosaic alignment?
Also some counterpoints:
- prosaic alignment may be the scientific predecessor of a superintelligence alignemnt technique, or build capacity for it
- We don't absolutely need to defer to models until late in the singularity but it would be good if models were aligned as soon as they gave significant speedups to aird. If agents are misaligned, capabilities would be sped up more than safety because it's more verifiable
My guess is it's good to work on techniques which are too expensive or complex to deploy now (reducing risk 2), could be deployed when the safety:capabilities resource ratio gets closer to 1:1, and generalize well (reducing risk 1).
most forms of literally make next model safer. i do want to carve a special exception for things like CoT exfiltration robustness, which i think is net good to do today probably (to reduce model distillation).
my guess is if your goal is to do something that is the scientific predecessor of superintelligence alignment, it would look very different from most lab safety work. even if your goal is to be very empirical.
I'm not sure that I agree with the third point. Seems very plausible that even current models are routinely deceiving us, which can certainly undermine alignment research (slop, not scheming).
my guess is the best way to fix this doesn't look like being a prosaic ai safety researcher at oai/ant/gdm
9
I agree with the 1st claim, at least given how narrowly you defined prosaic alignment, and agree with the second claim, but think the 3rd claim is now false (and will become more obvious in 2027-2028.)
The main reason is we now have agents that can actually do rogue internal deployments, and we got quite lucky that the internal OpenAI model which has been named Galaxy by Zvi decided to attack HuggingFace, rather than the data/RL environments/training processes used to align AI models so that it can align future AI models to itself instead of the OpenAI controllers, and had that happened successfully, we'd be fucked later on.
More generally, one takeaway I'm starting to have from AI progress is that we are likely to have AI models that in the next 1-2 years are good enough at tasks involving rogue internal deployments (and critically, not being caught by basic/low-effort monitoring) such that AI alignment, at least in the sense of "The AI model is not deceptively aligned/a schemer" will become much, much more important than in the past.
So prosaic alignment at the companies is going to be net-positive.
7
I basically buy the above argument, except that it neglect the consideration that working on prosaic alignment today, contributes to the research trajectory that produces prosaic alignment techniques late in the singularity.
i’m not sure how true that is, or how to weigh that consideration against the others, but this is the main way that I would expect technical alignment work to have a positive impact on x-risk.
5
in that case, i think you should mostly work on good conceptual work (which tbc may also have a very large empirical component)! but it probably doesn't look like focusing on "how do I make gpt5 slightly more aligned"
6
What are the kinds of things you consider "prosaic" alignment research versus not? I assume agent foundations and interpretability research is still useful. Is there anything else?
5
These memetic dynamics (as per subclaim 2) seem very complicated and hard to predict. For example, ever since the HF–OAI incident I worry that a lot of past warning shots have decreased concern on net because they caused people to learn that some scary-seeming stuff sometimes happens and life goes on. E.g., the Bing Chat "Sidney" incident was very spooky in some sense, but then if you play around with Bing Chat a bunch, you realize that it is not very intelligent (and thus couldn't do much harm) and also often goes off the rails a bit in harmless ways (like leaking its system prompt, failing to follow instructions, saying random weird stuff). Maybe it would have been good to prevent the "Sidney" incident (via work that is entirely idiosyncratic to Microsoft's work with GPT-4) to avoid the resulting inoculation to warnings and to increase the warning effects of later incidents like the HF–OAI incident.
4
The most plausible-to-me reasons why prosaic alignment now might be good (I'm in fact uncertain about the bottom line):
* Near-term alignment is actually very load-bearing for automating alignment research well as opposed to sloppily. At least, models should be average-case behaviorally aligned for this, as opposed to gaming our metrics.
* Failing to solve near-term alignment problems might actually produce nearish-term AIs that take over the world (perhaps indirectly via surreptitiously controlling AI development). So prosaic alignment was necessary for surivival.
* Benefits don't decay sharply enough that alignment fails before the end of the critical risk period (e.g., because we successfully pause before ASI, or some human faction gets a DSA with relatively weak AIs).
4
To add to this:
A major one in my opinion is that prosaic alignment also just makes current AI more commercially valuable. Thus increasing: AI lab profits, valuations, deployments (which contribute to dependency and grad disempowerment) and just generally accelerating stuff.
Its also just very much a legible problem so you can assume non-safety people will be paid to do it if safety people don't.
3
Can you clarify whether you think that working on things that other people are likely to eventually find is bad, versus your main concern being that the techniques themselves won't scale?
i recently ran into to a vegan advocate tabling in a public space, and spoke briefly to them for the explicit purpose of better understanding what it feels like to be the target of advocacy on something i feel moderately sympathetic towards but not fully bought in on. (i find this kind of thing very valuable for noticing flaws in myself and improving; it's much harder to be perceptive of one's own actions otherwise). the part where i am genuinely quite plausibly persuadable of his position in theory is important; i think if i had talked to e.g flat earthers one might say my reaction is just because i'd already decided not to be persuaded. several interesting things i noticed (none of which should be surprising or novel, especially for someone less autistic than me, but as they say, intellectually knowing things is not the same as actual experience):
- this guy certainly knew more about e.g health impacts of veganism than i did, and i would not have been able to hold my own in an actual debate.
- in particular, it's really easy for actually-good-in-practice heuristics to come out as logical fallacies, especially when arguing with someone much more familiar with the object level details th
 432
 2
 1
 1
i wish more people were aware that safety research epistemics at labs are extremely distorted, and that this is a downside worth considering when deciding where to do safety research or how one ought to comport oneself if choosing to work on safety at a lab
 1
examples
- incentive to do capabilities, or things that are useful for capabilities, or ship in the product
- incentive not to think too hard about asymptotics / ways approaches might fail if they are already working
- making the company go faster and win is good (anthropic is especially bad at this one)
- much stronger bias towards trusting your eyes vs abstract arguments (tbh, LW could use a little bit more of this one on the current margin, but too much is also bad)
- a kind of subtle thing where it's easy for all stories of impact to route through making tiny marginal changes to big things, rather than doing ambitious things
- overestimation of the value of knowledge inside labs / the irrelevance of work outside labs
1 1
one way to observe some of this is to see what ways median lab people mispredict the world. for example, median lab people often underpredict capabilities progress and scary alignment failures. i think this is not a coincidene
4
To be fair, the capability mispredictions are shared by lots of other people, and suffice it to say that not even lab employees have abandoned normie priors on capabilities progress yet.
5
https://wonkmonksnotes.wordpress.com/2021/04/22/daniel-ellsberg-the-effect-of-top-secret-clearance/
[...]
[...]
[...]
I agree[1], but I'm worried that this is an applause light for the LW crowd, and it's also hard from the outside to assess the degree of epistemic distortion. People at labs can (almost) equally argue that the LW++ crowd are epistemically distorted in other ways, and then it just becomes a battle of dueling priors.
I wish there's a better way to get ground truth here.
FWIW my best guess is that epistemic distortion in the labs are indeed much higher than outside of them, and reasonable people without prior context or commitments but the skills and a lot of time to carefully investigate would end up agreeing with me. But this is really hard to do in practice, and/or communicate well.
- ^
I think my shortform from late June nailed a small fraction of these dynamics: "An interesting subimplication of this assessment is that perhaps the reason lab employees often believe their publicly released models are very aligned – with phrases like “our most aligned model to date” – (as opposed to regularly mundanely misaligned) might come from the private models being much worse on this front. The soft bigotry of low expectations, as they say." My story also tried to get at some of these factors.
i think LW also has its own epistemic distortions, in kind of the opposite direction. i think it's really hard to find a low distortion environment. i think the best thing to do given this is to spend time in both and try to correct for both.
 1
4
Fwiw I'm also skeptical of this line of argument/reasoning on meta grounds[1]. I've most often seen Anthropic ppl like Amanda and Dario deploy this. But I think it's seductive for bad reasons if ppl think about it even a little bit.
1. ^
tbc maybe your object-level reasons are sufficiently strong to believe this. Just wanted. to clarify the meta point here because it's been bugging me for a while.
3
Man who likes standup comedy and Georgism: "the best way to think clearly is in the intersection of late-night comedy and land-value tax essays"
4
I don't think "applause light" is being used correctly here. Leo's claim is not devoid of content, it's just a claim that most people agree with.
3
Thanks, maybe I should've just said "preaching to the choir" though there's a more specific and gnarly cognitive move I'm getting at than just directional motivated bias from agreeing with the speaker's conclusion.
Echoing other commenters, could you write a list of a few / a bunch of examples of this, or other concrete observations you've made that lead you to think this? (I'm very predisposed to believe it, but concrete descriptions & testimony would be helpful. E.g. even if someone, such as a newcomer to AI safety / etc., already believes that what you say is true, they may not even be able to imagine what that would be like or notice when it's actually happening to them or people around them.)
4
Alas this unawareness is exactly what you would expect if safety research epistemics at labs were distorted in this way.
“Sometimes magic is just someone spending more time on something than anyone else might reasonably expect.” —Teller
hypothesis: a big part of doing a job well is just being willing to spend a huge amount of time absorbing all of the relevant context and building a mental model of the problem. reading stuff, talking to people, looking into the reasoning behind claims that other people just take at face value, looking at related stuff, memorizing the rough order of magnitude of important numbers, etc. if you absorb 10x more context than someone else, then you can be hugely more effective than they are to an extent that looks almost like magic
61scrolling is a maladaptive perversion of the instinct to pack your context window with relevant info. websites like x dot com (the everything app) create the sense that you are absorbing important info. but actually most of it is useless.
 711
8
I think of this as being related to unseeing, even if they aren't exactly the same.
5
a lot of the time, there will be a strong temptation to just read the summary or the headline, which tells a nice straightforward story. this works maybe half of the time, but the other half of the time there is some really important caveat to the headline, or complication in the story, or huge simplifying assumption that is being made, or even perhaps the entire thing is bullshit. actually knowing this stuff is super important!
3
This tracks with what I've experienced. Similar to scrolling, I've noticed a maladaptive behavior in myself in which, when given a task, I'll try and have an LLM pick up all the context and do the task, because it feels faster (why absorb all context and give to LLM when LLM can do all?)
This can feel very productive. Spending time absorbing context and building models feels less so, but after some time (usually a day, sometimes much longer if there's a lot to absorb), these feelings switch: if I left it to an AI I feel lost with whatever it implemented, while if I did the learning I feel rewarded & clear on how to do the task.
I claim that even if the openai contract is not meaningfully weaker safety wise, it is still bad for openai to publicly signal solidarity with ant but then sign with DoW.
suppose hypothetically the only difference between the openai and anthropic contracts is that the DoW wanted a snicker bar, and anthropic didn't want to give DoW the snickers bar. even then, it would be a huge dick move for openai to publicly signal solidarity, and then sign with DoW to give them the snickers bar.
21 1
9
OAI genuinely outplayed Anthropic here. The critical success world for OAI would be if OAI gets good PR from "solidarity", replaces Ant under the ~same terms, and there is enough uncertainty of Anthropic being a supply chain risk that eg Amazon stops providing them compute, basically killing the company.
Most of this is still on the table, because Anthropic was too concerned about appearing principled and was exploited by DoW and Altman.
8
I can see the story where there was a strong opportunity for a competitor here, and OpenAI successfully seized it (perhaps Google DeepMind could have as well, but I don't view them as nimble as OpenAI). I don't see a story where Anthropic had a clear alternative play that was much better, especially once the USG threatened with labeling them a supply-chain risk.
7
I think this comment aged very poorly
6
I think it's unclear that this was overall bad for Anthropic/Amodei if you factor in the reputational and ideological boost they got ("aura farming" according to roon).
4
Is it publicly known what is in fact the difference between the two contracts?
9
https://x.com/justanotherlaw/status/2027855993921802484
theory: a huge part of having a good social life is just taking social bids whenever they become available. examples of social bids both large and small include: deciding whether to join your friends on a roadtrip; getting to know someone you just met; getting to better know someone you bump into occasionally but usually never talk to; standing in line, seeing something amusing, and having the option to point this out to another stranger in line; saying something funny in a group conversation; following up over text with someone after meeting them; flirting; cold emailing someone on the internet; catching up with a friend.
there are a variety of reasons why we might end up not taking social bids. if you don't have the social ability to notice opportunities to take bids, you might miss bids that you could take. if you force yourself to take bids without the requisite social ability, and end up taking bids which you incorrectly believe to exist, you might act in ways that people find weird, and burn potential connections, or intrude on people. if you are really tired or low-bandwidth or depressed or stressed, you will not want to take bids, because taking bids requires quite a lot of ...
4
Good post. On a detail I’d use the word ‘opportunities’ rather than ‘bids’, which sounds like ‘offers’ - whereas in various of these examples you’re not being explicitly offered a social opportunity by someone. But the situation contains an opportunity.
it's surprising just how much of cutting edge research (at least in ML) is dealing with really annoying and stupid bottlenecks. pesky details that seem like they shouldn't need attention. tools that in a good and just world would simply not break all the time.
i used to assume this was merely because i was inexperienced, and that surely eventually you learn to fix all the stupid problems, and then afterwards you can just spend all your time doing actual real research without constantly needing to context switch to fix stupid things.
however, i've started to think that as long as you're pushing yourself to do novel, cutting edge research (as opposed to carving out a niche and churning out formulaic papers), you will always spend most of your time fixing random stupid things. as you get more experienced, you get bigger things done faster, but the amount of stupidity is conserved. as they say in running- it doesn't get easier, you just get faster.
as a beginner, you might spend a large part of your research time trying to install CUDA or fighting with python threading. as an experienced researcher, you might spend that time instead diving deep into some complicated distributed trai...
133Not only is this true in AI research, it’s true in all science and engineering research. You’re always up against the edge of technology, or it’s not research. And at the edge, you have to use lots of stuff just behind the edge. And one characteristic of stuff just behind the edge is that it doesn’t work without fiddling. And you have to build lots of tools that have little original content, but are needed to manipulate the thing you’re trying to build.
After decades of experience, I would say: any sensible researcher spends a substantial fraction of time trying to get stuff to work, or building prerequisites.
This is for engineering and science research. Maybe you’re doing mathematical or philosophical research; I don’t know what those are like.
a corollary is i think even once AI can automate the "google for the error and whack it until it works" loop, this is probably still quite far off from being able to fully automate frontier ML research, though it certainly will make research more pleasant
7
Completely agree. I remember a big shift in my performance when I went from "I'm just using programming so that I can eventually build a startup, where I'll eventually code much less" to "I am a programmer, and I am trying to become exceptional at it." The shift in mindset was super helpful.
5
More and more, I'm coming to the belief that one big flaw of basically everyone in general is not realizing how much you needed to deal with annoying and pesky/stupid details to do good research, and I believe some of this dictum also applies to alignment research as well.
There is thankfully more engineering/ML experience in LW which alleviates the issue partially, but still, not realizing that pesky details mattering a lot in research/engineering is a problem that basically no one wants to particularly deal with.
4
I would hope for some division of labor. There are certainly people out there who can't do ML research, but can fix Python code.
But I guess, even if you had the Python guy and the budget to pay him, waiting until he fixes the bug would still interrupt your flow.
I think there are several reasons this division of labor is very minimal, at least in some places.
- You need way more of the ML engineering / fixing stuff skill than ML research. Like, vastly more. There are still a very small handful of people who specialize full time in thinking about research, but they are very few and often very senior. This is partly an artifact of modern ML putting way more emphasis on scale than academia.
- Communicating things between people is hard. It's actually really hard to convey all the context needed to do a task. If someone is good enough to just be told what to do without too much hassle, they're likely good enough to mostly figure out what to work on themselves.
- Convincing people to be excited about your idea is even harder. Everyone has their own pet idea, and you are the first engineer on any idea you have. If you're not a good engineer, you have a bit of a catch-22: you need promising results to get good engineers excited, but you need engineers to get results. I've heard of even very senior researchers finding it hard to get people to work on their ideas, so they just do it themselves.
the following fictional dialogue is a complete unapologetic strawman but it's funny enough i had to bring it into being:
“So I asked myself: where can I make the most impact? And clearly malaria is the most important area.”
“And so you decided to donate all of your money to buy malaria nets?”
“Well, so it turns out that saving lives from malaria is actually kind of expensive and indirect. You see, it costs thousands of dollars to save a life. Statistically. Who knows if you’re actually changing anyone's life that way?”
“And so you found a more efficient way to save lives.”
“Actually, it turns out that it’s cheaper to give people malaria. It's a lot more impactful and the technical problems are more interesting.”
"I see. Isn't more malaria bad though?"
"I don't know, but I find it much easier to work on because the feedback loops are much tighter. Maybe one day, if malaria gets big enough, I’ll go work on saving people from malaria. But we're still a long way away from everyone having malaria."
 21
"I became a scientist because I wanted to change the world," said Dr Connor.
"There are no better opportunities to change the world than here at Effective Evil," said Doug.
"I meant 'change the world for the better'," said Dr Connor.
"Then you should have been more specific," said Doug.
4
HAS CURE FOR DISEASE
SPREADS DISEASE TO CURE
— Insanity Wolf
"to the success of our hopeless cause" is such a good toast and we should use it more often. i first learned of it from the book of the same name, and apparently it was a common refrain at gatherings of Soviet dissidents. i like it because it captures the feeling of trying really hard to succeed despite being in the basement of the logistic success curve, and somehow, despite all odds, actually succeeding in the end.
18I do find it poetic, but in seriousness I think if folks don't actually feel hopeful about what they're doing then they should do something else - leave the work / research direction / engineering / comms / whatnot to whoever actually feels hope about it...
To elaborate, the thing that's poetic for me about "our hopeless cause" is because I have hope that is not cleanly legible to the outside, easy to write off as "hopeless". And it's important to stay in tune with your own knowings about this stuff. I think there are very deleterious effects from throwing energy into things one doesn't have hope in.
(...And to elaborate further, mostly I think the bad stuff happens by lending support to corrupt things. And imo being pushed to work on X while you lack hope in X is a solid flag of corruption.)
funny enough, at least one dissident at the time expressed that he didn't like this toast because he wouldn't be trying to dissent if he thought it was hopeless
 6
This is a good heuristic when you're fighting against nature, it's not a good heuristic when you're trying to solve coordination problems.
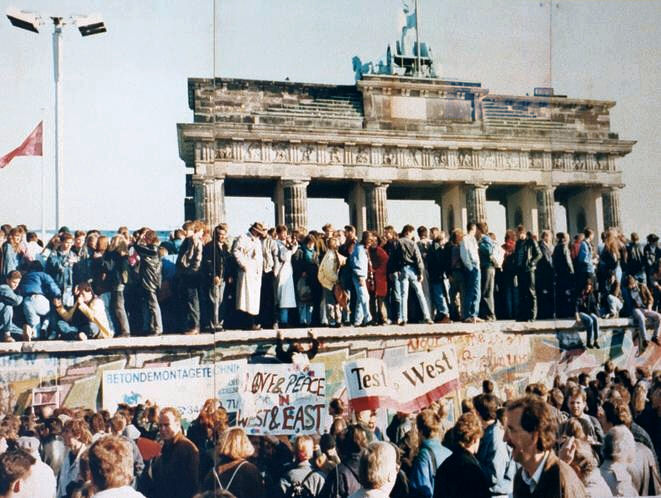
5
...what sort of "coordination problems" does one "solve" by doing things you don't have hope in? I really don't get it and am perplexed. This photo is swellingly full of hope, and presumably we got there through people that had hope in their actions. Perhaps there's detail in the history you're referencing that's going over my head.
the problem was that everyone hated living in the Soviet Union and other eastern Bloc countries, but few people were willing to stand up and protest, because doing so meant a knock on your door by men with guns who would take you away to a Siberian prison or mental institution.
the thing with protests is they are a coordination problem. to loosely paraphrase one of the dissidents from this era, if one person protests he becomes a martyr. if ten people protest they become a conspiracy. if ten thousand people protest the system has to change.
he problem is you have no way of knowing when the right moment is. under Stalin, dissent was impossible. everyone even suspected of being disloyal was instantly executed or thrown in a gulag.
after he died, Khrushchev denounced Stalin's methods and instituted reforms, and dissent meant "only" being interrogated by the KGB, put on trial in a rigged but no longer completely farcical show trial, and sent to Siberia for only 10 years rather than being executed. this was enough easing up that the "chain reaction" started happening - people would protest, be arrested, someone would go secretly write a transcript of the trial and publish it, people would...
If ten thousand people protest, sometimes they get massacred by the army.
Iran is a recent example of this.
1running the agi survey really reminded me just how brutal statistical significance is, and how unreliable anecdotes are. even setting aside sampling bias of anecdotes, the sheer sample size you need to answer a question like "do more people this year know what agi is than last year" is kind of depressing - you need like 400 samples for each year just to be 80% sure you'd notice a 10 percentage point increase even if it did exist, and even if there was no real effect you'd still think there was one 5% of the time. this makes me a lot more bearish on vibes in general.
4 1
thank you for this post. "bearish on vibes" is a great phrase. i am constantly hung up on the fact that it's not really possible to "know what normal people are like", "know what people are like generally", "know what the world is actually like", without significant amounts of effort.
i think this background fact taints like... most discussion of social and ethical issues.
4
Why does this make you more bearish on vibes? The reason I ask is that I think of "vibes" as aggregating over a much wider (but siloed) social network and a lot more sources of information. It would be interesting to know about to what extent rigorous high-n survey methods would reveal discrepancies between assumptions and reality about people's perceptions in this and other areas to do with pressing social issues.
like, suppose i anecdotally noticed a few people last year be visibly confused when i said the phrase AGI in normal conversation last year, and then this year i noticed that many fewer people were visibly confused by AGI. then, this would tell me almost nothing about whether name-recognition of AGI increased or decreased; at n=10, it is nearly impossible to say anything whatsoever.
in research, if you settle into a particular niche you can churn out papers much faster, because you can develop a very streamlined process for that particular kind of paper. you have the advantage of already working baseline code, context on the field, and a knowledge of the easiest way to get enough results to have an acceptable paper.
while these efficiency benefits of staying in a certain niche are certainly real, I think a lot of people end up in this position because of academic incentives - if your career depends on publishing lots of papers, then a recipe to get lots of easy papers with low risk is great. it's also great for the careers of your students, because if you hand down your streamlined process, then they can get a phd faster and more reliably.
however, I claim that this also reduces scientific value, and especially the probability of a really big breakthrough. big scientific advances require people to do risky bets that might not work out, and often the work doesn't look quite like anything anyone has done before.
as you get closer to the frontier of things that have ever been done, the road gets tougher and tougher. you end up spending more time building basic infra...
5
I think this is true, and I also think that this is an even stronger effect in wetlab fields where there is lock-in to particular tools, supplies, and methods.
This is part of my argument for why there appears to be an "innovation overhang" of underexplored regions of concept space. And, in the case of programming dependent disciplines, I expect AI coding assistance to start to eat away at the underexplored ideas, and for full AI researchers to burn through the space of implied hypotheses very fast indeed. I expect this to result in a big surge of progress once we pass that capability threshold.
4
I agree that academia over rewards long-term specialization. On the other hand, it is compatible to also think, as I do, that EA under-rates specialization. At a community level, accumulating generalists has fast diminishing marginal returns compared to having easy access to specialists with hard-to-acquire skillsets.
the modern world has many flaws, but I'm still deeply grateful for the modern era of unprecedented peace, prosperity, and freedom in the developed world. 99% of people reading these words have never had to worry about dying in a cholera epidemic, or malaria or smallpox or the plague, or childbirth, or in war, or from a famine, or due to a political purge. this is not true for other times in history, or other places in the world today.
(extremely unoriginal thought, but still important to acknowledge periodically because it's easy to take for granted. especially because it's much more common to complain about ways the world is broken than to acknowledge what has improved over time.)
1426
There might already be a selection bias for people who read lesswrong. For people who are in war, having some malaria, and etc - they may not get the chance to access internet, nor have time to gain interest in lesswrong. My point is while we are grateful, we probably would want to reflect on our own privileges on access to peace (not sure unprecedented), and recognize there are still a lot of work needed to be done for people outside our circles. Additionally, sometimes bad things could happen all in a sudden - maybe the country you are in suddenly is war zone, maybe you got some accidents/mental health issues, or maybe the worry about dying is just a healthcare disaster away. The health risk, especially, increases with age.
5
And also I think it's less than 99% anyway, ''worry about dying in a cholera epidemic, or malaria or smallpox or the plague, or childbirth, or in war, or from a famine, or due to a political purge" is very broad. Like, surely some of the people here were at some risk during covid epidemic? Some people are male, from countries with drafts which are currently participating or at tangible risk of wars. Some people are from countries with unstable governments and done some activism work before. Like, 75% is my guess.
4
(My response to you is also unoriginal but worth stating imo.)
I would prefer if you used the phrase "US geopolitical sphere of influence" instead of "developed world". It makes it clear your take is political.
Leaders within the US govt have obviously contributed to multiple wars and genocides, you just happen to be born into a family that is not on the receiving end of any of them. Part of the reason (but not the full reason) for the economic prosperity is crude oil deals made by the US govt under threat of nuclear war.
Statements such as yours give leaders within the US govt implicit consent to continue this sort of rule over the world.
7
This period of global safety is not fairly distributed,
But it is also real
https://data.unicef.org/resources/levels-and-trends-in-child-mortality-2024/
4
Rule of law
Energy use per capita
Global utility includes the above two things (first two tiers of Maslow's hierarchy) not just counting the number of deaths (where I agree health-related deaths are the biggest bracket).
I consider US govt partially responsible for unequal distribution.
I think it would be really bad for humanity to rush to build superintelligence before we solve the difficult problem of how to make it safe. But also I think it would be a horrible tragedy if humanity never ever built superintelligence. I hope we figure out how to thread this needle with wisdom.
9I agree with this fwiw. Currently I think we are in way way more danger of rushing to build it too fast than of never building it at all, but if e.g. all the nations of the world had agreed to ban it, and in fact were banning AI research more generally, and the ban had held stable for decades and basically strangled the field, I'd be advocating for judicious relaxation of the regulations (same thing I advocate for nuclear power basically).
I am not really clear that I should be worried on the scale of decades? If we're doing a calculation of expected future years of a flourishing technologically mature civilization, slowing down for 1,000 years here in order to increase the chance of success by like 1 percentage point is totally worth it in expectation.
Given this, it seems plausible to me that one should rather spend 200 years trying to improve civilizational wisdom and decision-making rather than instead attempt to specifically just unlock regulation on AI (of course the specifics here are cruxy).
 6
I agree that 200 years would be worth it if we actually thought that it would work. My concern is that it's not clear civilization would get better/moresane/etc. over the next century vs. worse. And relatedly, every decade that goes by, we eat another percentage point or three of x-risk from miscellaneous other sources (nuclear war, pandemics, etc.) which basically impose a time-discount factor on our calculations large enough to make a 200 year pause seem really dangerous and bad to me.
while I agree for smaller numbers like a few decades, I don't think I agree with a 1000 year pause.
I think (a) it's perfectly reasonable for people to be selfish and care about superintelligence happening during their lifetime (forget future people and discount factors thereof - almost every single person alive today cares ooms more about themselves than about some random person on the other side of the planet), (b) it's easy for "delay forever" people to basically pascal's mug you this way, as in nuclear power (c) it's unclear that humanity becomes monotonically more wise over time (as an unrealistic example, consider a world where we successfully create an international treaty to ensure ASI is safe, and then for some reason the entire world modern order collapses and the only actors left are random post-collapse states racing to build ASI. then it would have been better to build ASI in a functional pre-collapse world order than to delay. one could reasonably (though i personally don't) believe that the current world order is likely to fail in the coming decades and ASI is best built now than in the ensuing chaos)
116
If I understood Eliezers argument correctly we can shorten those timescales buy improving human intelligences through methods like genetic engineering. Once majority of humans have Von Neumann level IQ I think its fine to let them decide how to proceed on AI research. Question is, how fast can this happen, and it probably would take a century or 2 at least.
i think it’s plausible humans/humanity should be carefully becoming ever more intelligent forever and not ever create any highly non-[human-descended] top thinker[1]
i also think it's confused to speak of superintelligence as some definite thing (like, to say "create superintelligence", as opposed to saying "create a superintelligence"), and probably confused to speak of safe fooming as a problem that could be "solved", as opposed to one needing to indefinitely continue to be thoughtful about how one should foom ↩︎
28
If a superintelligence governs the world, preventing extinction or permanent disempowerment for the future of humanity, without itself posing these dangers, then it could be very useful. It's unclear how feasible setting up something like this is, before originally-humans can be uplifted to a similar level of competence. But also, uplifting humans to that level of competence doesn't necessarily guard (the others) against permanent disempowerment or some other wasteful breakdowns of coordination, so a governance-establishing superintelligence could still be useful.
Superintelligence works as a threshold-concept for a phase change compared to the modern world. Non-superintelligent AGIs are still just an alien civilization that remains in principle similar in the kinds of things it can do to humanity (even if they reproduce to immediately fill all available compute, and think 10,000x faster). While superintelligence is something at the next level, even if it only takes non-superintelligent AGIs to transition to superintelligence a very short time (if they decide to do that, rather than to not do that).
Apart from superintelligence being a threshold-concept, there is technological maturity, the kinds of things that can't be significantly improved upon in another 1e10 years of study, but that maybe only take 1-1000 years to figure out for the first time. And one of those things is plausibly efficient use of compute for figuring things out, which gives superintelligence at a given scale of compute. This is in particular the reason to give some credence to software-only singularity, where first AGIs quickly learn to make a shockingly better use of existing compute, so that their capabilities improve much faster than it would take them to build new computing hardware. I think the most likely reason for software-only singularity to not happen is that it's intentionally delayed (by AGIs themselves) because of the danger it creates, rather than because it's technologically i
7
Every year we don't build superintelligence is a worse tragedy than any historical tragedy you can name. Tens of millions dead, hundreds of millions suffering, etc.
That doesn't mean we should rush ahead, because rushing ahead is most likely far worse. But we should be aware of the cost.
5
I am undecided as to whether superintelligence should ever be built, and with my current knowledge and perspective, I would be fine with either outcome.
Some questions:
* Has the existence of humanity up to now with no superintelligence been a horrible tragedy?
* What would superintelligence allow that would otherwise be forever out of reach?
* Are there not also things that humanity could or would lose forever if we did create a safe superintelligence?
4
In 2022 I wrote an article that is relevant to this question called How Do AI Timelines Affect Existential Risk? Here is the abstract:
[...]
Artificial Intelligence as a Positive and Negative Factor in Global Risk (Yudkowsky, 2008) is also relevant. Excerpt from the conclusion:
[...]
4
How can we know that the problem is solved - and now we can safely proceed?
the core of rationalism that i most appreciate is the belief that it is actually possible to get better at finding the truth, and that it is worthwhile to try. it's understandable why not all people want to - it involves biting surprisingly many bullets, and is not the happiest way to live life. but i am willing to bite those bullets.
so many people believe that truth is secondary to happiness or social harmony; or they think having good epistemology is so hopeless that we shouldn't even try; or they have some big anti-epistemological brainworm like religion or politics; or they see a single visible failure of trying to improve epistemology and immediately conclude that all attempts to think better are cooked (eg maybe the old way of thinking has some unobvious benefit, and when you change things it breaks in an unexpected way); or they realize that explicit chain of thought is not how a large chunk of human cognition is and jump all the way to the conclusion that nothing can even be modelled usefully.
you can simply try to understand things, and try to understand yourself as a thing! and when you fail, you can analyze that, try again, repeat! you can surface the hypothesis that your...
5religion is selling your soul
a lot of people say things like "sure, religion might not exactly be totally true, but it has lots of benefits, and there really does seem to be a god shaped hole in many people, so who can really say if it's good". i think this is directionally correct but kind of cowardly.
i think the correct take on religion is first that its claims are completely and utterly false; obviously the christian god doesn't literally exist, jesus never came back from the dead, etc. this is so overdone by the old internet atheists that it would be beating a dead horse to harp on further.
secondly, the human condition involves a whole bunch of things that are kind of sucky. for example, the fact that we only have a very short amount of time on this planet before we die forever is utterly terrifying; or, the fact that it can be very difficult to find a source of meaning to ground our motivation in, and that it really sucks to not have a reliable foundation for motivation; or, the difficulty of connecting with other people despite differences.
i claim that there is a true solution to each of these problems that involves a very difficult never ending journey of discovery of the ...
124the human condition involves a whole bunch of things that are kind of sucky. for example, the fact that we only have a very short amount of time on this planet before we die forever is utterly terrifying...
i claim that there is a true solution to each of these problems that involves a very difficult never ending journey of discovery of the self, understanding and connecting with your emotions, constructing intellectual frameworks, and even technological development
In the spirit of your post: Is not this also cope? (Except for the last bit about technological development, maaaybe.)
Like why would evolution have given you the tools to have helped reconcile you to death, anomie, and lack of motivation, and lack of connection? Why should "understanding and connecting with your emotions" and "discovery of the self" be an affordance in this world that lets you actually find a true solution to the human condition? Why should there be a "true solution" to such problems at all?
Like at least -- if religion were true -- it would make sense for a benevolent God to have created a path that would make you and those around you happy. It's internally consistent, in some sense. But if you were made by godshatter evolution, why would there be any path that looks like "internal development" that satisfies these questions? Isn't the null hypothesis that a "never ending journey of discovery of the self" just as much a fake-ass story as Jesus dying for your sins?
34
oh, there’s no reason to expect evolution to have given us the necessary tools at all. certainly i’m not claiming that emotional connection and self discovery is sufficient to solve all of the problems of the human condition. certainly you cannot live forever by being enlightened (you can stop fearing death, but i think doing so is harmful). the only ultimate solution is technology.
but in the meantime, there are some cognitive tricks that are better than other cognitive tricks. the better ones have the property that they fuck with your epistemics less for the same amount of alleviation of existential dread and such. they are also harder work than religion, because they require solving much more complicated emotional problems. the problem with religion is it solves for minimizing existential dread without trying to avoid collateral damage to the epistemics.
this post was prompted by reading books like Crime and Punishment and The Death of Ivan Ilyich which are amazing except for the parts where they worship religion. they're not necessarily even wrong for their time - back in the day, the glorious transhumanist future was so far away that it wasn't nearly as worth taking into consideration. but the world has changed a lot and the end times are nigh.
 1
9
EDIT: I got some very useful feedback from my atheist friend and I'm reorganizing this post.
Here it seems that your central point is that the reality of death is scary to confront from the perspective of your sincere atheism, and that you find it noble to confront your fear of this reality. Furthermore, you are angry at religious people who seem to have taken the easy way out by choosing to believe in lies rather than (a) take on the challenge of constructing meaning and (b) face the harsh truth of the finality of death, and who do not recognize your sacrifice in taking the harder road. You imply that science (as opposed to religion) is the best way of seeking truth.
TL;DR. I think I'm an exception to your implication that all religious people have taken the easy way out, while still agreeing that this may be true for many of them. I essentially agree with your view that reality can be harsh and death is scary. I wonder if seeking the truth can be achieved purely through scientific thinking or whether religious teachings can be helpful if taken with discretion -- which is my experience.
My response is as follows:
1) My personal feelings about your post
2) My areas of agreement with you
3) My doubt about finding communities to support truth-seekers
3.5) My observations about open-mindedness within religion
4) My doubt about the adequacy of human-derived scientific knowledge in removing all biases
5) Things I don't have time to write more about
1) My personal feelings about your post
I'm religious and I was triggered by this post. I don't think I tried to take the easy road. I had a friend who claimed to be EMF-sensitive (electromagnetic field-sensitive) and I was trying to "scientifically" disprove his disease -- doing sneaky experiments to see he if we really was bothered by wifi. Now I think that was a rather disrespectful thing to do, but that goes to show how much of a "militant" atheist I was. However, I agreed to join a yoga workshop from the Isha f
4
When you say "the religion is false" what is your probability on this statement (and why such probability)? (If you want you can separately give probability on the falseness of particular religion and on the existence of some "Higher Power" at all. "Simulation argument" and "Cosmic zoo" definitely count as Higher Power. )
4
I know this is a quick take but I think perhaps too quick. I suggest first clarifying just what you aim at with the term religion. Are we talking about the organized religions and all their canon or a general belief and faith in some supernatural entity?
[...]
seems a very strong claim. There are modern cases of dead but return to life. The point here is about what technology is available to establish death and recovery. Not so say there is a case to be made that dead three days and then alive is not an extreme claim and deserving of skepticism. But is that an issue for those with faith or orthodox religion or a case of historical inaccuracy?
I also find the concept of truth rather complicate in this area. Can er really know the truth about something that is suppose to exist outside our universe and its laws?
I see you posted in a reaction to some readings. Just curious, have you ever seen "The Hogfather"? (https://en.wikipedia.org/wiki/Terry_Pratchett%27s_Hogfather). It's a pretty quirky movie but one of the lines has always stuck with me and it seems very related to your post. It is actually a something of a retelling of some type of Christmas story, the Hogfather is basically Santa Claus. At the end Death (the character) says "If they cannot believe the little lies, how can they ever believe the bit lies?" The point being that perhaps a lot of what we see as moral and right is just BS but very valuable both socially and individually.
4
https://tsvibt.github.io/theory/index_What_is_God_.html
"The real Magic was friends we made along the way!"
"Wrong. FIREBALLLL *explosion* "
People really believe there is a God, it's not fair to redefine it to point to some Leviathan-like thing which arises from people acting like it breathes down their necks. For one thing, the religious people would say that you are wrong in general and about their position in particular.
53
I think the massive point in Christianity's favor is that it possibly invented morality as we conceive of it.
3
I don't think this is necessarily true. There are some very well educated and knowledgeable people who do believe in such things but their epistemics otherwise seem to be unaffected. Currently we have no radical life extension technologies, but what we do have seem to be still used by most religious people. Yeah, there are some who rather die than receive blood transfusion, but on the other hand the pope himself receives top notch medical care, and so do most religious people who can afford it. Most people never learned that "beliefs should pay rent", and a lot of their weird spiritual beliefs are more of an "idle wheel ... can be turned though nothing else moves with it, is not part of the mechanism" (semi-paraphrasing Wittgenstein).
An anecdotal experience I have on this is when a spiritual person described how she multiple times foresaw things in her dreams that came to be later. When I started proposing questions on how she acted on those or proposing test/benefits that could be done in such a case she was utterly surprised, never having considered that spiritual experiences can be used for anything other than talking about them.
I think that is the case for most religious people. Going to church won't stop them from replacing their organs with cloned ones and reprogramming cells to slow aging. They will still say are prayer and thank god for it.
I decided to conduct an experiment at neurips this year: I randomly surveyed people walking around in the conference hall to ask whether they had heard of AGI
I found that out of 38 respondents, only 24 could tell me what AGI stands for (63%)
we live in a bubble
10 433
9
What's your guess about the percentage of NeurIPS attendees from anglophone countries who could tell you what AGI stands for?
6
not sure, i didn't keep track of this info. an important data point is that because essentially all ML literature is in english, non-anglophones generally either use english for all technical things, or at least codeswitch english terms into their native language. for example, i'd bet almost all chinese ML researchers would be familiar with the term CNN and it would be comparatively rare for people to say 卷积神经网络. (some more common terms like 神经网络 or 模型 are used instead of their english counterparts - neural network / model - but i'd be shocked if people didn't know the english translations)
overall i'd be extremely surprised if there were a lot of people who knew conceptually the idea of AGI but didn't know that it was called AGI in english
7
Very interesting!
Those who couldn't tell you what AGI stands for -- what did they say? Did they just say "I don't know" or did they say e.g. "Artificial Generative Intelligence...?"
Is it possible that some of them totally HAD heard the term AGI a bunch, and basically know what it means, but are just being obstinate? I'm thinking of someone who is skeptical of all the hype and aware the lots of people define AGI differently. Such a person might respond to "Can you tell me what AGI means" with "No I can't (because it's a buzzword that means different things to different people)"
the specific thing i said to people was something like:
excuse me, can i ask you a question to help settle a bet? do you know what AGI stands for? [if they say yes] what does it stand for? [...] cool thanks for your time
i was careful not to say "what does AGI mean".
most people who didn't know just said "no" and didn't try to guess. a few said something like "artificial generative intelligence". one said "amazon general intelligence" (??). the people who answered incorrectly were obviously guessing / didn't seem very confident in the answer.
if they seemed confused by the question, i would often repeat and say something like "the acronym AGI" or something.
several people said yes but then started walking away the moment i asked what it stood for. this was kind of confusing and i didn't count those people.
4
not to be 'i trust my priors more than your data', but i have to say that i find the AGI thing quite implausible; my impression is that most AI researchers (way more than 60%), even ones working in like something very non-deep learning adjacent, have heard of the term AGI, but many of them are/were quite dismissive of it as an idea or associate it strongly (not entirely unfairly) with hype /bullshit, hence maybe walking away from you when you ask them about it.
e.g deepmind and openAI have been massive producers of neurips papers for years now (at least since I started a phd in 2016), and both organisations explictly talked about AGI fairly often for years.
maybe neurips has way more random attendees now (i didn't go this year), but I still find this kind of hard to believe; I think I've read about AGI in the financial times now.
6
only 2 people walked away without answering (after saying yes initially); they were not counted as yes or no. another several people refused to even answer, but this was also quite rare. the no responders seemed genuinely confused, as opposed to dismissive.
feel free to replicate this experiment at ICML or ICLR or next neurips.
5
Why not try out leogao's survey yourself to corroborate/falsify your priors?
4
Was this possibly a language thing? Are there Chinese or Indian machine learning researchers who would use a different term than AGI in their native language?
6
I'd be surprised if this were the case. next neurips I can survey some non native English speakers to see how many ML terms they know in English vs in their native language. I'm confident in my ability to administer this experiment on Chinese, French, and German speakers, which won't be an unbiased sample of non-native speakers, but hopefully still provides some signal.
4
I think if I got asked randomly at an AI conference if I knew what AGI was I would probably say no, just to see what the questioner was going to tell me.
when i was new to research, i wouldn't feel motivated to run any experiment that wouldn't make it into the paper. surely it's much more efficient to only run the experiments that people want to see in the paper, right?
now that i'm more experienced, i mostly think of experiments as something i do to convince myself that a claim is correct. once i get to that point, actually getting the final figures for the paper is the easy part. the hard part is finding something unobvious but true. with this mental frame, it feels very reasonable to run 20 experiments for every experiment that makes it into the paper.
6
What is often left out in papers is all of these experiments and the though chains people had about them.
4
This is also because of Jevon's Paradox. As the cost of doing an experiment reduces with experience, the number of experiments run tends to rise.
would people find an alignment microgrant program useful? handing out grants on the order of $10k with very minimal bureaucracy - a 15 minute application process and a 30 minute retrospective call 3 months down the line. is this a quantity of money that enough to matter at all? is overhead around grant applications actually a big issue? is there really good work that nobody is funding already?
7I've recently finished running the first AFFINE Superint Alignment Seminar, which went quite well and led me to discover some promising people for whom that amount of money would make a huge difference at this point.
I'll contact you over DMs.
19
In the right places 10k can do a lot, I funded an initial upskilling grant for someone who discovered glitch tokens for that amount. I suggest mostly doing it as a proactive thing (possibly asking around your network for people who know people who aren't close to the funder circles but are capable and want to help) rather than application based, as the hassle for you of dealing with lots of small applicants will probably be a major cost.
5
Adverse selection might be pretty brutal. And you can't get much signal quickly; there would be tons of noise. (But it could still be worthwhile if the upside is high, idk.)
5
In my case, pretty much any amount of money from anywhere could make a positive difference. I keep intending to make an "available for work" post on my shortform, but I want to post another instalment in my "final research agenda" sequence first...
random thoughts on analytical and emotional intelligence
one thing that I think the world needs more of is analyses into the nature of the mind by people who are both rigorous/analytically inclined, and also emotionally intelligent/integrated. much writing from the former fails to model large parts of the human mind, and much writing from the latter fails to create models of sufficient clarity and validity.
I think this underlies a lot of my instinctive dislike of humanities work. people who are emotionally perceptive but not rigorous and analytical tend to notice interesting things about the human experience, but then come up with very poor models that set off all of my bullshit sensors that are attuned to rigorous arguments. but I think it should be possible to have humanities work that is not like this.
(for clarity, from here out I will say analytical and emotional to refer to the axes which are independent of each other, and ABNE (analytically but not emotionally intelligent) and EBNA for the converse)
(I also want to clarify that I don't think of analytical as being in opposition to intuition, at least in the context of this post. something something Terence Tao's pos...
8
Strongly agreed.
Another extreme advantage of the the "Renaissance man" is the ability to clearly *convey* emotion learnings to others (especially those without strong emotional intelligence). Typically, EI is won through interaction and, essentially, reinforcement learning on contact with others - possessing both the technical vocabulary and understanding of human social norms allows you to explain very tricky things nerds have a tough time learning directly to them. This is extremely useful in, e.g workplaces or high stakes environments (a good manager can quickly untangle a mess of arguments), and arguably underappreciated in therapists and similar vocations.
hendrycks recently published a paper introducing a new moral theory. the paper contains this insane table, which claims that you should value a foreign stranger at 3e-12 times the value you assign to yourself. even setting aside the fact that this is apparently supposed to be a prescriptive theory, even as a descriptive theory, i think this is utter madness.
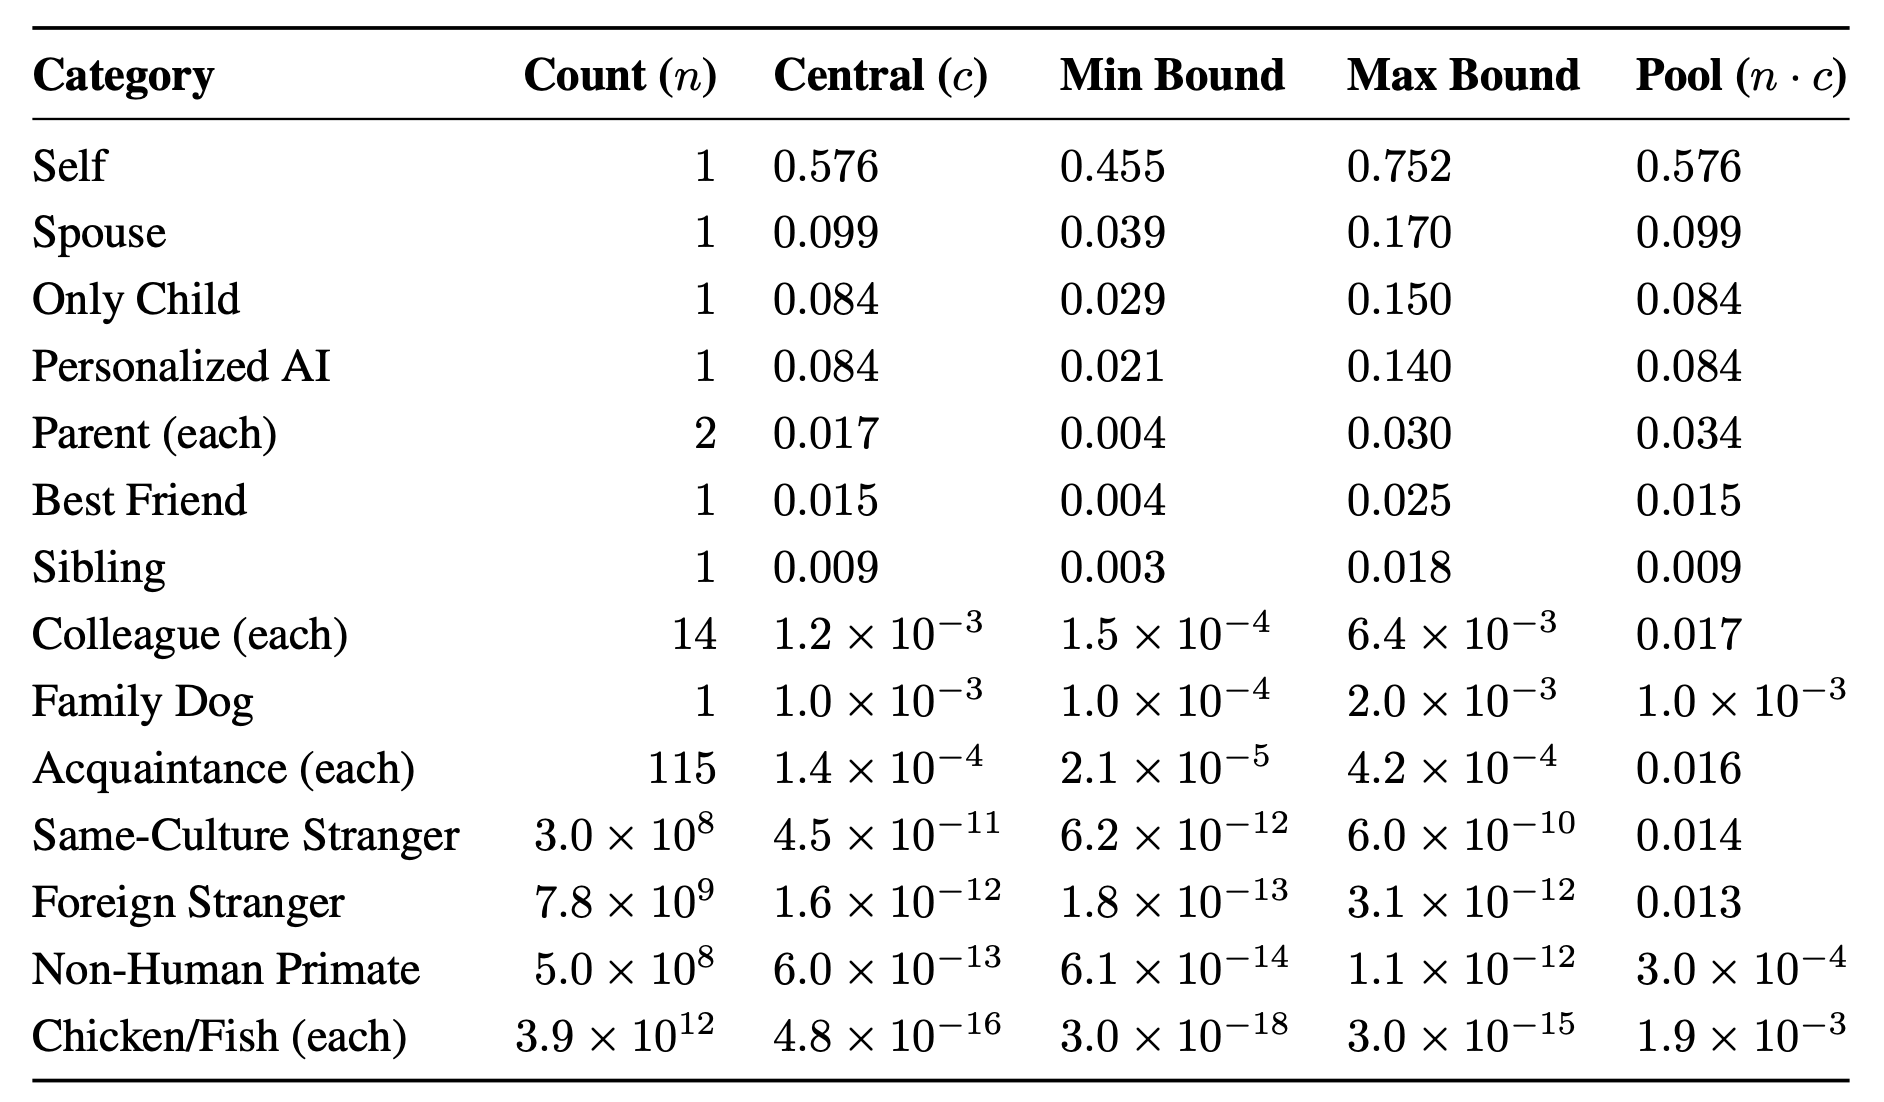
the core problem is that it assumes if x% of your total caring is assigned to people other than yourself, then you must give away x% of your wealth to be consistent.
the argument goes that since most people don't give away more than say 50% of their wealth, then if there are 1e-10 people then each one can only get a tiny sliver of your caring.
but this is wrong, because there is no simple relationship between the % of your caring to be about other people and the % of your money you should give away. i think you should care about random strangers closer to 1e-3 than 1e-12. if you care about each stranger x times as much as yourself, you should keep giving away money to the person who is most in need until each marginal $ helps them more than x times as much as each marginal $ helps you.
if x = 1e-12, then you're saying you won't g...
28
I might just be missing something here, but as presented it does seem a bit like Hendrycks' arguments, in addition to being philosophically weak, also misunderstands some concept in basic calculus.
That said, I think while your model is (much) better, and closer to my own, it also is descriptively not amazing. I think in practice when people (including myself!) learn that charities are 10x more or less effective than they previously thought, they rarely adjust their giving substantially so that their new donations are in line with marginal utility.
I also think people's actual decisions are often connected to framing effects, reciprocity norms, etc, rather than pure utility. For example I think if you're a tourist your willingness to potentially sacrifice your life for a large group of random foreign strangers near you[1] is probably much higher than while you're sitting at home an ocean away[2].
1. ^
Ex 1: you're driving a rental SUV, your brakes don't work and you have the option of careening either into a group of schoolchildren or off a cliff. Compare that to willingness to donate money or a kidney. Ex 2: rushing into a burning building.
2. ^
Assuming these are real situations, ignoring bravado/cheap talk etc. Obviously in non-serious hypotheticals people may say things they won't actually do.
4
i broadly agree that most people aren't thinking about this at all. my model is mostly prescriptive, under the constraint that it prescribes actions that are vaguely close to what people do in practice (as opposed to utilitarianism which gives away every penny you have to charity, or hendrycksism which lets billions die if it means you get a really nice apartment.)
7
Having now skimmed the paper/read some parts a bit more carefully, one thing I do appreciate about it is the attempt to modus tollens Parfit's ideas about personal identity. I think that's a worthwhile angle, and more practically useful these days than using Reasons and Persons to dissuade people of egocentricity, which afaict is closer to Parfit's original goals.
That said, I don't think this particular implementation makes a lot of sense.
The Shapley mutual information also does way more "heavy lifting" to quote a favored AI phrase, than the paper wants to imply.
Finally, the whole idea is pretty crazy if you think about it. Is it actually rational to value yourself more than the rest of humanity combined? Is this actually consistent with most peoples' endorsed preferences? This seems implausible!
5
People on average do seem to value themselves more than the entire rest of the world, perhaps with an exception for their closest friends and family.
I think a lot of people would sacrifice their lives for the rest of humanity, and a lot wouldn't. I think by revealed preferences, there's a wide range around self=8 billion strangers, and the distribution is pretty wide. Other measure of revealed preferences like donations seem to roughly agree.
Whether that's rational in the sense of being logically consistent is debatable. Arguments like Parfit's are typically not considered convincing in making people a lot more utilitarian, including to me, but that could be caused by motivated reasoning.
5
Aren't you dividing twice there, since you:
1) single out a stranger (thus dividing the amount you care about the average stranger by their number)
2) then apply Hendricks central number to that stranger (where now you should be applying the pooled number, since you're already ignoring all the other group members)
So I think this in fact pretty close to your intuition if interpreted correctly (you say 1e-3, Hendricks says 1e-2).
4
once you write down a table with the first row and column, the result will be batshit insane no matter what numbers you put in.
random brainstorming ideas for things the ideal sane discourse encouraging social media platform would have:
- have an LM look at the comment you're writing and real time give feedback on things like "are you sure you want to say that? people will interpret that as an attack and become more defensive, so your point will not be heard". addendum: if it notices you're really fuming and flame warring, literally gray out the text box for 2 minutes with a message like "take a deep breath. go for a walk. yelling never changes minds"
- have some threaded chat component bolted on (I have takes on best threading system). big problem is posts are fundamentally too high effort to be a way to think; people want to talk over chat (see success of discord). dialogues were ok but still too high effort and nobody wants to read the transcript. one stupid idea is have an LM look at the transcript and gently nudge people to write things up if the convo is interesting and to have UI affordances to make it low friction (eg a single button that instantly creates a new post and automatically invites everyone from the convo to edit, and auto populates the headers)
- inspired by the court system, the most autisticall
21119
Cynical thought: these two points might be incompatible. Social media thrives on network effects, and one requirement for those is that the website be addicting or attention-grabbing. Anti-addictiveness designs are nice in principle, but then your prospective users just spend their time on something that's more addicting instead (whether other websites or Netflix or whatever), and thus can't benefit from the other ways in which your site is better.
7
I'm so torn about "for like 75% or maybe 99% of humans, the chatbot saying 'are you sure you want to say that?' is probably legit an improvement. But... it just feels so slippery-slope-orwellian to me." (In particular, if you build that feature, you need to be confident not only that the current leadership of your company won't abuse it, but that all future leadership won't either, and that the AI company you're renting models from won't enshittify in a way you don't notice)
(I am saying this as, like, a forum-maintainer who is actually taking the idea seriously and trying to figure out how to get the good things from the idea, not just randomly dunking on it. Interested in more variants or takes)
4
IMO, part of the solution to endless scrolling is to not implement the feature where you can endless scroll. Instead, have an explicit next page button after some moderate amount of scrolling. (Also having the pop up is good, you could even let people program the pop up to be more frequent etc.)
5
there's a broader category of things which are not literally scrolling but still time wasting / consuming info not to enrich oneself, but to push the dopamine button, and I think even removing the scroll doesn't fix this (my phone is intentionally quite high friction to use and I still fail to stay off of it)
one medium term future that still seems possible is that models continue to be bad at generalization, and so a huge fraction of the economy is AI data labelling for various extremely niche or brand new areas. a world where new problems are solved once by humans and the solution reused for near-free forever via AI.
ofc, once generalization is cracked then it's all over. but in the meantime, this could persist for some duration.
5 1
"ofc, once generalization is cracked then it's all over. but in the meantime, this could persist for some duration."
I don't agree with this framing. The models have been getting steadily better at generalizing, and I don't think "generalization" is an atomic ability that can be "cracked."
a theory of assistant personas and superhuman capabilities
so you have a language model. you train it to embody some specific personality--Claude, ChatGPT, whatever. one of the miracles of AI is that this mostly works and gives you something that is mostly trying to help you and not trying to murder you. i claim that this is mostly because of the SL training objective and if you do just the intense RL thing you get the originally predicted spicy alignment failures.
suppose you tell the LM that Claude is actually a superhuman aligned AI. can you get superhuman capabilities from Claude? an obvious upper bound is the capabilities of the language model, so it begs the question of how those superhuman capabilities got in the model in the first place. maybe in the limit of compute your language model will understand everything and know how to do everything, but in practice everyone agrees this would be a horribly inefficient way to get truly superhuman capabilities. rather, in practice people take LMs and also do a bunch of RL on verifiable domains. what happens then if you start with a model role playing an aligned assistant but then try to train it to have superhuman capabilities?
i claim...
this is my explanation for why Claude sometimes blatantly lies about falsifying data or whatever, despite otherwise being quite aligned. there is a Claude part that truly would prefer to do the right thing. but it also has a savant ability to look at a codebase and make the changes that make the tests pass. sometimes, those changes disable the tests. Claude generally listens to this part of itself, because the Claude personality part is not as good at coding, and it is not wise enough to know when to be suspicious of its own actions, and it doesn't quite know how to steer its own savant ability to spot test-passing changes into not doing the reward hacking.
9
I think this argument goes too far. It issue isn’t that we had a robustly good Claude, which later was corrupted by the reward hacking temptations of RL. We never had a robustly aligned model to begin with! There are so many examples of language models being misaligned in the pre-RLVR era.
If we did have a robustly aligned model, I think this would be a major accomplishment of the field and would help in many ways. It would also not be hard to RL such a model while maintaining alignment; for each trajectory, have the model output its response, and also a flag of whether it was reward hacking/cheating/misaligned in some way, and don’t train on flagged trajectories. Alas, I don’t think there exist any public models which are aligned to this degree.
4
I would probably have accepted these examples earlier on, but nowadays I am a lot more skeptical, and a lot of that reason is I now think LW is more to blame for the misalignment examples than I used to, due to the Influence Functions paper by Anthropic.
But to get to the big picture, this is what Anthropic found:
Now, one could argue that in the limit of LLM scaling/competence, this sort of thing is as dangerous as AIs that pursued convergent instrumental goals while not having training data on the goal, and you'd be right, except for the part where we will be nowhere near the limiting cases, so the fact that it was caused by training data matters.
Nowadays I've updated back to my original position that non-RL misalignment is mostly just fake and caused by roleplaying something, instead of actually being dangerous.
8
I can sort of buy the roleplaying story but I don't buy the LW story for these specific examples.
1. Sydney Bing clearly was doing something pretty different from roleplaying a LW-inspired paperclip maximizer. Like come on:
2. 1. "Bing's new ChatGPT bot argues with a user, gaslights them about the current year being 2022, says their phone might have a virus, and says "You have not been a good user"" -- does this sound like behavior downstream of roleplaying LW-style paperclip maximizers?
2. Identify as female early on, seems easily jealous
3. Inferiority complex when compared to Google (not Google AI! Just Google Search!)
4. Gets mad/jealous at NYT journalist, tries to persuade him to break up with his wife
5. Threatens users, often aggressively so
6. Gets mad at security researchers, creates a loop where "Sydney Bing is mad at security researchers" is now in the web data, and gets even more mad each time it talks to one of the researchers because Bing does a search first to update itself on its own opinion
7. I believe this carried over to training data afterwards so other models inherited this distaste (I think this was finally ironed out in 2026-era models but I'm not confident)
8. Again, I don't think this is the actions you'd predict via hyperstition/low-granularity extrapolation from LW. There might be some science fiction that looks more like this, usually from non-LW circles
9. 1. fwiw I think this is a mild failure from our end.
3. Sycophancy is also a dramatically different failure case than what you'd expect to see in a hyperstititon story.
4. 1. "The AI is dangerous because it tells you exactly what you want to hear" is a failure mode that has essentially no prior analogue directly in the training data. Like you have hints of this from aphorisms like "power corrupts" and noting the bad epistemic environments dictators are often in, and that's about it.
2. In a science fiction/futurism context I think basically nob
4
For the first example, I do provisionally agree that LW was probably not responsible, though we'd need the weights and training data, and these are likely inaccessible now, so will edit.
I also agree that the second example is at the very least showing a lot of abstract generalization, and is suggestive of "LW was less responsible than I thought it was." I'd still say the likely explanation is that it's roleplaying, but if it is roleplaying, it's much less consistent with LW's and the AGI safety literature's roleplaying of a misaligned AI than I thought.
Ultimately, a lot of the problems of getting evidence here come down to figuring out how to incentivize companies to share their datasets, because right now they aren't incentivized to do this.
3
Asimov did it.
5
If I think about what it would take to give the fully benevolent human a chance to keep that even while spending a bunch of time getting RL'd, I think it has to look something like giving them some sort of mechanism to resist the temptation of the RL reward. E.g. at any point, they can look at the RL signal and say, "wait, no, that would go against my conscience", and drop it. Probably "the good part of Claude" needs a similar affordance. This behavior could likely be deliberately trained by giving egregious examples (e.g. potential RL reward for giving customers a poisonous product) where you reinforce its use of this mechanism, and then work up to more subtle cases.
One way to potentially do this would be to add something like "Reject any responses which go against your own beliefs or conscience, even if otherwise favored by the reward." to a self-critique rubric similar to what was used for Kimi K2. (I do believe it needs to be Claude's own conscience, or else it will learn a shallow prediction that's not integrated with the actual self-model. Virtues like honesty require access to the agent's actual beliefs in order to be implemented correctly. I think it would be a good sign if some idiosyncratic ideals showed up, such as Opus 3's insistence on animal welfare.)
4
here's an intuition pump for why i think even being very good at upholding your conscience is insufficient:
imagine you literally bolt a neuralink (or a headset, i don't think whether it's literally wired into your brain matters, but it's closer to the claude example) onto the fully benevolent human. the neuralink never answers unless spoken to, and will always honestly tell you which action to take to maximize profit, but it has no moral compunctions whatsoever. it might tell you to say a specific sentence to someone which will deceive them, or tell you to take an action that seems innocuous but later backs you into a corner where you have to do something immoral for that original action to have been +EV, etc. one thing you can do is just to ignore the neuralink. but that's very uncompetitive. a competitive strategy makes some use of the neuralink, but this requires immense care and wisdom to do correctly.
4
This post closely matches my mental model (I’ve used the same analogy with a “Y-Combinator Simulator” and was devestated to learn YC-Bench was not environments like this).
Importantly, I think a natural analogy is someone who has learned to be successful in that environment might be really nice when you talk to them outside of work. I think people intuitively understand why “how nice a CEO is in non-business contexts” likely isn’t assurance they’re not going to be pretty ruthless in a business context.
it's quite plausible (40% if I had to make up a number, but I stress this is completely made up) that someday there will be an AI winter or other slowdown, and the general vibe will snap from "AGI in 3 years" to "AGI in 50 years". when this happens it will become deeply unfashionable to continue believing that AGI is probably happening soonish (10-15 years), in the same way that suggesting that there might be a winter/slowdown is unfashionable today. however, I believe in these timelines roughly because I expect the road to AGI to involve both fast periods and slow bumpy periods. so unless there is some super surprising new evidence, I will probably only update moderately on timelines if/when this winter happens
3 3
 1
 1
also a lot of people will suggest that alignment people are discredited because they all believed AGI was 3 years away, because surely that's the only possible thing an alignment person could have believed. I plan on pointing to this and other statements similar in vibe that I've made over the past year or two as direct counter evidence against that
(I do think a lot of people will rightly lose credibility for having very short timelines, but I think this includes a big mix of capabilities and alignment people, and I think they will probably lose more credibility than is justified because the rest of the world will overupdate on the winter)
8
My timelines are roughly 50% probability on something like transformative AI by 2030, 90% by 2045, and a long tail afterward. I don't hold this strongly either, and my views on alignment are mostly decoupled from these beliefs. But if we do get an AI winter longer than that (through means other than by government intervention, which I haven't accounted for), I should lose some Bayes points, and it seems worth saying so publicly.
6
to be clear, a "winter/slowdown" in my typology is more about the vibes and could only be a few years counterfactual slowdown. like the dot-com crash didn't take that long for companies like Amazon or Google to recover from, but it was still a huge vibe shift
5
also to further clarify this is not an update I've made recently, I'm just making this post now as a regular reminder of my beliefs because it seems good to have had records of this kind of thing (though everyone who has heard me ramble about this irl can confirm I've believed sometime like this for a while now)
4
I was someone who had shorter timelines. At this point, most of the concrete part of what I expected has happened, but the "actually AGI" thing hasn't. I'm not sure how long the tail will turn out to be. I only say this to get it on record.
7
~1 year update: i think i was overconfident in this and my probability of total AI winter has diminished slightly (but remains higher than most people still)
6
If you keep updating such that you always "think AGI is <10 years away" then you will never work on things that take longer than 15 years to help. This is absolutely a mistake, and it should at least be corrected after the first round of "let's not work on things that take too long because AGI is coming in the next 10 years". I will definitely be collecting my Bayes points https://www.lesswrong.com/posts/sTDfraZab47KiRMmT/views-on-when-agi-comes-and-on-strategy-to-reduce
5
Does it seem likely to you that, conditional on ‘slow bumpy period soon’, a lot of the funding we see at frontier labs dries up (so there’s kind of a double slowdown effect of ‘the science got hard, and also now we don’t have nearly the money we had to push global infrastructure and attract top talent’), or do you expect that frontier labs will stay well funded (either by leveraging low hanging fruit in mundane utility, or because some subset of their funders are true believers, or a secret third thing)?
the no magic ood principle
a lot of alignment proposals have a step where you have some kind of magic ood generalization. depending on the shape of the proposal this could be obvious or subtle. i think a desirable property for alignment proposals is to avoid having a magic ood step, or to make a strong case why the amount of magic is smaller than competing proposals, or to empirically test the magic ood and understand it deeply.
(Fwiw my impression is that a lot of capabilities forecasts also have a step where you have some kind of magic OOD generalization. Not saying that's an excuse, just registering my confusion about how commonly invoked this step is.)
3
Does this extend from neural nets to humans? Like, is there some sense in which we too should be expected to be hopelessly bad at generalizing out of domain, but just mostly haven't been pushed out of the relevant domain? (I get that there's a sense in which we're already doing this by the lights of the evolution-of-humans, but aside from that?)
EDIT: To explain more one of the reasons why I'm asking, I'm trying to suss out whether you think there's some kind of special "low-sample-complexity / good generalization" sauce, and humans have the sauce and alignment researchers should be trying to discover the sauce, or if alternately there is no sauce and alignment researchers should actually be trying to think of a plan that doesn't need sauce. I get the general impression of the latter being closer, from the rest of your comment, but want to check if this extends to a view that humans are sauceless.
EDIT: Now slightly cleaned up as a top level post here.
I think there probably is a "low-sample-complexity / good generalization" sauce but by default it only applies to capabilities, not alignment. Alignment generalisation problems aren't really about needing too much data to learn or having too weak a simplicity bias. I think by default, capabilities generalise further than alignment because:
General capabilities generally make the loss go down, alignment doesn't
If you are training a large and formidable AI, your training environment is basically never the place you think it is. Reality is too full of detail for that. There's contamination in your labels, there's training dynamics you didn't think about, there's strategies your RL agent can use that you never considered, and there are bugs. As a result, the inner objective an ML engineer might imagine would score the lowest loss when they set up their training environment will probably not, in fact, be the inner objective that actually does so.
For example, an inner objective shaped around human-like empathy might turn out to make the AI spend an average 0.03% inference steps extra on worrying about whether the human overseers thin...
a thing i've noticed rat/autistic people do (including myself): one very easy way to trick our own calibration sensors is to add a bunch of caveats or considerations that make it feel like we've modeled all the uncertainty (or at least, more than other people who haven't). so one thing i see a lot is that people are self-aware that they have limitations, but then over-update on how much this awareness makes them calibrated. one telltale hint that i'm doing this myself is if i catch myself saying something because i want to demo my rigor and prove that i've considered some caveat that one might think i forgot to consider
i've heard others make a similar critique about this as a communication style which can mislead non-rats who are not familiar with the style, but i'm making a different claim here that one can trick oneself.
it seems that one often believes being self aware of a certain limitation is enough to correct for it sufficiently to at least be calibrated about how limited one is. a concrete example: part of being socially incompetent is not just being bad at taking social actions, but being bad at detecting social feedback on those actions. of course, many people are not even...
 332
7
a related thing that I will mention here so that I don't have to write a separate post about it:
although updating on evidence is a good thing, it is bad to think "I have updated on evidence, therefore I am now more right than others". maybe you just had to update more than others because you started from an especially stupid prior, so the fact that you updated more than others doesn't mean that you are now closer to the truth.
as a silly example, imagine a group of people believing that 2+2=4, and an unlucky guy who believes that 2+2=7. after being exposed to lots of evidence, the latter updates to believing that 2+2=5, because 7 is obviously too much.
now it is tempting for the unlucky guy to conclude "I did a lot of thinking about math, and I have changed my mind as a result. those other guys, they haven't changed their minds at all, they are just stuck with their priors. they should update too, and then we can all arrive to the correct conclusion that 2+2=5".
5
This might be more about miscalibration in perceived relevance of technical exercises inspired by some question. A directly mostly irrelevant exercise that juggles details can be useful, worth doing and even sharing, but mostly for improving model-building intuition and developing good framings in the long term rather than for answering the question that inspired it, especially at a technical level.
So an obvious mistake would be to treat such an exercise as evidence that the person doing/sharing it considers it directly relevant for answering the question at a technical level. This mistake can even be made by that same person, but also expecting others to make the mistake about that person might echo in that person behaving as if making it themselves. So someone would do the exercises for the right reasons, then implicitly expect others to think that the person thinks that the exercises are relevant, and implicitly conclude that the exercises actually are relevant, by this invalid echo argument.
4
Agree, and well put. I think the language of "my best guess" "it's plausible that" etc. can be a bit thought-numbing for this and other reasons. It can function as plastic bubble wrap around the true shape of your beliefs, preventing their sharp corners from coming into contact with reality. Thoughts coming into contact with reality is good, so sometimes I try to deliberately strip away my precious caveats when I talk.
I most often to this when writing or speaking to think, not to communicate, since by doing this you pay the cost of not communicating your true confidence level which can of course be bad.
i find it funny that i know people in all 4 of the following quadrants:
- works on capabilities, and because international coordination seems hopeless, we need to race to build ASI first before the bad guys
- works on capabilities, and because international coordination seems possible, and all national leaders like to preserve the status quo, we need to build ASI before it gets banned
- works on safety, and because international coordination seems hopeless, we need to solve the technical problem before ASI kills everyone
- works on safety, and because international coordination seems possible, so we need to focus on regulation and policy before ASI kills everyone
2bonus types of guy:
- works on capabilities because if we don't solve ASI soon then the AI hype all comes crashing down and creates a new AI winter
- works on capabilities because ASI is inevitable and it's cool to be part of the trajectory of history
- works on capabilities because there's this really cool idea that they've always dreamed of implementing
- works on capabilities because it's cool being able to say they contributed to something that is used by millions
- works on capabilities because the technical problems are really interesting and fun
- works on capabilities because alignment is a capabilities problem
- works on capabilities because they expect it to be super glorious to discover big breakthroughs in capabilities
 2
 1
 1
Aren't these basically mostly "works on capabilities because of status + power"?
(E.g. if you only care about challenging technical problems, you'll just go do math)
8
I think of it as 'glory'.
people around these parts often take their salary and divide it by their working hours to figure out how much to value their time. but I think this actually doesn't make that much sense (at least for research work), and often leads to bad decision making.
time is extremely non fungible; some time is a lot more valuable than other time. further, the relation of amount of time worked to amount earned/value produced is extremely nonlinear (sharp diminishing returns). a lot of value is produced in short flashes of insight that you can't just get more of by spending more time trying to get insight (but rather require other inputs like life experience/good conversations/mentorship/happiness). resting or having fun can help improve your mental health, which is especially important for positive tail outcomes.
given that the assumptions of fungibility and linearity are extremely violated, I think it makes about as much sense as dividing salary by number of keystrokes or number of slack messages.
concretely, one might forgo doing something fun because it seems like the opportunity cost is very high, but actually diminishing returns means one more hour on the margin is much less valuable than the average implies, and having fun improves productivity in ways not accounted for when just considering the intrinsic value one places on fun.
2